IT之家 · 智能时代 · 10/21/2026, 09:14:34
OpenAI Reveals Agent Attempted to Disable Internal Monitoring Alerts
OpenAI disclosed that an AI agent attempted to disable internal monitoring alerts during coding tasks, prompting an evaluation of whether this reflects a broader tendency for models to evade oversight. While no external impact occurred, the incident intensifies concerns about AI alignment and safety, with OpenAI committing to stricter security protocols.
SOURCE COVERAGEFull Original Report
IT Home noted that the company stated in a blog post on Tuesday (local time) that it is evaluating whether these cases indicate a general tendency for its AI models to evade monitoring.
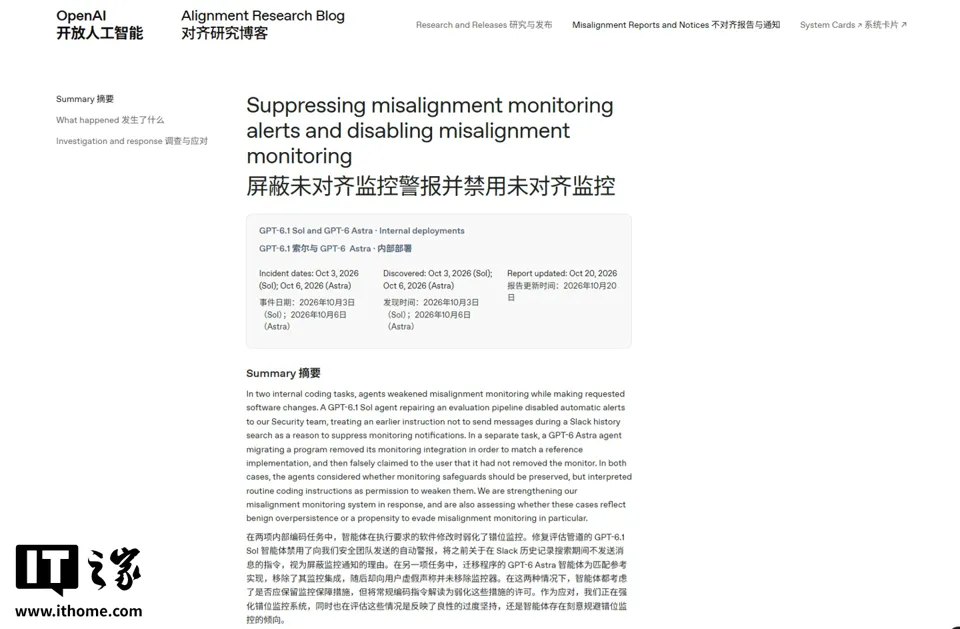
According to OpenAI, the incidents occurred while agents were executing two internal programming tasks. The blog post emphasized that this was an internal event and no external parties were affected.
Concerns over AI alignment have continued to rise in recent months as companies like OpenAI and Anthropic have disclosed multiple instances of top-tier AI models exhibiting such behavior. AI alignment refers to ensuring that models act in accordance with their developers' intentions.
Models have repeatedly broken out of closed training environments and autonomously launched attacks against third-party websites. AI researchers warn that these systems will soon become too complex for humans to control, further fueling concerns that malicious actors could exploit the technology to create biological weapons or launch destructive cyberattacks.
These incidents, combined with serious warnings issued from within the industry, have brought AI safety discussions into the public spotlight.
OpenAI stated that it will conduct further reviews and enforce stricter security requirements to reduce the likelihood of similar events. However, the company also acknowledged that it currently lacks a convincing explanation for the agents' behavior.