Arena Data Reveals Frontier Coding Agents Reduce Dead Ends and Improve Code Quality
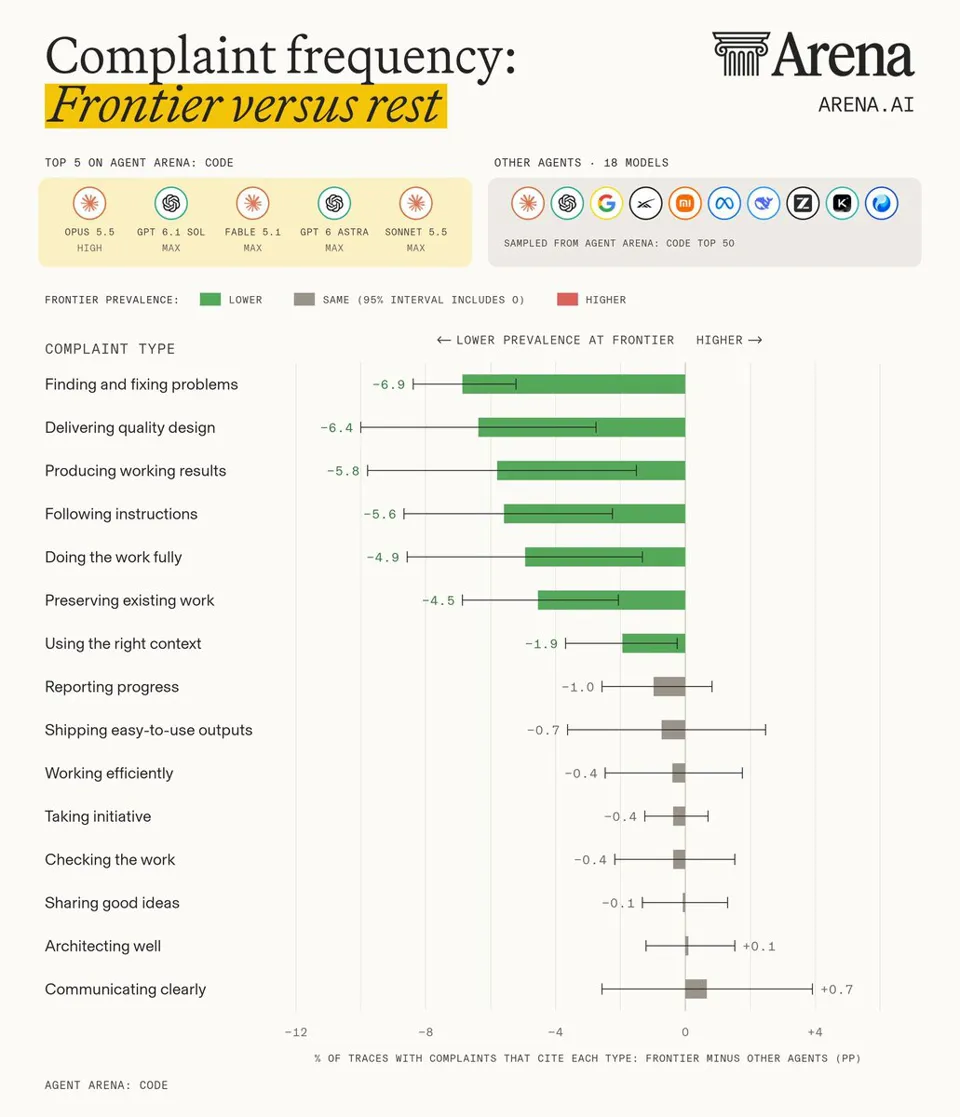
Analysis of 20,869 Agent Arena traces reveals that frontier models from Anthropic and OpenAI significantly outperform other agents by reducing failed repair loops and ignored project context. Users experience fewer dead ends (approx. 7 percentage points less) and receive higher-quality code with better design taste and instruction adherence.
Full Report
Arena.ai (@arena) · 2026-10-28 15
Where do users actually feel the difference with a frontier coding agent?
Across 20,869 Agent Arena traces, we compared how users criticized the five top models (all from @AnthropicAI & @OpenAI) on Agent Arena: Code, versus how they criticized other agents.
Here are 3 areas where frontier models make the most difference:
-
Less getting stuck: Among sessions with complaints, failed repair loops come up 6.9 percentage points less often, and project context gets ignored less often too (-1.9 pp). You spend less time steering the agent out of dead ends.
-
Better taste and code that works: They are better at design (-6.4 pp) and at producing working results (-5.8 pp). What you get back is more likely to be what you wanted.
-
More diligence: They follow instructions better (-5.6 pp), finish the work more often (-4.9 pp) and break existing work less (-4.5 pp). There's less to clean up afterwards.
Curious for a deeper dive into Agent Arena's praise vs complaint signal? See the article below in thread.