Hacker News AI · 10/11/2026, 01:12:33
Bag of Decisions Reranker: Using LLM-Generated Query-Specific Rubrics for Relevance Assessment
Introduces the 'Bag of Decisions' reranking concept, where an LLM dynamically generates query-specific Yes/No rubrics to assess relevance, replacing static judgment prompts. By decomposing search intent into concrete features (e.g., dimensions, usage, safety), this method enhances retrieval precision for complex semantics and offers a new prompt engineering paradigm for frontier rerankers like Jev.
SOURCE COVERAGEFull Original Report
Contents2 sections
What if instead of search queries being interpreted as a “bag of terms” we could see them as a “bag of decisions”?
We know Jev acts as frontier quality reranker. As a fun experiment, I wanted to try another technique: Don’t just ask Jev “Is this relevant for {query}?”. Instead, let an LLM generate the query’s criteria: a rubric to assess relevance for just this query.
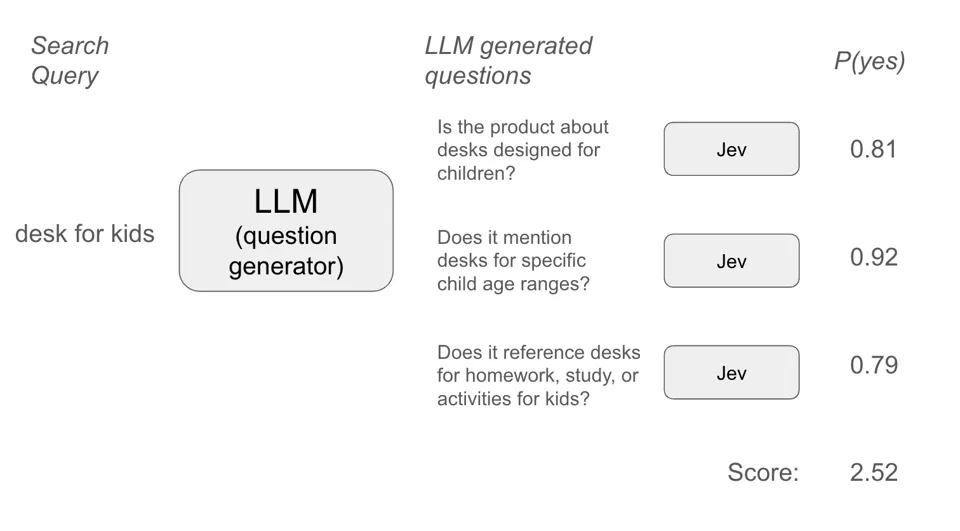
We prompt an LLM with “generate yes / no question where the affirmative indicates relevance”. For the query desk for kids it might produce:
1 -  Is the document about desks designed for children?
2 -  Does the document offer products or information on kids’ desks?
3 -  Does it mention child-sized or age-appropriate desk dimensions or ergonomics?
4 -  Does it reference desks for homework, study, or activities for kids?
5 -  Are features specific to children’s desks (e.g., height-adjustable for kids, safety/rounded edges, storage fo
r school supplies) discussed?
6 -  Does it include buying guides, reviews, or comparisons of kids’ desks?
7 -  Does it provide pricing or availability for children’s desks?
8 -  Does it mention desks for specific child age ranges (e.g., toddlers, elementary, teens) as kids’ desks?
9 -  Are brands or models of children’s desks listed?
10 -  Does it cover where to buy or how to choose a desk for kids?
Each of these can be turned into a noul question. P(yes) of each can be summed to score overall relevance:
document = """
This adjustable study desk is perfect for kids ages 5–12.
Its height grows with your child.
"""

response = client.decide(
    state=document,
    questions={
        "question_1": Noul(
            instructions="Is this document about desks designed for children?"
        ),
        "question_2": Noul(
            instructions="Does the document offer products or information on kids’ desks?"
        )
        ...
    },
)
Instead of a query being represented as a bag of terms, we have a bag of questions. Since Jev gives the probability of ‘yes’, we can simply sum the probability of each question being true as the rerank score:
total_probability = 0.0

for question_id, answer in response.answers.items():
    probability = answer.noul
    print(f"{question_id}: {probability:.2f}")
    total_probability += probability
Now total_probability can be our reranker’s final score. We can add that to BM25, or just take it directly. In other words:
How does it stack up?
I ran an experiment comparing BM25 vs two variants (gory details here):
- Jev reranking: i.e. “Is this document relevant for this query?”
- Bag of question reranking - multi-question flow described above.
I then evaluated on two e-commerce datasets Wayfair WANDS and Amazon ESCI. How did it fair?
Does this work? It seems to. Here’s some initial results:
| Dataset | Strategy name | Mean NDCG | Median NDCG |
|---|---|---|---|
| WANDS | bm25 | 0.5407 | 0.475 |
| WANDS | jev_reranker | 0.574 | 0.561 |
| WANDS | bag_of_decisions | 0.610 | 0.561 |
| ESCI | bm25 | 0.289 | 0.171 |
| ESCI | jev_reranker | 0.314 | 0.205 |
| ESCI | bag_of_decisions | 0.360 | 0.341 |
Or graphically
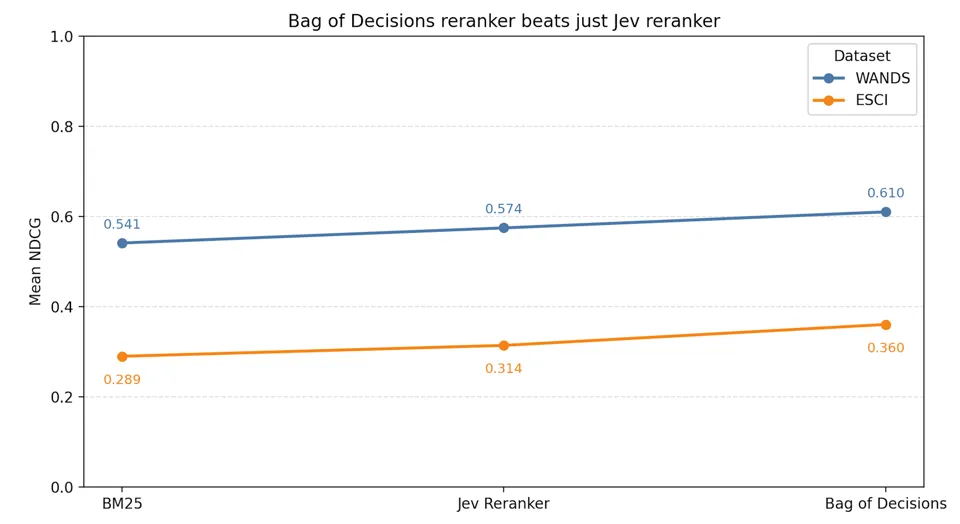
We’re essentially doing per-query feature creation. Use an LLM as inspiration of what’s important to consider for this query. Then use Jev to measure whether we’re covering that criteria. We might wonder how we might modify the LLM call to provide more incisive + diverse questions then the ones above (IMO some are repetitive)
It’s a fun approach. We seem to be able to train more and more decision models, possible even ones focused on specific domains. At least in this one toy experiment, it seems to be a promising approach worth deeper study. Enjoy!
Starting in November: AI-Powered Search — Modern Retrieval for Humans & Agents
Learn the latest AI search skills with the authors of AI-Powered Search. Join Doug Turnbull and Trey Grainger to explore modern retrieval for humans and agents. Explore the course on Maven.
More from Doug Twitter | LinkedIn | Newsletter | Bsky