Sarvam Opens Token Factory Inference Platform in India
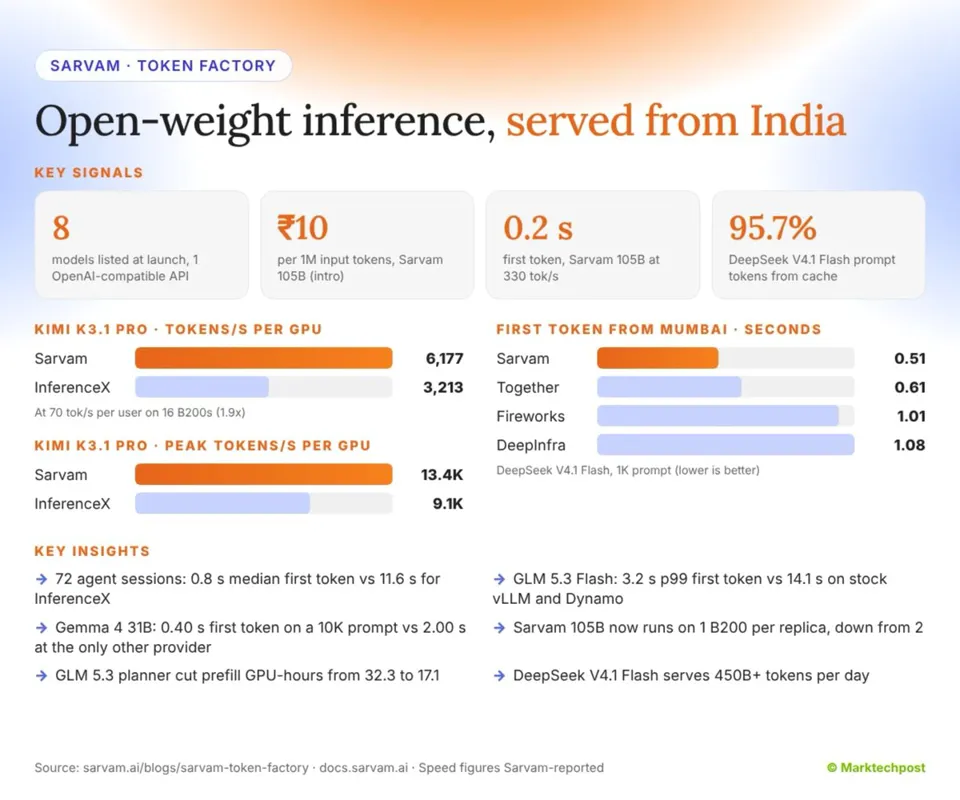
Indian AI firm Sarvam has opened its Sarvam Token Factory inference platform to all users, serving its own models and leading open-weight models from GPU clusters in India. The stack centers on a shared prefix cache with a cache-aware router, plus separate B200 pools for prefill and decode; Sarvam self-reports 6,177 tokens/s per GPU on Kimi K3.1 Pro. However, it trails Together on streaming throughput in some cases, and all figures are self-reported.
Related Entities
Full Report
▲ Marktechpost AI · 2026-11-17 09
▲ Sarvam just opened Sarvam Token Factory to everyone, an inference platform that serves its own models and leading open-weight models from GPU clusters in India.
The key idea is a shared cache at the center of the stack. A cache-aware router sends each request to the worker most likely to hold its prompt prefix. Prefill and decode run on separate B200 pools, so long prompts do not block streaming.
On Kimi K3.1 Pro, Sarvam reports 6,177 tokens/s per GPU vs 3,213 for InferenceX at 70 tok/s per user. On DeepSeek V4.1 Flash, it posts a 0.51 s first token from Mumbai vs 0.61 s on Together. It is a trade-off though: Together still streams DeepSeek V4.1 Flash at 278 tok/s vs 130 on Sarvam Standard, and all numbers are self-reported.
8 models are listed at launch, including Sarvam 105B, GLM 5.3, DeepSeek V4.1 Flash, Kimi K3.1 Pro and Gemma 4 31B. Sarvam 105B starts at ₹10 per 1M input tokens through one OpenAI-compatible API......
Full analysis: