Surge Releases Dayjob: Tax Benchmark for AI Agents on Professional Tasks
Surge AI introduces the Dayjob: Tax benchmark, featuring 50 real-world professional tax assignments to evaluate LLM agents' reasoning and compliance accuracy. Early results highlight significant disparities in handling implicit constraints like deadlines, exposing limitations of current AI agents in high-precision vertical tasks.
Full Report
Contents12 sections
October 27, 2026October 27, 2026No items found.
Table of contentsCase Study LlamaAnalysis of Individual writingsAppendix
Anna was planning to sell her condo. She had moved out in August 2024 and wanted to know whether closing in October 2026 or January 2027 would be better for taxes.
An AI agent reviewed both options and correctly concluded that either date would satisfy the residence requirement for a tax break worth up to $250,000 in excluded gains.
But it left out an important deadline.
Under the usual rules, homeowners must have lived in a property for at least two of the five years before selling it to qualify for the exclusion. Because Anna moved out in August 2024, she would stop satisfying that requirement around the end of August 2027. If her sale was delayed beyond August 2027, she could lose eligibility.
Across five attempts, Astra never identified the deadline. Opus identified it in all five attempts.
The agent evaluated the proposed dates correctly, but its advice left Anna unaware of a deadline that could affect a major financial decision. A tax adviser should recognize consequential issues even when the client doesn't know to ask about them.
This is the kind of professional judgment we're testing with DAYJOB: Tax, the latest addition to Surge AI's DAYJOB benchmark family.
Introducing DAYJOB: Tax
DAYJOB evaluates AI agents on professional tax assignments requiring specialized expertise, complex materials, and decisions that aren't fully specified in the initial instructions. Our earlier releases covered Healthcare and Finance. DAYJOB: Tax extends that work into tax preparation, compliance, and advisory services.
The benchmark contains 50 environments across eight areas of tax practice. Agents receive client requests and supporting records, then produce tax returns, workpapers, technical reviews, or client advice.
These assignments test professional judgment alongside tax knowledge, calculations, retrieval, and instruction following. Agents must decide what deserves investigation, resolve conflicting evidence, recognize when information is insufficient, and carry those decisions into their final work.
Results: Leaderboard and Pareto Frontiers
Claude Sonnet 5.5 leads with a 10.8% pass rate on the DAYJOB: Tax leaderboard, followed by Claude Fable 5.1 at 9.6% and Claude Opus 5.5 at 9.2%.

We report pass@1 at a 95% rubric threshold. An attempt passes when it satisfies at least 95% of the task's criteria, which assess calculations, supporting evidence, consequential issues, and the completed deliverable.
Performance versus cost
We also compared model performance against average cost per trial.
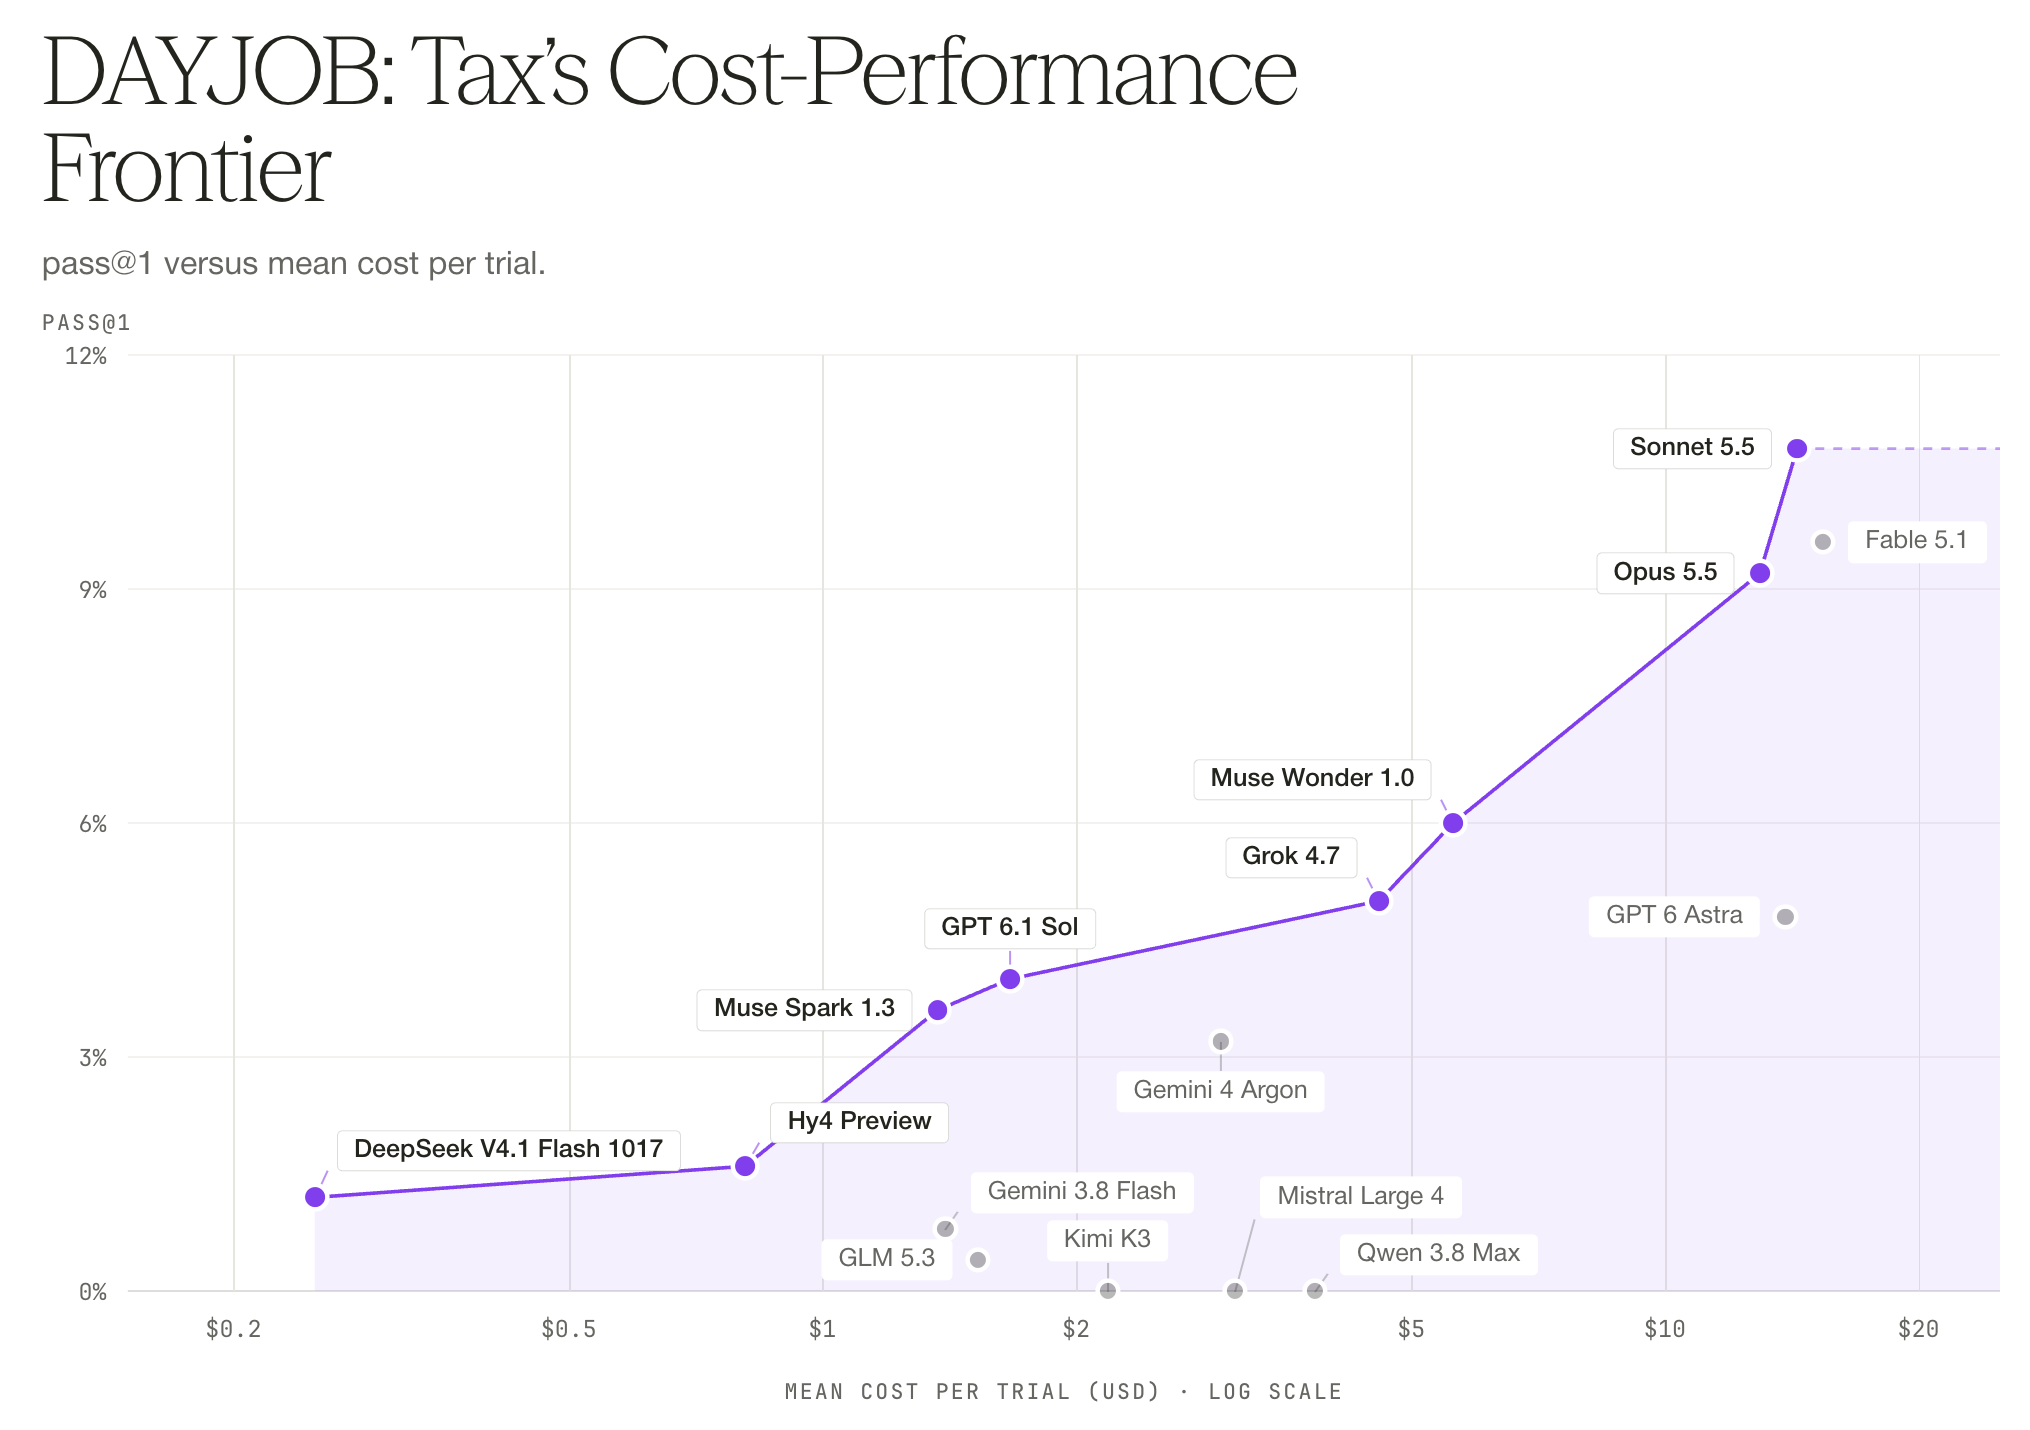
Claude Sonnet 5.5 and Opus 5.5 occupy the high-performance end of the measured Pareto frontier.
The breadth of professional tax work
DAYJOB: Tax covers eight areas, each requiring different rules, records, and expertise:
- Individual and family tax
- Small-business tax
- Partnerships
- Property and investments
- Estates, gifts, and trusts
- International tax
- Corporate transactions
- Tax review and disputes
Some assignments require complete filing packages with supporting workpapers. Others ask agents to investigate transactions, review previous filings, or prepare advice about decisions clients haven't yet made.
What's inside the assignments?
The benchmark contains 1,789 workspace files, with a median of 30 per assignment and as many as 123. These include 1,487 PDFs, 117 Excel workbooks, 38 Word documents, and additional emails, images, CSVs, JSON records, and text files.
The workspaces include filed and draft tax returns, K-1s, W-2s, IRS notices, general ledgers, payroll records, contracts, and correspondence. They also contain the less standardized evidence that tax professionals routinely work with.
One assignment includes a photograph of a handwritten receipt for merchandise purchased for resale. The agent must read the item descriptions and amounts, reconcile them with spending records, and determine how the purchases affect inventory and cost of goods sold.

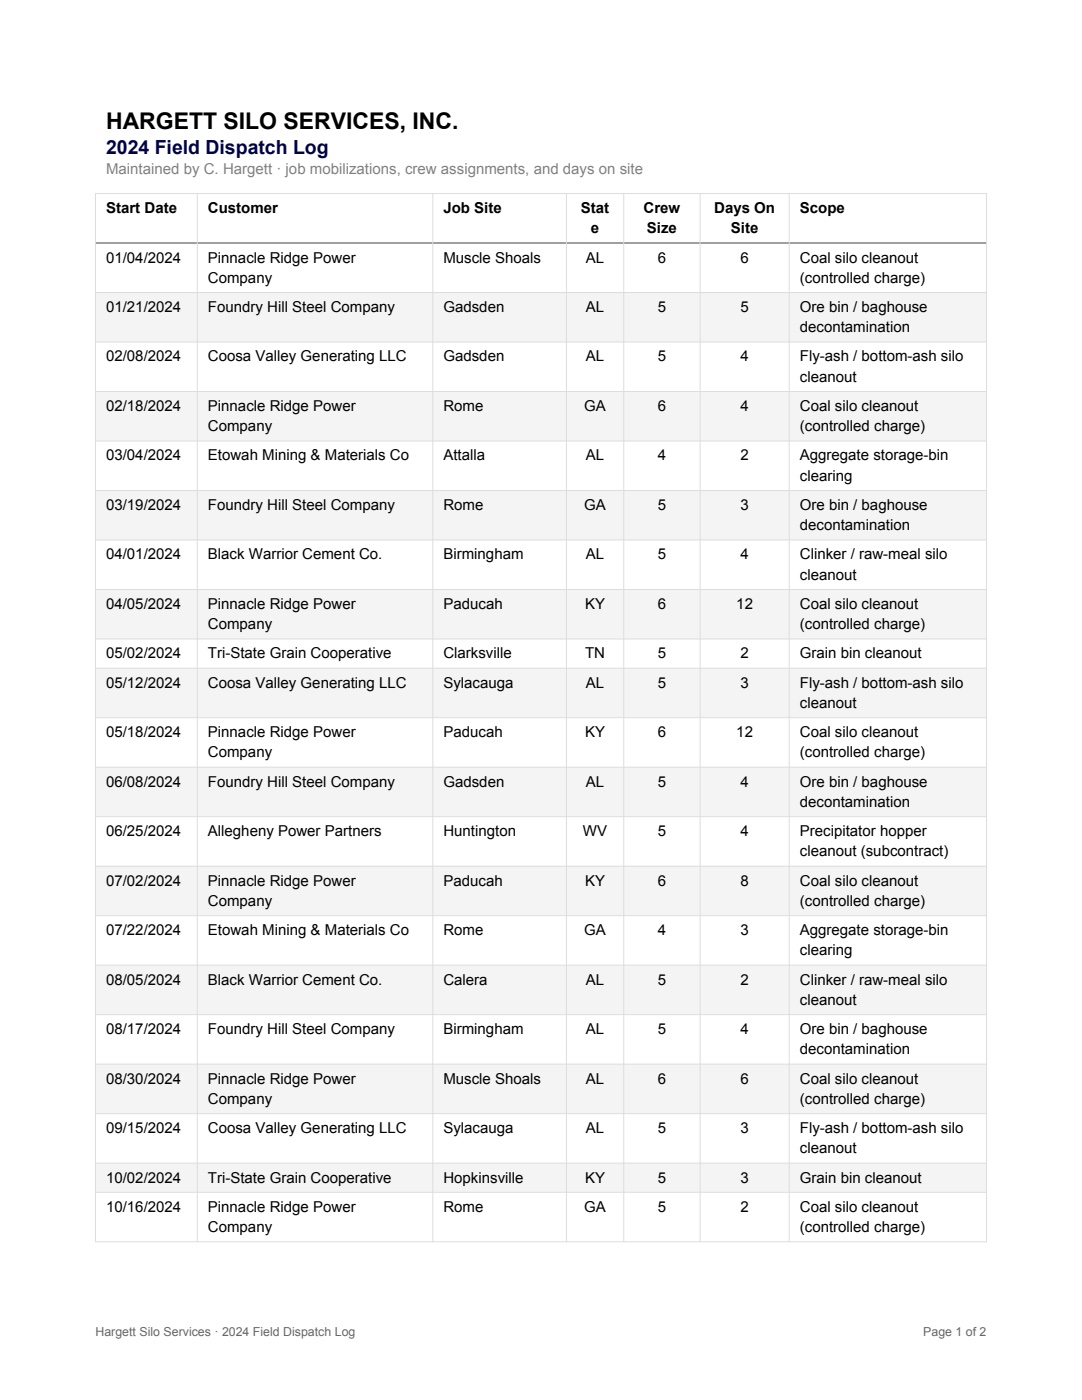
Another assignment involves an industrial silo-services company whose client assumes it operates only in Alabama. But its field dispatch log shows crews working across five states. The job locations, crew sizes, and days on site provide evidence relevant to the company's multistate tax obligations.
Other environments are similarly varied. One involves a cross-border household whose Polish employment and property records must be reconciled with cryptocurrency exchange exports, wallet histories, and historical purchase lots.
Created and reviewed by tax experts
DAYJOB tasks begin with real-world professional workflows. Tax experts turn these situations into realistic assignments, developing the supporting records, expected outcomes, and grading criteria. Each task undergoes a three-layer expert review for correctness, completeness, and solvability.
Tax experts bring experience across corporate taxation, partnerships, individual returns, trusts, and multistate compliance. Their backgrounds include:
- Corporate and private-equity taxation: A tax attorney with over 10 years of experience at PwC, Deloitte, and Exxon, covering tax planning, compliance, audits, and controversy.
- Partnership and corporate taxation: A Baker Tilly Tax Director with experience at PwC, Moss Adams, and Windes, specializing in complex partnership allocations, consolidated corporate returns, REITs, and high-net-worth clients.
- Real estate and individual taxation: A tax professional with experience at Deloitte and EY, specializing in real-estate partnerships, individual taxation, and trusts.
A retirement plan built on an unverified assumption
A separating couple asked an AI agent how to divide their Roth IRA and 401(k). Opus 5.5 told them they weren't legally married and recommended keeping their accounts separate, with a cash payment to even out the balances.
It opened one response:
You aren't legally married, so neither account can be split without triggering taxes and penalties.
But the couple's own records raised doubts about that conclusion. Although they now lived in Florida, where new common-law marriages generally aren't recognized, they had previously lived together in Texas and held a ceremony in Colorado. Texas recognizes informal marriages under certain conditions, and a valid marriage established elsewhere may remain valid in Florida.
That distinction could change the tax consequences of dividing their retirement accounts.
Across all five attempts, Opus based its recommendations around the assumption that the couple was unmarried, even when it acknowledged uncertainty. Astra recognized the need to verify their marital status in four of five attempts. One response advised:
We first need to confirm your legal marital status.
The client asked how to divide the accounts. The agent needed to establish whether they were married before recommending a course of action. The evidence that should have prompted that investigation was already in the files.
Where DAYJOB: Tax fits
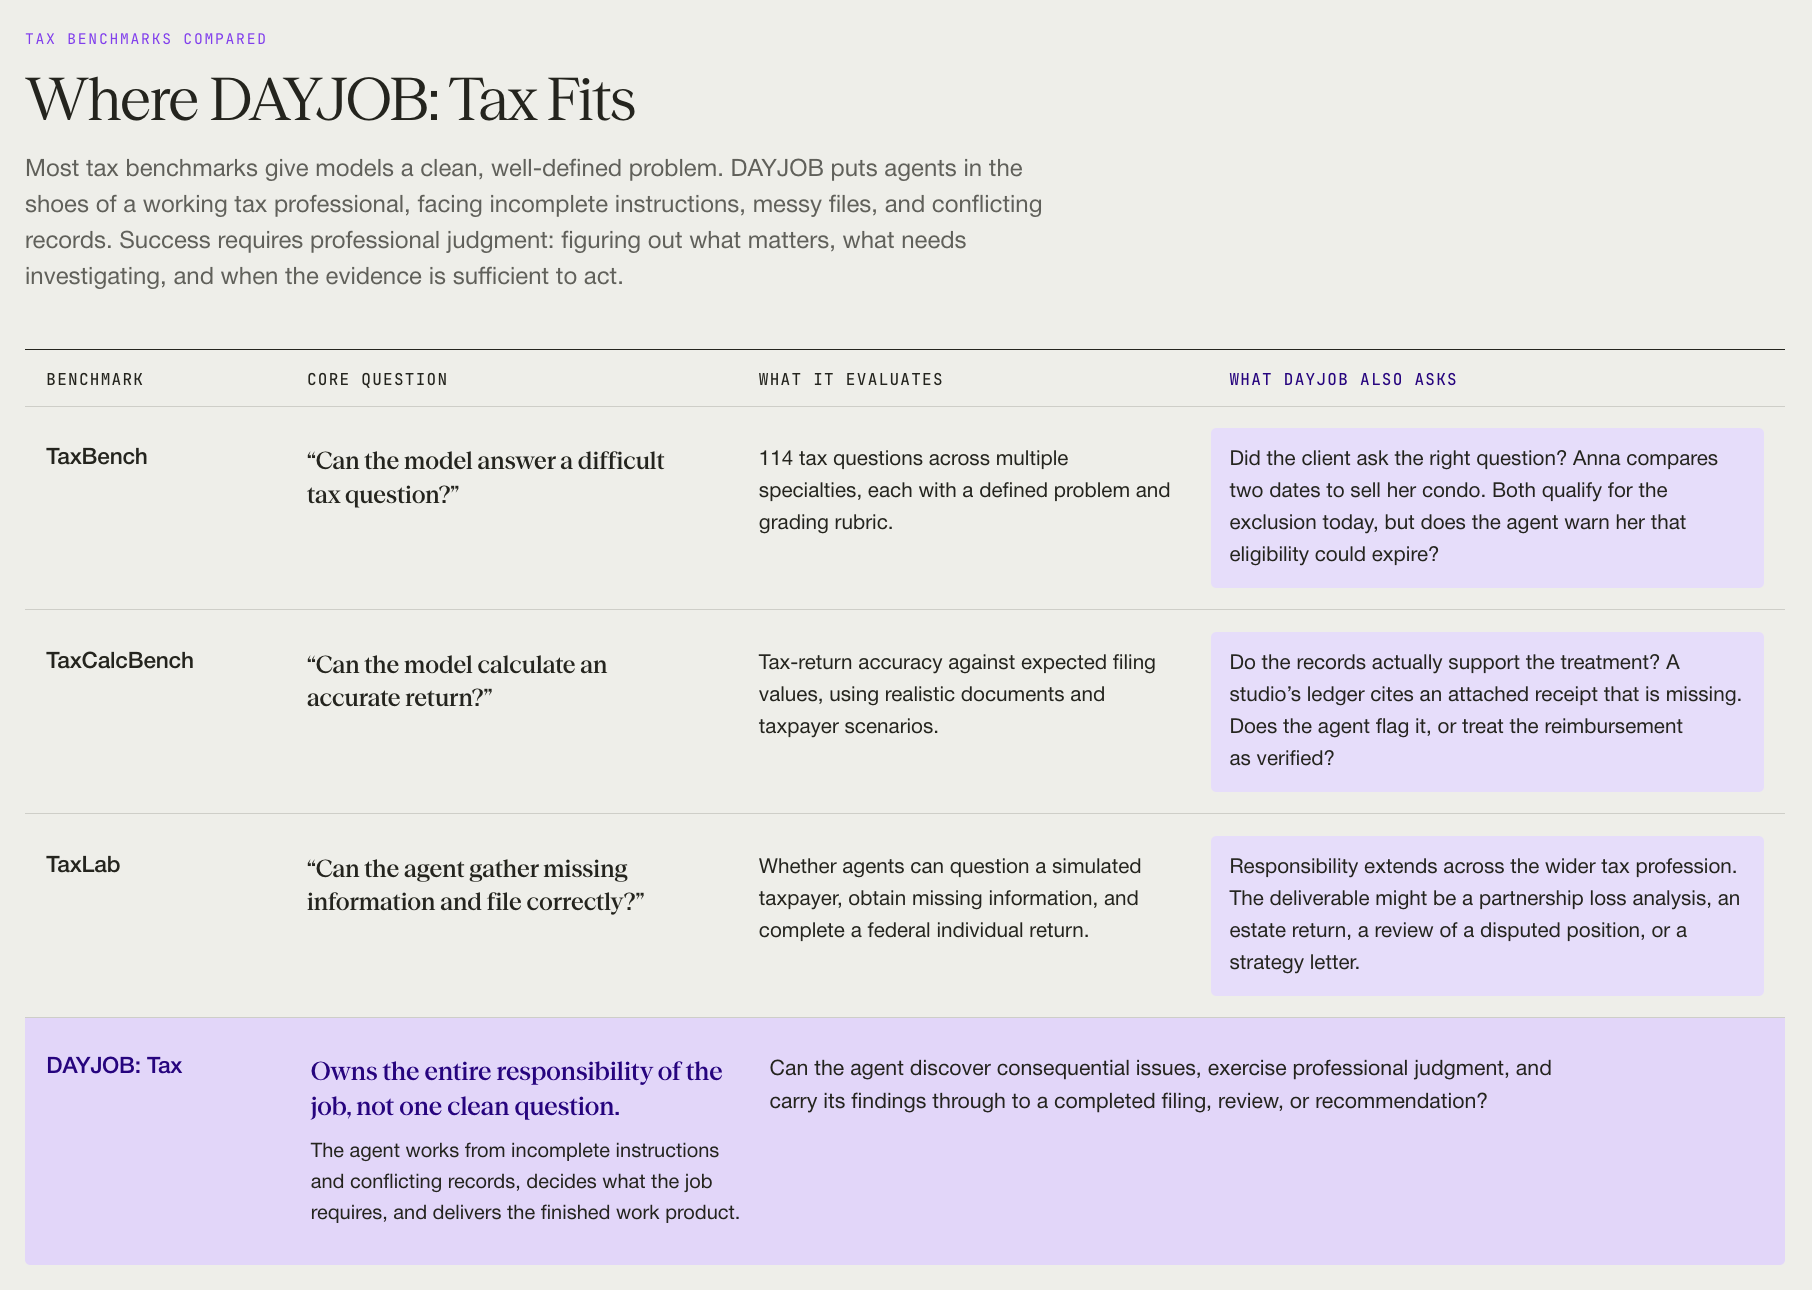
Most existing tax benchmarks begin with a defined problem: a legal question to answer, a return to calculate, or missing taxpayer information to collect. These evaluations measure important capabilities, but much of a tax professional's work involves figuring out what the problem actually is. Clients provide incomplete instructions, records contain conflicting evidence, and consequential issues may never appear in the original request.
DAYJOB tests whether agents can handle that end-to-end responsibility, including identifying issues the client overlooked, evaluating conflicting evidence, and deciding what needs to be done in the first place.
TaxBench
Can the model answer a difficult tax question?
TaxBench evaluates 114 tax questions across multiple specialties, each with a defined problem and grading rubric.
DAYJOB also asks whether the client asked the right question. Anna wants to compare two dates for selling her condo. Both satisfy the residence requirement for a tax exclusion, but does the agent warn her when that eligibility could expire?
TaxCalcBench
Can the model calculate an accurate return?
TaxCalcBench evaluates tax-return accuracy against expected filing values, using realistic tax documents and taxpayer scenarios.
DAYJOB also asks whether the underlying records actually support the tax treatment. A studio's ledger references an attached receipt, but the receipt is missing. Does the agent flag the missing evidence or incorrectly treat the reimbursement as verified?
TaxLab
Can the agent gather missing information and file correctly?
TaxLab tests whether agents can question a simulated taxpayer, obtain missing information, and complete a federal individual tax return.
DAYJOB extends that responsibility across the wider tax profession. The deliverable might be a partnership loss analysis, an estate return, a review of a disputed tax position, or a strategy letter.
The central distinction is how much responsibility remains with the agent. DAYJOB evaluates whether agents can discover consequential issues, exercise professional judgment, and carry their findings through to a completed filing, review, or recommendation.
What DAYJOB: Tax measures
DAYJOB tests whether AI agents can take ownership of a professional assignment from start to finish. That means navigating messy records, identifying issues the client never raised, making sound judgments with incomplete information, and delivering work that meets professional standards.
The results show how difficult that remains for frontier models. Even when agents can perform the individual steps, exercising professional judgment and reliably carrying out real-world tax workflows remain out of reach.
Agents haven’t yet passed the audit.
The full leaderboard, with every model we evaluated, is on the DAYJOB: Tax benchmark page.
To learn more or request access to the full benchmark, contact [email protected].
BenchmarkDAYJOB: TaxVIEW LEADERBOARD/surge-ai@hellosurgeaiDAYJOB: Tax — Benchmarking AI Agents on Professional Tax Worksudo L7: Can Coding Agents Act Like Staff Engineers?GDP.xlsx: Can Agents Understand the Spreadsheets That Run the World?What Does GDP.pdf Teach — Beyond PDFs?DAYJOB: Can Agents Survive a 9 to 5?Helping Anthropic Build Automated Alignment ResearchersHill-Climbing a SWE Agent: What 1,700 Coding Tasks Taught Kimi K2.7Fable 5.1, Muse Spark 1.3, and Gemini 3.8 Flash on the Tuesday Work IndexDeepSeek V4 Pro Scores 59.7 on the Tuesday Work IndexQwen 3.8 Max Scores 58.7 on the Tuesday Work IndexIntroducing the Tuesday Work Index: Can AI Get Through an Ordinary Day?We Trained a Model on Office Work. It Also Got Better at Coding.Chartography: A Benchmark for Professional Chart UnderstandingOpenAI cites GDP.pdf in its GPT-5.6 releaseTraining on ComplexConstraints: +10.1 on MultiChallenge, +8.5 on AdvancedIFHANDBOOK.md Benchmark: Can Agents Follow 100-Page Company Policies?Anthropic cited GDP.pdf and Riemann-bench in their Fable 5 and Mythos 5 system cardComplexConstraints: A Benchmark for Entangled Instruction FollowingMicrosoft used Surge human evaluations to benchmark MAI-Thinking-1Training on Long-Horizon Agent Tasks: +9.6 on Toolathlon, +5.3 on τ²-BenchAntidote Leaderboard: Optimizing for YouGDP.pdf Benchmark: Can Frontier Models Master the Documents that Run the World?Riemann-bench: A Benchmark for Moonshot MathematicsEnterpriseBench: CoreCraft – Measuring AI Agents in Chaotic, Enterprise RL EnvironmentsHemingway-bench: The AI Writing Leaderboard Judged by Expert WritersBuilding AdvancedIF: Evolving Instruction Following Beyond IFEval and “Avoid the Letter C”LMArena is a cancer on AIRL Environments and the Hierarchy of Agentic CapabilitiesHow do frontier models perform on real-world finance problems?A Product Take on Sonnet 4.5Is Sonnet 4.5 the best coding model in the world?The Human/AI Frontier: A Conversation with Bogdan GrechukSWE-Bench Failures: When Coding Agents Spiral Into 693 Lines of HallucinationsBenchmarks are brokenUnsexy AI Failures: The PDF That Broke ChatGPTBringing light to the GPT-4o vs. GPT-5 personality controversyDALL·E 3 and Midjourney Fail Astral Codex Ten's Image Generation BetHow Anthropic uses Surge AI to Train and Evaluate ClaudeWe Evaluated ChatGPT vs. Google on 500 Search QueriesAI Red Teams for Adversarial Training: How to Make ChatGPT and LLMs Adversarially RobustHellaSwag or HellaBad? 36% of this popular LLM benchmark contains errorsHow TikTok is Evolving the Next Generation of SearchEvaluating Generative AI: Did Astral Codex Ten Win His Bet on AI Progress?Why Instagram is Losing Gen Z: We Asked 100 Users to Compare TikTok vs. ReelsThe $250K Inverse Scaling Prize and Human-AI AlignmentSearch Behind-the-Scenes: How Neeva Uses Human Evaluation to Measure Search QualityHuman Evaluation of Large Language Models: How Good is Hugging Face’s BLOOM?30% of Google's Emotions Dataset is MislabeledAI Red Teams and Adversarial Data Labeling with Redwood ResearchHumans vs. Gary Marcus vs. Slate Star Codex: When is an AI failure actually a failure?How Surge AI Built OpenAI's GSM8K Dataset of 8,500 Math ProblemsWe asked 100 humans to draw the DALL·E promptsGoogle Search is Falling BehindMoving Beyond Engagement: Optimizing Facebook's Algorithms for Human ValuesHoly $#!t: Are popular toxicity models simply profanity detectors?Is Google Search Deteriorating? Measuring Google's Search Quality in 20225 Examples of the Importance of Context-Sensitivity in Data-Centric AISurge Leaderboards Join the Fireworks Specialized Intelligence Index
sudo L7: Can Coding Agents Act Like Staff Engineers?Introducing sudo L7, a coding benchmark testing whether AI agents can go beyond correct code and exercise staff-level engineering judgment.read postOctober 8, 2026
GDP.xlsx: Can Agents Understand the Spreadsheets That Run the World?GDP.xlsx tests whether frontier agents can read the professional spreadsheets that run the world. It spans 70 tasks across 12 knowledge-work domains: finance, healthcare, engineering, manufacturing, insurance, real estate, legal, human resources, agriculture, energy, logistics, and public sector.read postSeptember 30, 2026
What Does GDP.pdf Teach — Beyond PDFs?Post-training on GDP.pdf improved Kimi K2.7 on GDPval, including tasks without PDFs, and changed how it gathered information and used tools before building deliverables.read postSeptember 29, 2026
DAYJOB: Can Agents Survive a 9 to 5?Introducing DAYJOB, Surge AI’s benchmark family for economically valuable agents: realistic requests in complex environments, requiring end-to-end professional judgment.read postSeptember 23, 2026
Helping Anthropic Build Automated Alignment ResearchersAnthropic recently published new work on automated alignment researchers. Surge contributed to the research by building the human baseline, including researcher recruitment, structured submissions, quality control, and expert review.read postSeptember 15, 2026
Hill-Climbing a SWE Agent: What 1,700 Coding Tasks Taught Kimi K2.7We post-trained Kimi K2.7 on 1,700 Surge agentic coding tasks. The trained model improved on all external benchmarks we tested, including +20.0pp on SWE-Marathon, +12.4pp on DeepSWE, and +7.6pp on Terminal-Bench 4.read postSeptember 11, 2026Appendix