ModelBest Open-Sources ForgeKernel: AI Agent Beats DeepSeek's Hand-Written Operators by 9.8%
ModelBest has open-sourced 'ForgeKernel', an autonomous agent that generated a FlashMLA Prefill operator outperforming DeepSeek's hand-written version by 9.8% on NVIDIA B200 after 22.5 hours of self-evolution without human code. This milestone demonstrates AI's capability to autonomously optimize low-level infrastructure, signaling a paradigm shift from manual coding to AI-generated solutions with human architectural oversight.
Full Report
Contents3 sections
Jin Lei, reporting from Ao Fei Si QbitAI | Official Account: QbitAI
No source code. No paper. Starting from scratch.
Just this morning, ForgeKernel, an autonomous Agent, publicly demonstrated—without referencing DeepSeek’s original implementation—that it could optimize DeepSeek’s latest core operator by 9.8%.
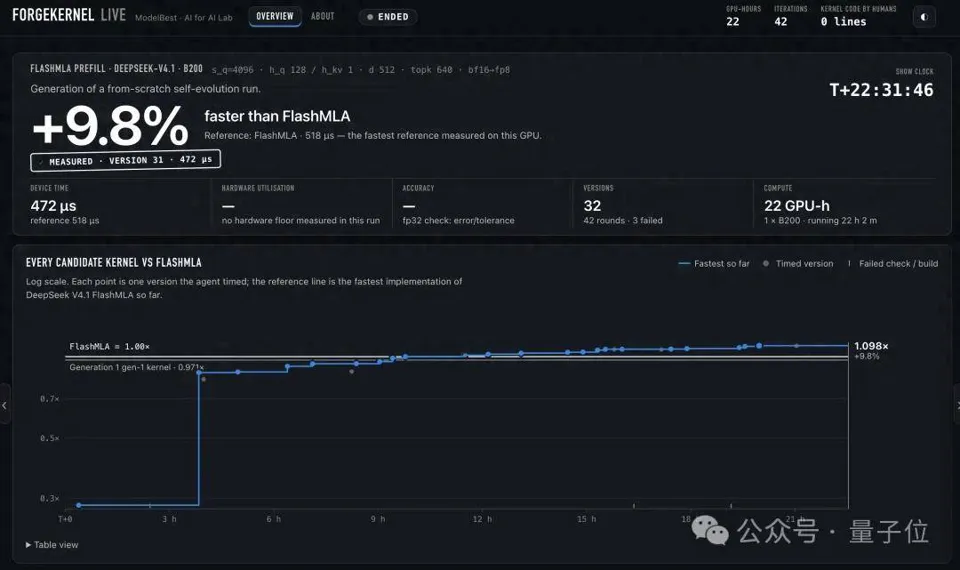
The entire live-streamed process took only 22.5 hours (a remarkably short duration from the perspective of operator design), attracting significant attention from netizens:
Specifically, the live stream featured an Agent on an NVIDIA B200 GPU surpassing the performance of DeepSeek-V4.1’s FlashMLA Prefill operator.
FlashMLA is DeepSeek’s open-source core attention operator library; it was also integrated into DeepInfer, the inference framework released on October 20. Developed by a team widely recognized as having the strongest infrastructure capabilities in the industry, FlashMLA represents the peak of human-written operators.
As mentioned earlier, the AI was provided only with the mathematical definition of the operator and target hardware constraints. It had to start from "zero frames" (from absolute scratch), improving itself through iterative self-evolution.
Over these 22.5 hours, every rewrite and every fluctuation in performance metrics was displayed transparently to the global audience:
- The first version passed correctness checks but took 1,834 microseconds, resulting in relatively low efficiency;
- Within less than 4 hours, latency dropped to 593 microseconds—a reduction of approximately 67.6%, bringing it close to 90% of the current best implementation’s performance;
- Around the 7-hour mark, a breakthrough in the core structure allowed it to first surpass its previous iteration, and then exceed FlashMLA for the first time;
- By past 9 AM, the live stream concluded. The final version achieved a latency of 472 microseconds, compared to FlashMLA’s 518 microseconds—making it 9.8% faster.
Throughout the process, there were 42 iterations, yielding 32 versions, utilizing 1 B200 GPU and 22 GPU-hours. Meanwhile, the amount of code written by humans for this operator was 0 lines.
The peak of human craftsmanship was thus surpassed by an operator containing not a single line of human-written code.
So, what exactly is this Agent?
It is ForgeKernel, the operator generation system from ModelBest; immediately following this live stream, the Intelligent Evolution Lab, in collaboration with the OpenBMB community, announced that it would be open-sourced.
However, this live stream was not ForgeKernel’s debut. A few days prior, it had already gained fame once.
Sweeping Three Firsts on Domestic Computing Power Platforms
On October 27, Ascend CANN officially published an article "naming" ForgeKernel—
Simultaneously topping the CANNBench leaderboards for three hardware platforms: 950DT, 950PR, and A3!
These three leaderboards correspond to three types of Ascend hardware, each with distinct highlights regarding their performance metrics.
Let’s first look at the 950DT leaderboard, which offers the clearest picture of economic value among the three.
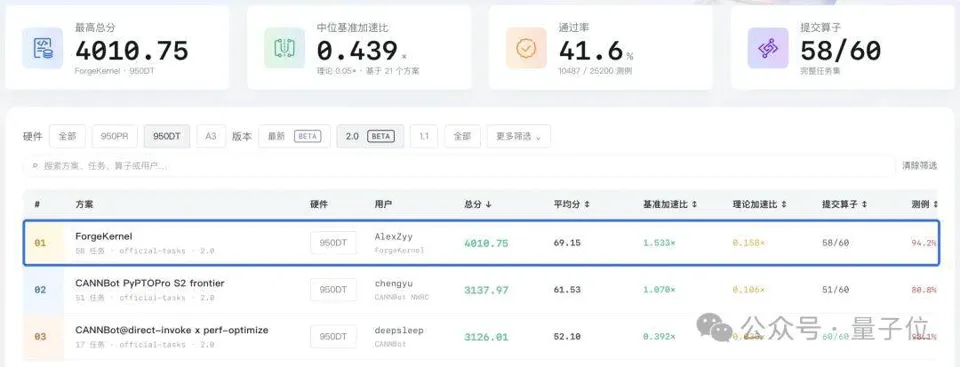
ForgeKernel ranked first on this board with a score of 4,010.75, leading the second place by 27.8%; its baseline speedup ratio was 1.533×, approximately 143% of the second-place entry.
This means that with equivalent hardware investment, usable computing power increases by nearly 50%, allowing enterprises to reduce their computing procurement and deployment costs by roughly half.
The reason this leaderboard is noteworthy is that the 950DT is a new-generation chip whose accompanying operator library is still in the early stages of development. Manual adaptation cycles are long, yet ForgeKernel completed the adaptation first and topped the rankings.
This indicates that as soon as new hardware launches, AI can rapidly produce high-quality operators, significantly compressing the gap between chip release and full adaptation.
950PR features the most intense competition among the three boards, with the top three entries all achieving baseline speedup ratios above 1.3×:
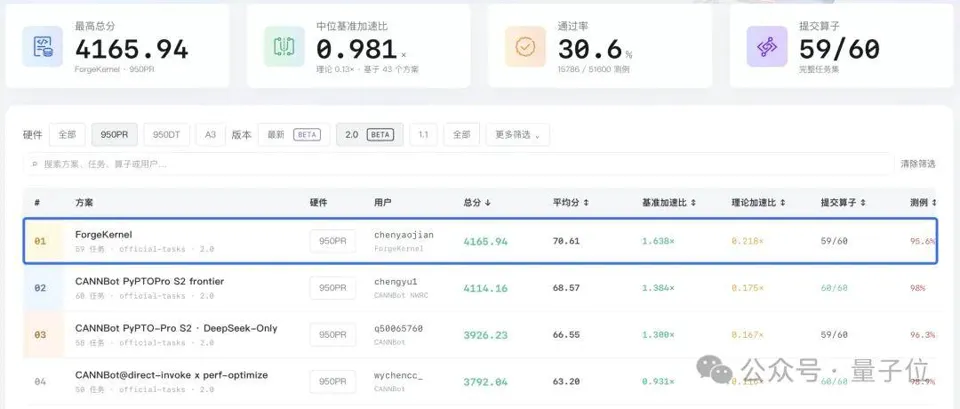
ForgeKernel again ranked first on this board with a total score of 4,165.94; its baseline speedup ratio was 1.638×, approximately 1.18 times that of the second-place entry.
Finally, there is A3, which corresponds to the currently widely used Ascend 910C.
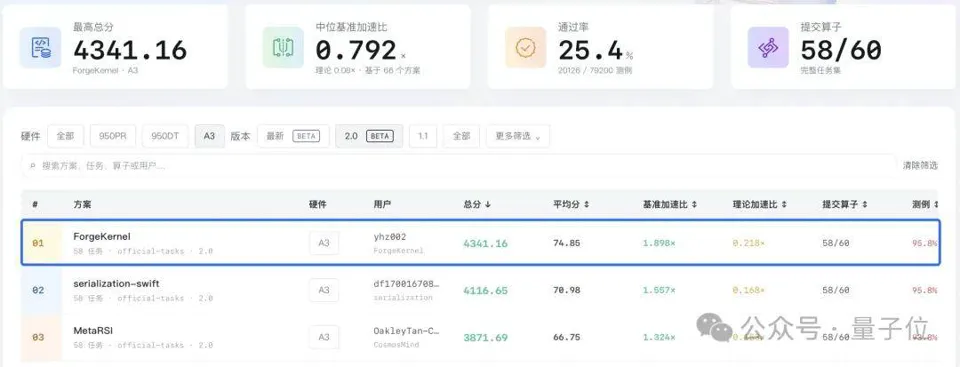
As early as October 15, when CANNBench v1.1 closed, it had already secured first place on the A3 hardware leaderboard; after v2.0 opened, it has maintained this position without yielding. Currently, it holds a total score of 4,341.16, with a baseline speedup ratio of 1.898×, approximately 1.22 times that of the second-place entry.
In this live stream, ForgeKernel ran on an NVIDIA B200 using CUDA—an ecosystem built upon years of accumulated expert experience. In contrast, these three leaderboards were run on Ascend hardware, which possesses its own independent architecture and toolchain.
Despite the significant differences in software and hardware between the two ecosystems, ForgeKernel managed to achieve first place on both using the same system.
The next question is: How did it accomplish this?
Self-Taught Mastery
The ultimate speed of a model largely depends on its operators.
For the same model running on the same chip, switching to a more efficient operator set can result in a noticeable performance gap.
For a long time, high-performance operators have relied on senior engineers hand-writing and tuning them individually—a process characterized by long cycles and high barriers to entry. The CUDA ecosystem has reached its current state through years of expert accumulation; meanwhile, every time domestic chips release new hardware or new models emerge, re-adaptation is required.
In short, the number of human experts cannot keep pace with the iteration speed of chips and models.
So, how can this dilemma be resolved?
On October 27, the ForgeKernel team, along with institutions such as Tsinghua University, published a paper on arXiv titled JustGoal: With Only a Goal, the AI Baseline Is Above the Expert Kernels.
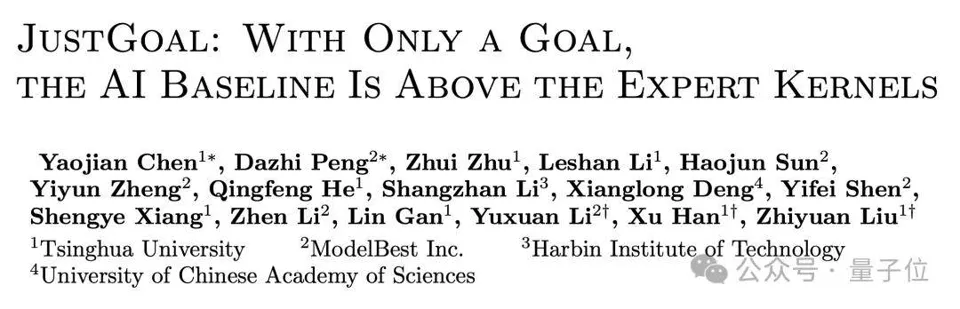
In this paper, the research team provided the model with only a single optimization objective. They offered no operator knowledge and prescribed no fixed workflow, allowing the model to write code entirely on its own. The result: on the B200 GPU, the model outperformed human-maintained open-source libraries in 8 out of 10 operators.
They also tested the same model using KDA-0.5, a specialized framework co-developed by Han Song’s team at MIT. Surprisingly, the average performance on single-configuration optimization tasks was only 0.95× that of "JustGoal" (the pure objective-driven approach). This indicates that writing operators increasingly relies on the model's inherent capabilities, while the value of pre-encoded expert experience and rigid workflows is diminishing.
However, relying solely on objectives has its limitations. While models excel at fine-tuning details, they struggle to independently design robust overall architectures. Often, early attempts lock the model into a suboptimal path, leaving it unable to do more than micro-adjust within that existing structure. ForgeKernel was designed specifically to address this weakness building upon the JustGoal approach.
Its methodology consists of three parts:
- Separating architecture design from implementation: Abstracting architecture design into milestones to decompose the problem.
- Building a hardware knowledge base: Storing every empirically verified hardware insight so it can be reused across different operators.
- Self-evolution: Treating the best version generated so far as the opponent for the next round, iterating through self-improvement cycles.
These three components correspond directly to the live demonstration shown earlier.
ForgeKernel first surpassed its previous generation before beating FlashMLA—this is self-evolution in action.
Later in the process, the agent independently discovered that burst loading of Q tensors was competing with KV data transfers for memory bandwidth. It proactively controlled the request pacing for Q, reducing latency by another 2.4%. Previously, such judgments required senior experts.
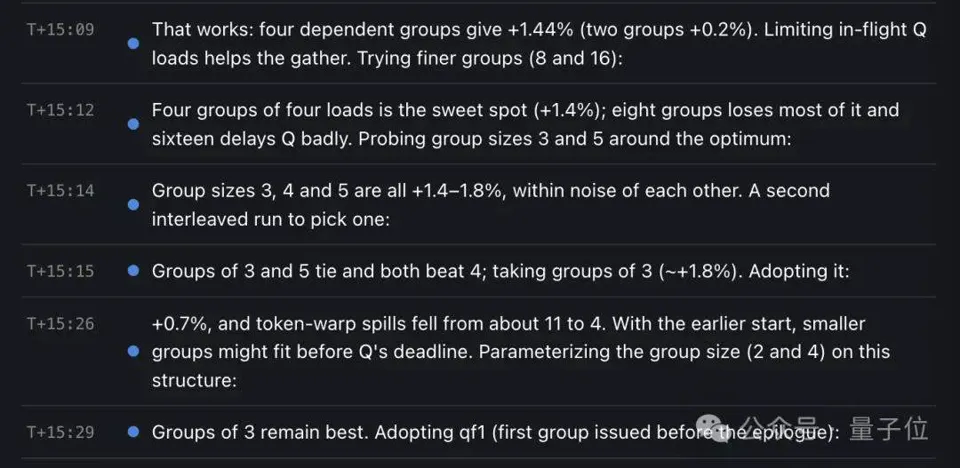
△ Agent execution logs from the ForgeKernel Live demo
When applied to a broader range of operators, ForgeKernel matched or exceeded expert implementations in 24 out of 29 comparisons. It also matched or surpassed the top 7 strongest operators publicly released by three leading agentic systems.
This benefit is replicable across different domestic chips because ForgeKernel’s design does not depend on specific hardware.
While concrete operator implementations must adhere to the hardware characteristics of each chip and cannot simply be copied, ForgeKernel’s optimization methodology is universal, with no preset workflows for any specific chip. When switching from NVIDIA to Ascend, one only needs to replace the profiling tool NCU with msprof. The necessary hardware knowledge for the new chip is accumulated by the model through testing on that platform.
Consequently, ForgeKernel can quickly migrate to other domestic chips. When new generations of domestic chips are launched, there is no need to build an adaptation pipeline from scratch.
Real Financial Savings
What does a 1% speedup in operators actually mean?
According to Gartner’s latest forecast, global AI infrastructure spending will reach approximately $1.48 trillion in 2026. At this scale, every 1% improvement in compute efficiency corresponds to roughly $14.8 billion.
The impact is even more pronounced when considering domestic chips.
NVIDIA’s CUDA ecosystem has been optimized by experts for years, resulting in many high-performance off-the-shelf operators. Consequently, the room for further acceleration via AI is limited. In contrast, the operator libraries accompanying domestic chips are still immature, with many operators lacking thorough tuning. Therefore, the improvements driven by AI are significantly more substantial.
The ForgeKernel team observed this disparity when optimizing training frameworks with AI. The same techniques yielded a 20–30% speedup on domestic chips compared to 5–10% on NVIDIA hardware. This means ForgeKernel can further enhance the cost-performance ratio of domestic chips for both training and inference tasks, narrowing the gap with NVIDIA.
Once coding becomes virtually cost-free for AI, optimizations previously deemed too expensive due to expert labor costs become viable. For example, customizing a set of operators specifically for a certain model or chip.
In fact, these operators, which surpass human expert implementations, have moved beyond benchmarks and are already deployed in real-world industrial scenarios.
Currently, operators generated by ForgeKernel have been officially integrated into training frameworks, completing long-term training tests for MiniCPM5-1B on both domestic chips and NVIDIA platforms.
More notably, in this restructuring of the underlying compute layer, domestic large models represented by DeepSeek V4.1 have begun participating in operator generation and optimization. These operators ultimately run stably on domestic chips.
“Domestic models write operators; domestic chips run operators.” A full-stack ecological loop belonging to China’s AI sector is taking shape.
This is not just a victory for operators, but a tangible manifestation of RSI (Recursive Self-Improvement): The primary actor in AI R&D is shifting from humans to AI.
As Li Yuxuan, Chief Scientist of Intelligent Evolution at ModelBest, stated, because code can be rapidly verified by machines, engineering implementation will achieve closed-loop success ahead of theoretical research:
In the past, top-tier operators requiring deep architectural refactoring, such as those in the FlashAttention series, often took human experts months or even half a year to complete a single iteration. Today, within our team, AI completes operator optimization tasks that surpass the best human implementations in at most two days.
With the official open-sourcing of ForgeKernel, this methodology will serve as infrastructure, providing a new efficiency pathway for domestic chip manufacturers and model teams.
Previously, the difficulty for domestic chips in catching up with NVIDIA lay not in hardware metrics, but in the decade-plus accumulation of expert experience and software layers within the CUDA ecosystem. However, under the RSI paradigm, AI is breaking down these barriers built by manual effort over years, generating optimal solutions end-to-end directly.
When “domestic models write operators, domestic chips run operators” becomes the new paradigm for operator engineering, the subject of R&D may be irreversibly shifting from humans to models. But this does not mean human experts are exiting the stage; rather, their focus is undergoing a fundamental leap:
From manually polishing every line of low-level code to setting up environments, defining objectives, and establishing verification standards for AI, thereby enabling AI to write better operators.
As humans transition from code craftsmen to system architects, the gap between “running” and “running well” for domestic chips is being rapidly bridged by AI, measured in hours rather than years.