InfoQ 中文 · 10/16/2026, 12:04:03
Pi Launches Durable Framework and Native MCP Support for Agents
Pi has upgraded to version 1.0, launching the new Pi Durable infrastructure framework and officially integrating the Model Context Protocol (MCP). Pi Durable handles state management, crash recovery, and task scheduling, significantly reducing boilerplate code for long-running agents. Additionally, Pi reversed its previous stance on MCP, adopting a progressive disclosure mechanism to balance token efficiency with tool compatibility.
SOURCE COVERAGEFull Original Report
Contents10 sections
Pi has received its largest update of the year: the project has upgraded to version 1.0, with Code Mode and native MCP officially entering stable release; on the same day, the team also launched a brand-new Harness—Pi Durable.
These changes have been brewing for some time. Over the past year, the MCP protocol underwent six or seven rounds of adjustments, gradually evolving into a truly usable state; the architecture of Pi Durable went through eight iterations. A protocol once publicly rejected by Pi has now entered its core, while a meticulously refined long-running Agent framework debuted simultaneously, marking Pi’s expansion from a terminal-based coding Agent toward comprehensive Agent infrastructure.
For developers, the most intuitive value of Pi Durable is eliminating a significant amount of repetitive code. Previously, when building personal assistants, Slack Bots, or other Agent applications on Pi, developers had to design their own databases to store messages, then handle Agent startup, task scheduling, process crashes, and state recovery. Some developers estimate that Pi Durable can directly replace half of their code, as these peripheral details are now managed by the framework.
This also explains why some believe Pi Durable will become the foundation for many Agent workflows and applications. In the past, every company repeatedly implemented conversation logging, task persistence, fault recovery, and session forking. Pi Durable fills this gap perfectly. It saves user messages, model responses, tool execution results, and task states; after a process crash, the Agent can resume exactly where it left off. Operations that can be safely replayed are re-executed, while those that might cause duplicate side effects are not blindly rerun.
Mario Zechner summarized it simply: An Agent starts up, calls tools, and the process suddenly dies; upon restart, it should accurately continue from where it stopped, without requiring humans to type "continue" again, and tool results and streaming outputs must not be lost. Armin Ronacher focuses more on the reliability behind it: The models themselves are already sufficiently unpredictable; when Agents begin operating without real-time human monitoring, the outer layer of task orchestration and fault recovery should at least be stable and understandable.
Another controversial change comes from MCP.
Over the past year, Pi founder Mario Zechner and Flask founder Armin Ronacher have been among the most outspoken critics of MCP. Pi’s official website even proudly stated "No MCP support." They publicly criticized MCP for being bloated and wasting tokens, arguing that Agents using Bash, CLI tools, and code are often more efficient.
Now that models have undergone more training related to MCP, and MCP Servers and protocols have gradually matured, Pi finally decided to officially integrate it. However, instead of stuffing all tool names, parameters, and descriptions into the context at once, it uses tool search and progressive disclosure to load them on demand.
Code Mode, which also entered stable release alongside MCP, allows Agents to write and run JavaScript programs within a QuickJS sandbox. It can call tools in parallel, filter data, deduplicate, and perform calculations, sending only truly useful results back to the model. Large amounts of intermediate data remain in the sandbox, thereby reducing token consumption, operational costs, and context burden.
Code Mode has another interesting capability: it can directly call System 1 models, such as Jev, inside JavaScript loops. For example, if Pi retrieves 200 GitHub comments via MCP, Code Mode can pass each comment individually to Jev to determine whether the user is dissatisfied, whether the issue is urgent, and which category it belongs to. GPT or Claude ultimately only needs to see the classified and summarized results. MCP handles data retrieval, Code Mode handles orchestration and processing, Jev handles rapid judgments, and frontier models focus on high-level reasoning.
However, some Pi users are not happy. One commented: "So Pi is starting to accumulate junk too." This statement represents the concerns of the minimalist camp: As MCP, Code Mode, and more capabilities enter the core, will Pi slowly turn into the bloated Harness it previously tried to avoid?
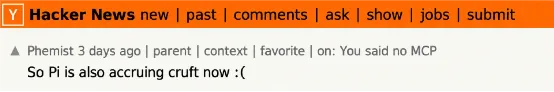
Armin responded that the content loaded by default in Pi has not increased compared to before. Code Mode is not just "Bash with extra steps": Bash runs Shell tools, whereas Code Mode allows the model to directly search, combine, and orchestrate tools within the Harness. Pi has accepted the MCP ecosystem while still controlling the burden it places on the context.
Interestingly, while the Pi team enables Agents to use more tools and run for longer periods, they remain reluctant to fully entrust all work to them. Mario admitted frankly that Agents can fix many small issues, but when it comes to design and architecture, they often just pile up code locally, "shitting all over your codebase and making things worse."
When Agents can finally survive crashes and run continuously for hours or even days, new problems arise: They won’t easily stop anymore, but who guarantees they haven’t turned the codebase into a shit mountain along the way?
Recently, Mario Zechner and Armin Ronacher discussed the design of Pi Durable, the boundaries of AI programming capabilities, and why Pi doesn’t want to remain just a coding Agent in a podcast. InfoQ translated and organized this conversation. Below is the edited full transcript.
TL;DR
Q: Why not let Coding Agents fix bugs?
Armin: Because it’s almost impossible for them to solve problems without touching the code. The more you trust fully automated processes, the more the codebase naturally grows with every bug fix.
Q: Is AI-written code actually usable?
Mario: It depends on the level. Much of Pi’s TUI library is pure slop; I haven’t looked at a single line of code in the markdown or text components to this day. I don’t care, as long as tests pass and rendering is correct. But once it involves design or architecture, humans are still needed, because Agents just "shit in place" within the codebase, making things worse.
Q: Has model architectural capability actually improved?
Armin: No, it may have even regressed. Their outputs are becoming increasingly complex, their speech patterns weirder, filled with technical jargon pulled straight from a thesaurus.
Q: Why can't models learn architecture?
Mario: Because architecture is the only part of programming that hasn't been encoded into text, and therefore LLMs cannot learn it. You can easily build training data for cybersecurity, website creation, or frontend development, but the process of "building" itself—designing and architecting something—has no training data.
Q: What tasks are models particularly good at?
Mario: Tasks with an Oracle, binary outcomes, or those amenable to fuzzing. If you have an Oracle that can tell the LLM whether it's right or wrong, you've basically won. Bun's Rust rewrite relied on this; just getting the test suite to pass was enough.
Q: What is Pi Durable?
Mario: An Agent starts in a process, calls tools, the process crashes, restarts, and resumes exactly from the breakpoint. But Pi Durable doesn't use event sourcing; instead, it uses an "effect sandwich" of "intent, execution, result," along with versioned document storage to apply state.
Q: Is personal Agents viable?
Armin: Millions of people are using things like Grok Bot, logging everything onto their machines. I think that’s a disaster waiting to happen. All these companies are facing a potential catastrophe.
Q: What does Earendil want to do next?
Armin: We don’t want to become a Coding Agent company. There are two tracks: one is building products that allow non-engineers to find joy; the other is building infrastructure so everyone can construct their own Agents.
Q: What is the future direction for Pi?
Mario: I’ve recently been working on PIM (Pi Mobile) on my phone. It’s no longer about "me and Clanker," but many Clankers on many machines interacting with many people.
Agents Fix Bugs, But Also "Shit On" The Codebase
0xSero: Why did you decide to acquire Pi?
Armin: Actually, before acquiring Pi, we spent a long time trying to bring Mario on board. After the OpenClaw frenzy, the opportunity arose, and Mario became open to the idea. We work on "malleable software," and Pi was a great early experiment in that regard, so acquiring it made sense.
Mario: Only an idiot would create Pi. Now I’m stuck here farming it.
0xSero: Do you really feel trapped by this project? It’s so successful that stopping wouldn’t make sense.
Mario: Like Armin, I have a long history with open source, though we come from different fields. Once an open-source project I created gains users, I foolishly keep maintaining it for everyone, even if they haven’t paid a cent. Sometimes, negative feedback is truly draining.
However, my current goal isn’t to hand off Pi, but to get more people involved in its development, thereby reducing the "bus factor." So far, we’ve done quite well achieving this. Even if I died tomorrow, Pi would remain in reliable hands.
0xSero: Speaking of finding contributors, what changes have you seen? More and more people are starting to use AI. I know you previously disliked people throwing together piles of AI-generated code. How has the experience been lately?
Mario: Terrible. To put it another way, if I hadn’t spent most of my time from February to around July maintaining Pi, reviewing issues, and fixing them, Pi Durable could have launched much earlier.
The problem is that Agents currently can’t help you fix issues—at least not for my project. I lack the trust to let an Agent determine which reported issues are worth our time and need fixing. So, at minimum, I still have to personally review every submitted issue.
Can Agents fix issues? Sure. The key question is whether they fix them well. Many problems can indeed be delegated to Agents, especially small ones. But whenever design or architecture is involved, human input is still required, because Agents often just "shit on" local parts of the codebase, making things worse. Right, Armin?
Armin: Another problem with Agents is that while they will definitely solve the immediate issue, they almost never fix it without adding code. This is actually strange, because after fixing many issues, the net code volume in the codebase shouldn’t increase.
Of course, it’s ironic coming from me, since I frequently submit PRs that touch 200 files and add 20,000 lines of code—it’s terrifying. I’m also a victim of abusing "clankers" (slang for AI). But software shouldn’t evolve this way. Especially a fully automated maintenance codebase will inevitably bloat with every bug fix.
When Is AI Slop Acceptable?
0xSero: DHH has completely embraced this "AI slop coding" workflow. I call my own work "slop operations" because I basically use models for everything. In some ways, I feel dumber than before, but on the other hand, efficiency is extremely high. If your job isn’t to build something that millions of people will copy and use, I don’t see any harm in hacking together a script. For example, what I’ve been doing recently is creating Docker containers for specific hardware combinations, letting the model optimize performance on random VRAM/RAM configurations. This trick works well; design and architecture aren’t critical as long as the result runs and does what it needs to do. But you guys don’t have that luxury—you’re building things used by millions.
Mario: We certainly have that too. A lot of things inside Pi are purely hacked together. The difference lies in where you insert human intervention, and where you trust the Agent to produce usable output without caring about the specific implementation details.
For example, Pi’s TUI library was originally designed by me in early 2025 for another project. That design was robust and minimalist; I knew it would likely withstand real-world usage, even if imperfect, it was sufficient. But when I actually started building Pi, I didn’t go in saying, "Write me a markdown component, write a text component, write an editor component." Instead, I directly told the Agent: Here is the API, write against this API, and build out all these components. I didn’t care what they looked like, as long as they ran and had a bunch of tests ensuring correct rendering. I didn’t care about anything else.
To this day, I haven’t read a single line of code in the Markdown component or the text component. I don’t care; it’s not important. The only time I care is when performance degrades. At that point, Agents are very good at identifying a bunch of issues, but they are extremely poor at providing generalized solutions. They’ll go in and patch a local issue to improve performance for one edge case, but they won’t think holistically. They fail to identify the root cause—architectural flaws that slow down the system overall and consequently give rise to these slow edge cases. I believe my current value lies precisely here.
0xSero: I remember your workflow: creating interfaces, tinkering with APIs, trying to get a feel for what you’re building first. Has this process changed?
Mario: No.
0xSero: Models have gotten significantly better at executing tasks overall, but their architectural capabilities remain messy and stagnant. Have you noticed any differences?
Armin: Sometimes I even feel they’ve gotten worse. More accurately, they might indeed be slightly worse in terms of architecture. The final results may have degraded because we’ve given models more control. Almost every time a new model is released, I use it to build something, and I’m increasingly dissatisfied with their independent work. The main reason is likely that I trust them more than before.
The models themselves may still be improving, but if you factor in my expectations and usage patterns, the net result has actually declined. Every time, I ask the model to write a game in C, because I used to love writing C—it’s my standard test. I feel they’re getting worse. It could also be that I’m paying less attention myself, but at least it’s certain that the results haven’t noticeably improved.
0xSero: It’s not about how they build things, but how they communicate with us has become weirder: their speech is increasingly complex, they use far more technical jargon, and they dive into obscure niche tech topics in their replies.
Armin: However, Opus has definitely improved.
Two Codex Accounts Cracked My Software
Mario: With versions around Fable 5.x and the previous Opus release, I completely stopped using them for a while just because of their tone. Every word seemed freshly pulled from a thesaurus—it was unbearable. Astra was also bad. But I’m quite satisfied with Sol 6.1 and Opus 5.5; they’ve dialed back that pretentiousness, and now they sound like normal machines.
One improvement I genuinely felt was in cybersecurity. Last year, I used Clanker to harden some desktop software, but it was useless—it couldn’t understand what was happening at all.
This year, a Chinese user cracked this software using two Codex accounts. Subsequently, I used a "reverse engineering bot" to replay the attack and figure out how he breached the software defenses. The entire process was astonishing. No human reverse engineer in the world could dig that deep, let alone complete it in such a short time. It’s insane.
To get slightly low-level: This is a JVM system. On top of the JVM sits Java bytecode, which is ultimately compiled into machine code by the Just-In-Time (JIT) compiler. I protected all of this well; others couldn’t simply extract the bytecode or inject their own. However, there was a tiny escape path on the native side that no human could identify or exploit. That Clanker went straight in, reversed the native structures inside the JVM, started directly reading process memory, mapped it back to the correct version of the JVM, and identified which structure in native memory corresponded to which part of the Java representation. It’s like science fiction—incredible.
Armin: I have a small gadget I always show off: a USB chip, a Chinese CarPlay adapter. It figured out on its own how to decrypt the little thing meant to protect new root image uploads, and it found a CGI file on the web interface that allowed bypassing some restrictions. I did nothing; I just plugged it in and let it run. After spending about $500, the whole thing was mine. That’s truly impressive.
0xSero: I’ve stockpiled a bunch of hardware at home just to run these models, ranging from the smallest Qwen 27B to DeepSeek and GLM. They’ve become very strong at handling this kind of task. I gave them a Nintendo DS ROM hack—a ROM game—and asked it to build a Nintendo DS emulator from scratch. It could reference Dolphin and other projects, but had to write it in a completely different way. And it actually ran. I’ve found that whenever a task is binary—either done or not done—they eventually nail it.
Agents Can Rewrite Bun, But Can’t Learn Architecture
Mario: If you have an Oracle that can tell the LLM whether it’s right or wrong, you’ve basically won. Take Bun, for example. Bun has extensive tests. I’m sure it doesn’t cover 100% of everything that needs testing, but it’s enough for Jared to guide a swarm of Agents: "We port it this way, then that way; I’ll point you in the right direction at key checkpoints." Basically, you just need to get the test suite running in your Rust rewrite of Bun, and this approach works exceptionally well.
Regarding the emulator mentioned earlier, I’ve actually done something similar. There are massive numbers of emulators for various systems, and all this stuff is in the training data—crazily abundant, including specifications for those systems. So this is also a domain perfectly suited for Oracle-based testing, as the training data is stuffed with relevant information.
Armin: Moreover, it’s easily fuzz-testable. I think anything that can be fuzzed applies here. Recently, I took a bunch of sample files in various formats—TOML, CBOR, MessagePack, JSON...—and said: "Here is my serialization library; implement support for all these formats." It eventually did finish. Then I said: "Okay, now fuzz it to death." It found a ton of bugs. While fuzzing libraries wasn’t exactly difficult before, now it’s practically a default operation. You just let it run until it takes you hours to find the next regression.
Mario: I think this is a fantastic use case. Especially during fuzzing, you might already have some automated fuzz generation, but adding an LLM on top allows it to reason about additional cases your fuzz generator missed. It’s like rocket fuel for all testing work—stunning and highly useful.
But this brings us back to the things we mentioned earlier, like architecture. I remember DHH saying something along those lines: "You think you're special because you know how to design architectures? Think again—the models will crush that too." I don't think DHH really understands what machine learning is actually doing.
Armin: If you ask a model about the correct architecture for a problem, they’re actually quite good at it. But the trajectory they generate as the "most likely solution" ultimately lands in a completely different part of the weight space.
Mario: This can largely be explained by training data. It’s easy for me to curate training data for cybersecurity tasks, for building things that already exist with standard answers, for creating websites, frontends, or whatever else you want.
But there is no training data for the process of building itself—for designing and architecting something. This is the only part of programming that typically isn’t encoded into text form, and therefore isn’t learned by LLMs. It’s precisely this process of constructing the architecture of something that leaves us stuck here.
Armin: That’s why we’re recording all our meetings now, so we can sell them to OpenAI for two million dollars later.
0xSero: I met someone in Germany who runs a robotics company. Their main business is actually selling training data. They pay people to wear hats, attach robotic arms, and do work, then sell the collected data to labs. It’s a very good business. But I’m convinced everything lies within these trajectories. So if you’re discussing architecture with a model, those conversation trajectories should be weighted higher. But how do you assign weights? How do you decide which data deserves higher weighting?
Armin: There’s a lack of clear signal here. For example, how many iterations did Pi Durable go through?
Mario: Eight rounds.
Armin: Right, it went through many iterations. So how does the training system know which specific interaction in those conversations eventually became the version we released? Theoretically, it’s possible—you can train it, label it, and there are ways to do this—but it’s a significantly harder problem, and the volume of such conversations is much smaller.
Mario: I tend to think this is essentially a classification problem. You have a pile of trajectories. Regardless of your zero-data retention policies, OpenAI, Anthropic, and DeepSeek have massive amounts of trajectories on hand. Now you want to pick out the truly high-value, high-quality ones from among them.
How do you do that? It’s impossible manually. They do label some by hand, but that doesn’t scale. So the fallback plan is to use a machine learning model to classify trajectories into high-quality and low-quality.
0xSero: I think they have an opportunity to do one thing: just like when you use Claude Code, it automatically tags GitHub repositories and commits. So if you build not just conversation trajectories but also repository history itself, that could be a good approach. Because you can directly map which repositories are still being used by users, which PRs were merged, and what proportion of that code is still alive.
Mario: But here’s the issue: given the volume of data they have, you’d expect them to be doing something complex. But from what I’ve heard internally, they aren’t currently doing anything particularly sophisticated.
Armin: I think once they crack this, it ties into RSI (Recursive Self-Improvement). Models will start doing those complex things because suddenly it becomes easier.
This is actually why I think the situation might improve: right now, humans find this task extremely tedious. But if models deem it worth investing in, that will drive progress. Perhaps through self-improvement, we’ll reach that point.
0xSero: With the latest Opus, I give it many reasoning tasks, and it makes breakthroughs every day. It’s becoming very good at navigating between hardware and software layers; GPT is completely useless in this regard. I don’t know if their models are better at math or certain other domains, but I definitely see breakthroughs there. However, that can’t really be used to build applications yet. It’s just a skill for climbing the hill, which is a bit disappointing.
How Does Pi Durable Keep Agents Running After Crashes?
0xSero: I want to talk about Pi Durable. Why did you choose the word “Durable”? What’s the logic behind it?
Mario: Let me try to explain it in five sentences: An Agent starts in a process → The Agent calls tools → The process crashes → You restart the process → The Agent resumes exactly where it left off. That is durability. You don’t need to manually type “continue,” tool results or assistant streams aren’t lost, and your application state is persisted and reliably recoverable. That’s “Durability,” or persistent execution capability.
We needed it because any long-running Agent—like various “Claws”—must have this capability.
Another problem Pi Durable solves is that previous versions of Pi loaded the entire conversation—or rather, the entire conversation tree within Pi—into memory. If you have a Bot running in Slack for years, the complete conversation trajectory might contain countless messages, making this approach unworkable. Not all of this content is necessarily sent to the LLM, but the system still needs to retain the full history.
Pi Durable handles these issues. It can also be easily deployed to Vercel, Cloudflare Durable Objects, E2B, your laptop, or even my phone, so it’s well worth exploring.
0xSero: Could you elaborate on its architecture? I looked at the repo today and had an Agent explain it to me. My understanding of recoverability is: every action must be committed and written to a file before it becomes an official record. If the connection drops midway, the system has an event queue where events are stored. Is my understanding correct?
Mario: We didn’t adopt that approach. We don’t use event sourcing, although many other systems do, because event sourcing introduces a lot of problems.
The fundamental challenge of Durability is: the system is executing something, and it might crash before execution begins, during execution, or after execution completes. The thing being executed is usually called an “effect.”
Many persistent execution solutions do this: before actually executing, write a record to the storage system stating, “I am preparing to execute this with these parameters.” If the process crashes after writing the record, I know all inputs have been evaluated and validated, ready for execution. When the process restarts, it checks the database, finds a pending operation that hasn’t actually run yet, and proceeds to run it. This is the first layer of the “effect sandwich.”
The second scenario occurs while an effect is running. How you recover depends on the specific execution content. For example, consider an external system like GitHub Actions: you send a message saying "build this commit, run this action," and then the process dies. Upon restart, you might not know whether it actually ran because the results haven't been saved yet. This case is manageable with GitHub: you can state "I am about to schedule a run," obtain a key/ID before the actual execution begins, and store it. When executing, you say "run using this ID." If it’s already running, GitHub will inform you, and you simply wait for the result; if it hasn’t started yet, it launches using that ID. This is what we call idempotency, which allows the system to withstand crashes during execution.
The final step: once the effect completes and the result is obtained, save the result. Thus, the "intent → execute effect → store result" sandwich is complete. Afterward, you don’t need to think about it anymore; intermediate information can be discarded unless you want to keep traces for logging or auditing purposes. The important thing is that you have the desired result; and no matter where in this sandwich the process dies, it must ultimately reach that end state.
Of course, there are complex cases. For instance, if the effect is deleting files from disk, it usually cannot be undone unless you have Git; similarly, charging a credit card—I certainly don’t want to charge twice. Therefore, all effects you intend to run must, in some sense, be compatible with this persistence system.
Returning to Pi’s durable architecture. Essentially, every event occurring within the Harness is a task, which is an effect sandwich.
For example, if I want to generate an LLM response, I create a task: prepare the request, gather context window, parameters, thinking level, model information, etc., save a record stating "about to execute this call," and then actually invoke the LLM—this step is the effect. Once the answer is received, persistently save the answer.
Tool calls work the same way. The system receives a tool call from the LLM, then establishes a task to execute it.
0xSero: These tasks should be nestable, right?
Mario: Yes. A task can spawn another task and wait for it to finish. That’s essentially the magic of the whole thing.
On the other side is application state. We built a document store similar to MongoDB, storing JSON objects that can be freely modified. The special aspect is this: I have a document that has a certain value at time zero of the transcript, such as a to-do list. Then you collaborate with the Agent, and users, assistants, and tool calls continuously modify it, so the document is updated at the corresponding position in the transcript. If I want to go back in time, which version of the document do I want at that point? It depends. Sometimes I want the old to-do list from that moment; sometimes I only want the latest version, regardless of my position. So our document store allows associating these two types of documents with any position in the transcript. With this, we can store application state.
For example, if I have a canvas for drawing, it is a document that stores only a list of strokes; I can replay it to draw the picture. I converse with the Agent while simultaneously drawing on the canvas, then say "show this new drawing to the Agent," and the document evolves alongside the Agent. If I go back in time, to let the Agent see it, I want the old version of that drawing.
With just these two fundamental primitives—versioned documents and tasks—you can accomplish a lot. Basically, this is Pi Durable.
0xSero: So you have a versioned document that gets updated as you progress through the session, with each update being a version. Do you store the diffs between versions?
Mario: Yes. There is something called JSON Patch, which is an RFC. It basically defines operations on JSON objects, such as "set this field to this value," "create an array," "set the element of that array to this value," and so on. I found it lacking for this use case, so we created something similar but optimized for Agent scenarios.
Armin: The entire React ecosystem revolves around State 1, State 2, and the core problem is how to express state changes on immutable data structures. Somehow, this problem has never truly significantly improved.
Mario: There are things like Immer, which mostly gets it right most of the time.
Armin: But that’s about it. It has never become a universally agreed-upon, well-understood standard for expressing structured updates to nested data structures. Then you have Automerge, a project by the folks at Ink & Switch, which tries to give you some kind of Agent object, recording all changes made to it, and generating the necessary CRDTs behind the scenes to represent those changes. But its mapping onto JavaScript is basically a huge hack with too many loopholes.
Mario: This is a problem inherent to software development itself. Pi Durable obviously has similar pitfalls; we also use the Proxy approach.
Basically, I tell the storage layer to give me this document, and you get a JavaScript object. You can manipulate it just like any other JavaScript object. I can write object.x = 10, and this operation is automatically recorded as an operation, then applied to the real object, used to reconstruct state during replay. This also relies on Proxy, which is basically a slow hack. But for what we need to do in the Agent Harness, it works very well.
Building a Persistent Agent Harness
0xSero: Why did you decide to tackle the persistence problem rather than other issues with Agent Harnesses?
Mario: There really isn’t much existing work in this area. Obviously, there are Hermes, OpenClaw, and various other "claws," and even AMP has something called an orb, allowing you to transfer sessions and keep them running. They all have to solve the persistence problem specifically for Agent Harnesses in some way. But none of these are general-purpose solutions; I can’t directly take them to build the next Earendil project, the next open-source product, or internal tools for Shopify.
But we have multiple projects where we build Agents, truly making them work in a way you can trust, giving them some reliability, and enabling them to continuously recover from failures. Most importantly, they keep recovering even when no one is watching. Making them inherently reliable—so that you feel confident building on top of them—is itself a massive undertaking. And it’s not measured by the number of lines of code ultimately delivered, but by whether the core design actually works.
As Agents become more orchestrated and operate increasingly independently of human observation, you at least want their orchestration to be understandable. After all, the Agent itself is already unreliable enough; it contains an LLM that does whatever it wants, behaving like an organic entity. So the orchestration layer should at least be comprehensible, bringing some degree of order and rationality.
0xSero: I’m trying to use my laptop less, so I want sessions to flow between different machines. I had GLM build something called parcels using Pi. The solution it came up with was: copy the session JSON from one machine to another and restart, because all the environment variables are inside it. It should suffice. But I want it to run automatically and sync across all my devices.
So what’s next? What are you working on now? Are you stabilizing this?
Mario: Mostly internal dogfooding. We use it to build a lot of things, then decide what to release externally. Armin, you take it from here?
Armin: I think you can view Earendil as having two tracks. One track involves products we’ve built that are non-Coding Agents; ideally, in the long term, even non-engineers can find joy in using them. Meanwhile, we’re also building infrastructure-level components that people can ideally use to build their own Agents.
Before Pi, we built a product called Lefos. Today you’d call it a Personal Agent, but it was essentially an Agent sitting behind a plain-text communication interface—in our case, email. We really loved the concept: having a small entity accompanying you, helping solve certain problems, but without imposing itself on external parties. Not the kind that says, “Hey, book this for me, I have an appointment,” and then goes off spamming real humans with AI-generated junk. Instead, it’s a helpful assistant that stays by your side. There’s clearly a lot happening in this space, but we genuinely dislike any products currently out there; they quickly turn into these massive, chaotic contraptions.
0xSero: And I think it’s extremely dangerous. There are already plenty of people trying to hack you, and then millions of users are logging everything into tools like Grok Bot. I think that’s a disaster waiting to happen.
Mario: I found it amusing, actually. Just five minutes before we started talking, I saw a post on Twitter where a guy said, “My Grok Bot sent all my personal financial info to the company Slack, and everyone could see it.” Then Elon said he would compensate him if such an incident actually occurred.
0xSero: I do like Personal Agents. I run DeepSeek locally at home. I used to use Codex for this, but the speed was abysmal. So now I run DeepSeek locally. These open-weight models are good enough; they can scan fifteen different mailboxes, organize the content into Linear, and handle it. But it’s still messy and highly uncertain.
Jev and MCP in Pi
0xSero: What do you think about Jev?
Armin: When I’m not leading MCP, I lead Jev.
Mario: If Armin could marry Jev, he definitely would. He loves Jev very much.
0xSero: Merging the two, letting one classify for the other, seems very reasonable, especially when dealing with large volumes of junk content, like emails.
Armin: This is actually why MCP eventually landed in Pi.
It has nothing to do with MCP itself; it’s because I needed to create code patterns for Jev. From there to MCP was just a five-minute task. But to make Jev work—or to make any classification model work—it needs another system to generate a custom Harness to drive it.
But there’s a more fundamental issue here: many tasks get stuck because they are inherently "soft" tasks. You have to use an LLM, but they are too slow.
Of course, this isn’t anything new. But Jev truly proved one thing: if you train it well enough to become a general-purpose single-pass classifier, it achieves product-market fit, and then the whole thing starts rolling. Surprisingly, I love it. Suddenly, besides image generation and LLMs, another class of models has emerged that people are seriously exploring.
Mario: Right, and it’s genuinely useful. I personally have zero use for image models, but I can use Jev in countless places.
0xSero: You seem to quite like Amp. Why? How do you view different Harnesses? What is your approach?
Mario: When we were dealing with the Codex stuff, if the backend wasn’t working, we’d clone the openai/codex repository to see exactly what they stuffed into it to make their backend run. That’s roughly the extent of how we look at other Harnesses. Amp is different because it appeared long before Pi. OpenCode did too—I remember it being around early 2025. I don’t look at OpenCode much anymore, but I checked out their V2, which was interesting. They are also wrestling with persistence now.
But I’ve never actually used Amp; I just really like the team. I think they have their own vision for the future of software engineering. They aren’t sure about it, but they have a perspective.
0xSero: Exactly. If you have enough VRAM, it’s genuinely great for local models because they implemented that advisor mechanism. You set up a model like Opus, and it reads the entire conversation. When the model starts going in circles or deviating from the task, it steps in—almost like injecting a message as the user—saying, “Here is the scope; here is where you need to change your approach.” Then there are the Sub Agents. I think they’ve done a really good job replicating the fan-out behavior that Claude Code achieves with Opus and Fable. Plus, the login flow allows you to just /connect directly to your own resources, which is fantastic. It has definitely improved, but it consumes tokens aggressively—that’s an issue—and its system prompt is massive, which is another problem. I’ve been really enjoying the DeepSeek Harness recently. Have you spent any time looking at it? It’s quite impressive.
Mario: I did read through its source code, and the plugin architecture is particularly interesting. Although, in terms of actual plugin mechanisms, they promise more than they deliver, their thinking is very clever. That was one of the few Harnesses I actually took the time to examine, because obviously we want Pi to evolve. Seeing another Harness pursue the path of “the thing itself must be self-modifiable” feels good.
We’re seeing this in Claude Code now too, which is hilarious. When Boris says, “Oh my god, these mods are amazing, how can we not let Claude modify Claude Code itself?”—well, go for it.
0xSero: I think their Harness has gotten a bit better. I didn’t like it much last year, but it’s more stable now. However, it still has too many bugs, random errors, and different sessions leak into each other, which is one of its problems.
Armin: I did look at DeepSeek’s Harness. When we started researching plugin architectures, there was definitely stuff worth examining in there. I generally don’t pay much attention to what others are doing because it’s a huge distraction. And you never know if they’re doing something because they’re solving a real problem, or just because “code is free,” so they ran an experiment on a whim.
When I worked on MCP, I basically cross-referenced everything related to MCP across all the major Harnesses, just to figure out if it was worth doing. Because you get a list of features people want—they really want these things—so I went to see what everyone else was building.
Mario: I absolutely hate elicitations.
Armin: I used Amp quite a bit last year, then mostly stopped, but I looked at Orbs again. I do like the philosophy behind Orbs, but somehow, I’m not attached to web interfaces. I use the mobile apps for Claude and Codex, but I never use desktop apps. As for terminals, I don’t actually find them particularly good. I haven’t found that perfect experience yet.
0xSero: The reason I like DeepSeek is that it feels like Pi within a desktop app context. The actual user experience is extremely minimalist and clean. And because it launches as a web process, you can put it directly on your tailnet and access it from your phone or another machine. I don’t have to deal with those weird “connect your device” operations, which have always been annoying.
Future Direction of Pi
0xSero: Have you considered building an app or a web interface?
Mario: Yes, I’ve been tinkering on my phone over the past few days, building something primarily intended to run on mobile. I call it PIM, Pi Mobile. It’s not a product I plan to open-source, at least not currently. But we are definitely exploring this direction as part of Pi’s evolution. I think Pi is a preliminary proof-of-concept for “self-modifiable Agentic software,” and it works. Now we need to pull ourselves together and evolve it toward a direction where it’s no longer just “me and Clanker,” but many Clankers on many machines, conversing with many people. It should allow me to freely jump around, reconnect agents and humans, and collaborate in whatever configuration I desire. I think that’s where Pi needs to go.
Building PIM was essentially about ensuring Pi Durable actually works—it’s dogfooding. I wanted to replace Claude for Android, since I was previously a Claude for Android user. Now it’s completely replaced because PIM runs entirely on my phone; except for the LLM, everything else runs locally on the device, and I love that. It can also connect directly to any of my other machines as an execution environment. So it connects to my Hetzner server and helps me do sysadmin tasks there, while the “brain” runs on my phone. I’ve already implemented that part of the vision. The next step is figuring out how to make this the evolutionary path for Pi, complete with a plugin system. And I’ll be completely honest, DeepSeek is definitely an inspiration here—not necessarily technically, but conceptually.
Armin: But there is a staggering level of complexity in web-based plugin systems, and much of it stems from silly reasons, like how do you make it secure? Because you’re somewhat constrained by abstraction; almost as if “making it secure” inherently degrades the experience. So the question becomes: how do you find a good balance throughout this whole endeavor?
0xSero: Right, the security aspect has always been painful for me. A few days ago, I noticed one of my Clankers tried to share files with another device, and it ended up exposing my entire file system to the public internet for about a day, despite having protections like WireGuard in place.
Armin: But the goal is for multiple people to experience the same session within an operational environment where our Harness can scale. But that means some people will be trusted more than others. You don’t want to fall into a situation where you “must fully trust the person connected to your session,” right?
0xSero: What about Docker? This looks like a Docker-type problem—you have a created entity that acts like an image.
Armin: Right, but let's set aside the Docker part for now—that’s practically a walk in the park. Securing the server is straightforward. But how do you secure the web interface? Because right now, when you connect to our web interface, the UI pops up with links. If I click one... it’s too easy. If we end up in a shared space where we all have accounts, and Clanker brings up a user interface, that’s literally XSS—used to steal my cookies or whatever else. It’s solvable, but solving it is annoying. And many actual solutions involve iframes, which are terrible for both security and user experience. So building a truly scalable and secure web interface is much harder than it looks. Ironically, sandboxing Docker on the server is the easy part.
0xSero: Have you heard of IPFS?
Mario: That’s from the Web3 community—you have a distributed file system ledger on the web. I don’t think it actually solves the problem of information leakage. It might be an interesting way to persist and replicate data storage, but honestly, I don’t see how it contributes much to security.
0xSero: What it primarily addresses is this: if Clanker is building something, it needs to place that thing somewhere that doesn’t trace back to you personally. For example, if you and I are working on something together, we want a neutral space to put it in—a place we can both trust won’t be compromised by...
Armin: This is also a major headache for us; we’re just pretending we know what we’re talking about.
Onboarding Non-Developers to Agents
0xSero: What are you excited about recently?
Mario: Building products that aren’t Coding Agents, and evolving our existing Coding Agent into a form that our current community will genuinely love. This is a challenge, and we’ve already seen it: just releasing MCP and code mode support caused anger because people were upset that we added a feature we previously said wasn’t needed. But now models have been trained on this, and MCP servers and standards have improved. It’s basically good enough to integrate as a built-in feature—that’s our thinking. But people get angry because “How can you change your mind?” I change my mind when there’s new information. It’s not like I’m chasing the MCP hype wave; we spent a year adding support for it, after extremely painful deliberations.
Armin: I’m quite satisfied with the current state of AI. I just feel the user experience surrounding it could be better. So, what would really excite me—and I think this is societal—is if this technology could deliver something truly great and valuable. Give me a room-temperature superconductor, please. Or cancer drugs, anything.
On a purely technical level, the main thing I hope to see is for the hype to die down a bit, so we can finally use this technology to build truly cool software, collaborating to create better software rather than garbage forks of Photoshop.
Mario: Let me give you an example: PS5 emulation on PC has now been solved by Clanker. This counts as a contribution to society because it helps preserve PS5 games for the future. I love this—it’s awesome.
0xSero: Yeah, I keep telling people that everything is now AI doing AI work. This happened in crypto too, in every bull and bear market cycle. During a bull market, it’s not time for building; it’s time for marketing and making money. Then the real builders activate when the bear market hits, starting to construct those weird things that eventually blow up. We’re at that stage now. I think it’s incredibly crazy and abnormal, but I don’t believe it will last. What truly excites me is how we bring someone who has never used an Agent into the fold and get them using Agents. Because if I can get my wife using Agents, and my kids using them, many problems cease to exist.
Mario: You just want household logistics handled by others. Armin and I have had similar experiences. I introduced my wife to this; she used Claude last summer for some linguistic research. I also had my then-four-year-old child write a game for my wife as a birthday gift, things like that. It’s cool—that’s how I like to use technology.
And the point about onboarding is spot on. No one does anything about it; this is the biggest problem. Everyone gives you a chat box and a sidebar, and then, good luck figuring it out yourself. You’re a secretary. Here, use AI to improve efficiency.
0xSero: Yes, no one wants to put in the effort to onboard a person. The core issue is that if you don’t know something, you can ask, and then you’ll know. But the logical step from “I don’t know” to “I can ask” is a skill people often lack. It’s like what I learned when studying programming: you shouldn’t ask; you should figure it out yourself first, and only ask others if you can’t solve it, so as not to waste time.
Original interview video link: https://www.youtube.com/watch?v=ja_7AF54OtE