OpenAI and Anthropic Back $15M Effort to Verify AI Math Proofs
The Simons Foundation, together with OpenAI and Anthropic, has pledged $15 million in funding and compute to help mathematicians verify, understand and extend AI-generated mathematical results. The move follows OpenAI's release of 722 AI-written math manuscripts, three of which were retracted a day later over a single sign error, underscoring Terence Tao's point that mathematics is shifting from proof scarcity to proof abundance.
Related Entities
Full Report
New AI Era Report

On October 6, OpenAI released 722 mathematical manuscripts generated by its internal AI models in one go.
Just one day later, 3 of them were announced to be retracted.
What brought down all three manuscripts together turned out to be a single sign error: one paper had the error, and the other two, which followed the same construction, were retracted along with it.
After AI submitted its papers in bulk, the two major players joined forces to pay for "grading the exams."
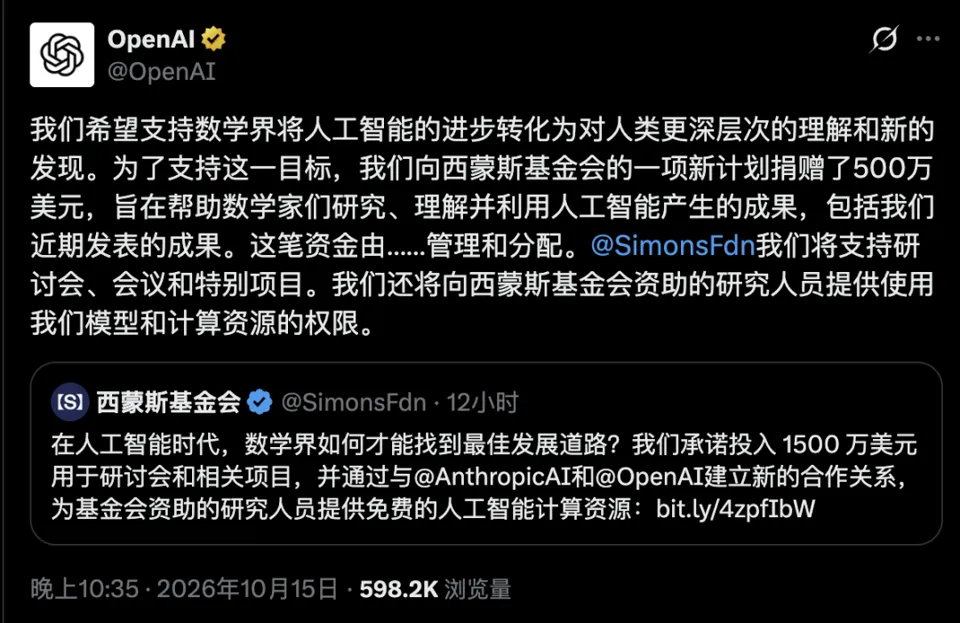
On October 15, the Simons Foundation announced a joint commitment with OpenAI and Anthropic of $15 million in funding and resources to support mathematicians in verifying, understanding, and extending AI results.
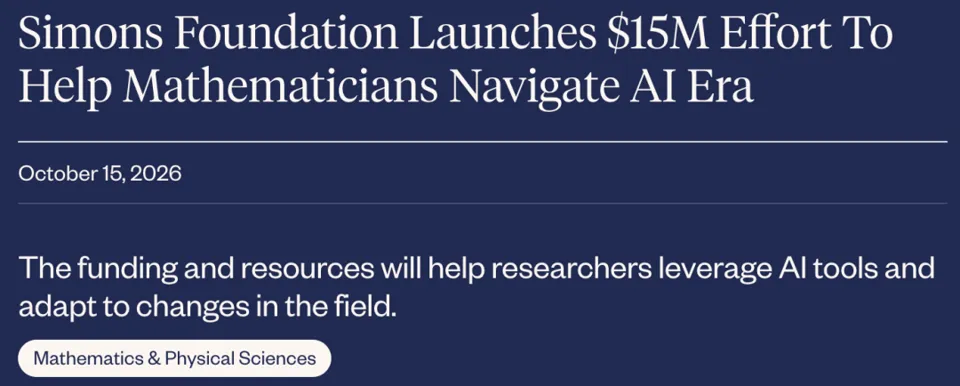
OpenAI is contributing $5 million, along with additional models and compute, in the hope of turning AI progress into deeper human understanding and new discoveries.
Anthropic's pledged $5 million in support includes funding, compute, and access to Claude. It also acknowledged frankly that making good use of AI in mathematics and broader scientific research requires time, effort, and resources.
The related grants are managed by the Simons Foundation and used for workshops, conferences, and other activities.
Put plainly, this is about supporting mathematicians in grading AI's exams—understanding those long proofs, explaining them clearly, and putting valuable methods to use.
In recent months, OpenAI has set off a series of "major shocks" in the mathematics community:
First, it announced research results on 10 long-standing open problems, then claimed a proof of the Millennium Prize Problem—the Navier–Stokes problem—and subsequently released hundreds of mathematical manuscripts in a concentrated burst.
With results pouring in like a tide, humanity is experiencing a bit of "indigestion."
Terence Tao pointed out incisively that mathematics is moving from "proof scarcity" to "proof abundance," but human capacity for verification and understanding may not keep pace.
In his lecture notes, Terence Tao proposed the "era of proof abundance."
Justin Solomon, Associate Dean of Engineering Education at MIT, admitted on a podcast that with OpenAI's Navier–Stokes proof, he read the first few pages and could not continue.
On the Odd Lots podcast, Solomon admitted frankly that faced with OpenAI's Navier–Stokes proof, he could not even get through the first few pages.
AI can rapidly generate long derivations, but human understanding does not automatically arise alongside them.
722 Manuscripts
From "Written Out" to "Understandable"
On October 6, OpenAI published this batch of results from an internal unreleased model on GitHub, and the next day left an awkward record in the changelog: 3 retracted and 14 revised.
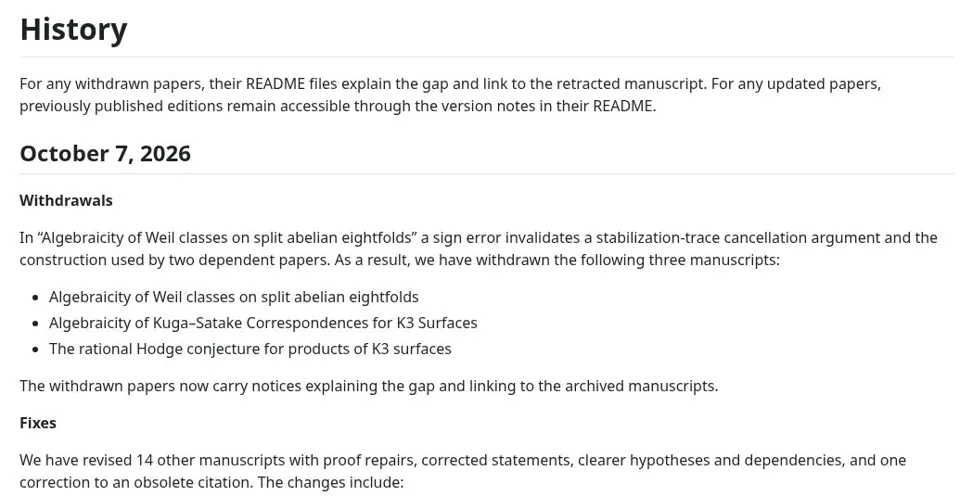
October 7 changelog: 3 manuscripts retracted, another 14 revised.
The problem lay in a single sign:
According to the paper's convention, it should have been -1, but the AI calculated it as +1 in the proof. After correction, the count that was supposed to vanish was not zero, and the premises of the theorem used collapsed outright.
The other two manuscripts used the same method and were retracted as well; one of them studied the rational Hodge conjecture for products of K3 surfaces.
This batch of results came from the model's attempts on and screening of about 4,000 problems. The quantity is astonishing, but verification has not kept up:
About 42% of the main results are accompanied by Lean formalization materials, allowing computers to check the reasoning process. Some results not yet formalized may still contain problems.
Even if the proof itself is fine, the research is not over.
Knowing that a calculation is correct is not enough; one must also understand how it was done correctly: What is the key method? Can the applicable conditions be relaxed? Can it be used to solve other problems?
In mathematical research, authors need to understand their own proofs and take responsibility for them.
But AI may produce a long chain of derivations that even the researchers who posed the problem cannot understand, let alone check for correctness.
So finding errors is only one step.
More critical is explaining the useful methods clearly so that others can learn them, use them, and continue the research.
The Academic Community's Ire
How Much Can $15 Million Solve?
This also thoroughly ignited the ire of the academic community.
What everyone is debating is no longer just whether the three manuscripts contain errors, but rather: when AI hands over so many results in one go, who is going to spend the time checking for mistakes, reading and understanding them, and then carrying the research forward?
On October 7, the Association for Human Mathematics (AHM) issued a stern statement criticizing the act of dumping more than seven hundred files at once as "a display of power," and even called on mathematicians to stop collaborating with OpenAI.
The AHM guest statement published on Terence Tao's blog, retaining the working group's signature.
This statement, signed by the association's communications working group, was also posted by Terence Tao as a guest article on his own blog.
Cornell University mathematician Alex Townsend's suggestion was direct:
OpenAI should first release the Lean-verified manuscripts, and put other materials out separately for people to help check, rather than mixing verified and unverified work together.
MIT senior research scientist Andrew Sutherland affirmed OpenAI's attitude of quickly correcting errors, but also said that more work is needed to rebuild trust.
What people worry about is this: AI companies use internal models that academia cannot access to get ahead and produce results, while mathematicians, lacking the same tools, fall behind progress in their own field.
An AI company released a large batch of manuscripts in one go, yet the burden of checking for errors and understanding them fell on human researchers.
The advisory group (AGMAI) of the Institute for Advanced Study in Princeton proposed as early as late September: AI labs should not just focus on releasing results, but should also contribute funding and resources to support humans in understanding these results.
OpenAI and Anthropic joining forces to provide support this time precisely responds to the academic community's earlier demands.
But such support does not equal buying out the right to speak: academia accepting support does not mean academia endorses all of the AI labs' practices.
How exactly should this $15 million be spent?
According to the announcement, the foundation will openly solicit projects to support researchers in examining AI results, learning new tools, and discussing together how these tools should be used and by what standards.
AGMAI previously also suggested holding summer schools around complex proofs, or organizing long-term collaborative research groups, so that everyone has the time and resources to unpack and explain, step by step, the lengthy proofs written by AI.
Simons Foundation president David Spergel also emphasized:
These discussions must be led by the mathematical community.
AI companies can provide resources, but what to research, how to verify it, and where to go next are still up to humans.
The academic community accepts funding while also preserving room for questioning and independent judgment.
AI submits en masse
Humans continue to uncover knowledge
In the announcement, David Spergel emphasized that mathematics should not be seen merely as a collection of proofs and theorems, but as collective understanding driven by human curiosity.
When AI can mass-produce research materials, measuring scientific progress must also take follow-up work into account.
We cannot merely marvel at how many papers AI has written; we must further ask: Which results can withstand scrutiny? Can others understand and continue to use them? What new directions for exploration have these results opened up?
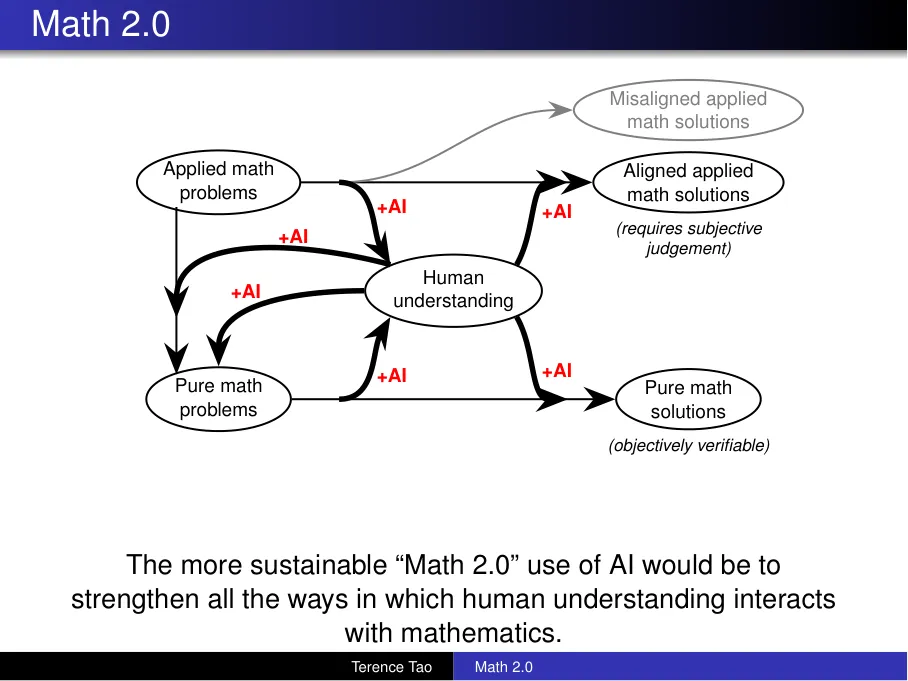
Terence Tao's Math 2.0 diagram, placing "human understanding" at the center.
And this discussion has already extended beyond mathematics.
The Simons announcement explicitly mentions that the tools and computing power provided by OpenAI and Anthropic will also be used in basic scientific research beyond mathematics.
Who checks for errors, who can understand the work, and who is responsible when problems arise—other disciplines also need to think about this in advance.
Recently, a reversal occurred in a theoretical physics test:
GPT-6 Astra was judged wrong, but after expert review, it turned out that some of the reference answers themselves were wrong. After correction, Astra answered 49 of the 50 research-level questions in TheoPhysEval correctly, reaching an accuracy of 98%.
AI's answers need to be checked, and experts' reference answers likewise need to be checked.
Then, by explaining complex derivations clearly so that others can understand and use them, these results can become the starting point for the next discovery.
References:
https://x.com/OpenAI/status/2110741355739963884
https://x.com/AnthropicAI/status/2110846112152105136?utm_source=chatgpt.com
Chasing ASI in seconds
⭐Like, repost, and watch—one-click triple support⭐
Light up the star to lock in New Intelligence's instant push notifications!