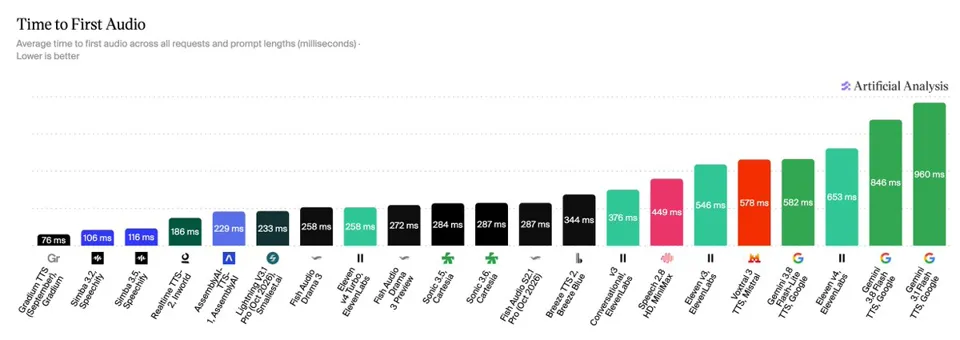
Artificial Analysis Adds Time to First Audio Benchmark for TTS Models
Artificial Analysis launched Time to First Audio, a benchmark measuring how long text-to-speech models take before audible speech begins, filling a gap in its existing TTS quality and speed evaluations. Leading models range from 76 ms to nearly one second, with streaming models at a 376 ms median versus 2.0 seconds for non-streaming ones, making streaming the key divide for voice agent responsiveness.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-16 17
Announcing Artificial Analysis Time to First Audio, measuring how quickly Text to Speech models start speaking. Among the leading models the wait ranges from 76 ms to nearly a second
Our Text to Speech benchmarks already cover quality, pronunciation and generation speed, but not how long a user waits before hearing anything — the number that decides whether a voice agent feels responsive. We measure every model daily on the same 12 prompts across four input lengths, timing audible speech rather than the first byte, and report a rolling 7-day mean.
Key results:
➤ Fastest at the frontier: @SpeechifyAI's Simba 3.5 starts in 116 ms — the highest Arena Elo of any model that begins speaking in under 200 ms. @InworldAI's Realtime TTS-2 follows at 186 ms.
➤ Turbo variants earn their name: @ElevenLabs' Eleven v4 Turbo starts in 258 ms against 653 ms for Eleven v4, at the same Arena Elo. @FishAudio's Fish Audio Drama 3 matches it at 258 ms and @cartesia's Sonic 3.6 is at 287 ms.
➤ Streaming is the dividing line: The 65 streaming models typically begin speaking within a few hundred milliseconds, a median of 376 ms. The 20 non-streaming models must finish generating before they return anything: a median of 2.0 seconds.
See more details below ⬇️