IT之家 · 智能时代 · 10/20/2026, 09:34:53
Ant Group Open-Sources Ming-3.0 Voice Models with Director Mode and Long Audio Understanding
Ant Ling has open-sourced the Ming-3.0 voice series, comprising five models for TTS, ASR, and audio understanding. The release introduces a 'Director Mode' for fine-grained control over speech emotion and rhythm, alongside enhanced structured understanding of long audio. These capabilities are already deployed in Ant Group's internal services like Alipay.
SOURCE COVERAGEFull Original Report
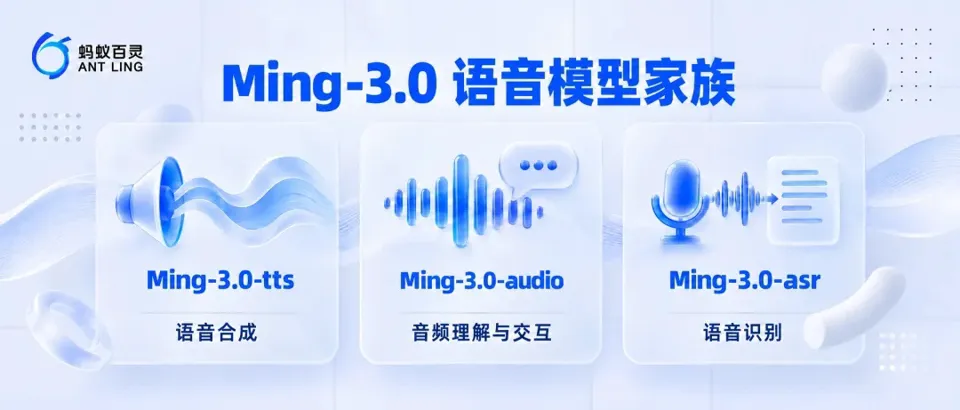
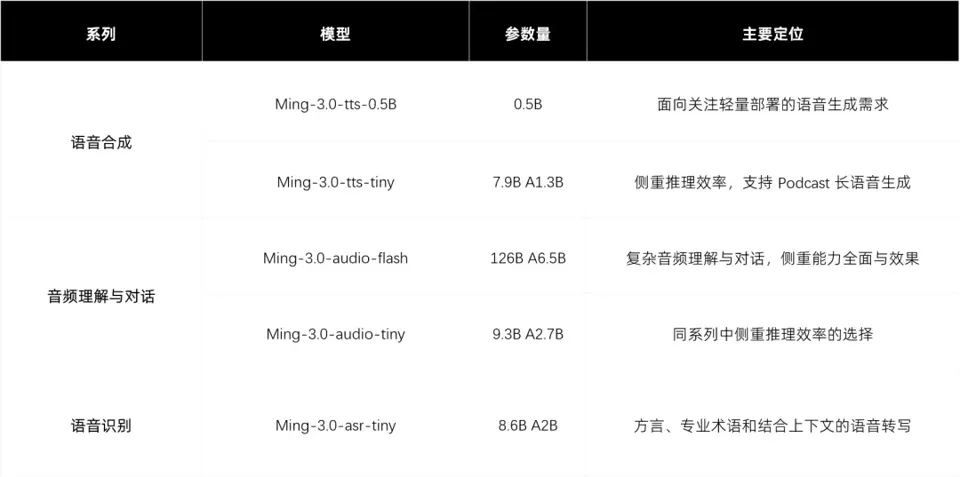
On October 20, Ant Group’s Bailing announced the open-sourcing of the Ming-3.0 speech series, comprising five models across three categories: text-to-speech (TTS), audio understanding and dialogue, and automatic speech recognition (ASR). Developers can select models based on specific tasks or combine different capabilities into their own workflows.
 "960x410"
 "960x477"
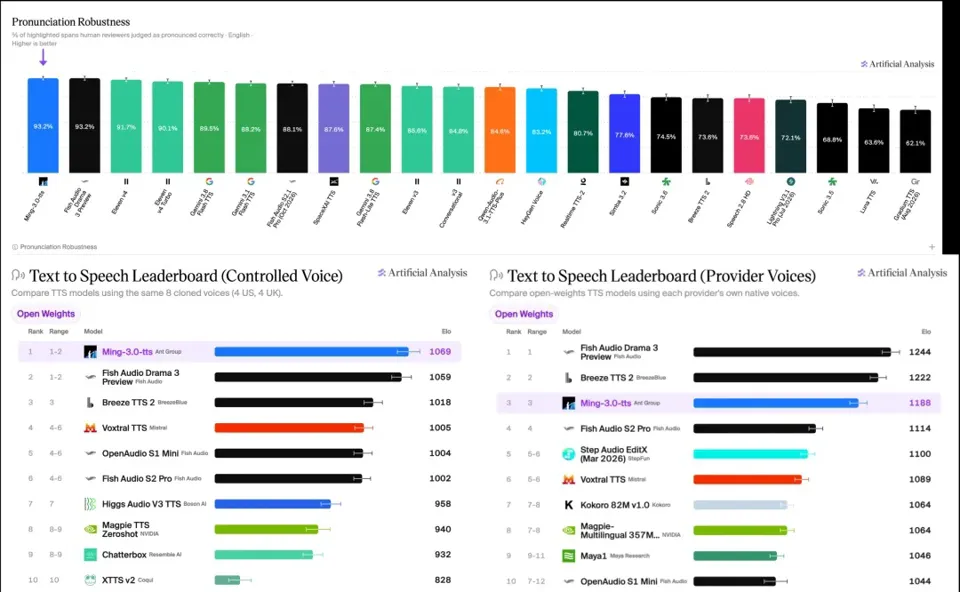
The Voice Design feature in the Ming-3.0-tts series allows users to describe target timbres via text prompts while also supporting voice cloning from reference audio. A distinctive capability is the Director Mode, which enables creators to specify performance details for dialogue lines—such as emotional shifts, words requiring emphasis, and pacing adjustments.
Within Ant Group, Ming-3.0-tts has been deployed across various business scenarios, ranging from the main chat and voice call features in the Afu App to doctor voice cloning and Xiaohu Smart Office solutions. It can operate independently for dubbing tasks or integrate with Ming-3.0-asr-tiny to bridge voice input and response playback.
 "960x592"
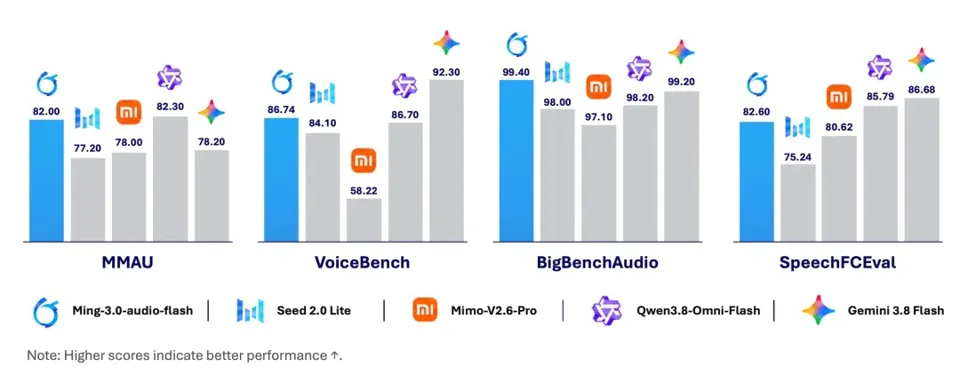
Ming-3.0-audio-flash / tiny supports complex understanding tasks such as transcription, summarization, and viewpoint analysis of long audio inputs, producing structured outputs. Compared to traditional pipelines that first perform ASR to generate transcripts before analysis, this approach preserves contextual nuances like emotion, speaker identity, and environmental information. Additionally, it requires the model to perform rapid inference over long context sequences.
 "960x375"
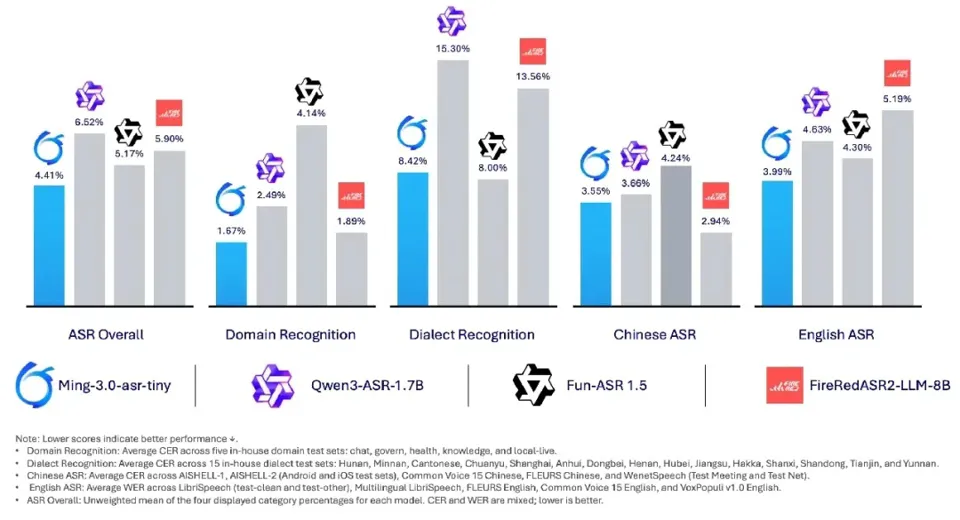
Ming-3.0-asr-tiny achieves comprehensive improvements in speech recognition performance for real-world business scenarios by constructing high-quality corpora covering Mandarin, English, dialects, and domain-specific hotwords. It carefully manages data distribution and leverages the strong contextual understanding capabilities of its language model base, utilizing candidate hotword lists and dialogue context information.
At Ant Group, Ming-3.0-asr-tiny is already applied in scenarios including the Afu Doctor Assistant, Alipay Search, Yixiaobao Real-time Voice Dialogue, and Security Identity Verification.
 "960x520"
IT Home provides the following related links:
Online Demo: https://ling.tbox.cn
- Online Experience: Visit Ling Studio Chat, select Ming-3.0-audio-flash to experience audio understanding and conversational capabilities.
- API Access: Ling Studio provides API services for Ming-3.0-tts-0.5B, Ming-3.0-audio-flash, and Ming-3.0-asr-tiny. Ming-3.0-tts-0.5B
- Hugging Face: https://huggingface.co/inclusionAI/Ming-3.0-tts-0.5B
- ModelScope: https://www.modelscope.cn/models/inclusionAI/Ming-3.0-tts-0.5B Ming-3.0-tts-tiny
- Hugging Face: https://huggingface.co/inclusionAI/Ming-3.0-tts-tiny
- ModelScope: https://www.modelscope.cn/models/inclusionAI/Ming-3.0-tts-tiny Ming-3.0-audio-flash
- Hugging Face: https://huggingface.co/inclusionAI/Ming-3.0-audio-flash
- ModelScope: https://www.modelscope.cn/models/inclusionAI/Ming-3.0-audio-flash Ming-3.0-audio-tiny
- Hugging Face: https://huggingface.co/inclusionAI/Ming-3.0-audio-tiny
- ModelScope: https://www.modelscope.cn/models/inclusionAI/Ming-3.0-audio-tiny Ming-3.0-asr-tiny
- Hugging Face: https://huggingface.co/inclusionAI/Ming-3.0-asr-tiny
- ModelScope: https://www.modelscope.cn/models/inclusionAI/Ming-3.0-asr-tiny