Baidu Open-Sources Unlimited OCR 2 with Infinite Page Support
Baidu has officially released and open-sourced the Wenxin Unlimited OCR 2 model, pushing document parsing limits to 'infinite' by processing over 3,600 pages in a single pass. The model natively supports layout segmentation and cross-page merging, achieving end-to-end SOTA performance on both MPDocBench and MarathonDocBench benchmarks.
Related Entities
Full Report
IT Home reported on October 30 that Baidu officially released and open-sourced the Wenxin Unlimited OCR 2 model on October 27. This model pushes the upper limit of document parsing from dozens of pages to "unlimited," capable of parsing all seven books in the Harry Potter series—cumulatively exceeding 3,600 pages—in a single pass.
Unlimited OCR 2 natively supports layout element segmentation recognition and features cross-page text merging and table recognition/merging capabilities, allowing it to process more content faster and more efficiently with the same computational resources.
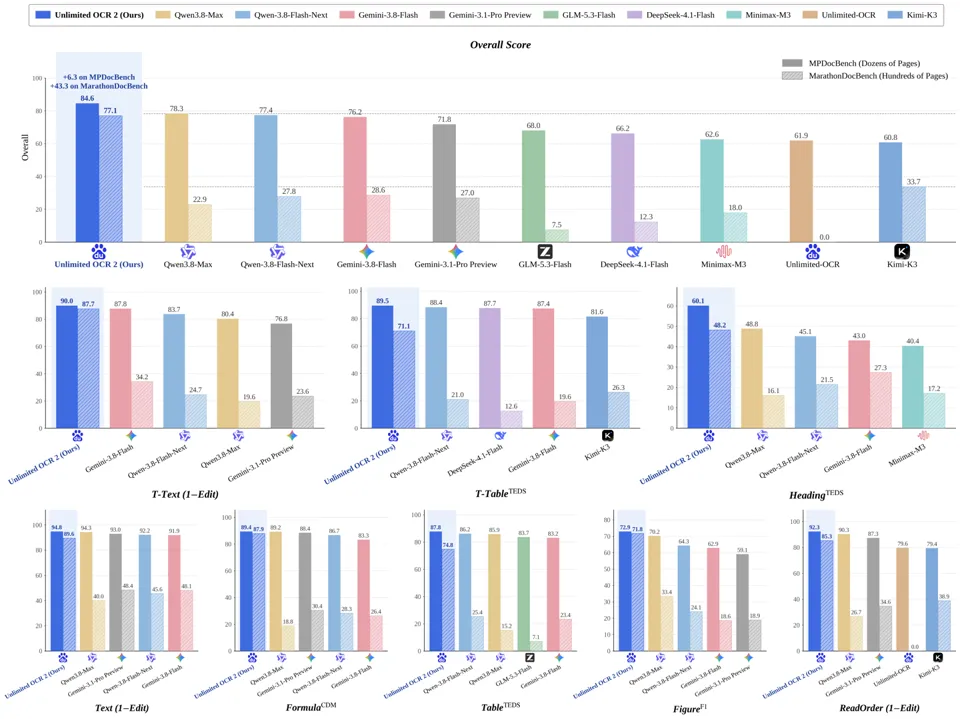
According to Baidu, Wenxin Unlimited OCR 2 achieved a score of 84.6 on MPDocBench, a benchmark for multi-page document parsing, and 77.1 on MarathonDocBench, which specifically evaluates ultra-long document parsing capabilities (hundreds of pages). Both results represent state-of-the-art (SOTA) end-to-end performance.
References
Advertisement Disclosure: External links contained in this article (including but not limited to hyperlinks, QR codes, and command codes) are provided to convey additional information and save selection time. Results are for reference only. All IT Home articles containing external links include this disclosure.