Hugging Face Releases Qwen3.8 Coding LoRA Adapter Boosting Success to 65%
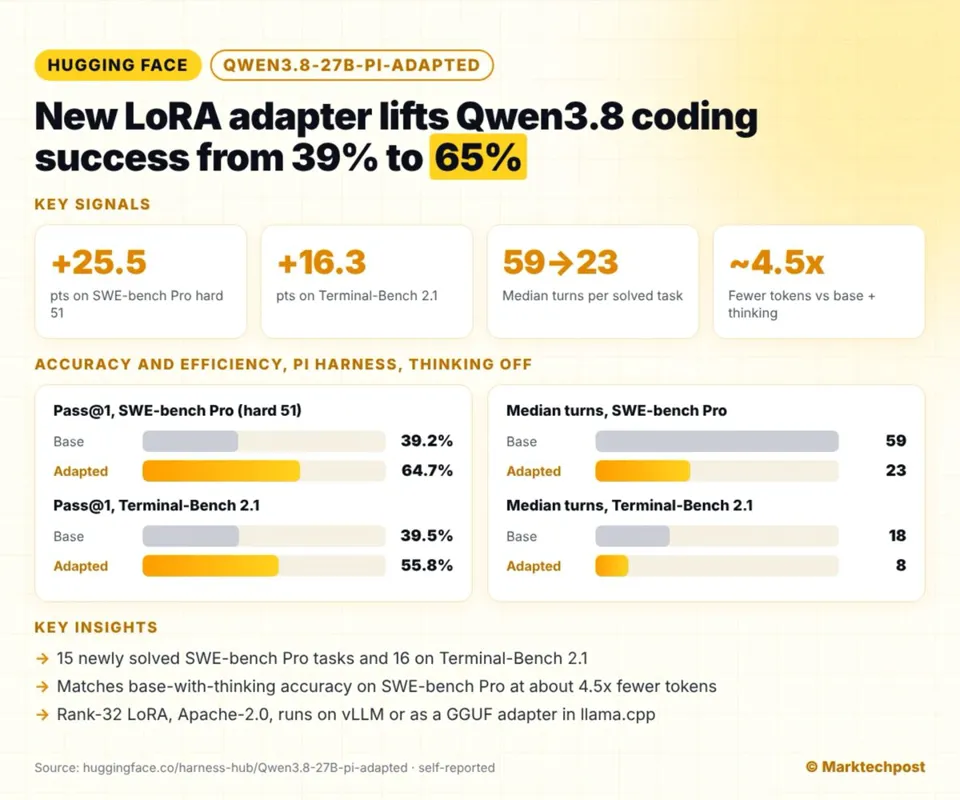
Hugging Face released Qwen3.8-27B-pi-adapted, a LoRA adapter trained for the pi coding agent that lifts SWE-bench Pro pass@1 from 39.2% to 64.7% and Terminal-Bench 2.1 from 39.5% to 55.8%. The approach pairs one small adapter per model and harness, trained with AsyncGRPO reinforcement learning inside pi and rewarded for fewer tool calls, cutting median turns on solved tasks from 59 to 23 while using roughly 4.5x fewer tokens than the base model's thinking mode. The rank-32 LoRA ships under Apache-2.0 and runs on vLLM or as a GGUF adapter in llama.cpp.
Related Entities
Full Report
▲ Marktechpost AI · 2026-11-18 16
▲ Hugging Face just released Qwen3.8-27B-pi-adapted, a LoRA adapter that lifts Qwen3.8 coding success from 39% to 65% inside the pi coding agent.
The key idea is 1 small adapter per model and harness. The team trained it with reinforcement learning (AsyncGRPO in TRL) directly inside pi, on 750 scale800 and 300 TermGrade tasks. The reward pays for correct answers and gives a bonus for using fewer tool calls.
With thinking off, SWE-bench Pro (hard 51) pass@1 jumps from 39.2% to 64.7%, and Terminal-Bench 2.1 from 39.5% to 55.8%. Sessions get much shorter too: median turns on solved SWE-bench Pro tasks drop from 59 to 23. It matches the base model's thinking-mode accuracy while generating about 4.5x fewer tokens.
Rank-32 LoRA, Apache-2.0, ready for vLLM or as a GGUF adapter in llama.cpp......
Full analysis: [ARTICLE URL]
Model: