DeepSeek V4.1 Flash Gains Up to 1.5x Per-Agent Speed on GB300 NVL72
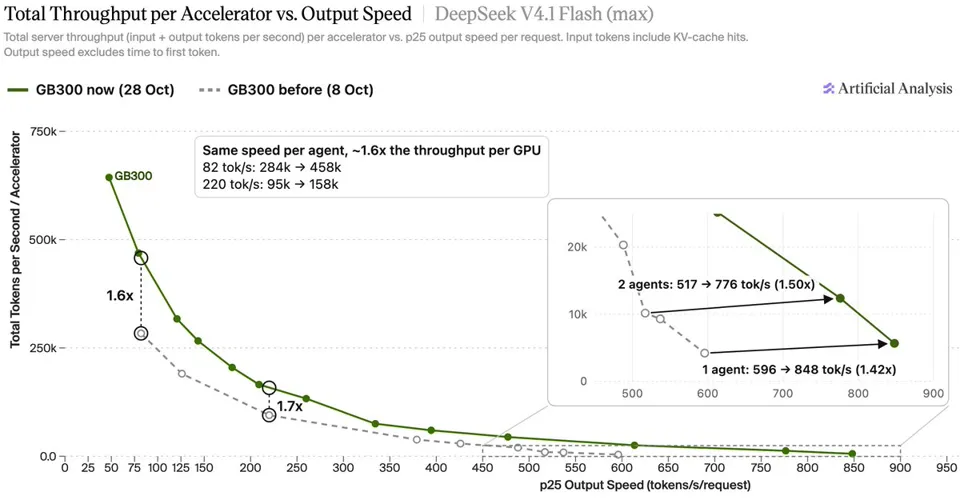
Artificial Analysis' AA-AgentPerf benchmark shows DeepSeek V4.1 Flash on GB300 NVL72 rising from 596 to 848 tok/s for a single agent (1.42x), with roughly 1.6x throughput per GPU at ~80 tok/s per agent. The gains stem from a newer vLLM release with GB300-specific kernels, FlashInfer autotuning, fuller CUDA graph coverage, tuned speculative decoding, and co-locating prefill and decode on the same GPUs in NVIDIA's updated Dynamo + vLLM stack.
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-06 20
DeepSeek V4.1 Flash speeds on GB300 NVL72 have increased by up to 1.5x tok/s per agent over the past month on AA-AgentPerf, our benchmark of datacenter systems running realistic agentic coding workloads
This improvement comes from a newer vLLM version, new vLLM kernels for DeepSeek V4.1 on GB300, FlashInfer autotuning, fuller CUDA graph coverage, tuned speculative decoding, and running prefill and decode on the same GPUs in NVIDIA’s updated Dynamo + vLLM setup
➤ Faster speeds: 848 tok/s for a single agent, up from 596 (1.42x)
➤ Higher throughput: ~1.6x the throughput per GPU at ~80 tok/s per agent