Liquid AI Open-Sources d1 Decision Models: 3B Params Achieve 8ms Inference with Multimodal Support
Liquid AI has released and open-sourced the d1-3B and d1-omni-600M decision models, emphasizing ultra-low latency and multimodal capabilities. The d1-3B model achieves 8ms text inference on an RTX 4090 and leads in Decision Index v0.2.1 benchmarks among sub-10B models. The d1-omni-600M variant adds voice input support, offering a lightweight solution for real-time agent applications on edge devices.
Full Report
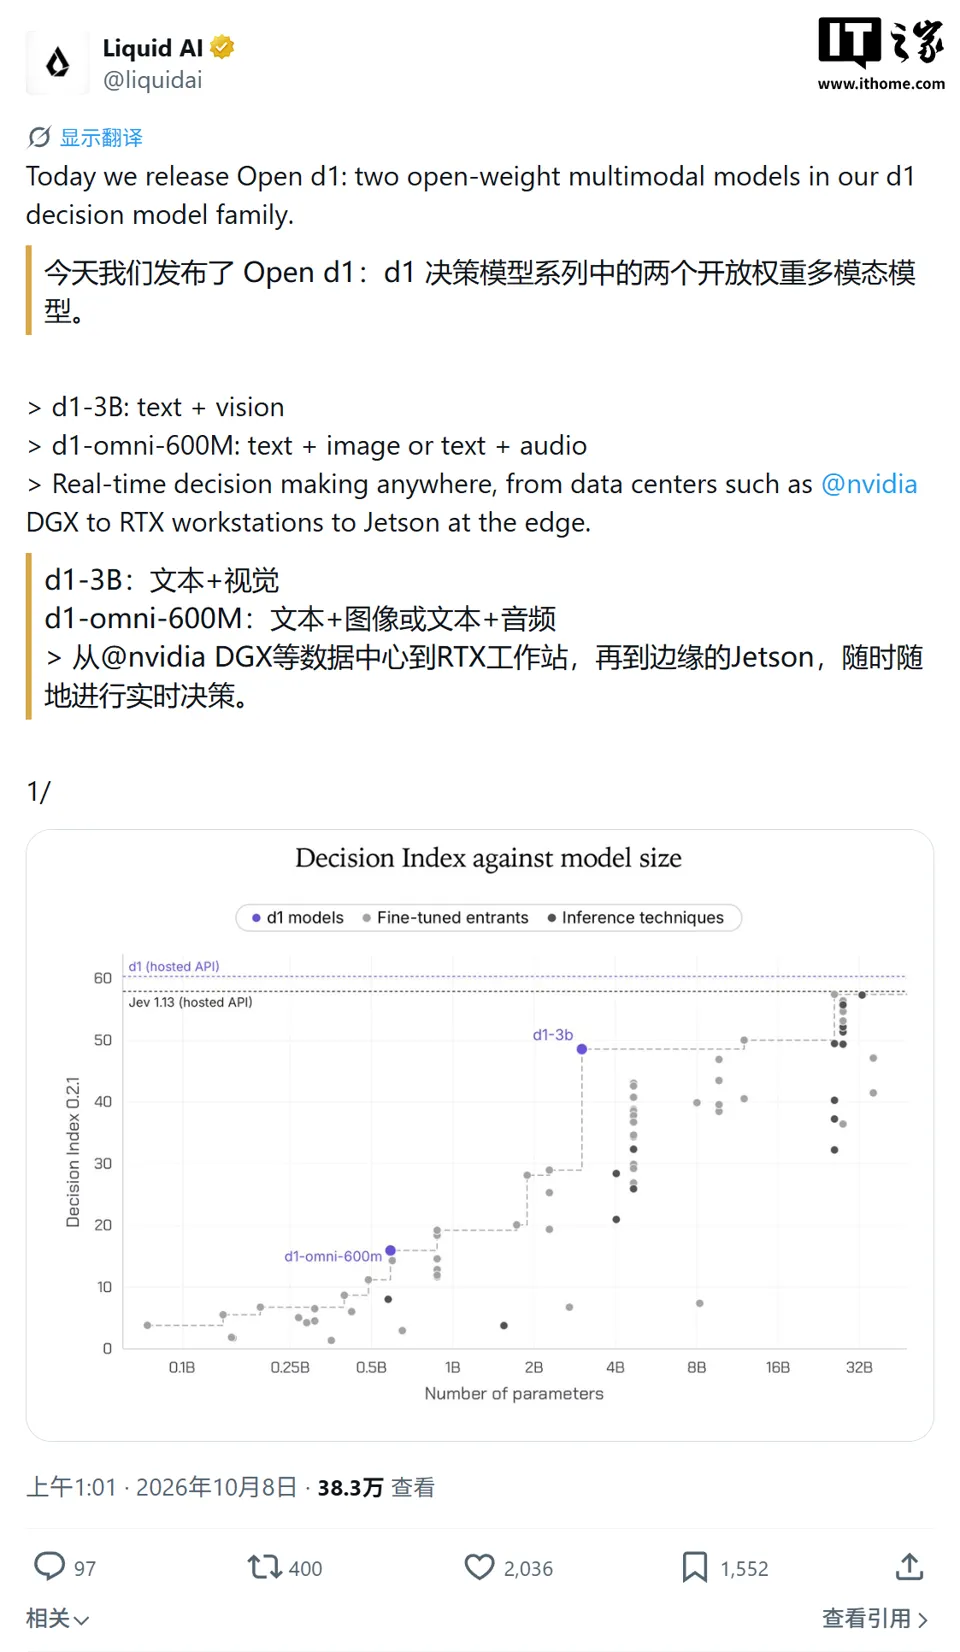
On October 9, it was reported that Liquid AI published a blog post on October 7 announcing the release of two open-weight decision models in its d1 series: d1-3B, which supports text and image judgment with 3.12 billion parameters, and d1-omni-600M, which handles text, image, and audio inputs with 587 million parameters.**
As cited by IT Home from the blog post, following the viral launch of Jev models in September, companies like OpenAI have also successively released similar decision models. Liquid AI is the latest entrant to this competitive landscape. The newly launched d1-3B and d1-omni-600M are now available on Hugging Face, allowing users to download, fine-tune, and deploy them.
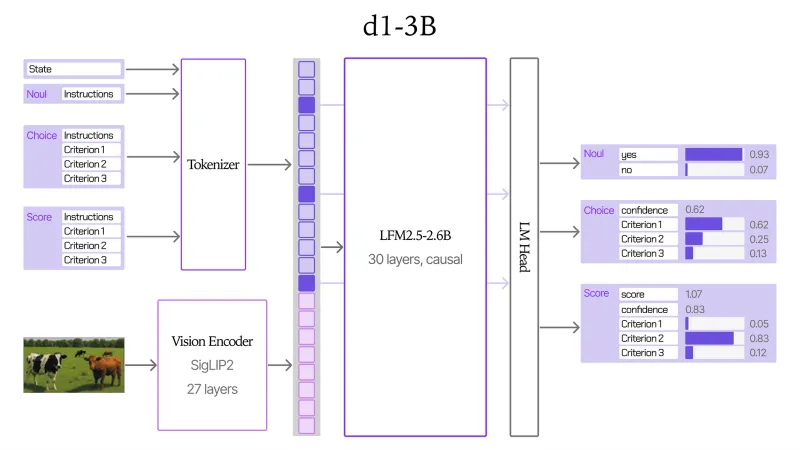
The d1-3B model features 3.12 billion parameters and is trained on the vision-language model LFM2.5-VL-3B, supporting both text and image inputs. It achieved a score of 48.57 on the public test set for Decision Index v0.2.1, with Liquid AI claiming it leads all models under 10 billion parameters.
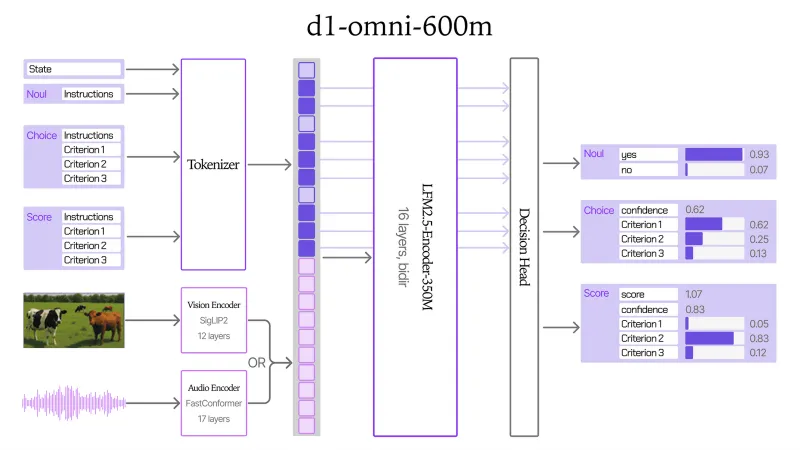
The d1-omni-600M model has 587 million parameters and is built upon the bidirectional encoder LFM2.5-Encoder-350M. This model supports combined inputs of text and images, or text and audio, marking it as Liquid AI's first experimental multimodal decision model checkpoint.
Regarding inference speed, the d1-3B model answers a single question in 8 milliseconds on an NVIDIA RTX 4090, while processing a 384-pixel image takes 102 milliseconds. On the Jetson AGX Thor, single-question latency is 16 milliseconds; on the Jetson Orin Nano, it is 50 milliseconds.
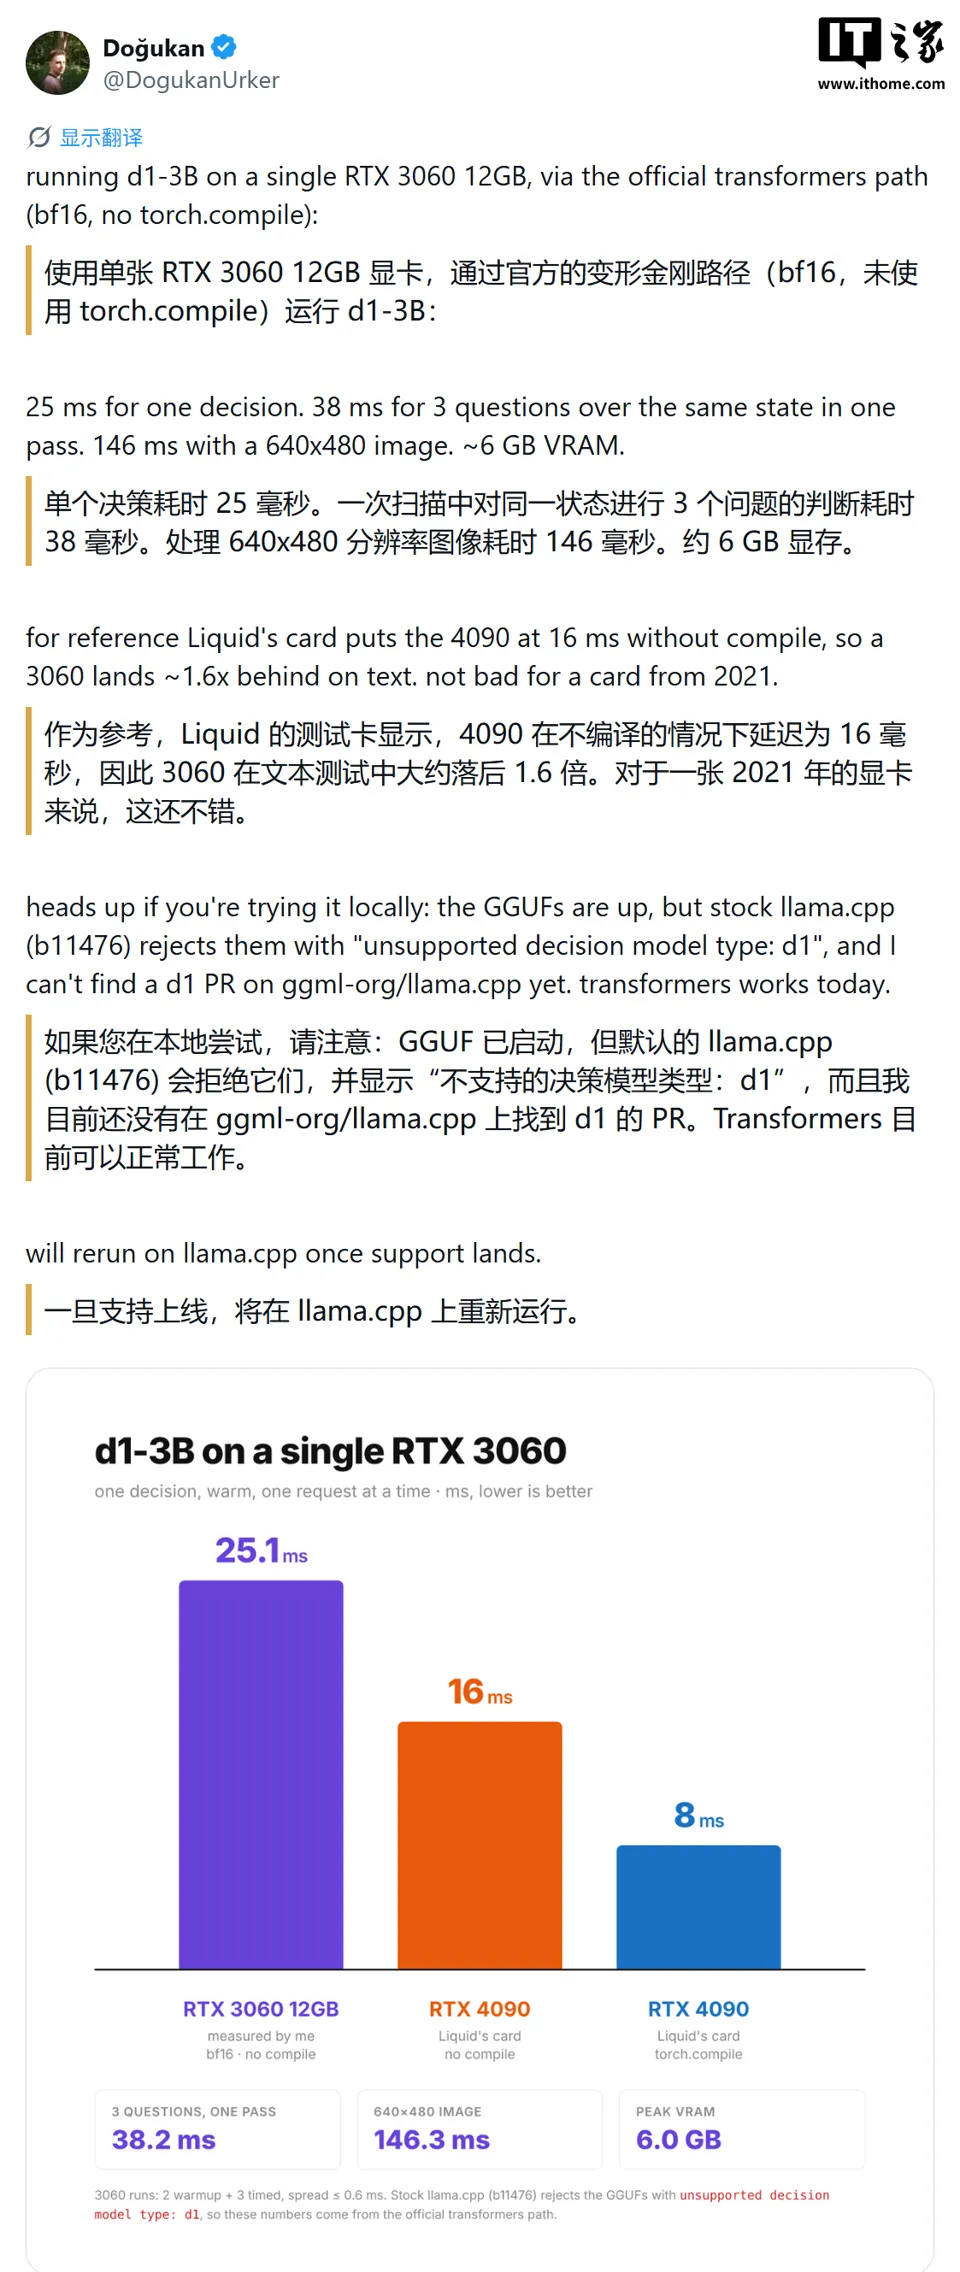
User tests indicate that on a GeForce RTX 3060 with 12GB of VRAM, the d1-3B model completes a single inference in 25 milliseconds, with processing a 640×480 pixel image taking 146 milliseconds and peak VRAM usage at approximately 6GB. Additionally, some users reported that the model achieves 8-millisecond single-inference times on an RTX 3090.