量子位 (微信公众号) · 10/20/2026, 12:06:00
MemT 1.0 Released: Native Memory Architecture Scales to 300B Parameters
MemTensor has open-sourced the MemT 1.0 series, marking the first engineering validation of a 'memory-native' architecture at nearly 300B parameters. By embedding parallel memory pathways within Transformers, it encodes experiences as learnable internal dynamic states, addressing long-term memory and knowledge retention challenges in AI Self-Improvement (RSI).
SOURCE COVERAGEFull Original Report
Contents6 sections
Welding Memory Natively into Transformers
By Lu Yu, reporting from "Ao Fei Si"
QbitAI | Official Account: QbitAI
The AI community has recently been collectively focused on three letters: RSI.
Hinton’s RSI paper features 22 signatories, including Bengio, OpenAI Chief Scientist Pachocki, and Anthropic co-founder Jack Clark... essentially half of the AI industry's heavyweights are represented here.
While attention shifts toward AI self-improvement, a more fundamental question emerges:
How does one improvement become the starting point for the next?
Effective methods need to be retained, and missteps need to be identified. The mechanism responsible for this is, in fact, memory.
The conventional approach is straightforward: attach an external experience library to the AI, allowing operational procedures and historical lessons to be stored and retrieved.
Memory Tensor, however, offers a completely different answer through its exploration of native memory.
What is native memory? It involves turning the retention, updating, and retrieval of experiences into capabilities that the model can learn.
When memory takes root within the model, it constitutes a native-memory model.
Their latest open-source release, the MemT 1.0 series, provides a concrete path forward:
It encodes experiences into internal dynamic states, learns how to write, update, and read these states through training, and finally allows these states to participate in subsequent computations via a dedicated memory branch.
Compared to external memory, not only is capability preserved without compromise, but the ceiling for future scalability is also higher.
This marks the first time a native-memory model has achieved engineering validation at a scale approaching 300 billion parameters.
(Paper link: https://arxiv.org/abs/2610.26825)
Remarkably, although memory is intangible, it has solidly become the foundation for model growth.
From early requirements for models to simply remember information, to effectively leveraging experience, demands on memory have continuously escalated, moving it step by step from behind the scenes to the forefront.
Embedding Memory into the Model
MemT 1.0 directly introduces two variants:
MemT-1.0-Nano has a total of 36B parameters with 3B active, built upon the base model "Source God" Qwen3.6-35B-A3B; MemT-1.0-Flash pushes boundaries further, reaching 288B parameters with 17B active, based on DeepSeek-V4-Flash which has undergone further post-training.
The common change in both is the addition of a parallel memory computation pathway alongside the existing attention mechanism within selected Transformer modules.
Let’s illustrate with a simple example.
Consider facing a new task. The external memory approach involves stuffing raw memory text, retrieval evidence, and even abstract methods back into the context, allowing the model to reuse experience.
Learning mechanisms can also be introduced into the retrieval and organization process.
In contrast, native-memory models like MemT 1.0 choose to delve deeper into the model's internals:
Experiences are encoded into updatable matrix states; when the model generates answers or actions, it reads these states via a dedicated memory branch. The read results are then fused with the original attention outputs, influencing subsequent generation.
The distinction lies in how experience is represented and through what computational process it exerts its effect.
The benefits are clear: involving read/write operations in training enables smoother method reuse. However, there are trade-offs: precise deletion, explanation, and recovery require additional mechanisms.
External text is undoubtedly easier to inspect and trace. Currently, both approaches have their respective pros and cons.
To truly see the difference, one must observe how the model performs after utilizing experience.
First, consider a scenario familiar to developers: code modification.
The typical workflow involves receiving a bug report → locating the code → making modifications. But if the issue isn't reproduced initially or boundary conditions aren't confirmed, fixes often introduce new vulnerabilities, propagating errors downstream.
Take SWE-bench Verified as an example. One task involves fixing the parsing logic for two-digit years in Django's parse_http_date function.
The research team compared execution trajectories under three settings: no experience, textual experience, and native memory.
Without experience, the Agent quickly began modifying the parsing logic after finding the bug, only introducing targeted reproduction and verification in later steps. Both groups with experience first constructed reproduction tests before modifying the code.
Notably, MemT-1.0-Nano re-checked a boundary condition after the initial modification, corrected the implementation, and performed additional verification.
It is evident that experience altered the sequence of actions and participated in intra-task checking and correction.
On a larger sample comparison across 500 SWE-bench Verified tasks, each run independently three times, MemT-1.0-Nano achieved an average success rate of 69.73% at critical breakpoints, compared to 66.07% for the baseline without experience and 69.13% for the textual experience group.
The proportion of tasks succeeded in all three runs increased from 54.00% (without experience) to 62.80%, while the textual experience group reached 61.80%.
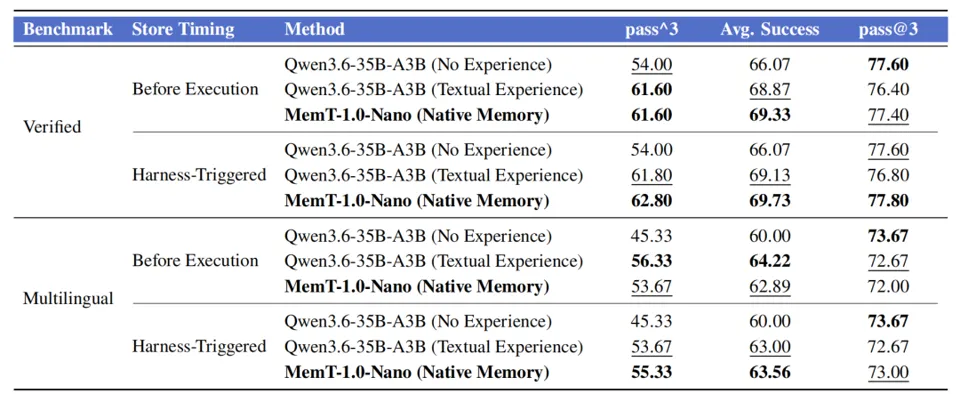
Looking at SWE-bench Multilingual tasks under the same trigger settings, the native memory group achieved an average success rate of 63.56%, compared to 60.00% for the no-experience group and 63.00% for the textual experience group.
In other words, procedural experiences can be retained through native memory, performing comparably to explicit textual experiences, with advantages primarily reflected in average success rates and reliability during repeated executions.
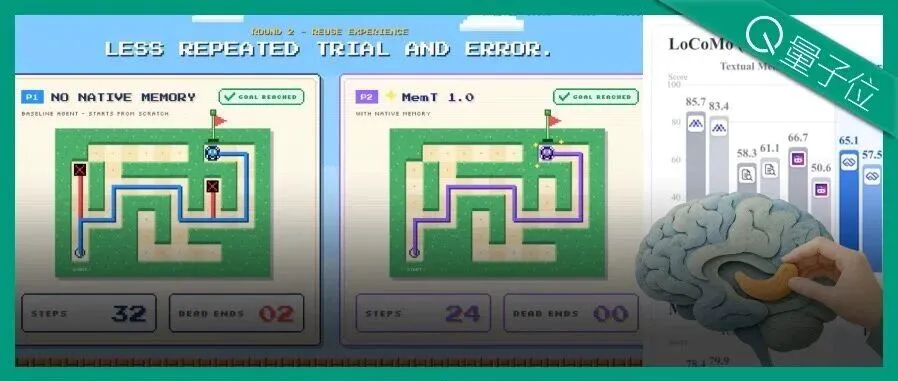
For a more intuitive demonstration, consider a pixel-art style maze exploration demo.
Using the same maze and movement speed, the left side shows an Agent without native memory, while the right side features MemT 1.0 with native memory.
Round 1: Both sides must explore unknown paths and both will hit dead ends.
The difference emerges after this round concludes: successful routes and岔paths to avoid are organized, archived, and loaded into MemT 1.0's memory, providing reference for the next round of exploration.
In the second round, starting again from the origin, the left path still repeats trial-and-error at the fork, while the right path leverages experience from the previous round to avoid dead ends already explored and reaches the destination via an effective route.
The paths established in the previous round begin to directly influence how the next round is navigated. This is a concrete manifestation of why "memory-native" approaches are worth pursuing.
Here is another scenario closer to our daily office work: information updates.
An exhibition was originally scheduled for Saturday at 3 PM, then officially changed to Sunday at 4 PM. Later, someone suggested moving it to Monday, but this decision has not yet been finalized.
This kind of incremental information with repeated changes is actually quite challenging for AI.
It is not enough to simply remember the last date mentioned; the system must also distinguish between official decisions and casual suggestions, while preserving content that remains unchanged.
After multiple rounds of dialogue, MemT-1.0-Nano still successfully grasped the context, correctly answering the original time, the officially revised time, and confirming that other arrangements remained unchanged.
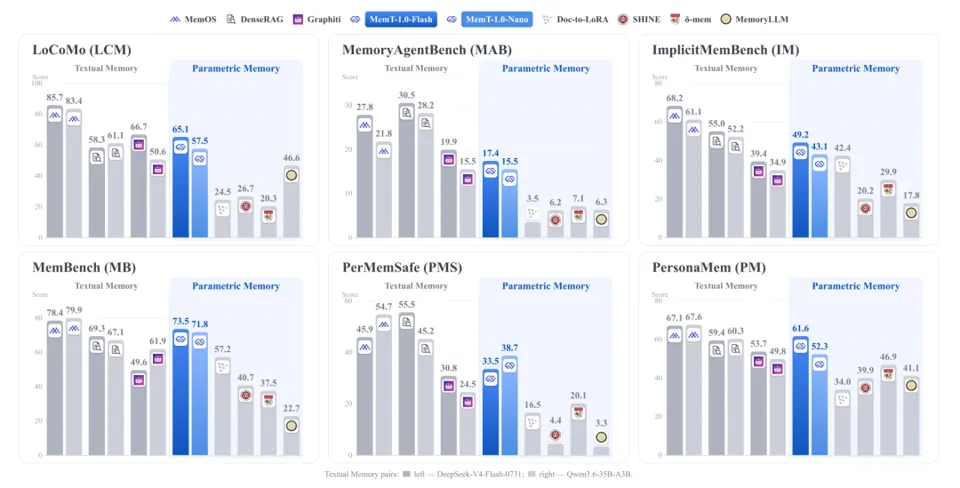
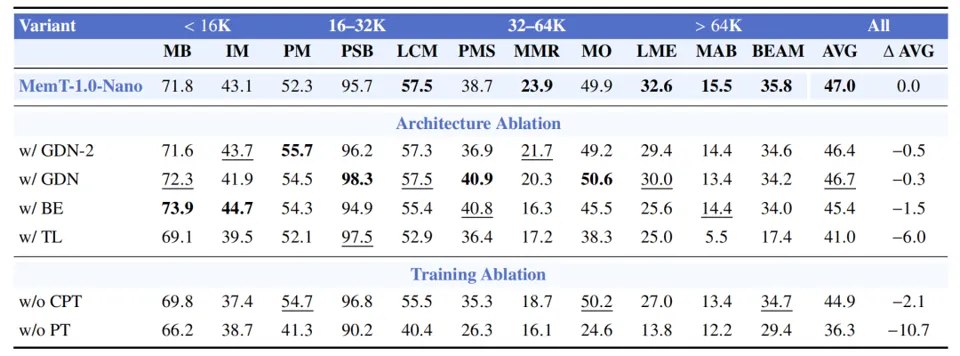
In comprehensive evaluations across 11 memory benchmarks, Flash and Nano also demonstrated outstanding performance.
With average scores of 50.6 and 47.0 respectively, they ranked first and second among the parametric memory methods evaluated, leading other models by a significant margin.
However, to be frank, text-based memory systems still hold an overall advantage, particularly in recalling details from long histories.
What MemT 1.0 presents today is merely an initial computational implementation of the memory-native paradigm. Yet its actual performance already rivals that of text-based memory systems, suggesting infinite potential as development continues.
Memory-Native: What Makes It Native?
So the question arises: if experience is not retained within the task context, where does the model retrieve and utilize it?
This is precisely the focus of MemT 1.0's architecture.
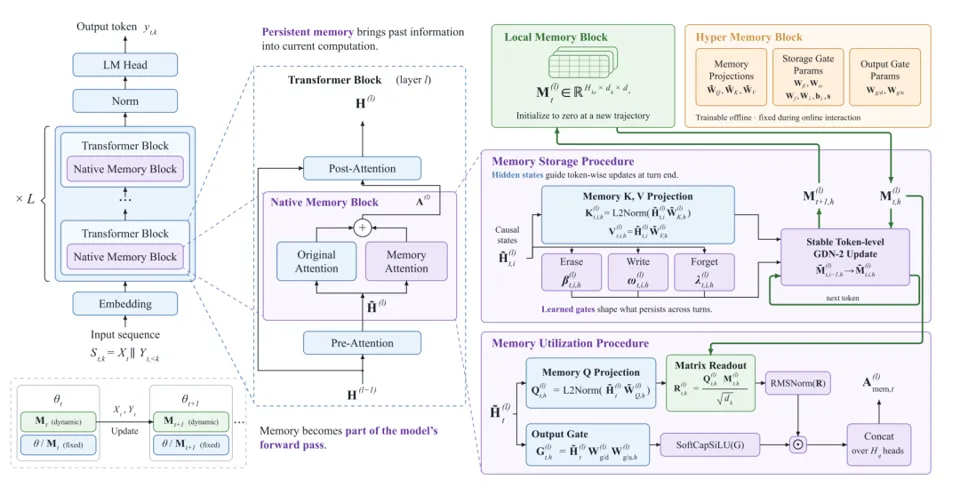
The native pathway provided by MemT 1.0 first encodes relevant experiences into internal dynamic states. When generating subsequent actions, the current query reads this state via a dedicated memory branch, and the result is fused with the original attention output.
In terms of specific parametric implementation, MemT 1.0 preserves the base model's original computational flow, adding a native memory branch to selected Transformer modules. Broken down, this includes three layers:
- Backbone Weights: Carry the model's existing general capabilities and remain frozen during memory training.
- Hyper-Memory: Trainable parameters such as read/write projections and gating mechanisms determine exactly how memories are encoded, updated, and retrieved.
- Local Memory: Dynamic matrix states store new information added during interactions.
By making these distinctions, the model can incorporate new experiences without needing to fine-tune the entire backbone every time; only the dynamic states corresponding to the task trajectory change.
The read/write mechanism of this system is also highly sophisticated.
During writing, hidden states undergo projection to generate memory keys and values; erase, write, and forget gates jointly regulate associations within the existing matrix. During reading, the current input is mapped to a memory query to retrieve relevant information, which then passes through normalization and output gating to participate in subsequent generation.
The update mechanism employs token-by-token generation based on Gated DeltaNet-2, with stabilization measures applied.
(Insider info: The author of Gated DeltaNet-2 participated in related discussions.)
It triggers after each round concludes, using gating to adjust existing memory associations, while within a round, states are adjusted sequentially per token.
Ablation studies confirm this: replacing token-by-token updates with whole-round aggregation caused Nano's average score on memory benchmarks to drop from approximately 47.0 to 41.0.
This six-point gap sufficiently demonstrates that continuous token-level updates better handle memory decay and timely correct intra-round associations.
But what happens when the volume of memory content expands beyond the model's capacity?
At this point, MemT 1.0 leverages MoE (Mixture of Experts) to propose the MoS* (Mixture-of-Storage)* solution.
MoS expands a single memory-native module into multiple memory experts, learning storage and usage routing separately. It adopts dense fusion, where all memory experts participate in computation, and routing weights determine their respective contributions.
This differs significantly from the sparse expert routing found in base MoE architectures.
However, structure is just the starting point.
To ensure the model truly learns to use this pathway, the team constructed a 34-billion-token memory training corpus, comprising 20 billion tokens for continued pre-training and 14 billion tokens for post-training.
The format for continued pre-training is uniform: long texts are first segmented into continuous chunks and written into memory, after which the model uses its memory state to answer queries.
After processing each chunk, the model updates its state for use in the next segment.
Post-training further aligns task outcomes. The data includes three categories: memory-native language modeling data, memory storage and utilization data (such as summarization, continuation, and compression), and task data specifically designed to reinforce long-term memory.
One point deserves special mention: the previously frozen backbone serves as the teacher model, having access to the complete historical information. MemT 1.0 acts as the student, seeing only its own memory state. Through off-policy distillation, the student is aligned with the teacher's distribution.
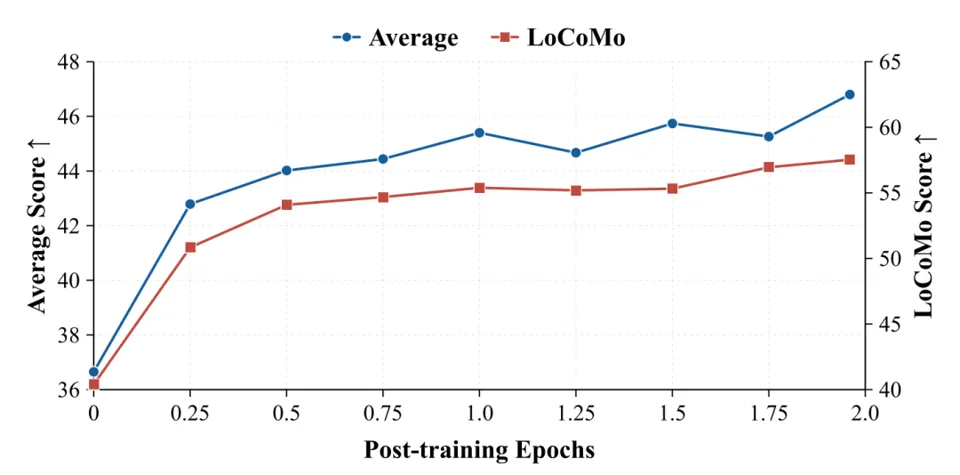
Synthesizing these elements, the focus of memory-native architectures becomes clearer: encoding history into state is merely the first step; how that state is preserved, updated, and read constitutes the entirety of a memory-native model.
The value of this approach must be evaluated comprehensively by considering experience reuse effectiveness, resource overhead, and conditions for long-term operation.
From Continual Learning to RSI: Memory Unlocks Room for Capability Growth
So, some might ask: Why use memory-native architectures?
Existing external memory solutions are already mature, with solid practical cases. In comparison, memory-native approaches are just getting started, and their performance is roughly comparable.
Not quite! Memory-native architectures have a unique advantage:
They make the representation, reading, and writing of experiences themselves objects for expanding model capabilities—what the MemT team refers to as Memory Scaling. This identifies a third curve for model performance growth, beyond inference scaling.
△ Image generated by AI
Previously, the utility of past experiences was judged by whether retrieval improved task results. With MemT 1.0, we can go further and ask: For the same experience, can different internal representations, update rules, and reading mechanisms yield better usage?
This introduces a set of variables adjustable through training and architectural design to improve memory effectiveness.
Admittedly, this does not yet prove that the long-term ceiling of native memory exceeds that of external memory. However, it demonstrates that training and capacity expansion around internal states can bring about further capability gains.
The next step is to verify whether these gains hold up outside the current training distribution, maintaining performance in longer interactions and on new tasks.
Returning to the concept of RSI mentioned at the beginning.
Once memory-native architectures are fully realized, they will significantly benefit breakthroughs in continual learning and Recursive Self-Improvement (RSI).
As is well known, RSI consists of three key components: memory, feedback, and verification/update mechanisms. Memory allows effective results to persist, while the latter two help determine which changes are worth incorporating into the next iteration.
What MemT 1.0 is currently exploring is precisely the step of carrying over and reusing experience. It validates that experience can guide actions via native memory, filling in the first—and arguably most important—piece of the puzzle from the model perspective.
△ Image generated by AI
If we push further, experiences accumulated in local memory could potentially be distilled into super-memory parameters through subsequent training, which would in turn improve how the model manages its memory.
Once this loop is established, systems might achieve an intelligence explosion across tasks by leveraging recorded results and methods—the ultimate goal of RSI.
These benefits remain theoretical for now. On the application side, memory-native architectures also facilitate enterprise experience accumulation.
Currently, when discussing enterprise AI, the primary focus is often on the early deployment stage, such as assessing whether the current model is usable and what it can accomplish.
While this is valid, enterprises realize the importance of experience accumulation only after prolonged use.
Long-term enterprise operations involve project rules, operational sequences, and validation methods. If every new task requires re-stating similar constraints and repeating similar failures, previous investments struggle to translate into subsequent returns.
Therefore, for such repetitive workflows, how many times validated experiences can be reused should enter enterprise AI selection criteria alongside single-instance model performance.
Memory-native architectures provide a model-side mechanism to support this.
With the same 128K long history, Nano’s end-to-end inference speed is approximately 1.86 times that of full-context solutions. For the same history length, the persistent state footprint per trajectory is one-sixty-sixth that of the full-context KV Cache.
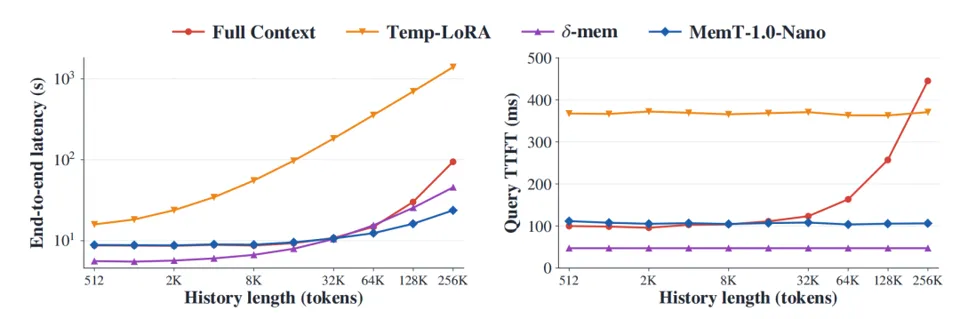
In plain terms, this represents immediate cost control benefits.
State budgets for long sessions are easier to estimate, and multiple queries can reuse built states, amortizing preparation overhead.
However, to be fair, memory-native architectures do not necessarily guarantee higher task quality than external memory. Yet, in scenarios where quality is comparable, they are more likely to steadily reduce rework through underlying experience reuse. This benefit is tangible for enterprise operations.
In other words, memory-native and external memory are not mutually exclusive adversaries. Collaborative division of labor between the two may yield greater additional benefits.
For queries requiring exact original text, sources, or versions, external records remain valuable. For invoking experience for subsequent execution, the role of native mechanisms can continue to be tested.
Regardless, when effective progress is retained and repeatedly validated across new tasks, it provides a foundation for accumulating improvements through continuous self-enhancement.
By implementing comprehensive hierarchical memory management and scheduling, optimal global read/write efficiency can be achieved. Today, the release of memory-native models has made this engineering deployment and implementation possible.
The value of memory in driving continuous self-improvement will gradually become apparent through such long-term validation.
GitHub Link: https://github.com/MemTensor/MemT-1.0 HuggingFace Link: https://huggingface.co/collections/MemTensor/memt-1
Like, Share, and Favorite!
We welcome your thoughts in the comments section!
— End —
🌟 Star Us 🌟
Daily Updates on Cutting-Edge Tech Progress