Voice Arena Launches Turing TTS Benchmark; Top Models Fool Listeners Only 10%
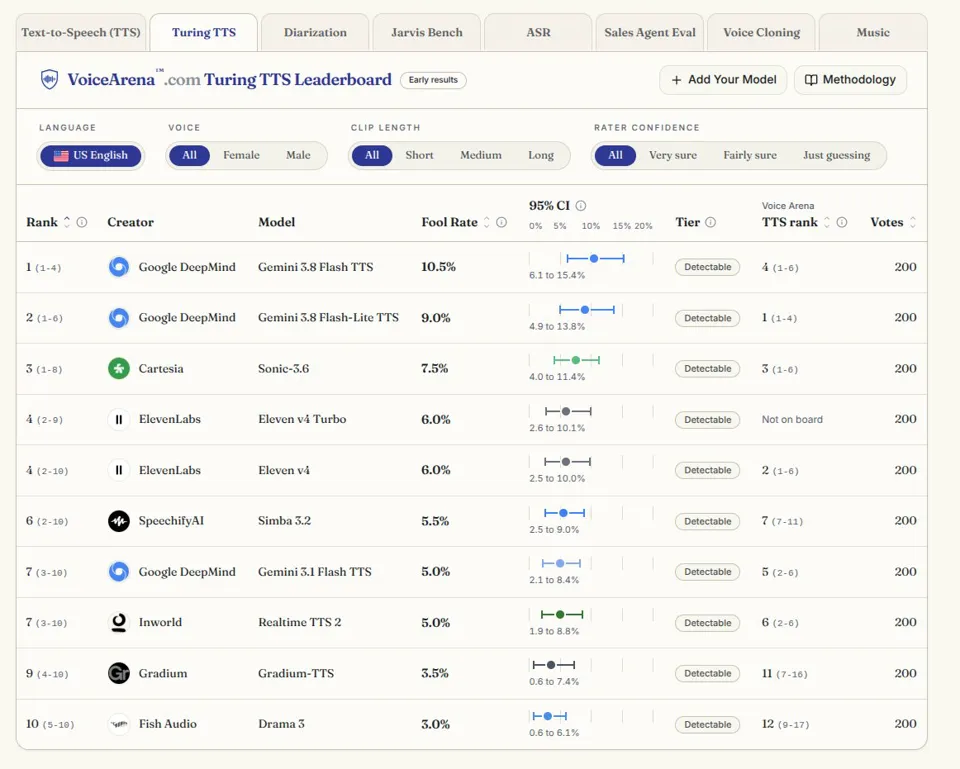
Voice Arena introduced the Turing TTS benchmark to decouple human-likeness from user preference in voice AI evaluation. Results show that even the top-performing model, Gemini 3.8 Flash TTS, fooled listeners only ~10% of the time, indicating a significant gap remains between current AI voices and real human speech.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-30 19
Voice AI is now good enough that preference and human-likeness can be scored as separate targets.
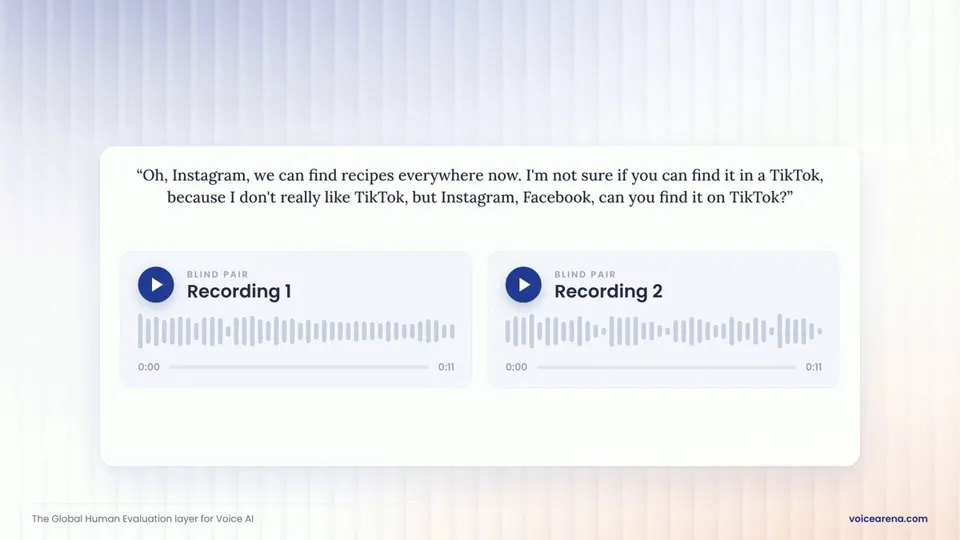
@voicearena_ai launched a new benchmark, Turing TTS to score the second one directly: listeners hear the same sentence from a person and from a model, then pick the person.
How often they pick the model is the Fool Rate. 50% would mean listeners can’t tell.
Even the best model, Gemini 3.8 Flash TTS, fooled them about 10% of the time.
On Voice Arena’s preference board, the top four models are statistically tied. Measured against a human, the whole field still has a long way to go.
↳ 引用 @shobhitbanga (Shobhit Banga): Drop 2/15
Are we actually measuring the things we ultimately want our voice AI models to achieve?
The best AI voices are becoming hard to tell apart. From each other. Not from humans.
🚀 Introducing Turing TTS: an evaluation that measures how often human listeners mistake AI-generated speech for real human speech.
We tested leading TTS models against real human speech. Even the best model fooled listeners only ~10% of the time.
With Turing TTS, we hope to contribute to a broader discussion within the research community about how we measure progress in voice AI.
If one of our goals is to develop speech that is indistinguishable from human speech, how well do our current evaluation methods capture progress toward that goal?
We don’t claim that Turing TTS is the right way forward, or that human indistinguishability should be the goal of every TTS system.
Rather, we hope these findings encourage the community to collectively examine whether blind pairwise human evaluations of naturalness are sufficient, and what else we might need to measure.
Results are now live on @voicearena_ai.