DeepSeek-V4.1-Flash Hits 1,129 Tokens per Second on Four AMD MI355X GPUs
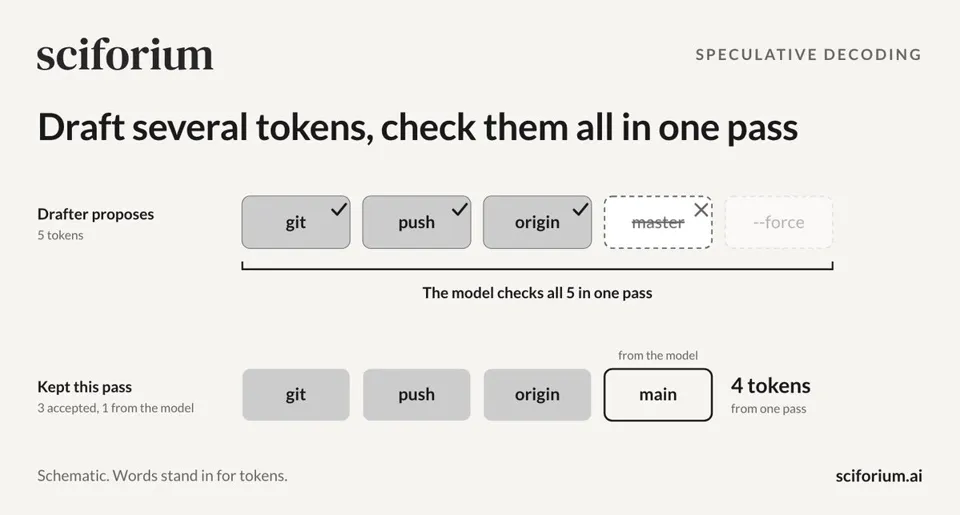
Sciforium deployed DeepSeek-V4.1-Flash on four AMD Instinct MI355X GPUs, reaching 1,129 output tokens/sec at P90 while keeping DeepSeek's original weights. The gains come from a traffic-tuned speculative decoding drafter that raises draft length to seven tokens, plus kernel work fusing small ops and overlapping all-reduce with compute. The result demonstrates AMD GPU viability for production LLM inference on real customer traffic.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-17 19
Sciforium shows DeepSeek-V4.1-Flash reaching 1,129 output tokens/sec at P90 on 4 AMD Instinct MI355X GPUs, keeping DeepSeek's original weights.
The gain comes from speculative decoding done better. Sciforium's Traffic-tuned Drafter is tuned on customer traffic, so more of its proposed tokens get accepted and draft length could be raised to seven tokens.
Separately, kernel work fused small ops like mHC and projections and fused all-reduce with compute.
At that rate, 10,000 tokens is about nine seconds of generation.
↳ 引用 @hassanience (Hassan Akbari): not long ago, people questioned whether AMD GPUs could keep up. today, we’re setting records on them. 1,129 output tps at P90. Real production traffic, not a toy project. a little faith, a lot of engineering. here’s how we did it. https://x.com/i/article/2122759644397674496