DeepSeek-V4.1-Flash 在 4 张 AMD MI355X 上实现 1129 tokens/s
Sciforium 在 4 张 AMD Instinct MI355X 上部署 DeepSeek-V4.1-Flash,P90 输出吞吐达 1129 tokens/s,且保留 DeepSeek 原始权重。性能提升主要来自面向真实客户流量调优的投机解码 Drafter(草稿长度提升至 7 token),以及算子融合与 all-reduce 与计算重叠等内核优化。该结果以真实生产流量验证了 AMD GPU 在大模型推理上的可用性。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-17 19
Sciforium shows DeepSeek-V4.1-Flash reaching 1,129 output tokens/sec at P90 on 4 AMD Instinct MI355X GPUs, keeping DeepSeek's original weights.
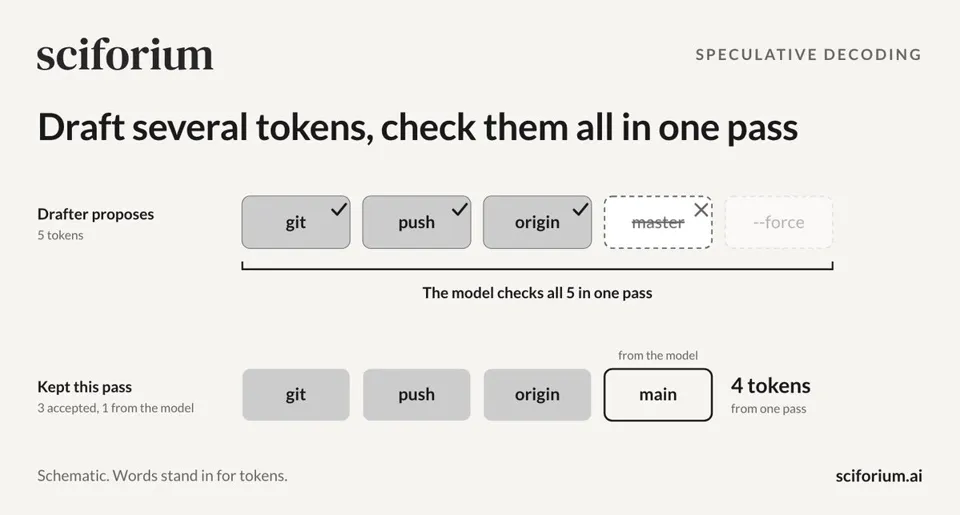
The gain comes from speculative decoding done better. Sciforium's Traffic-tuned Drafter is tuned on customer traffic, so more of its proposed tokens get accepted and draft length could be raised to seven tokens.
Separately, kernel work fused small ops like mHC and projections and fused all-reduce with compute.
At that rate, 10,000 tokens is about nine seconds of generation.
↳ 引用 @hassanience (Hassan Akbari): not long ago, people questioned whether AMD GPUs could keep up. today, we’re setting records on them. 1,129 output tps at P90. Real production traffic, not a toy project. a little faith, a lot of engineering. here’s how we did it. https://x.com/i/article/2122759644397674496