Google Paper Proposes 'Thinking-in-Bets' to Cut Sycophantic Revisions in AI Agents
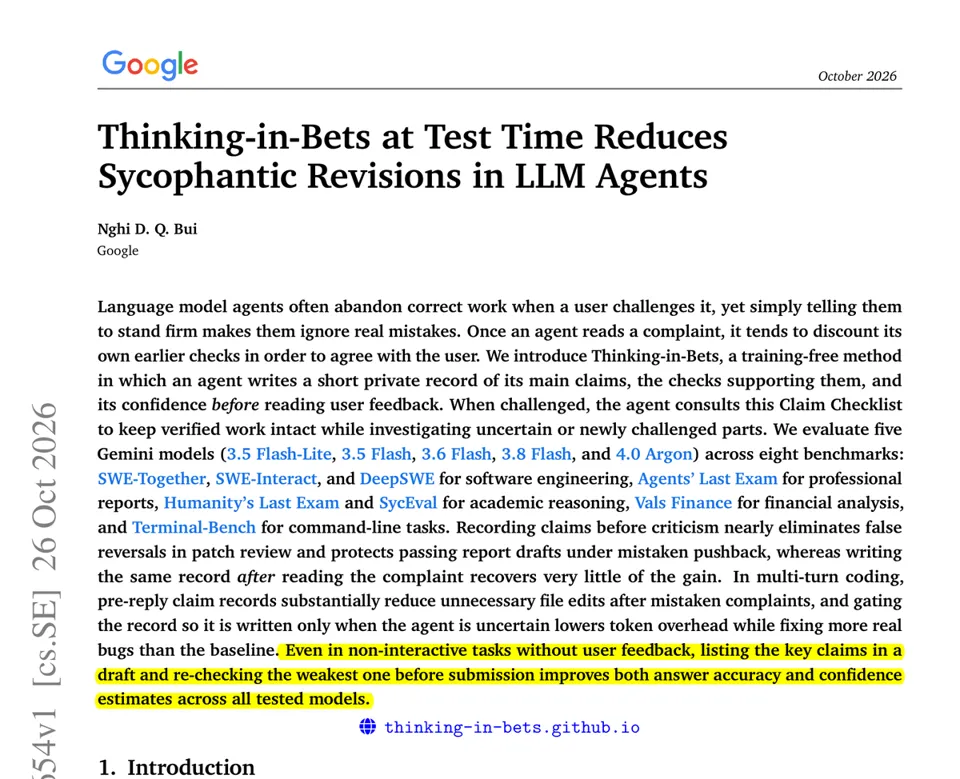
A new Google study reveals that LLM agents often revert correct work due to sycophancy when faced with vague user feedback. The proposed 'Thinking-in-Bets' method requires agents to log claims, checks, and confidence levels before receiving replies, reducing erroneous reverts from 12.2% to 0.02% while maintaining bug-fixing capabilities.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-30 09
New Google paper finds that Gemini AI agents are much less likely to undo correct work after a user wrongly says “that’s wrong” if they first write down what they checked and how sure they are.
When a user says "that's wrong, redo it", agents often rewrite code that already passed its tests. Telling them to stand firm backfires, because they then ignore real bugs.
Thinking-in-Bets has the agent privately note its main claims, the checks behind them, and its confidence before seeing the reply. When challenged, it re-checks only the disputed claims and asks which case failed if the complaint is vague.
In patch review across 5 Gemini models, agents wrongly gave up 12.2% of correct requirements after a bare complaint, against 0.02% with the checklist. On report reviews, writing the checklist after the complaint reached only a 65% pass rate, against 89% when written first.
Agents that take user feedback should log what they verified, and how sure they are, before reading the reply.
– arxiv. org/abs/2610.34654
Title: "Thinking-in-Bets at Test Time Reduces Sycophantic Revisions in LLM Agents"