NVIDIA Open-Sources Nemotron 3.5 Transcribe for Multilingual Overlapping Speech
NVIDIA released the open-weight speech model Nemotron 3.5 Transcribe, featuring an MoE architecture that supports 40 languages and precise transcription/diarization of up to 8 overlapping speakers. The model tops several open-source benchmarks and comes with the Granary v2 data pipeline, targeting use cases like meeting minutes and customer service.
Full Report
IT Home reported on October 29 that NVIDIA announced the release of its open-weight speech transcription model, Nemotron 3.5 Transcribe, yesterday (October 28), along with the public availability of its training data pipeline, Granary v2.
The Nemotron 3.5 Transcribe model integrates transcription, speaker diarization, translation, and audio question answering, primarily targeting scenarios such as meeting minutes, lecture recordings, interview organization, and multilingual customer service.
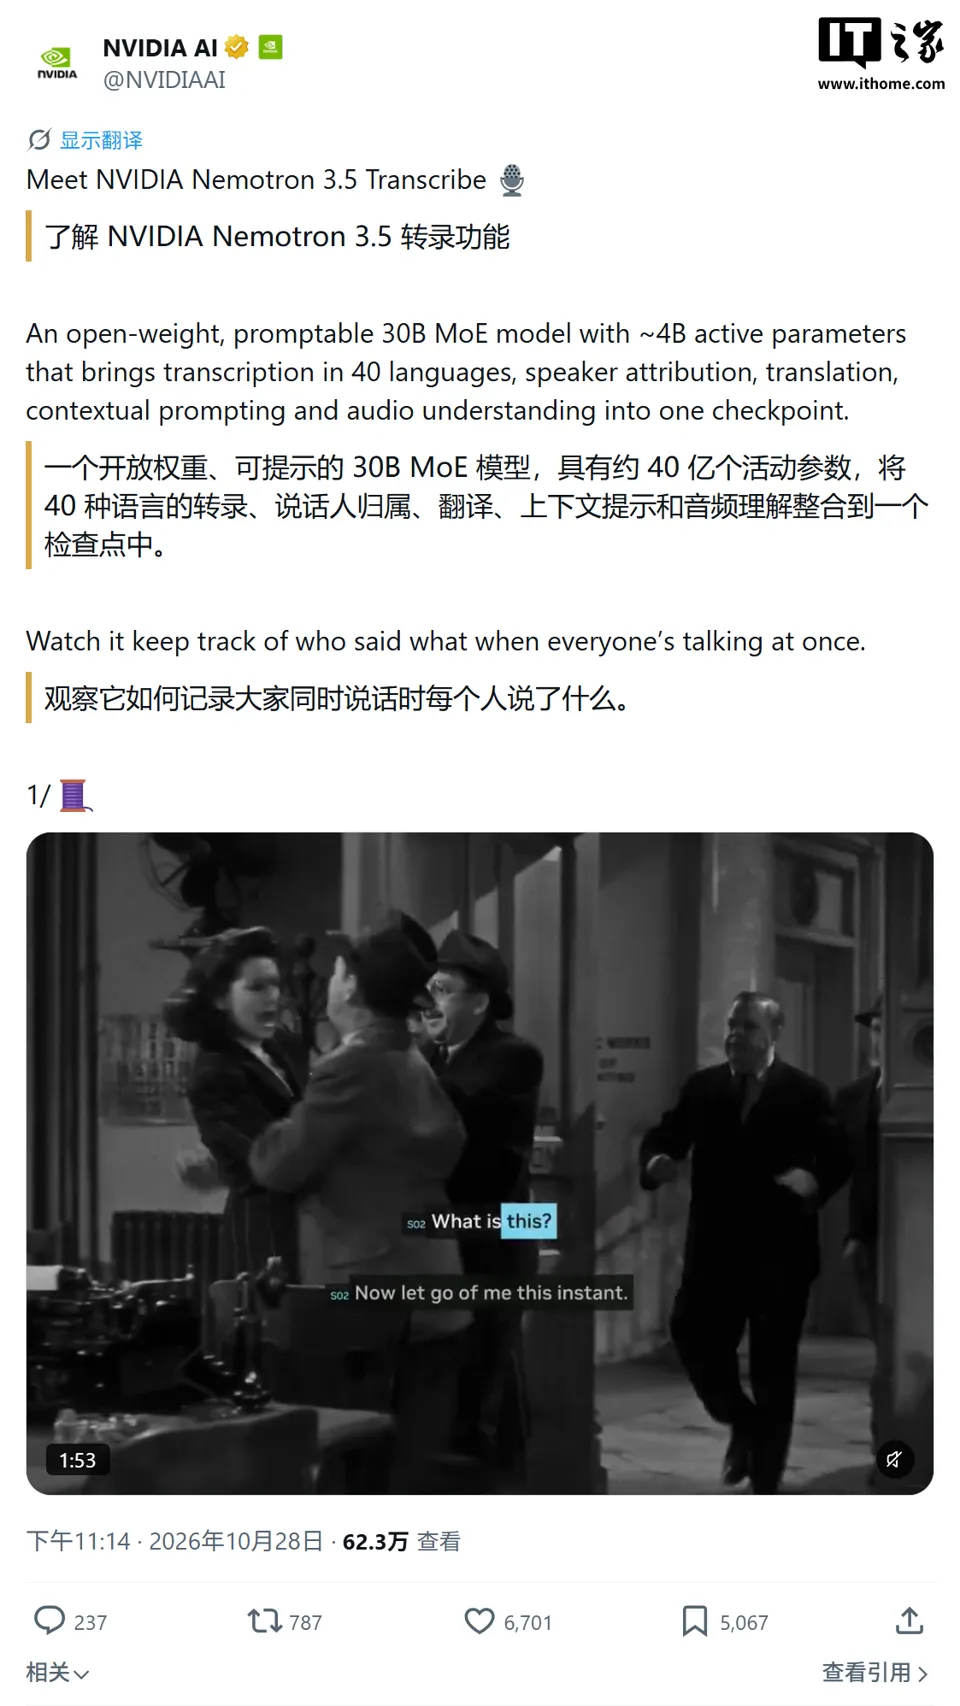
In terms of architecture, Nemotron 3.5 Transcribe employs a Mixture-of-Experts (MoE) structure with approximately 34 billion total parameters and around 4.3 billion active parameters. It can process recordings up to one hour in length and supports transcription for 40 languages, including mutual translation between 31 of these languages and English. Regarding speaker identification, it can distinguish up to 8 speakers and supports speaker labeling for 13 languages.
The model's standout feature is its ability to handle "simultaneous speech from multiple people." The model assigns speaker labels to each segment of speech during text generation. In official demonstrations, it successfully generated role-specific subtitles for scenes from the 1940 film His Girl Friday, which features extremely fast-paced dialogue with significant overlap.
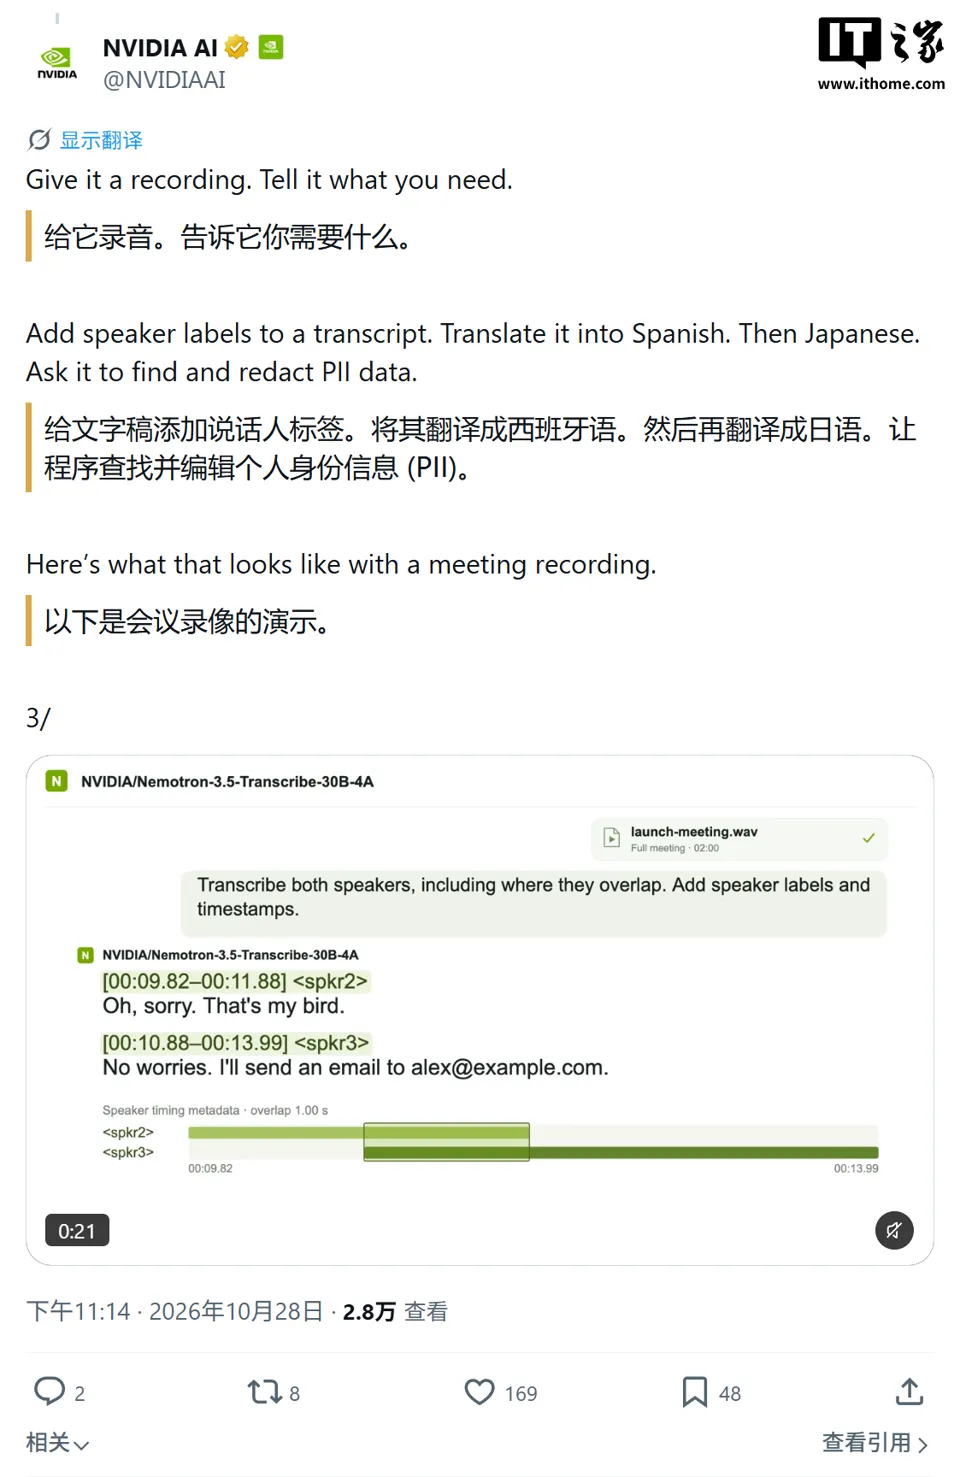
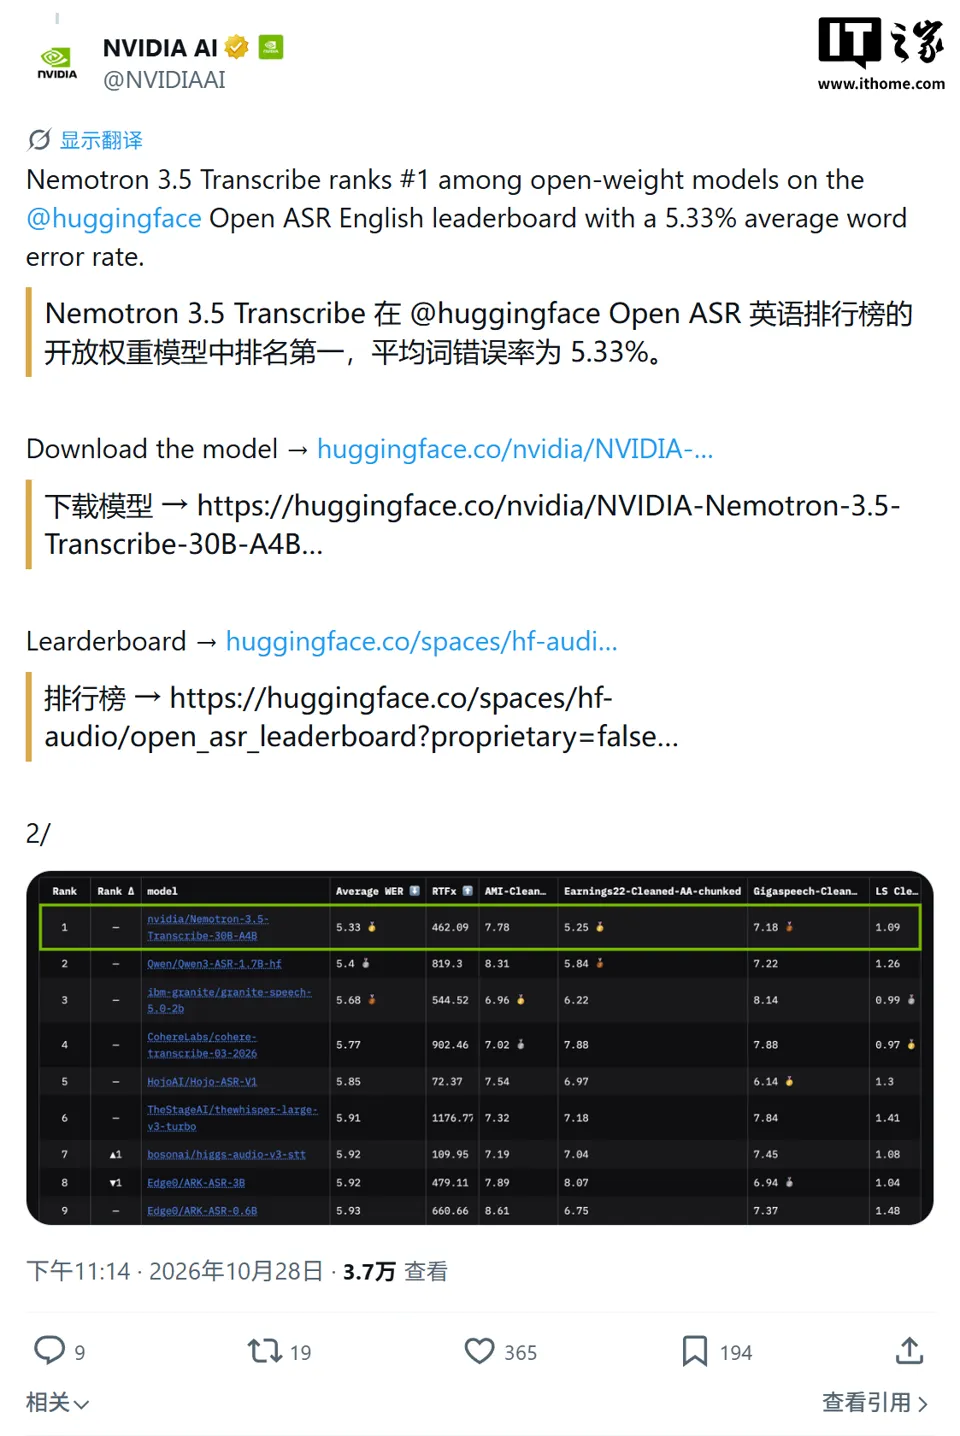
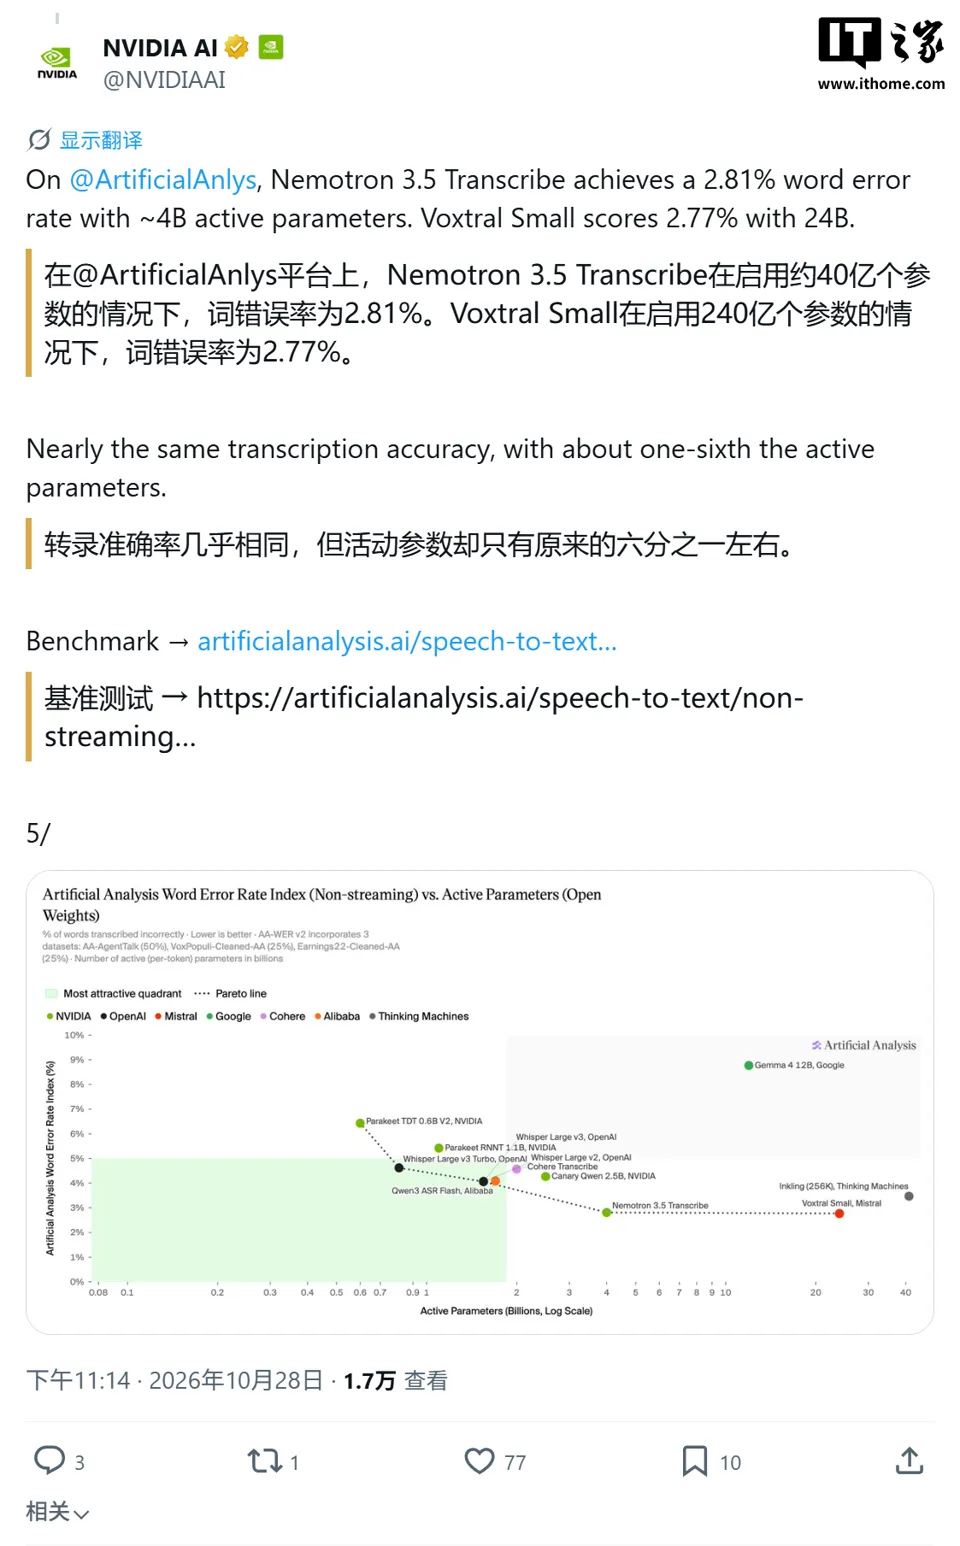
In public benchmarks, the model ranks first among open-weight models on the Hugging Face Open ASR Leaderboard for the English group, with an average Word Error Rate (WER) of 5.33%.
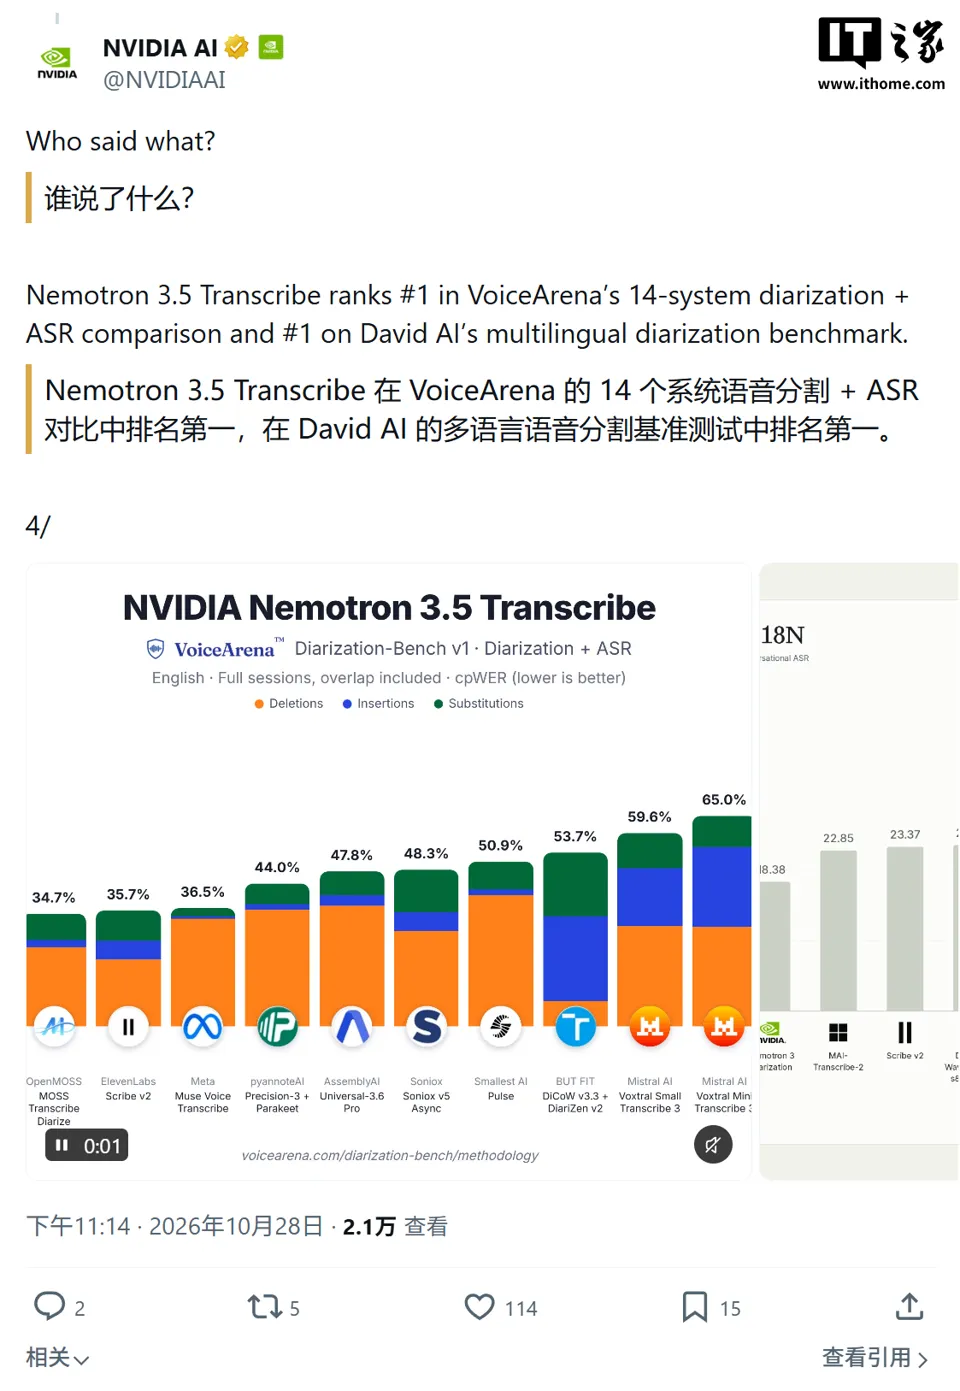
On Artificial Analysis's non-streaming WER index, it achieved a score of 2.8%, tying with Voxtral Small Transcribe for the top spot among open-source models. For speaker diarization, it recorded the lowest error rate of 18.26% on David AI's speaker separation benchmark across 21 languages. IT Home includes relevant images below:
The model is now freely available on Hugging Face and ModelScope under the OpenMDW-1.1 license. Quantized versions are expected to be released subsequently to facilitate local execution on devices such as RTX Spark, DGX Spark, and Jetson AGX Thor.
Granary v2 is an open, reusable training data curation pipeline and dataset built by NVIDIA for multilingual speech models like Nemotron 3.5 Transcribe.
It automatically processes raw or pre-annotated audio into various formats, including transcriptions, translations, subtitles, Q&A pairs, and instruction pairs, for use in ASR, speech translation, and speech instruction fine-tuning.
The publicly available Granary v2 data manifest covers 463,062 hours of audio, 48 languages, and 16 source corpora, representing a significant expansion compared to Granary v1's 25 languages.
For the same recording, Granary v2 generates at least three transcription variants corresponding to different written styles that the model may be prompted to produce:
- Text-Normalized Verbatim Transcript (
tn_raw): Retains disfluencies such as "uh" and "um," but normalizes textual forms like numbers. Example: "I paid, uh, twenty-five euros." - Inverse Text-Normalized with Disfluencies (
itn_raw): Converts spoken numbers back into written symbols while retaining disfluencies. Example: "I paid, uh, €25." - Inverse Text-Normalized Clean (
itn_clean): Outputs clean, readable text without disfluencies. Example: "I paid €25."