Hugging Face Blog · 10/20/2026, 08:00:00
Hugging Face Integrates TorchTPU for Native PyTorch Support on TPUs
Hugging Face announces native PyTorch support for Google TPUs via TorchTPU, eliminating the need for torch_xla or JAX. Developers can now directly run models from Transformers and Diffusers on TPU devices by simply specifying 'tpu', significantly lowering the barrier to entry for TPU-based AI development.
SOURCE COVERAGEFull Original Report
Contents10 sections
Hugging Face ❤️ TorchTPU: TPUs, Natively
Alvaro Moran tengomucho Jingya Huang Jingya Simon Pagezy pagezyhf Jeff Boudier jeffboudier Régis Pierrard regisss
If you ever tried to run PyTorch on a TPU, you probably ported your code to torch_xla, or you ended up having to learn JAX. With TorchTPU, a native PyTorch backend, TPU is now just another device. It opens up native support of TPU in the Hugging Face ecosystem. Transformers, Diffusers and Kernels run natively on TPU. Pick a model from the Hub, send it to "tpu", and you're done.
Wait, what's a TPU? 🤔
TPU stands for Tensor Processing Unit. TPUs are Google's own AI accelerators. They are chips built for one job: the matrix math that neural networks spend most of their time on. Google has been designing them for about ten years, and uses them to train and serve its own models, including Gemini.
TPUs are available on Google Cloud, from a single chip up to pods of thousands of chips. They shine when you need a lot of compute, for training or for serving at scale.
The catch has always been software. The TPU stack grew up around TensorFlow and JAX, and PyTorch users had to work harder to get in.
The old way
Until now, running PyTorch on TPUs meant going through PyTorch/XLA (torch_xla). It worked, but it had its quirks. Tensors were lazy (the tensors, not you), so your code didn't always run when you thought it did. Small changes could trigger graph recompilations, and debugging was hard to reason about.
To make life easier, we built Optimum TPU. It gave Hugging Face models inference and training support on TPUs. Now that TorchTPU brings native support, Optimum TPU is not required anymore to run Hugging Face models with Transformers and Diffusers.
Enter TorchTPU 🚀
TorchTPU adds TPU as a new backend to PyTorch. You write regular PyTorch code. It comes with Pallas kernels tuned for TPUs, support for distributed training, and a torch.compile integration for when you want more speed. Installing it on a TPU VM takes one command:
The extra index gives you the CPU build of torch. Without it, pip pulls the much bigger CUDA build, which you don't need on a TPU.
Your favourite libraries, now on TPU
Transformers
Transformers v5 was built around one idea: be the source of truth for model definitions, so they can run anywhere. "Anywhere" now includes TPUs. To load a model on a TPU, pass device_map="tpu". That's it.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "Qwen/Qwen3.5-9B"
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    device_map="tpu",
)
tokenizer = AutoTokenizer.from_pretrained(model_id)
inputs = tokenizer("The future of AI is", return_tensors="pt").to("tpu")
out = model.generate(**inputs, max_new_tokens=64)
print(tokenizer.decode(out[0], skip_special_tokens=True))
The model runs in eager mode by default. You can also use torch.compile for better performance, or run it in a distributed setup.
Images? Videos? Diffusers paints them on TPUs 🎨
TPU is now a first-class device in Diffusers. For prototyping or debugging, eager mode only needs pipe.to("tpu"). For deployment, compiled mode adds one compile call. Your pipelines and code stay the same, and there's no TPU fork to maintain.
import torch
from diffusers import StableDiffusion3Pipeline

pipe = StableDiffusion3Pipeline.from_pretrained(
    "stabilityai/stable-diffusion-3.5-medium", dtype=torch.bfloat16
)
pipe.to("tpu")

pipe.transformer.compile(backend="tpu", fullgraph=True, dynamic=False)

image = pipe("a corgi astronaut planting a flag on a pizza moon").images[0]
The first call compiles, and every call after that with the same image size reuses the graph.
Models too big for one chip? Pass a TensorParallelConfig to from_pretrained and the transformer is sharded across chips as it loads, so the full model never has to fit in one place. Many popular pipelines support it out of the box, and the ones that don't are just a tp_plan away. The Diffusers TPU guide has the full recipe.
Here are some examples run on a Cloud TPU v6e-4:
TP=4 (each model split across four chips) · bf16 · batch 1
| MiniMax-H3 (video + audio) | Qwen-Image-2.1 |
|---|---|
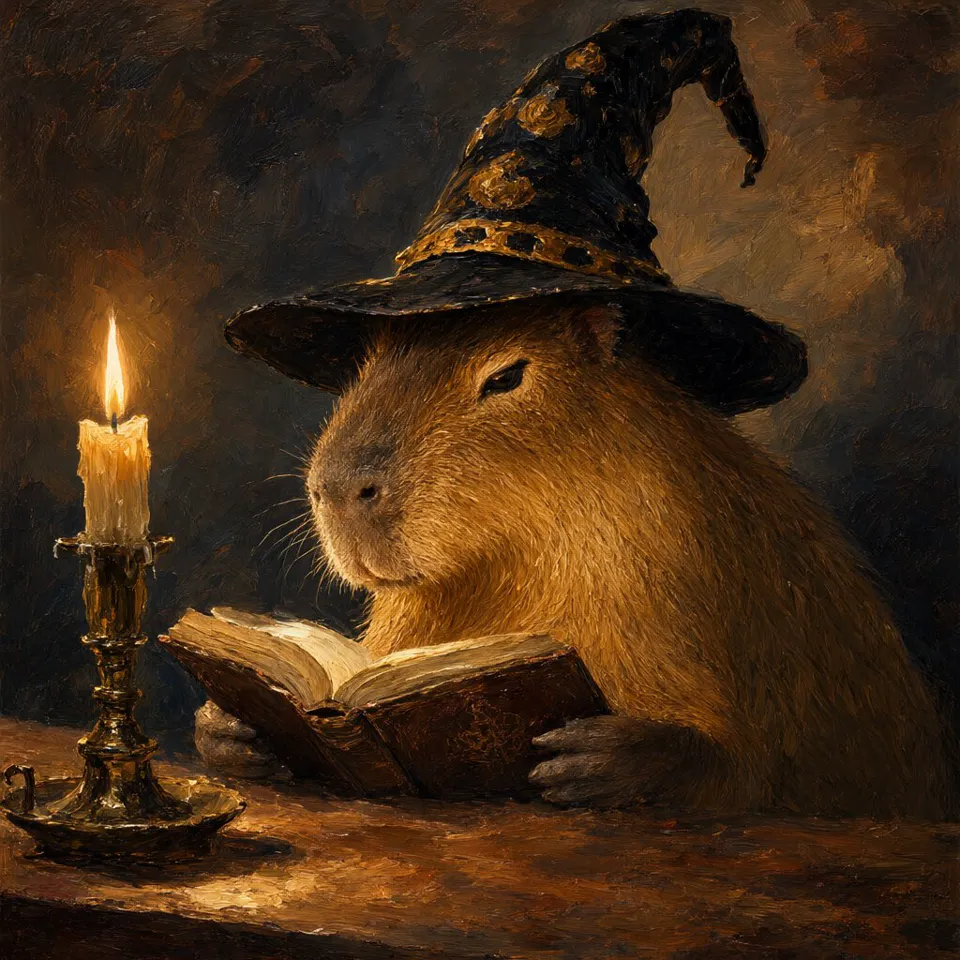 | |
| "The fluffy plush Hugging Face mascot from the picture, a round yellow smiling face with rosy cheeks and two little open hands, stands at the prow of an ancient Greek trireme […] Sound of crashing waves, creaking timber, wind in the rigging, distant seagulls, and a low epic orchestral swell." · 1344×768, 5.2 s, 49 steps · 188 s compiled, 262 s eager | "A capybara wearing a wizard hat, reading a book by candlelight, oil painting" · 1024×1024, 40 steps · 3.5 s compiled, 8.0 s eager |
Kernels
The Kernels Hub has ready-to-use TPU kernels. Load one with the Kernels library and give your model a speed boost.
TPU kernels are written in Pallas, which gives you low-level control over the hardware. You can also bring in kernels from the Tokamax library. Here is a ragged-dot kernel from Tokamax plugged into a Mixture-of-Experts model:
from kernels import get_kernel
from transformers import AutoModelForCausalLM
from transformers.integrations.moe import ALL_EXPERTS_FUNCTIONS

repo_id = "tengomucho/ragged-dot-tpu"
kernel = get_kernel(repo_id, version=1, trust_remote_code=[repo_id])
ALL_EXPERTS_FUNCTIONS.register("tokamax_ragged_dot", kernel.experts_forward)
model = AutoModelForCausalLM.from_pretrained(
    "Qwen/Qwen3-30B-A3B-Instruct-2507",
    experts_implementation="tokamax_ragged_dot",
)
The bigger the batch, the bigger the win. At batch size 64, decoding is 21.5× faster on Qwen3-30B-A3B and 12.8× faster on Gemma 4 26B-A4B.
 Decode throughput on a TPU v6e-8, Hub kernel vs. the default implementation.
We test it so you don't have to 🧪
We're continuously improving TPU support in transformers by running the library test suite. We are working to add a nightly CI on TPU and make the results available in the (transformers dashboard)[https://huggingface.co/spaces/transformers-community/transformers-ci-dashboard].
 The Transformers CI dashboard, with TPU results next to other accelerators. Work in progress!
It's not all green yet, and we're fine with that. Of the tests that run on TPU, 96.5% pass. Every failure we find becomes a small repro script and an issue on the TorchTPU repo. So far we have reported 34 issues, and 19 are already fixed. Running on TPU also caught a few bugs in Transformers itself, like in StaticCache and the Qwen3 tensor-parallel plans. We fixed those upstream.
If something breaks on TPU, we want to find out before you do.
Get started
TPUs are no longer a side quest for PyTorch users. Install TorchTPU, grab a model from the Hub, and send it to "tpu".
We can't wait to see what you build 🤗. If you hit a problem, open an issue and tell us about it.