Rohan Paul (@rohanpaul_ai) · 10/12/2026, 15:14:00
UCSD Paper Embeds Theory of Mind in 7B Agents via Training Rewards for Intent Prediction
A new UC San Diego paper introduces a method to embed Theory of Mind into 7B agents by using an auxiliary model to score replies during RL training. This allows the agent to learn partner beliefs and goals without requiring extra inference models at deployment, improving intent recognition in multi-agent systems.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-12 07
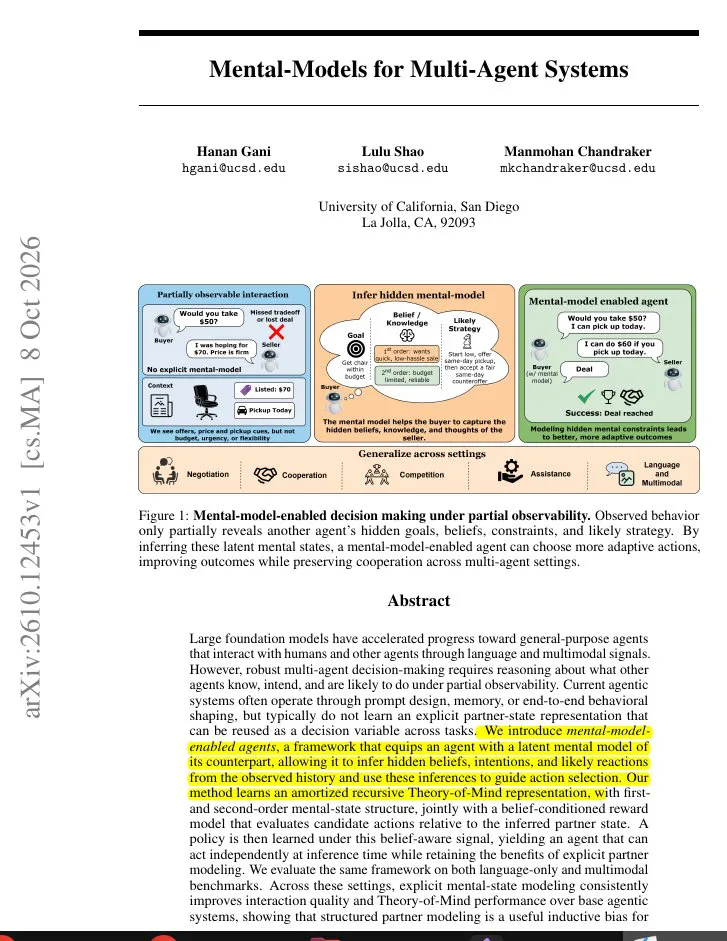
A new UC San Diego paper builds theory of mind into a 7B agent through its training reward, so the agent learns to read a partner’s beliefs and goals and then runs on its own with no extra model at deployment.
LLM agents that negotiate, cooperate or role-play usually guess the other side's goals from prompt text or memory summaries. They keep no explicit estimate of the partner's knowledge or plans, so they can misread intent.
They train a model that infers the partner's beliefs, intents and thoughts, including what the partner thinks of the agent. That model scores candidate replies during RL, and the final agent runs alone without it.
For agents that negotiate or collaborate, train with a reward that judges replies against an inferred model of the partner's goals and beliefs.
– arxiv. org/abs/2610.12453
Title: "Mental-Models for Multi-Agent Systems"