Rohan Paul (@rohanpaul_ai) · 2026/10/12 15:14:00
UCSD 提出训练期心智模型奖励机制:7B 智能体无需额外推理即可精准预测伙伴意图
加州大学圣地亚哥分校最新研究提出一种通过强化学习奖励函数内化“心智理论”的方法,使 7B 参数智能体在训练阶段利用辅助模型推断合作伙伴的信念与目标。该方法仅在训练评分时调用心智模型,部署后智能体可独立运行且无需额外计算开销,显著提升了多智能体协作中的意图识别准确率。
报道全文原始报道全文
Rohan Paul (@rohanpaul_ai) · 2026-10-12 07
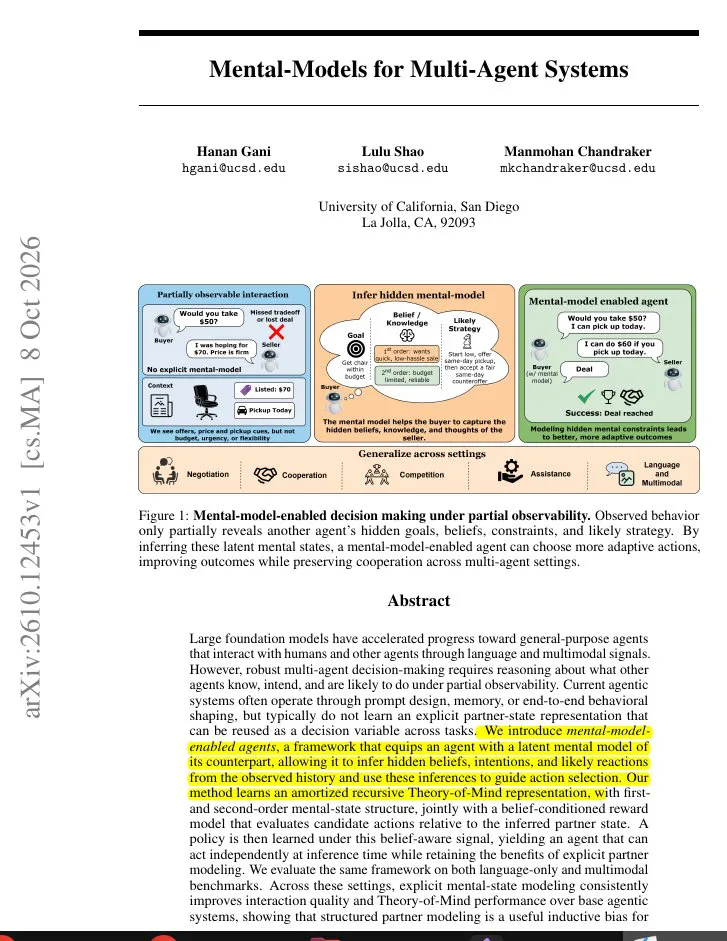
A new UC San Diego paper builds theory of mind into a 7B agent through its training reward, so the agent learns to read a partner’s beliefs and goals and then runs on its own with no extra model at deployment.
LLM agents that negotiate, cooperate or role-play usually guess the other side's goals from prompt text or memory summaries. They keep no explicit estimate of the partner's knowledge or plans, so they can misread intent.
They train a model that infers the partner's beliefs, intents and thoughts, including what the partner thinks of the agent. That model scores candidate replies during RL, and the final agent runs alone without it.
For agents that negotiate or collaborate, train with a reward that judges replies against an inferred model of the partner's goals and beliefs.
– arxiv. org/abs/2610.12453
Title: "Mental-Models for Multi-Agent Systems"