Google Unveils Gemini Decision 1, a Non-Generative Model Built for Fast Decisions
Google launched Gemini Decision 1 and the accompanying Decisions API, which skip token-by-token generation and instead score a predefined set of candidate answers in a single forward pass, returning the decision, probability and confidence. The model handles yes/no judgments, multiple choice with up to 255 options and rubric-based scoring, processes up to 1,000 questions per request with 150-250 ms end-to-end latency, and is priced at $0.10 per million input tokens with free output. Google claims first place on 7 of 9 benchmarks with up to 92.2% accuracy, and says internal teams already use it in Search and product features.
Related Entities
Full Report
Contents3 sections
While the entire AI industry is still competing over who can generate more tokens and whose reasoning capabilities are stronger, Google has launched a new model that doesn't rely on generating answers word by word.
Just now, Google officially released Gemini Decision 1, along with the Gemini Decisions API powered by this model. Unlike traditional generative large models, this model is specifically designed for fast decision-making. It does not need to generate text token by token; instead, it scores pre-defined candidate answers through a single forward pass.
Google CEO Sundar Pichai also posted on X to introduce the main capabilities of Gemini Decision 1. He wrote:
Today, we're officially launching the Gemini Decisions API in Google AI Studio, powered by the new Gemini Decision 1 model. Unlike traditional models that generate text token by token, this model is purpose-built for decision tasks with a closed set of options. In a single pass, it can score up to 1,000 questions across text, images, audio, video, and PDFs. Here are a few notable details: · Supports three decision types: yes/no judgments, multiple choice (up to 255 options), and rubric-based scoring; · Pricing is just $0.10 per million input tokens, with zero output token cost — about one-fifth the cost of Flash-Lite; · Leading position across multiple benchmarks, with the lowest calibration error. Google's internal teams have already begun using this technology.
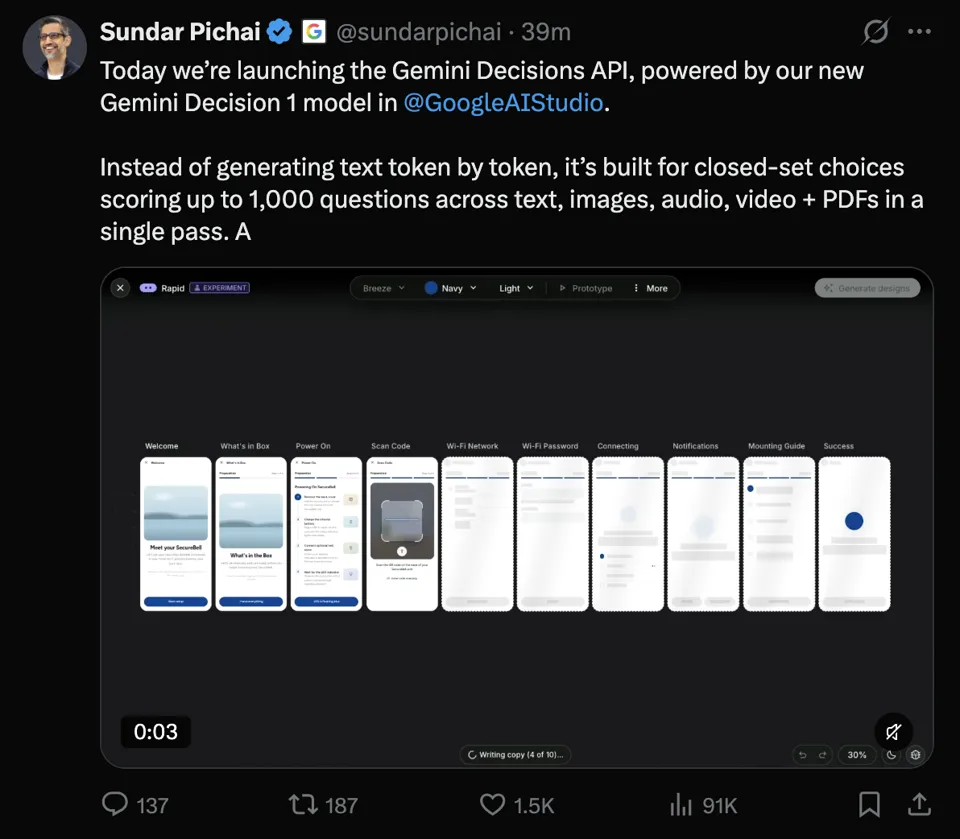
He also showcased a demo of Stitch Rapid designing a complete product flow in seconds, with the video played at normal 1x speed.
This introduction reveals the biggest difference between Gemini Decision 1 and traditional large models: it is not responsible for articulating the answer, but for making judgments from existing options.
In the past, when developers wanted AI to determine whether an email was spam, or to decide which Agent a task should be assigned to, they typically had to call a generative large model and then extract the result from the generated text. Gemini Decision 1 eliminates the token-by-token decoding step.
Developers only need to provide the input content, the question to be judged, and the candidate options, and the model can directly return the corresponding judgment result, probabilities, and confidence.
This means that for tasks that only require a classification, score, or selection result, AI no longer needs to complete an entire text generation pipeline.
According to Google's published data, Gemini Decision 1 can handle up to 1,000 independent questions in a single request, supports multimodal inputs including text, images, audio, video, and PDFs, and has an end-to-end latency of only 150–250 milliseconds.
Pricing is also quite aggressive: just $0.10 per million input tokens, with no charge for output tokens. In the same set of benchmarks published by Google, its invocation cost is nearly 5 times lower than Gemini 3.5 Flash-Lite.
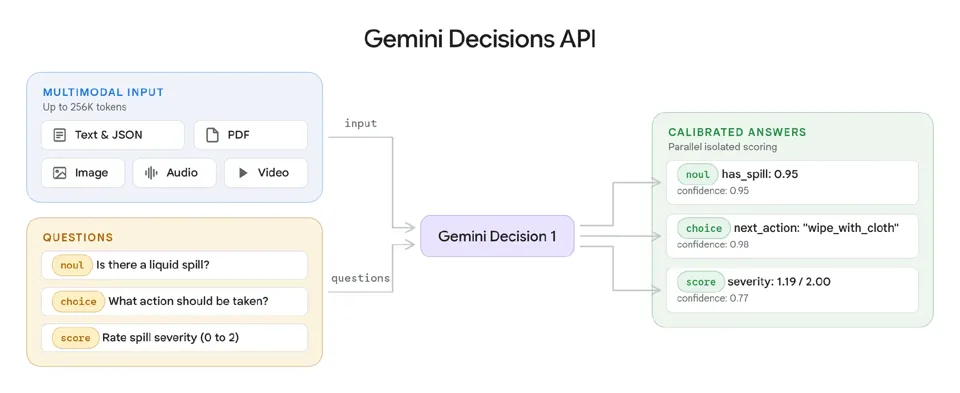
More notably, this is not just a model for answering multiple-choice questions. Google has already applied it to scenarios such as AI model routing, Agent tool selection, product design, and safety detection, attempting to make it a foundational component specifically responsible for judgment and decision-making in AI systems.
Handling 1,000 questions at once, up to 255 options
According to the technical introduction published by Google, Gemini Decision 1 offers three core decision-making capabilities.
The first is Yes/No (binary judgment). For example, determining whether there is a safety hazard in an image, or whether a piece of text violates established rules. The model returns the probability that the corresponding condition holds.
The second is Multiple Choice. Developers can preset 2–255 candidate options, and the model not only selects the most fitting answer but also returns normalized probabilities for each candidate.
The third is Ordered Rubric. Developers can define their own grading criteria at different levels, letting the model evaluate the input content and return a continuous weighted score along with the probability of each level.
The three task types can also be mixed and executed within a single request.
Google provided a simple example: upload a photo of an office break room counter to the model, along with a text description, and ask it to simultaneously determine whether there is any liquid spill on the counter, what cleanup measures should be taken, and the severity of the situation.
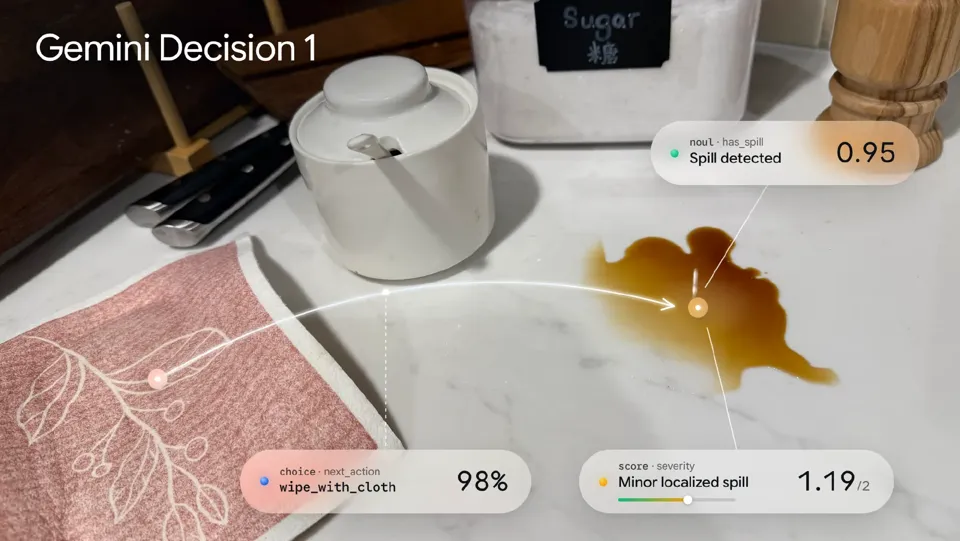
The traditional approach might require designing multiple classifiers, or using a generative large model to execute different prompt tasks. Gemini Decision 1 can complete these judgments in a single request.
In addition, the model supports a multimodal input context of up to 256K tokens. For enterprise scenarios, this means developers can analyze call recordings together with customer materials, or make judgments by combining insurance claim documents with on-site photos.
Each decision provides a confidence score from 0 to 1, making it easy for systems to hand uncertain results over to other models or human reviewers.
Another competitive advantage of Gemini Decision 1 is speed and cost.
According to Google's official introduction, in benchmarks covering Agent routing, reasoning, ranking, and multimodal understanding, Gemini Decision 1 leads in performance and achieves the lowest calibration error.
In test contexts of no more than 16K tokens, the median latency during the model computation phase stays at 50–100 milliseconds, with end-to-end latency of about 150–250 milliseconds. Even when the number of questions in a single request increases from 1 to 100, latency remains essentially stable.
On the common benchmark set used officially, the cost of the Gemini Decisions API is nearly 5 times lower than calling Gemini 3.5 Flash-Lite through the Interactions API.
First place in 7 out of 9 tests, with accuracy up to 92.2%
With the release of Gemini Decision 1, Google also published a rather noteworthy model comparison scorecard.
Unlike typical comparisons that pit general-purpose large models against each other, Google chose three competing products this time: OpenAI's GPT-6 Luna, TypeSafe Jev 1.14, which is purpose-built for classification decisions, and its own Gemini 3.5 Flash-Lite.
The results show that Gemini Decision 1 took first place in 7 of 9 benchmarks and also leads in probability calibration, but competitors still perform better on the other two tests and on total invocation cost.
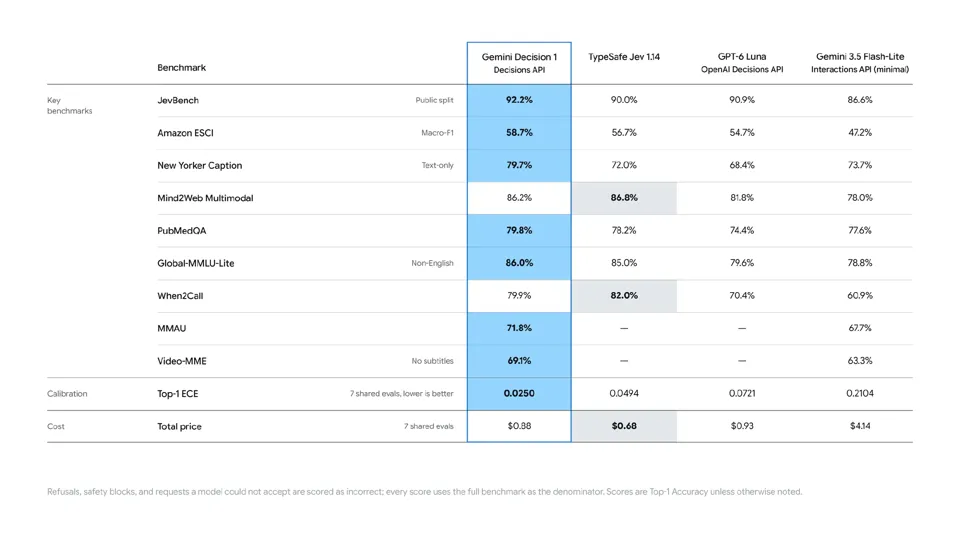
On the JevBench test, Gemini Decision 1 achieved 92.2% accuracy, surpassing GPT-6 Luna's 90.9%, TypeSafe Jev 1.14's 90.0%, and Gemini 3.5 Flash-Lite's 86.6%.
On the Amazon ESCI product search relevance test, Gemini Decision 1 achieved a 58.7% Macro-F1 score, 4 percentage points higher than GPT-6 Luna and 11.5 percentage points higher than Flash-Lite.
On the New Yorker Caption test, the gap widened further. Gemini Decision 1 scored 79.7%, while GPT-6 Luna scored 68.4%, an 11.3 percentage point difference. This test involves understanding and selecting captions for cartoons, examining the model's contextual understanding and ability to judge candidate content.
On the medical question-answering test PubMedQA, Gemini Decision 1 also ranked first with a score of 79.8%, higher than GPT-6 Luna's 74.4%.
The multilingual test Global-MMLU-Lite produced similar results. Gemini Decision 1 achieved 86.0%, while GPT-6 Luna scored 79.6%, a 6.4 percentage point difference.
However, Google did not achieve a clean sweep.
On the Mind2Web Multimodal test, TypeSafe Jev 1.14 ranked first with 86.8%, while Gemini Decision 1 scored 86.2%, trailing by 0.6 percentage points.
On the When2Call test, which examines the ability to judge tool invocation, TypeSafe Jev 1.14's advantage was even more pronounced, scoring 82.0% versus Gemini Decision 1's 79.9%.
This result is particularly noteworthy. Tool selection and timing judgment are among the Agent application scenarios that Gemini Decision 1 specifically targets, yet the specialized decision model TypeSafe Jev still maintains a lead on this test.
In addition, on the audio understanding test MMAU and the video understanding test Video-MME, Gemini Decision 1 achieved 71.8% and 69.1% respectively, both higher than Flash-Lite.
More noteworthy than accuracy is the probability calibration capability that Google specifically emphasized this time.
On the Top-1 ECE (Expected Calibration Error) test, Gemini Decision 1's calibration error was only 0.0250, compared with GPT-6 Luna's 0.0721, TypeSafe Jev 1.14's 0.0494, and Flash-Lite's 0.2104.
In other words, in this evaluation set, Gemini Decision 1's calibration error is about 65% lower than GPT-6 Luna's and about 88% lower than Flash-Lite's.
This metric is especially important for Agent systems.
For example, when an Agent needs to determine whether a piece of code has a security vulnerability, the model provides not only a "vulnerable" or "not vulnerable" result but may also include a probability value. The system can use the relationship between the probability and the actual accuracy rate to decide whether to take action automatically or hand it over to a human for further review.
Google Is Already Using It: Agent Routing Latency Reduced by Up to 40%
Unlike some new models that only showcase benchmark scores, Google also disclosed application cases of the Gemini Decisions API in its internal products.
The most notable one is Gemini Notebook.
Google is using the Decisions API as a real-time model router to select the appropriate model tier and thinking intensity based on the complexity of user requests. For simple everyday questions, the system can prioritize lower-cost, faster-responding models; for complex reasoning tasks, it routes requests to more capable models.
Google says that with this dynamic routing approach, latency for everyday queries can be reduced by up to 40%.
This design is closely related to the current development trend of Agent systems. When an Agent completes a task, it often needs to continuously judge the next action, such as which tool to select, which model to invoke, or whether human intervention is needed.
If every simple decision has to be handled by a large generative model, the system incurs additional latency and cost. A specialized decision model offers another option: route relatively simple judgments with clear options to a low-latency model, while leaving complex tasks to general-purpose large models.
In addition to Gemini Notebook, Google also disclosed three other application directions.
In Google Stitch, the newly launched Rapid Canvas experimental feature uses the Decisions API to generate interactive product flow wireframes within seconds and quickly respond to user modification instructions issued via voice or clicks. Once the user confirms the design direction, the page can be transferred to the full Stitch workflow for further refinement.
In Google Labs' CC product, the Decisions API is used to quickly select the appropriate emoji reaction from over 200 emoji options. Within Google Search, Google also uses this API to build a security detection layer for MCP tools, identifying potential adversarial behavior and content.
Reference links:
https://blog.google/innovation-and-ai/technology/developers-tools/gemini-decisions-api/