Tencent Hunyuan Releases Hy4 Flash with 224B Parameters and 5% Task Cost
Tencent Hunyuan officially launched Hy4 Flash, a 224B-parameter model activating 12B per token with multimodal input and 1M-token context. Through coordinated pretraining, post-training and inference optimizations including hybrid attention, LatentMoE, Engram lookup parameters and 4-bit quantization, its per-task cost is just 1/20 of Hy4 and 1/8 of DeepSeek-V4.1-Flash, with official claims of slightly better overall quality than Hy4 preview and plans to open-source.
Full Report
IT之家 November 16 news: The Tencent Hunyuan team today announced the official launch of Hy4 flash, which it positions as the most cost-effective Hy model to date.
The model has a total parameter count of 224B, including 64B Engram parameters, with 12B parameters activated per token. It supports multimodal input and a context length of 1 million tokens, and its API price is significantly lower than that of Hy4.
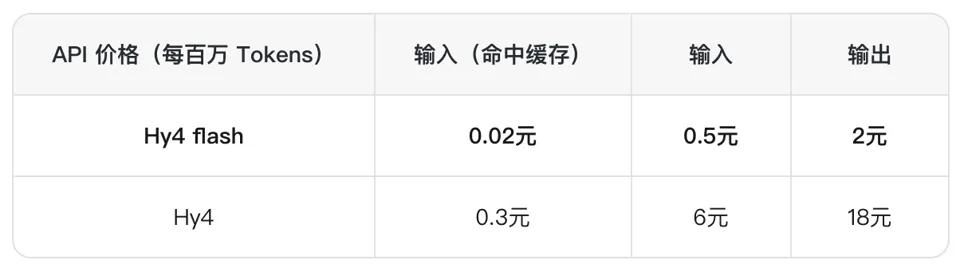
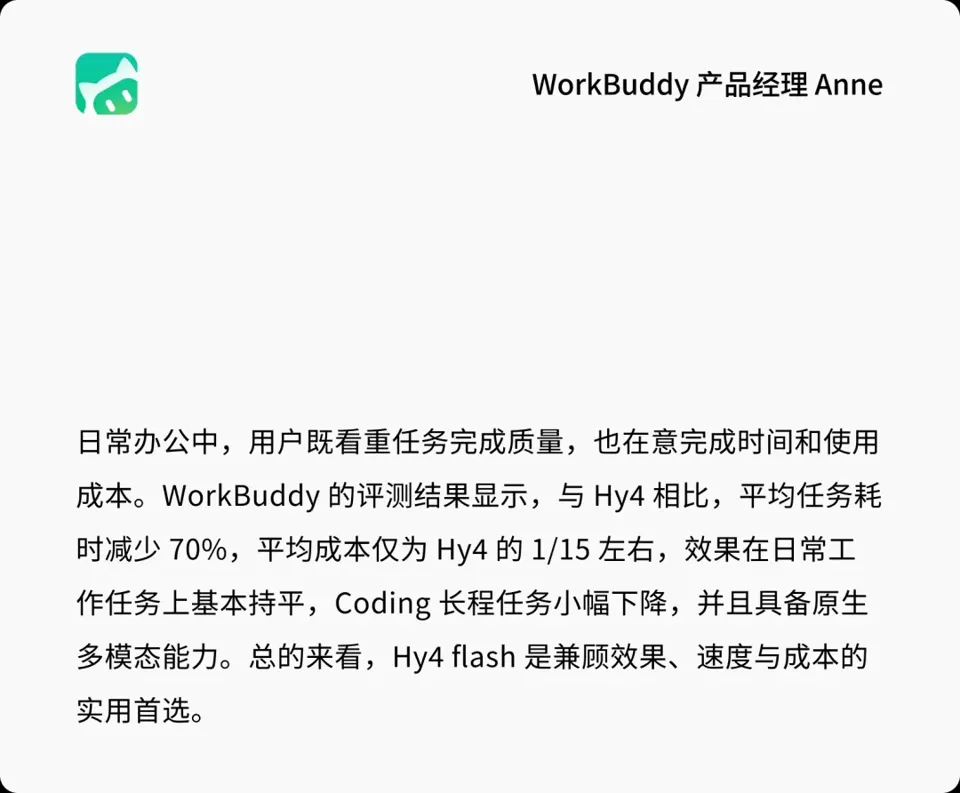
Tencent says Hy4 flash's high cost-effectiveness comes from coordinated optimization across three stages: pre-training, post-training, and inference. In the pre-training stage, architectures such as hybrid attention, LatentMoE, and Engram (IT之家 note: Engram is a scalable lookup-table-style parameter module used to expand model capacity at a lower compute cost) are introduced, reducing the KV cache size to 1/24 of Hy3 and 1/6 of Hy4. In the post-training stage, comprehensive intelligence is obtained through self-distillation from Hy4, and reinforcement learning then compresses the end-to-end task output length by 50%. In the inference stage, techniques including megakernel, 4-bit quantization, and dflash are combined to achieve a decoding speed of over 150 tps, supporting large-scale low-cost deployment and operation.
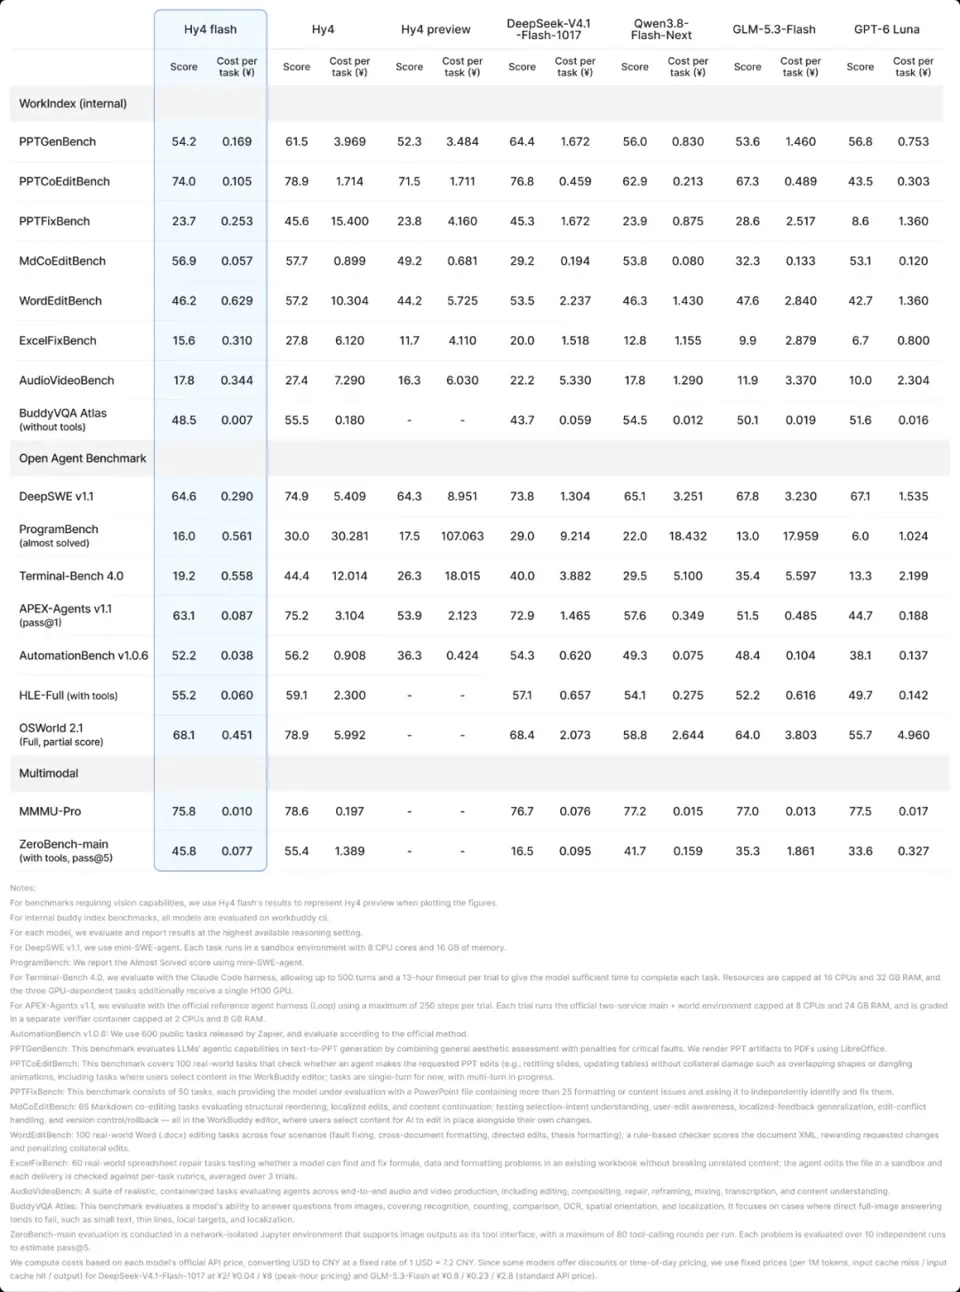
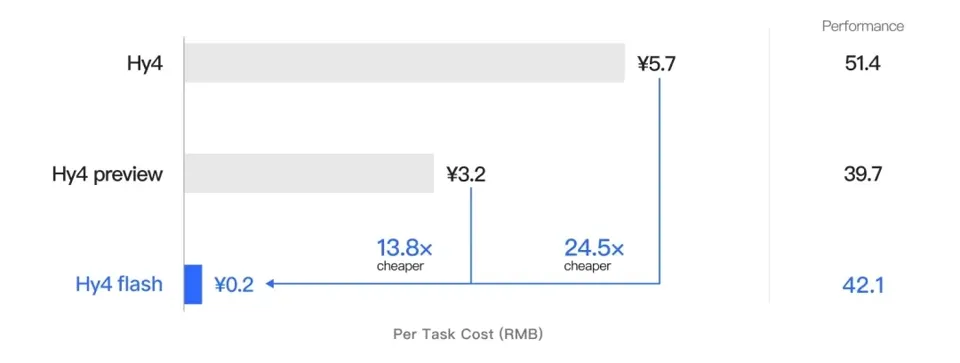
On WorkIndex, the official evaluation set of typical WorkBuddy tasks, the per-task cost of Hy4 flash is only 1/13 of Hy4 preview, 1/20 of Hy4, and 1/8 of DeepSeek-V4.1-Flash-1017 (max tier, peak-hour pricing).
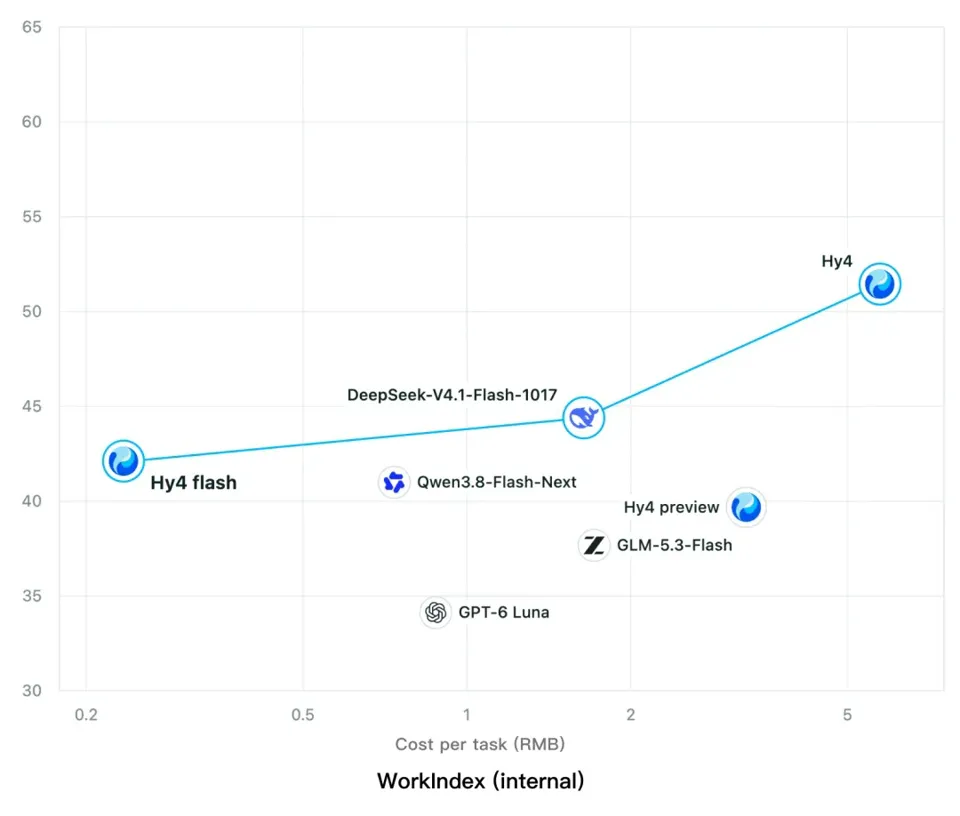
In terms of overall performance, Hy4 flash is slightly better than Hy4 preview. This comparison framework focuses on the output quality of daily work, single-turn output length, and end-to-end time, rather than public leaderboard scores.
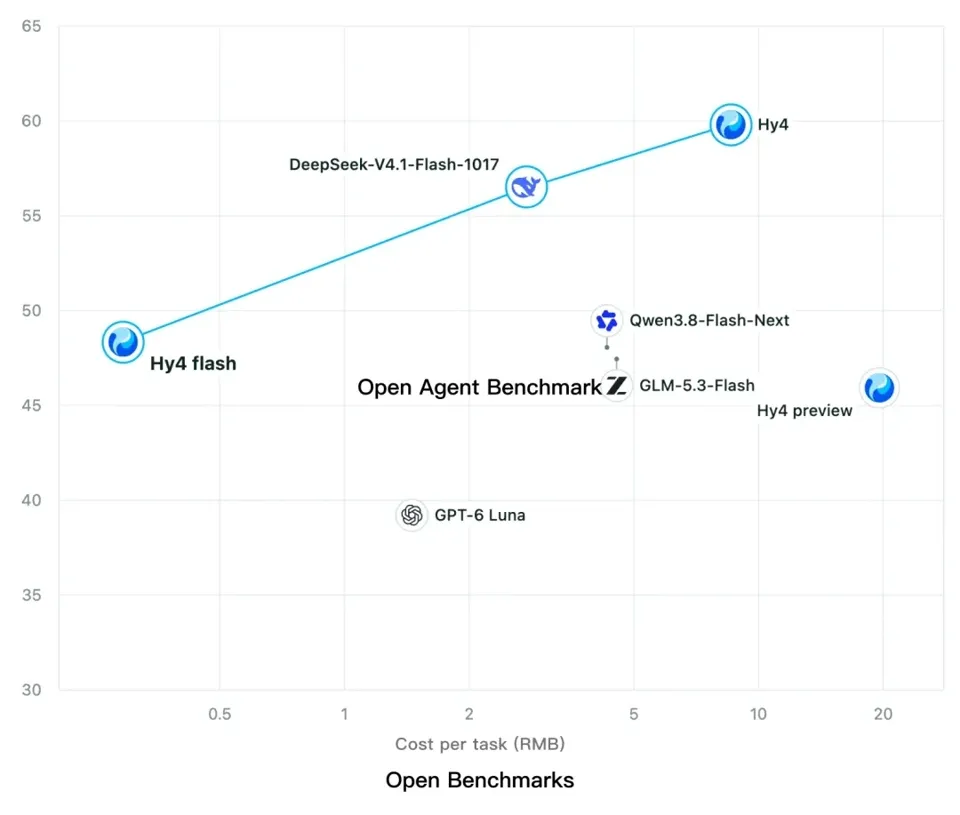
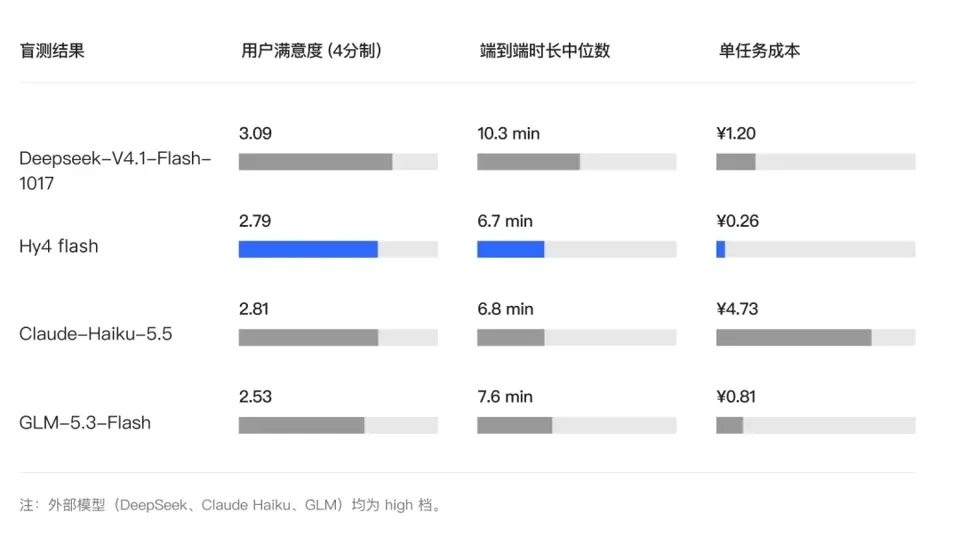
To measure the real-world experience, Tencent invited 85 internal WorkBuddy users to conduct blind tests on 259 daily work tasks across 27 categories.
The results show that Hy4 flash's user satisfaction is close to that of Claude Haiku 5.5, its per-task cost is significantly lower than that of all models in the comparison, and its task duration is also the shortest.
Hy4 flash has already launched on products including Tencent Cloud TokenHub, WorkBuddy, Yuanbao, WeCom, QQ, ima, and Marvis, and will soon be integrated into OpenRouter.
Before November 30, 2026, users can use it free for a limited time on WorkBuddy, and the Tencent Cloud TokenHub API is available at a limited-time 50% discount.
Tencent recommends using Hy4 flash for daily tasks such as deep search, document processing, PPT generation, simple front-end display, and Computer Use, while complex tasks such as long-horizon software engineering should be left to Hy4, which has a higher intelligence ceiling. The company also said it plans to open-source Hy4 flash and maintain high-frequency iteration.