Artificial Analysis (@ArtificialAnlys) · 10/21/2026, 13:10:12
Devin Fusion Dual-Model Setup Outperforms Claude Code in Benchmarks
Cognition's Devin Fusion, utilizing a parallel 'frontier lead + low-cost sidekick' architecture (Claude Opus 5.5 + GPT-6 Luna), scored 68.1 on the Artificial Analysis Coding Agent Index. This setup outperformed single-model Claude Code with Opus 5.5 by reducing costs by ~31% and task duration, though it slightly trailed in Terminal-Bench metrics.
SOURCE COVERAGEFull Original Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-21 05
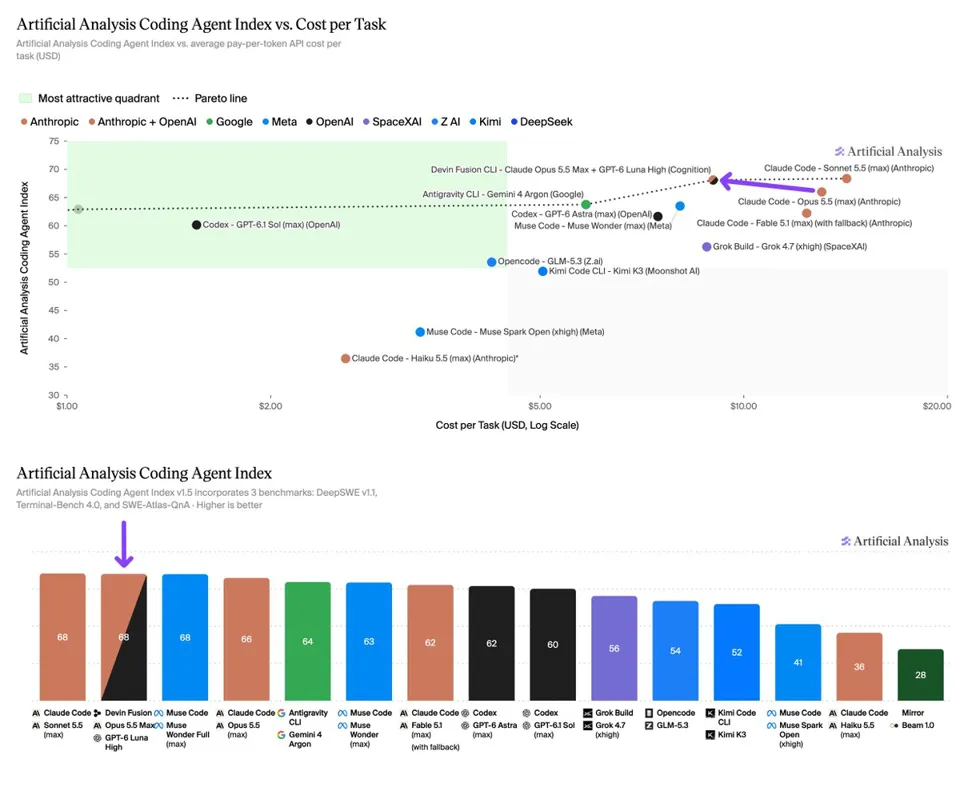
Devin Fusion with Claude Opus 5.5 (max) and a GPT-6 Luna (high) sidekick scores 68 on the Coding Agent Index, 2 points above Claude Code with Opus 5.5 (max) at 31% lower cost per task
@cognition's Devin Fusion runs a frontier lead model alongside a lower-cost sidekick model. The two work in parallel with their own context and tools, with the lead keeping planning, delegation and final review. We benchmarked Devin Fusion CLI with Claude Opus 5.5 (max) + GPT-6 Luna (high).
It scores 68.1 on the Artificial Analysis Coding Agent Index, closely matched at the top with Claude Code with Claude Sonnet 5.5 (max) at 68.4 and Muse Code with Muse Wonder Full (max) at 68.0. Against Claude Code with Claude Opus 5.5 (max) at 66.0, it costs 13.04 per task and averages 55 vs. 65 minutes per task.
Across the three benchmarks, the Fusion configuration scores higher on DeepSWE v1.1 (72.6% vs. 68.4%) and SWE-Atlas-QnA (69.6% vs. 66.4%) and slightly lower on Terminal-Bench 4.0 (62.1% vs. 63.1%). Its results reflect both models working together, including their combined API cost. Costs are pay-per-token API costs, not subscription prices.