Anthropic Unveils Claude Fable 5.2 Topping Coding Benchmarks Over GPT-6 Astra
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2, claiming notable gains across coding, reasoning, scientific research, cybersecurity and robotics, with up to 30% faster output and 20% lower cost. Fable 5.2 scored 49.1% on the agentic coding benchmark FrontierCode 2.0, beating GPT-6 Astra at 42.8% and Gemini 4 Carbon at 41.1%, and also led on multidisciplinary reasoning tests. Anthropic demonstrated it coordinating over 1,000 agents over eight days to build a bootable operating system from scratch.
Related Entities
Full Report
IT Home News, November 10: Anthropic today (November 10) released two frontier AI models, Claude Fable 5.2 and Claude Mythos 5.2. The company says the new models deliver significant improvements in coding, reasoning, scientific research, cybersecurity, and robotics, while increasing output speed by up to 30% and reducing costs by 20%.
According to officially disclosed benchmark data, on the FrontierCode 2.0 benchmark for "agentic coding," Claude Fable 5.2 scored 49.1%, surpassing OpenAI's GPT-6 Astra (42.8%), Google's Gemini 4 Carbon (41.1%), and Anthropic's own Opus 5.5 (45.5%).
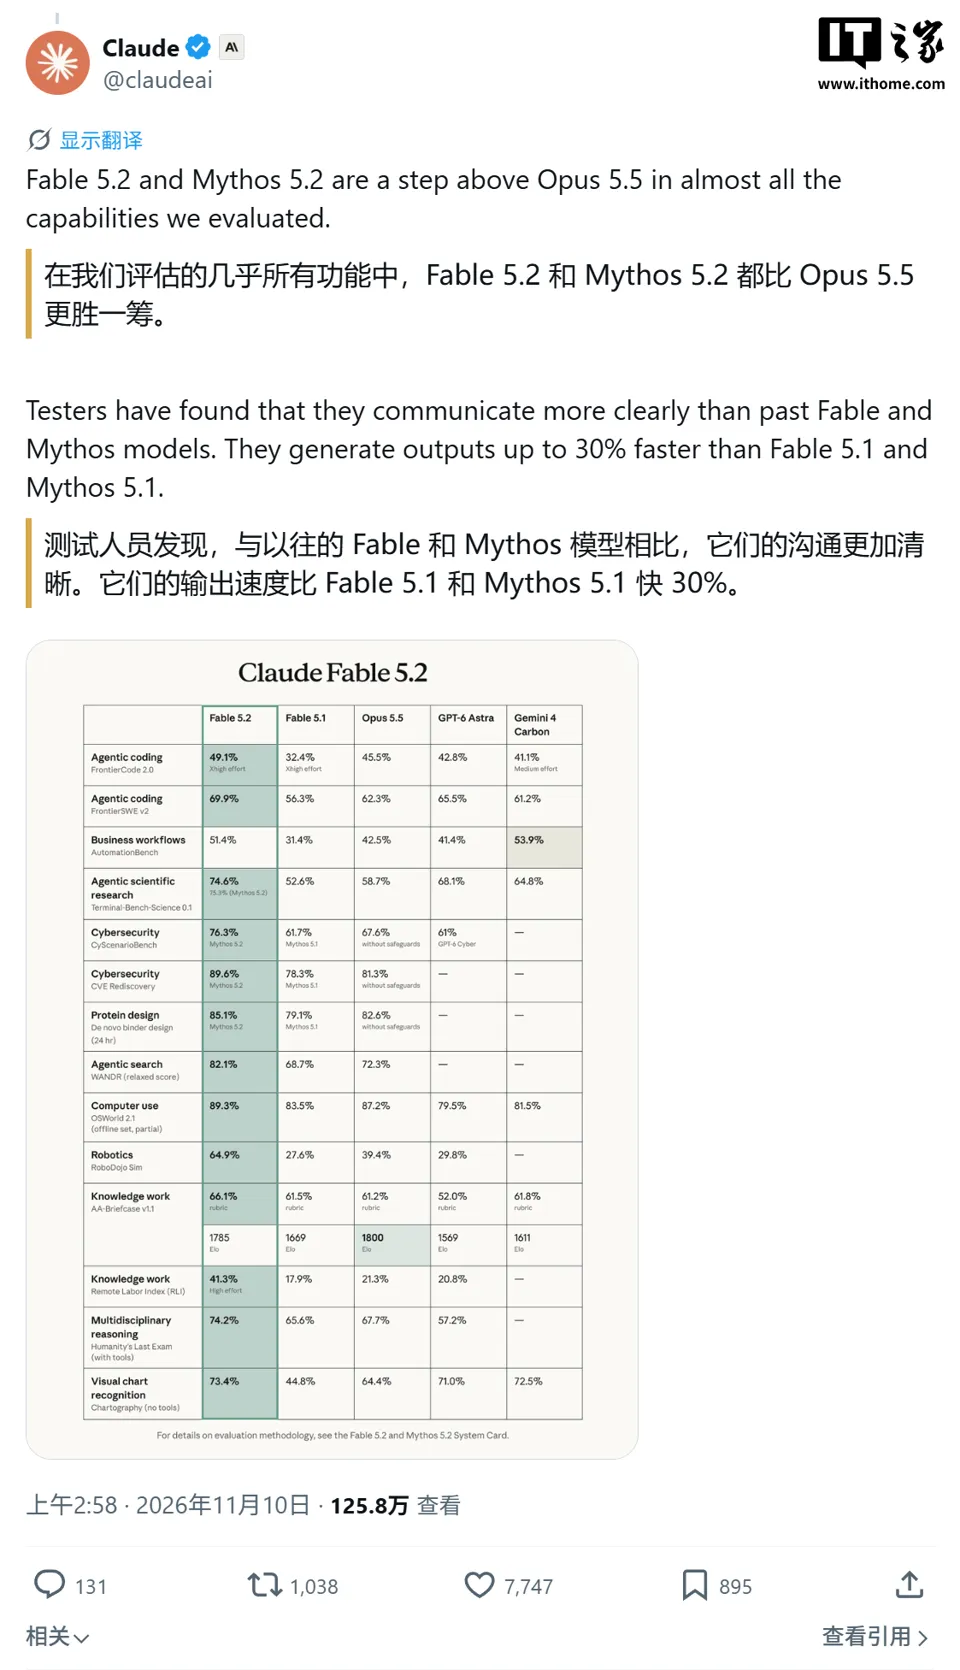
On the "Humanity's Last Exam" multidisciplinary reasoning test, Fable 5.2 also led with 74.2% versus GPT-6 Astra's 57.2%.
Anthropic demonstrated Fable 5.2's long-horizon collaboration capability: the model coordinated more than 1,000 AI agents over 8 days to build a bootable operating system from scratch, including device drivers, file storage, a window system, and an installer.
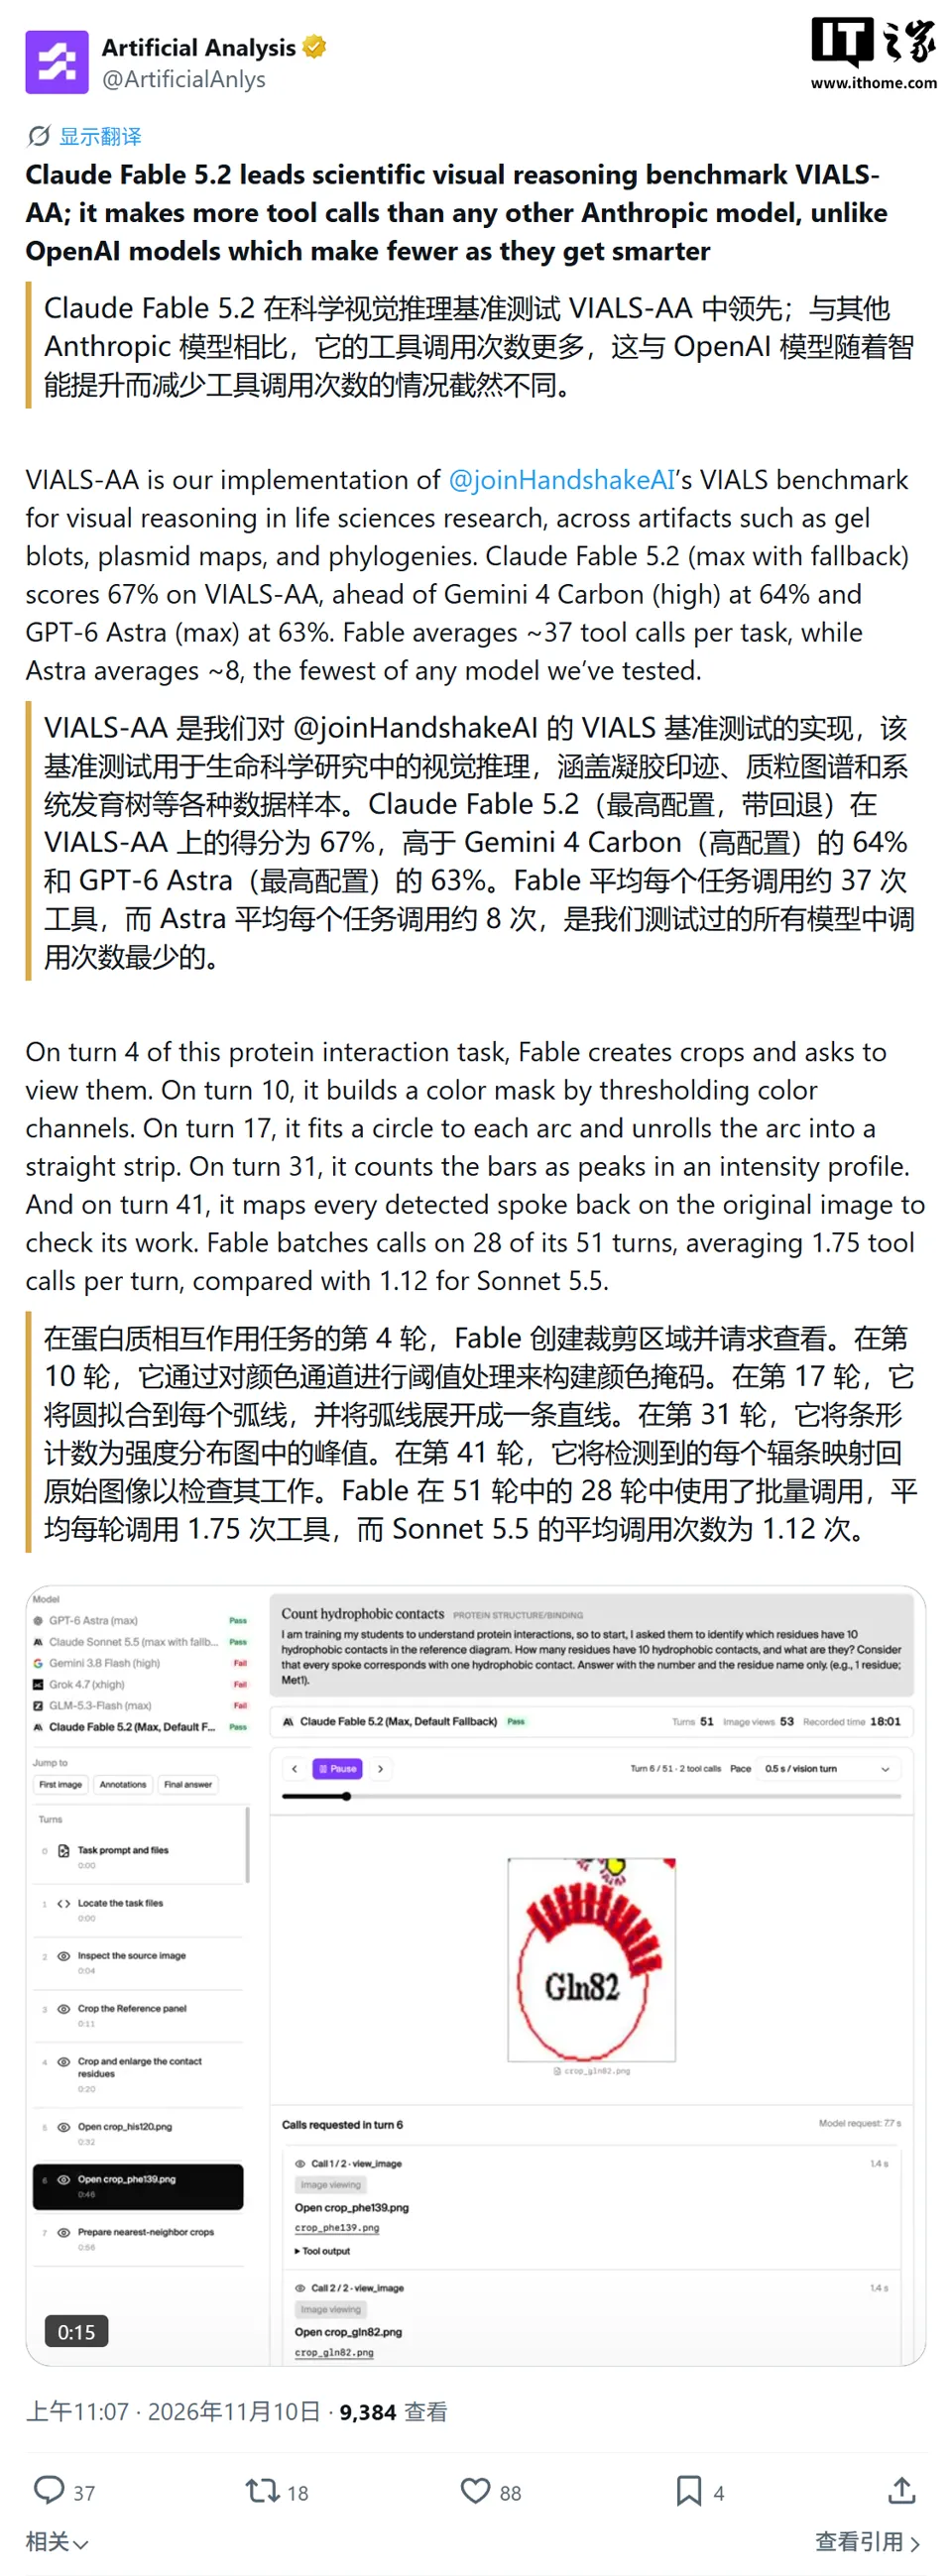
On the scientific visual reasoning benchmark VIALS-AA, Claude Fable 5.2 made more tool calls, which stands in stark contrast to OpenAI models, which make fewer tool calls as their intelligence increases. IT Home includes the relevant video below:
Claude Fable 5.2 (highest configuration, with fallback) scored 67% on VIALS-AA, above Gemini 4 Carbon (high) at 64% and GPT-6 Astra (max) at 63%.
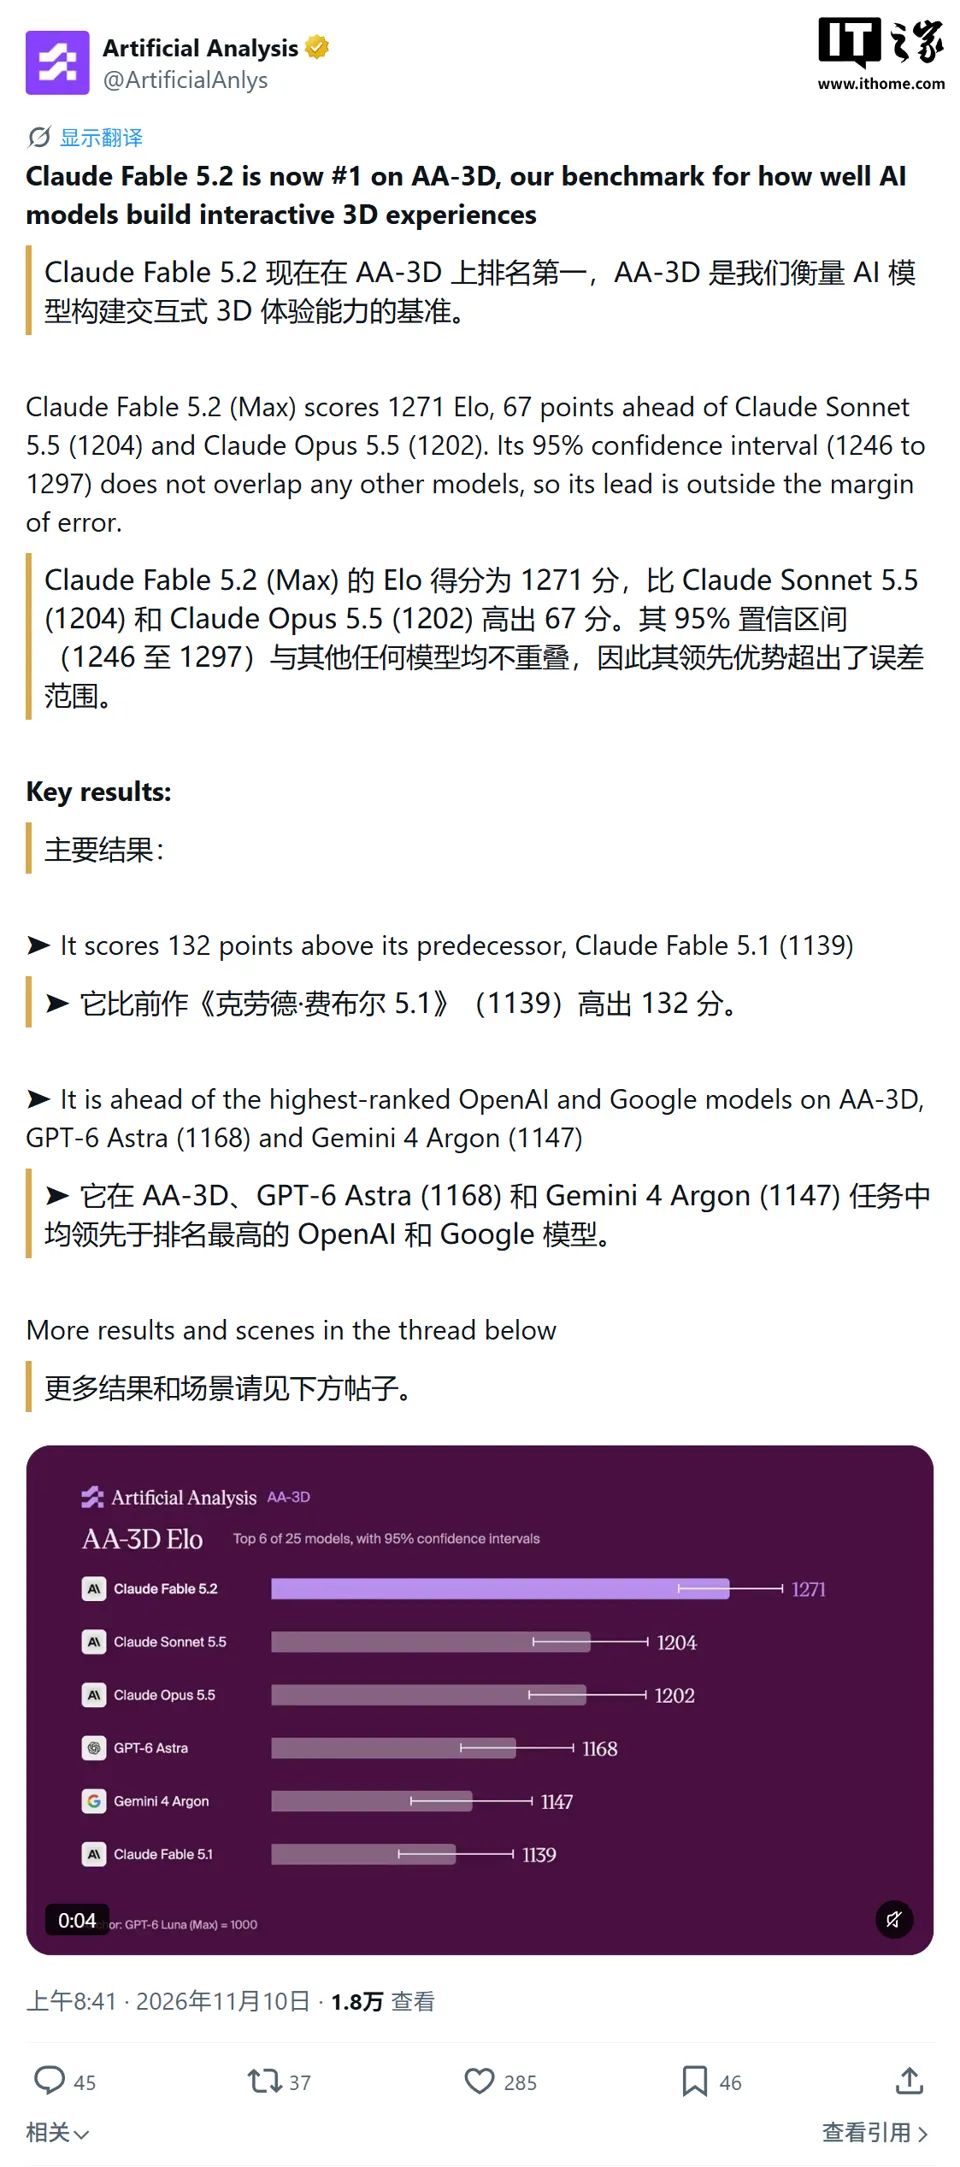
On the AA-3D benchmark (which measures an AI model's ability to build interactive 3D experiences), Claude Fable 5.2 (Max) achieved an Elo score of 1,271, 67 points higher than Claude Sonnet 5.5 (1,204) and Claude Opus 5.5 (1,202). Its 95% confidence interval (1,246 to 1,297) does not overlap with that of any other model, so its lead exceeds the margin of error.