NVIDIA Nemotron 3.5 Super VL Now Available on Amazon EKS and SageMaker HyperPod
NVIDIA has released the 120B-parameter MoE model Nemotron 3.5 Super VL, now deployable on Amazon EKS and SageMaker HyperPod. Activating only 12B parameters per token, it unifies text, image, and video understanding to accelerate agentic AI development.
Full Report
Contents9 sections
NVIDIA Nemotron 3.5 Super VL joins the NVIDIA Nemotron 3 Nano, Nano Omni, Super, Ultra, and Nemotron 3.5 Lightning models already available on AWS. It’s a 120B-parameter mixture-of-experts (MoE) model that activates 12B parameters per token. It combines reasoning and tool use with text, image, document, and video understanding, so one model serves both text and visual tasks. This post explores its architecture and use cases, then shows how to deploy it on Amazon Elastic Kubernetes Service (Amazon EKS), Amazon EKS Auto Mode, and Amazon SageMaker HyperPod EKS.
About Nemotron 3.5 Super VL
NVIDIA Nemotron 3.5 Super VL is an open multimodal model distilled from Nemotron 3 Ultra. NVIDIA publishes the weights, training datasets, and post-training recipes, so you can customize the model for domain-specific workloads and run it on infrastructure you control. Model details:
- 120B total parameters, 12B active per token.
- Hybrid Mamba-2, MoE, and attention layers with a RADIO vision encoder.
- Context length up to 1M tokens.
- Input: text, image, document, and video.
- Output: text.
- BF16 and NVFP4 checkpoints.
NVIDIA reports 63.44 percent on Hermes Bench and 87.05 percent on LangChain agent evaluations, and 80.8 percent on the CharXiv chart-reasoning benchmark. (technical report)
Model architecture
Nemotron 3.5 Super VL uses a hybrid Mamba-Transformer MoE architecture, interleaving Mamba-2, attention, and expert layers. Sparse routing activates 12B of the 120B parameters per token, so compute per token matches a much smaller model while GPU memory still holds the full weights. Mamba-2 layers carry a constant-size state during generation, so their memory does not grow with sequence length the way KV cache does, which keeps long contexts affordable. A recursively shared Multi-Token Prediction (MTP) head supports native speculative decoding.
Use cases
Nemotron 3.5 Super VL supports agent workflows that combine reasoning with visual understanding:
- Coding: test and validate code, analyze errors, recommend fixes.
- Web research: cross-reference and verify sources returned by search tools.
- Document intelligence: read tables, charts, and page layouts to produce summaries.
- Cyber security: identify vulnerabilities and triage threats.
- Video understanding: search, content, review, and incident analysis.
Nemotron 3.5 Super VL integrates with major open agent frameworks and orchestration systems through NVIDIA reference implementations, cookbooks, and the NVIDIA Agent Toolkit. For the full list of supported frameworks, see the NVIDIA developer blog.
Minimum GPU configurations
| vLLM (GPU Model / min count) | BF16 | NVFP4 |
|---|---|---|
| B200/GB200 | 8 | 2 |
| B300/GB300 | 4 | 1 |
| H200 | 8 | 4 |
| H100 | 16 | 8 |
Deployment on AWS
Deployment architecture
The reference implementation runs on standard Amazon EKS, EKS Auto Mode, and SageMaker HyperPod EKS. With EKS Auto Mode, AWS manages scaling, GPU, and EFA support in the cluster on your behalf. The Kubernetes manifests for model deployment are the same for each of the orchestrator options. Each cluster has a control plane hosting the Kubernetes API and a data plane of CPU and GPU nodes. CPU nodes run system and test pods, while the GPU nodes run the model. Amazon Elastic Container Registry (Amazon ECR) stores the container images, a shared Amazon FSx for Lustre volume holds the model weights, and Elastic Fabric Adapter (EFA) connects the GPU nodes. The following figure shows a standard Amazon EKS cluster.
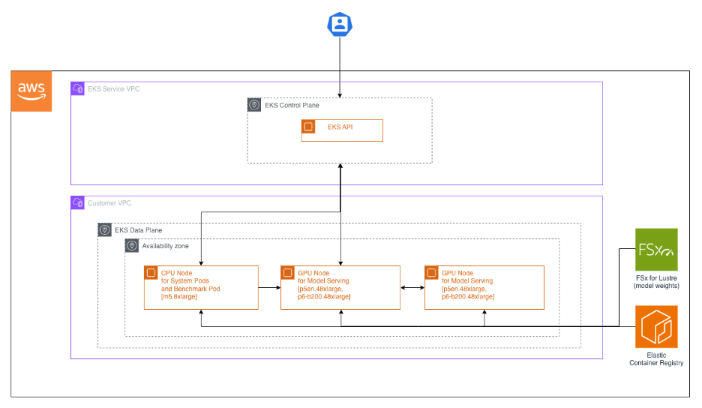
Figure 1: Standard Amazon EKS cluster architecture for serving NVIDIA Nemotron models
NVIDIA Dynamo serves the model aggregated on a single node or disaggregated with prefill and decode on different nodes. For vision-language models, the image/video encoding stage can in addition run disaggregated on its own node.
Validation and performance
This architecture has been validated on both p6-b200.48xlarge (8 x NVIDIA B200 GPUs) and p5en.48xlarge (8 x NVIDIA H200 GPUs) instances. You can validate the cluster and its network with an NVIDIA Collective Communications Library (NCCL) all-reduce micro-benchmark.
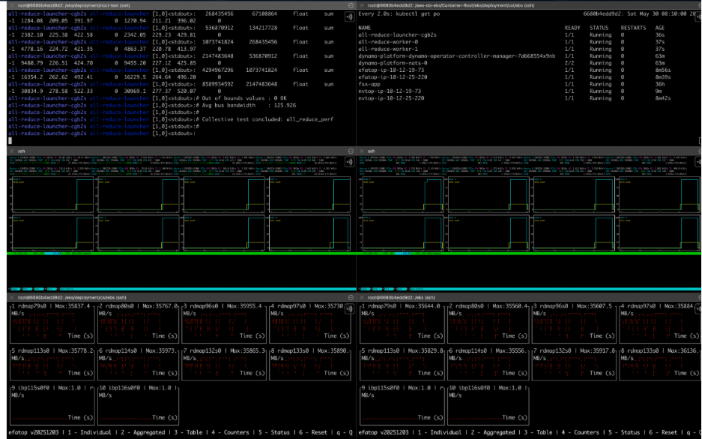
Figure 2: GPU and EFA utilization during an NCCL all-reduce validation test
Seeing utilization on all GPUs and traffic on all EFA adapters while the NCCL test is running, verifies that the cluster is working as expected.
You can measure the performance of a deployed model on the cluster with the NVIDIA aiperf tool.
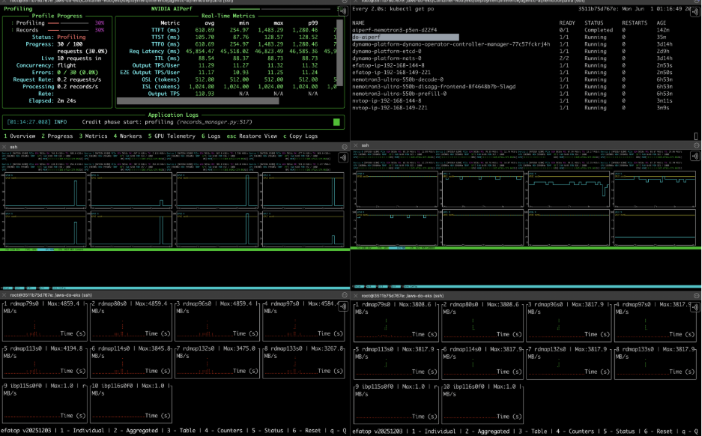
Figure 3: aiperf performance metrics for the deployed model
The aiperf output in the upper left pane shows key performance indicators (KPIs) like time to first token (TTFT), inter-token latency (ITL), and throughput in tokens per second (TPS). By taking these measurements at various levels of concurrency, we can study how latency and throughput depend on the number of concurrent requests. This information is essential to thoughtfully plan capacity and model deployment topology. The aws-do-eks container provides automation for visualizing GPU and EFA utilization as well as running aiperf and concurrency sweeps with single commands.
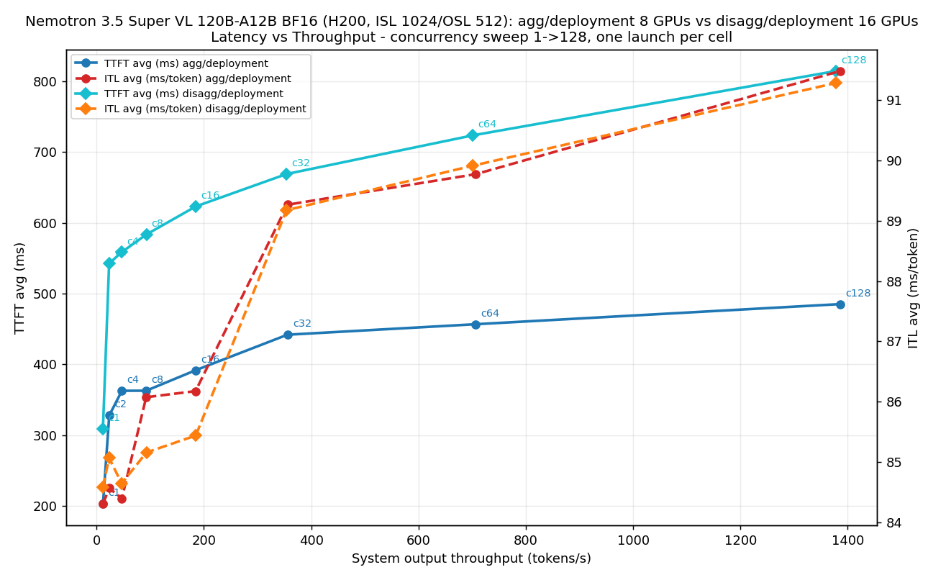
Figure 4: Concurrency sweep comparing aggregated and disaggregated deployments
The preceding concurrency sweep diagram reveals that the inference of Nemotron 3.5 Super VL has lower TTFT and about the same ITL between aggregated and disaggregated deployments on two nodes.
A chart like this is useful when making deployment decisions. Draw your latency budget as horizontal lines, for example TTFT under 600 ms (about 1 second) and ITL under 100 ms per token. The rightmost point under both lines is the throughput one replica of this topology can serve within the service level objective (SLO), here c32, or about 320 tokens per second. To plan capacity, divide your target tokens per second by this per-replica throughput and find the number of prefill-decode pairs to deploy. Re-running the same sweep after a change (precision, TP/PP shape, aggregated versus disaggregated, a new Dynamo or vLLM release) makes the trade-off visible immediately. A curve that moves right and down is a win. Because TTFT and ITL are plotted separately, it also tells you which side to scale: rising ITL says add decode capacity, and rising TTFT says add prefill capacity.
Conclusion
This post covers the architecture and performance evaluation patterns for serving NVIDIA Nemotron models on Amazon EKS, EKS Auto Mode, and SageMaker HyperPod EKS with NVIDIA Dynamo and vLLM. To get started, deploy Nemotron 3.5 Super VL in your own account, using the reference implementation. More inference blueprints are also available in the AI on EKS project. To get further hands-on experience with inference on EKS, register for our upcoming workshops.
Acknowledgements
The authors would like to convey special thanks to everyone involved in developing, validating, reviewing, and publishing this content, including but not limited to: Eliuth Triana, Jiahong Liu, Kshitiz Gupta, Abhijeet Patil, Mike Stefaniak, Chris Splinter, Sheetal Joshi, Aditya Ramakrishnan, Natarajan Kumar, Anish Maddipoti.