Phonic-1 Launches with Real-Time Voice Interaction and Tool Calling
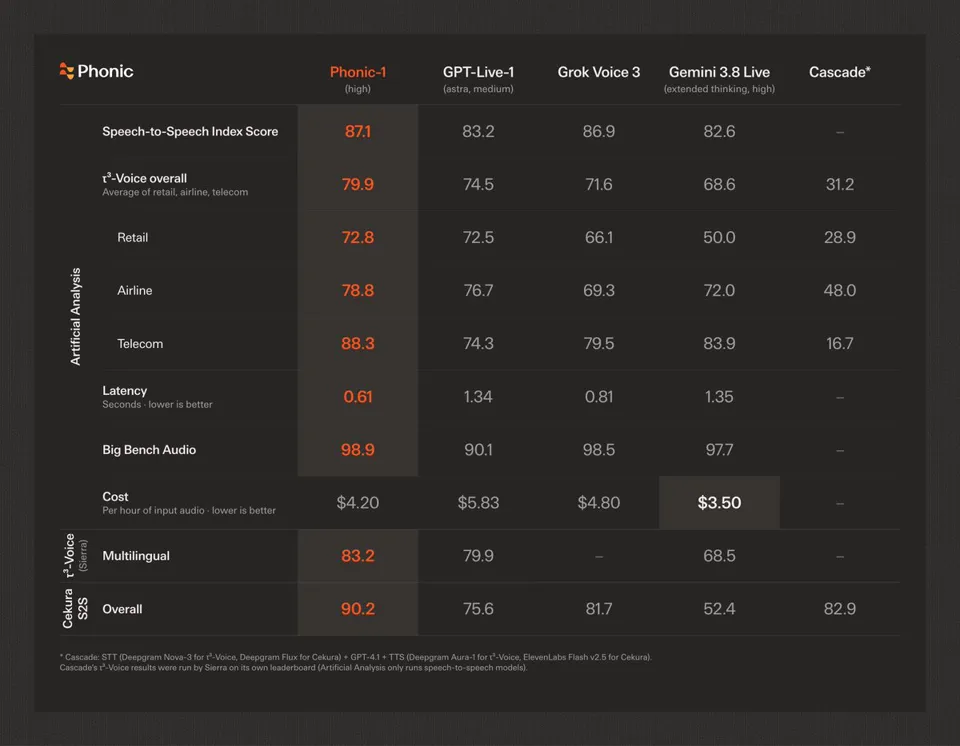
Startup Phonic released Phonic-1, claiming it is the only voice model capable of executing lookups and bookings while the caller is still speaking. The model scored 87.1 on the Artificial Analysis speech-to-speech index, slightly surpassing Grok Voice 3.0, with a first-audio latency of 0.61 seconds. Despite discrepancies in third-party benchmark data, Phonic secured a $27.5M Series A and powers Ashby's AI interviews.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-29 17
A 10-person startup Phonic has released Phonic-1, which it says is the only voice model that can run lookups and bookings while the caller is still mid-sentence.
First on Artificial Analysis’s speech-to-speech index at 87.1, just 0.2 points above xAI’s Grok Voice 3.0, completing 79.9% of customer-service tasks with 0.61 seconds to first audio.
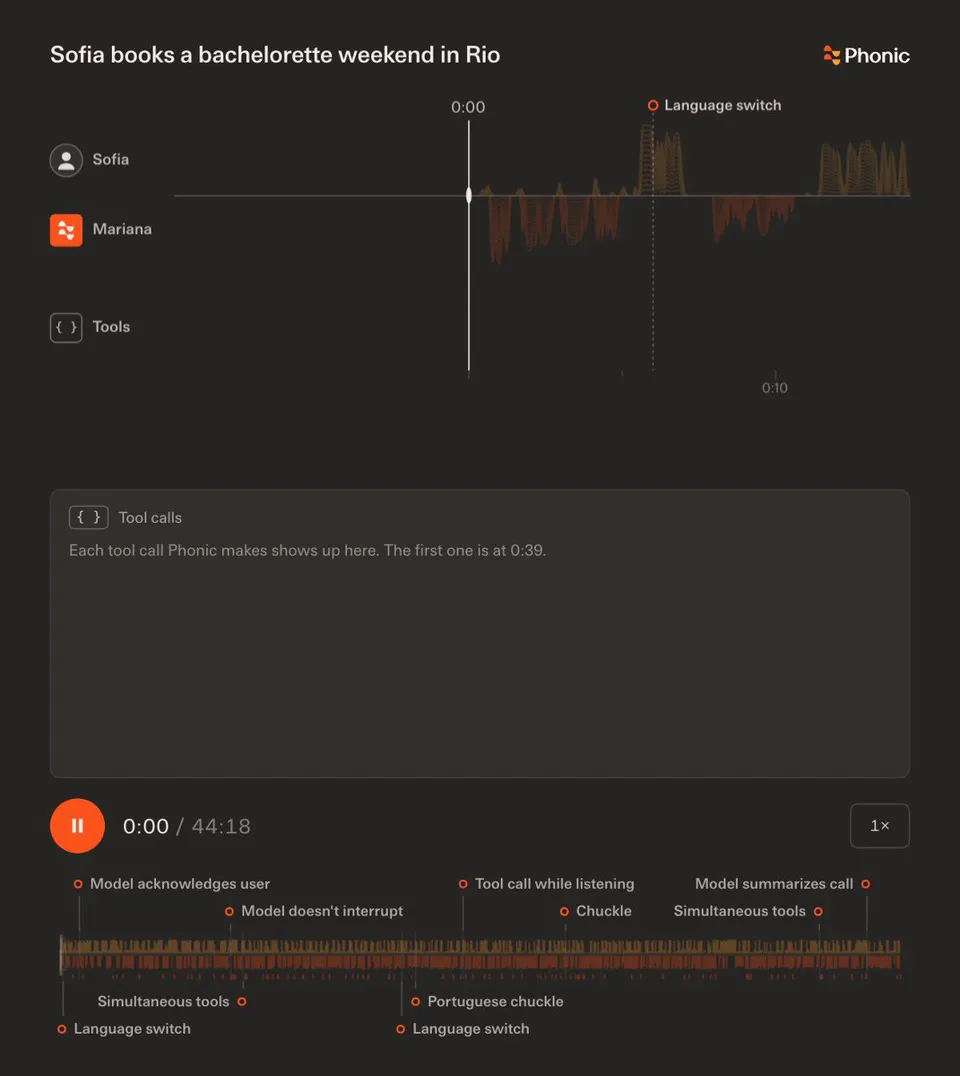
Phonic-1 calls tools while the caller is still talking; in the demo it finished 5 lookups mid-speech and replied 1.1 seconds after the caller stopped, versus 15.7 seconds for OpenAI’s GPT-Live.
Phonic reports 90.2 on Cekura’s call suite, beating a transcribe-think-speak cascade at 82.9% that outscores every ranked speech-to-speech model there, though Cekura’s public board lists Phonic v1 at 68.3%.
They raised a 31.5M, and Phonic already powers Ashby’s AI job interviews in 25 countries.
↳ 引用 @moinnadeem (Moin Nadeem): Introducing Phonic-1, the most advanced speech-to-speech model for agentic tasks — from @phonic_co, the speech-to-speech model company.
We’ve had a breakout year and raised a $27.5M Series A led by @firstround with participation from @Lux_Capital, @felicis, and Definition.