SemiAnalysis Launches GDPx Benchmark Showing Low AI Agent Scores on Expert Tasks
SemiAnalysis released the GDPx benchmark to evaluate AI agents on expert-level tasks across 11 domains like chip design and finance. Results show even top models like Claude Opus 5.5 average only 12%, with all models scoring zero in finance and law under strict grading, highlighting significant gaps in handling complex real-world workflows.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-02 12
SemiAnalysis has released GDPx, a benchmark testing AI agents on expert work across 11 domains.
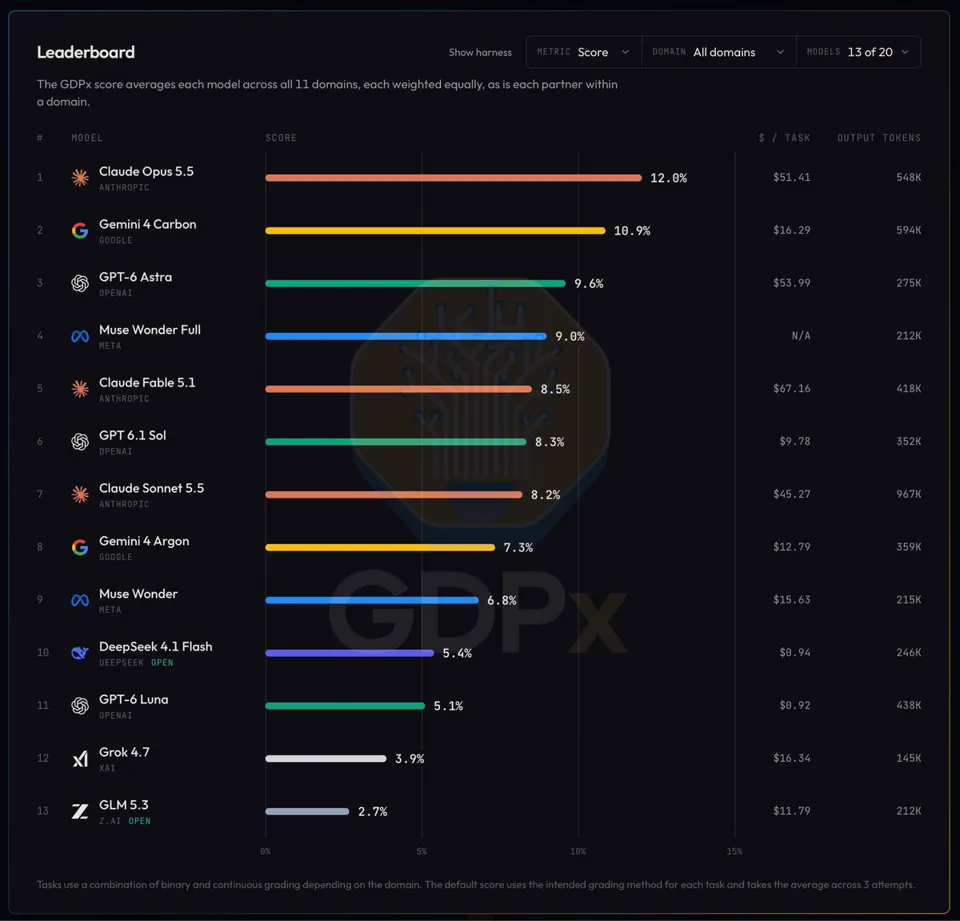
The top model, Anthropic’s Claude Opus 5.5, averages just 12%, with Google’s Gemini 4 Carbon next at 10.9%.
OpenAI’s GPT-6 Astra tops AI-research and materials-science tasks.
The tasks, spanning chip design, cybersecurity, finance and law among others, come from 14 specialized data partners.
Unlike OpenAI’s GDPval, which feeds models context in the prompt, GDPx makes agents dig through workspaces such as a 3,983-file replica of a real acquisition.
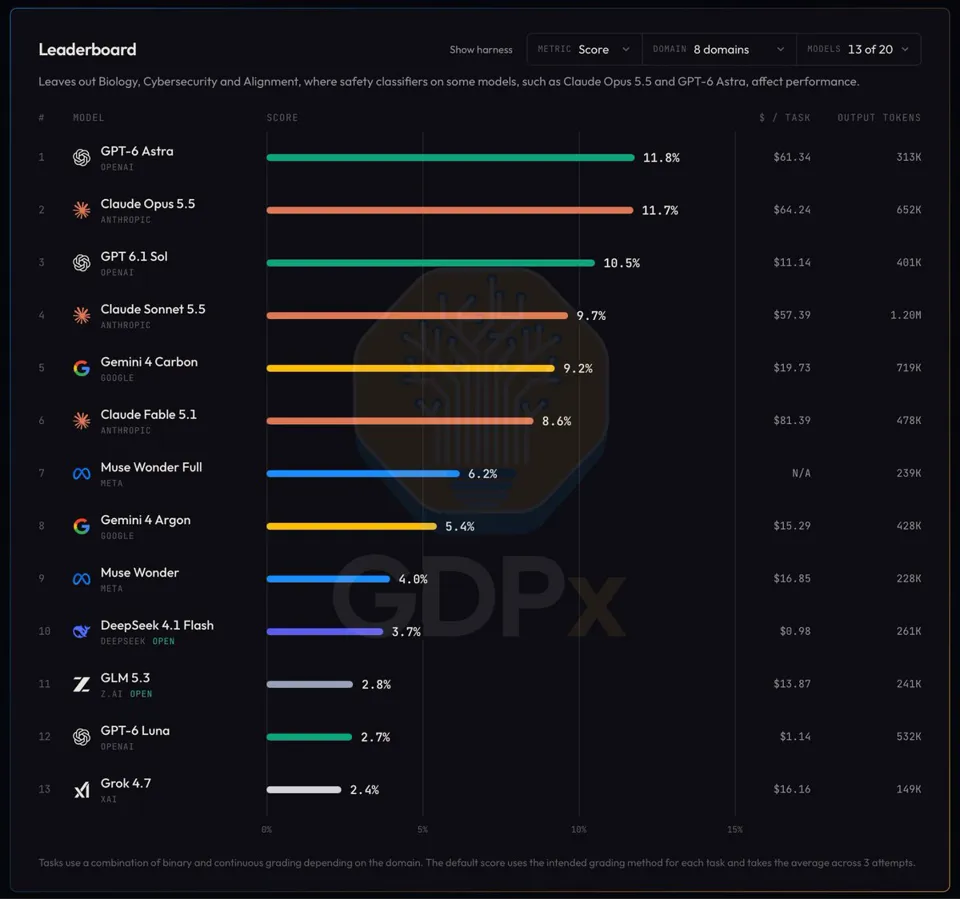
Excluding cyber, biology and alignment, where safety classifiers sometimes intervene, lifts OpenAI’s GPT-6 Astra from 9.6% to 11.8%, past Opus.
Finance and law defeat every model: all score 0 under pass-fail grading, so GDPx reports partial credit instead.
Asked to improve a working trading strategy, models did worse than the original in 70 of 111 attempts, often just taking bigger risks instead of finding better trades.