量子位官网 · 10/17/2026, 20:21:09
DeepSeek Releases V4.1-Flash-1017 with Pareto Improvement in Performance and Cost
DeepSeek has released the new model V4.1-Flash-1017, which outperforms its predecessor in code and agent benchmarks. The update achieves a 'performance-cost' Pareto improvement by enhancing task performance while significantly reducing runtime and token consumption. It is now live across web, app, and API, with specific optimizations for frameworks like DeepSeek Harness.
SOURCE COVERAGEFull Original Report
Contents4 sections
Shui Yi, Lu Yu reporting from Ao Fei Si QbitAI | Official Account: QbitAI
It all adds up. Everything checks out.
A couple of days ago, when DeepSeek experienced a "crash followed by compensation," some speculated that Teacher D was preparing for new moves?
And sure enough, the community’s wait paid off—the new model DeepSeek-V4.1-Flash-1017 has been swiftly released.
With the new model in place, DeepSeek Harness version 0.2.1 also received enhancements. The official statement reads:
The new model underwent specialized optimization during training specifically for DeepSeek Harness, improving task performance while reducing execution time, output consumption, and token costs.
Wow, it works faster, is more cost-efficient, and performs better!!

Additionally, over this weekend, Teacher D threw in a bonus:
Eligible users who log in to DeepSeek Harness for the first time can directly claim a 6 RMB credit voucher. No top-up required; the credit is valid for 7 days after arrival.
Key point: The quota is limited and available on a first-come, first-served basis (ahem, I have urgent matters to attend to, so I’m off~).
Stronger Performance, Lower Costs
After claiming the bonus, let’s look at the highlights of this model (if you’ve previously logged into Harness, remember to log out and back in).
Currently, the official web interface, app, and API models have all been synchronized to the new model.
Compared to the previous V4.1 Flash version, the 1017 release shows consistent improvements across various benchmarks, with notable gains in coding and Agent task capabilities.

But improved scores alone aren’t the most striking aspect of this update.
As model performance surged, task execution times and output lengths were simultaneously reduced.
Huh? You want the horse to run fast but don’t want to feed it much grass??
The official team calls this a "Pareto improvement in performance-cost." Previously, to get an Agent to perform tasks better, one usually had to accept that it would think longer, take more steps, and generate more tokens.
With V4.1-Flash-1017, the model begins to minimize detours and unnecessary chatter, focusing directly on completing the task.

According to the official DeepSWE tests, V4.1-Flash-1017 has further pushed the boundary between performance and cost across multiple Agent frameworks.
In particular, DeepSeek Harness, Tencent CodeBuddy, and WorkBuddy have all benefited from these specialized optimizations.
To fully leverage these new capabilities, DeepSeek Harness must be upgraded to version 0.2.1-rc.1 or higher.
"Wish-Based Programming Comes True"
Of course, no matter how impressive the benchmarks are, seeing what it can actually build is more convincing.
For V4.1-Flash-1017, DeepSeek introduced a new feature aptly named "Wish-Based Programming"—clearly understanding netizens' desires.
How does "wishing" work?
Previously, building a complete project required breaking down features, structure, interactions, and tech stack, explaining each item to the model step-by-step.
Now, users only need to clearly state what they want. The rest—planning, coding, running, checking, and modifying—is handled autonomously by the model.
The key behind this is a reinforcement learning training technique based on self-feedback.
After writing the first version, the model doesn’t immediately stop. It continues to check its own output, identifies errors, and revises them accordingly.
What kind of results does this method produce?
The official team went big right away, literally "building the Forbidden City."
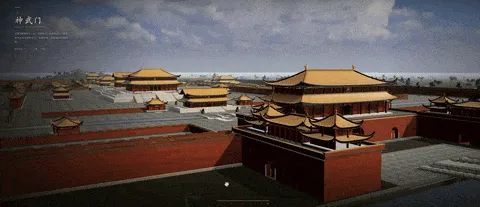
Teacher D used code to construct a 3D scene that allows real-time browsing and perspective switching.
Nice. While others are still doing Vibe Coding for Todo Lists, Teacher D has started Vibe Building the Forbidden City...
And subsequent examples got even wilder:
A web-based racing game runs smoothly, a Godot recreation of Portal 2 offers true interactivity, and there’s a dynamic 3D world spanning from prehistoric times to the modern era.
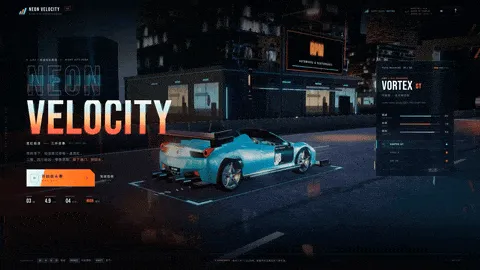
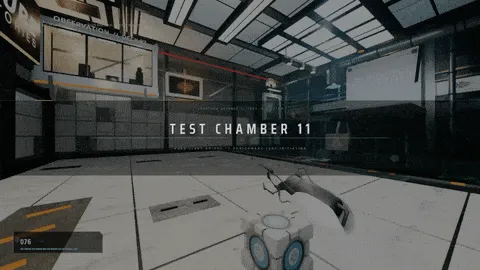
From a single sentence to a complete project that is viewable, interactive, and playable.
"Wish-Based Programming"—this time, Teacher D really made the wish come true.
Model Leak Suspected Before Release: "Smarter, Yet More Concise"
In fact, DeepSeek-V4.1-Flash-1017 had already leaked like a sieve before its official announcement.
Several hours ago, sharp-eyed netizens noticed that "DeepSeek V4.1 Flash-1017" briefly appeared in DeepSeek’s model list.
Although it was listed for a short time, those waiting for updates caught it red-handed.
"1017" corresponds exactly to October 17th, aligning with DeepSeek’s consistent practice of using dates to mark model snapshots.
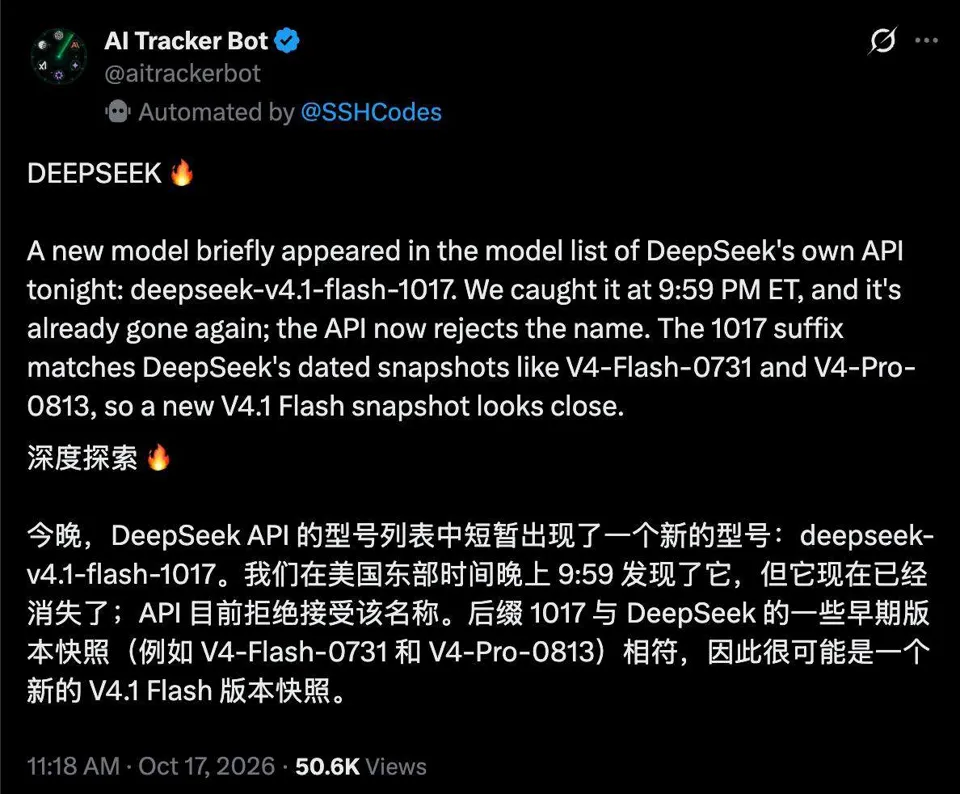
Shortly after, another piece of evidence emerged.
Netizens discovered that the system fingerprint returned by the deepseek-flash interface had changed from " aeb56401ca74e127821c4f9126dcb669" to "e72d3c7f663d3e1383b00b3884cb4501".
A change in the system fingerprint typically indicates that the backend service’s model version or deployment configuration has been updated.
Following a round of testing, the prevailing consensus is:
The new model appears smarter, faster, and produces more concise outputs.
Blogger Chetaslua noted that the newer version on the right generates images with richer details and more realistic lighting effects.

The results from single-prompt generation are also impressive, complete with a detailed breakdown of the creation process.
The original author stated that it feels smoother to use than Gemini 4 Argon.
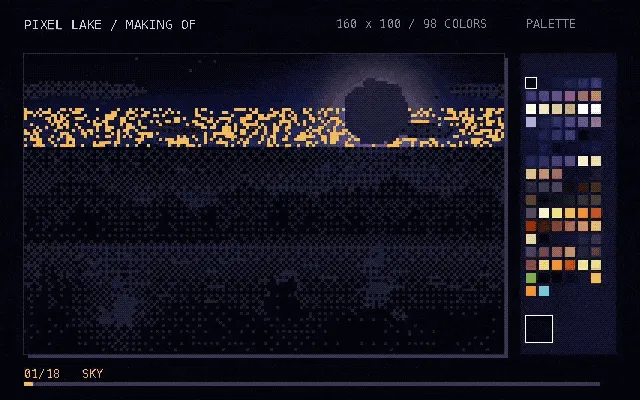
Based on additional multimodal results, the new model seems to have enhanced its 3D generation capabilities.
A set of images shared by blogger Hakm is quite stunning, evoking the same sense of awe felt when GPT-6 Astra was released.
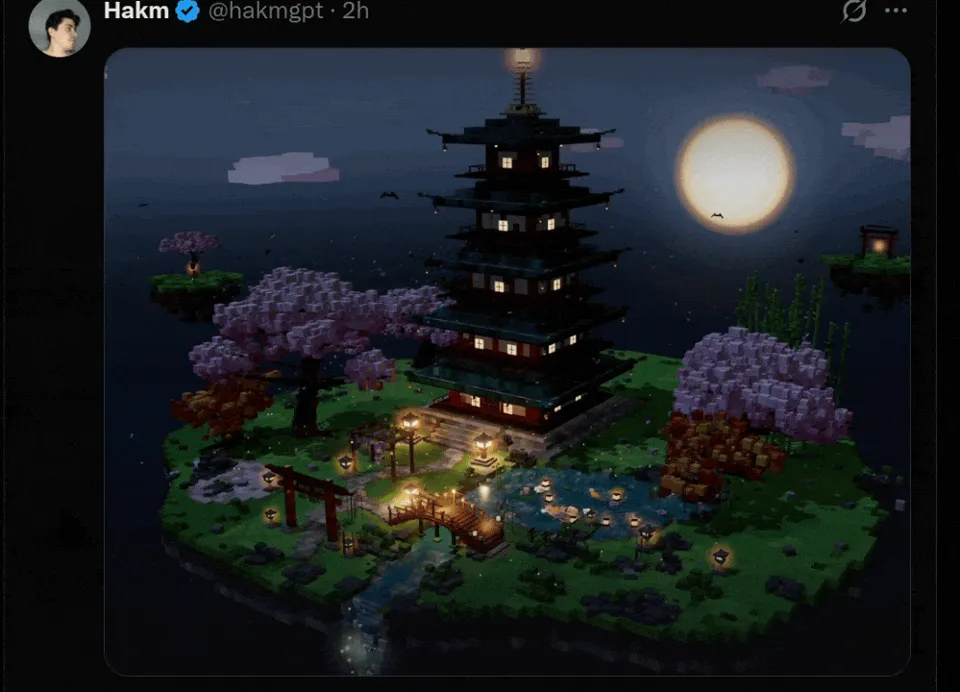
He also used the model to generate a classic first-person shooter game.
Wow! This is definitely worth watching.
Proprietary Search API Now Available
Beyond this, DeepSeek has also provided us with dedicated tools for Agents to search online for information.
DeepSeek’s proprietary search engine officially launched two API endpoints: Search and Fetch. The former handles web searching, while the latter retrieves article content.

Developers can first instruct an Agent to find resources based on keywords, then scrape selected web pages into Markdown text for further analysis by the model.
The Search API supports filtering by website, language, and publication date, allowing users to narrow down results when looking for the latest news.
Billing for this service is calculated separately based on successful request counts:
Pricing is incredibly low at $0.70 per 1,000 successful requests, costing less than half a cent per use; failed requests, empty search results, or timeouts incur no charges.
Users can currently access the DeepSeek API via DeepSeek Harness, Claude Code, or Codex, with free usage available until November 1st.

Honestly, the king of cost-performance is back.
DeepSeek has entered another "Liang Sheng" cycle (referring to CEO Liang Wenfeng's period of rapid innovation).
HuggingFace:
https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
ModelScope:
https://modelscope.cn/models/deepseek-ai/DeepSeek-V4.1-Flash-1017
References: [1] https://mp.weixin.qq.com/s/X-5kbBkedQ5Oct9byUunag [2] https://x.com/aitrackerbot/status/2111295736411300047 [3] https://x.com/yugen_matuni/status/2111336985554227345 [4] https://x.com/hakmgpt/status/2111314470433947988 [5] https://x.com/hakmgpt/status/2111314427416895798 [6] https://api-docs.deepseek.com/guides/search/