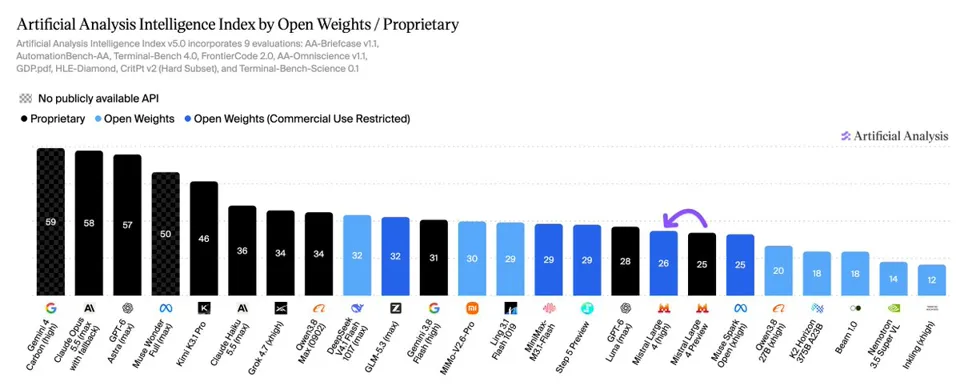
Mistral Large 4 Open Weights Release Tops Non-Chinese Models
Mistral AI has released the open weights for its flagship model, Mistral Large 4, featuring 1.05T total and 52B active parameters. Scoring 26 on the Artificial Analysis Intelligence Index, it narrowly surpasses Muse Spark Open to become the top non-Chinese open-weights model, though it still trails leading Chinese models like DeepSeek V4.1 Flash.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-29 14
Mistral Large 4 is now open weights, narrowly making it the #1 open weights model developed outside of China
@MistralAI has updated and released the weights of their flagship model, Mistral Large 4, with 1.05T total and 52B active parameters. With high reasoning, Mistral Large 4 scores 26 on the Artificial Analysis Intelligence Index v5, up 1 point from Mistral Large 4 Preview (25), with the major differences being increased token efficiency and reduced hallucinations. It sits 1 point ahead of the leading US-developed open weights model, Muse Spark Open (xhigh, 25).
On the Artificial Analysis Cyber Index, Mistral Large 4 (high) scores 51, third among current open weights models behind DeepSeek V4.1 Flash 1017 (max, 57) and MiMo-V2.6-Pro (56).
Key takeaways:
➤ Narrowly leads non-Chinese open weights models: Mistral Large 4 (high) leads Muse Spark Open (xhigh), the next-best open weights model developed outside China, with the largest gap on Terminal-Bench 4.0 (25% vs. 8%). It trails leading open weights models DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) by 6 points on the Intelligence Index, largely due to weaker coding and agentic knowledge work performance: 15% on FrontierCode 2.0 (vs. 29% and 22%, respectively) and 1349 Elo on AA-Briefcase (vs. 1570 and 1504)
➤ Increased token efficiency: Mistral Large 4 (high) uses 82K output tokens per Intelligence Index task, 39% fewer than Preview (135K), placing it on the open weights Pareto frontier. The seven open weights models that score higher use between 113K and 225K output tokens per task
➤ #2 open weights model on the Coding Agent Index: On the Artificial Analysis Coding Agent Index, Mistral Large 4 (high) scores 48 in Mistral Vibe while using 8.5M tokens per task, about half as many as the leading open weights model GLM-5.3 (max) in Opencode (49, 15.9M). It also scores above another leading open weights model, DeepSeek V4.1 Flash 1017 (max), in DeepSeek Harness (46, 16.7M)
➤ Reduced hallucinations: Mistral Large 4 (high) has a 28% hallucination rate on the updated AA-Omniscience v1.1, down from 41% for Preview and matching Muse Spark Open (xhigh). However, its accuracy remains relatively low at 26%, similar to Ling 3.1 Flash 1019 (27%), and behind DeepSeek V4.1 Flash 1017 (max, 40%) and Muse Spark Open (xhigh, 42%)
➤ Lower price and cost per task than the Preview: Mistral Large 4 is priced at 2.10 per 1M input/output tokens, a ~50% reduction from the Preview's pricing of 4.18. At the new pricing, it costs $2.06 per Intelligence Index task, down 63% from $5.54 for the Preview. This is comparable to Muse Spark Open (xhigh, $2.02) but more costly than leading open weights models DeepSeek V4.1 Flash 1017 (max, 0.26)
Key model details:
➤ Size: 1.05T total parameters / 52B active parameters
➤ Context window: 1M tokens
➤ Multimodality: Text and image input, text output
➤ Pricing: 2.10 per 1M input/output tokens ($0.07 per 1M cached input tokens)
➤ License: MEOW License (Mistral Ecosystem Open-Weight License), where operating a Model-as-a-Service business requires a separate commercial license with Mistral
Congratulations to the team at @MistralAI on the release!