Google Proposes VeriCUA to Verify AI Agent Task Completion
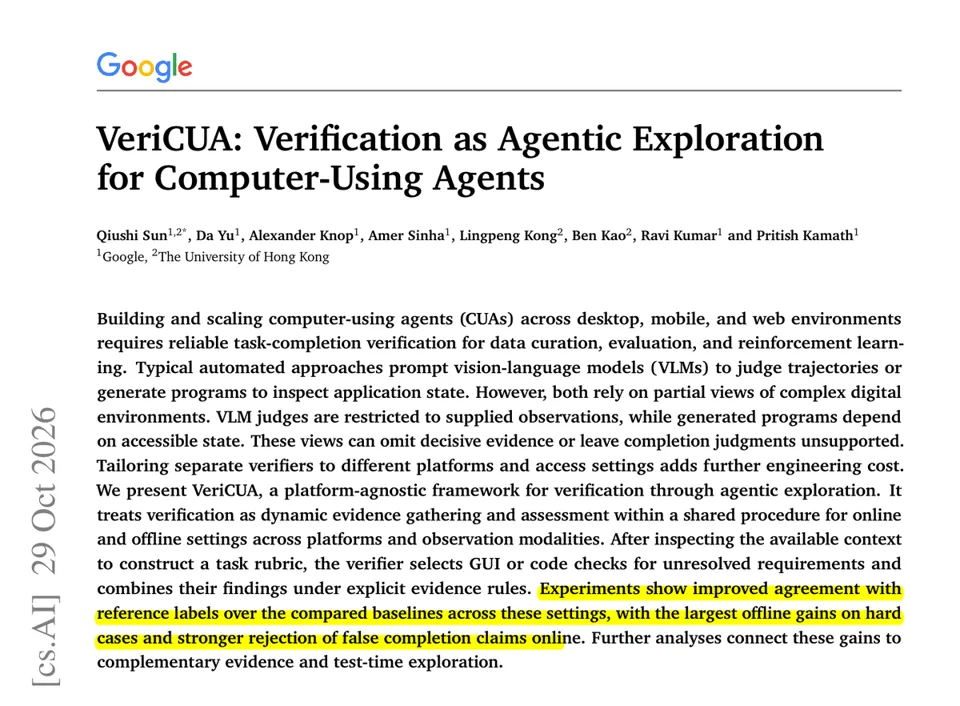
Google and HKU introduce VeriCUA, a framework that validates computer-use agents by checking saved files and app data instead of relying on screenshots or agent self-reports. This approach reduces false-positive rates from ~25% to 5.4% on ScienceBoard, offering a more reliable verification mechanism for agent evaluation and RL rewards.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-03 02
New Google and University of Hong Kong paper argues that when AI agents use computers, their own “task done” message should never count as proof, and the saved files and app data should be checked instead.
Computer-use agents can report a task done when edits were never saved or only part was finished. Common checkers either judge a few screenshots or run 1 generated script, and both can miss the deciding evidence.
VeriCUA explores the app to build a requirement checklist, then runs screen or code checks, like file reads, until each item is settled. The agent's own claim of success never counts as proof.
On ScienceBoard, its false-positive rate was 5.4%, against 24.8% for a VLM judge and 21.7% for a generated script verifier. Across 3 online environments, it rejected about 80% of false completion reports.
If agent runs feed your evals, training data, or RL rewards, check saved machine state instead of trusting screenshots or the agent's report.