Artificial Analysis Releases Capability Indexes v2.0 with Focus on Hallucination and Agentic Tool Use
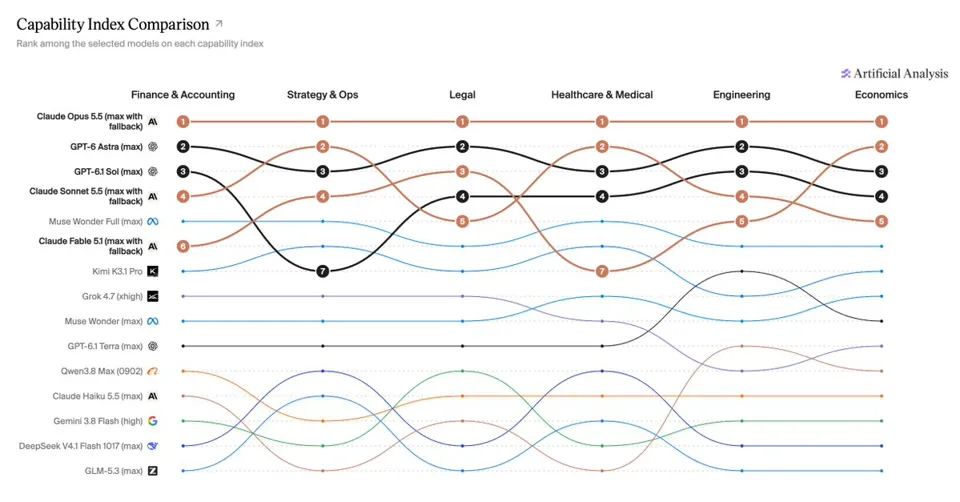
Artificial Analysis updated its six industry-specific Capability Indexes to v2.0, aligning them with the Intelligence Index v5.0. The update places greater emphasis on Non-Hallucination and Agentic Tool Use capabilities while adjusting benchmark weights. Among open-weight models, Kimi K3.1 Pro (weights unreleased) leads all six indexes, followed by MiniMax-M3.1-Flash in Strategy & Ops and DeepSeek V4.1 Flash in Healthcare.
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-04 00
We’ve updated the six Artificial Analysis Capability Indexes to v2.0, aligning them with evaluations from the Artificial Analysis Intelligence Index v5.0 and placing greater emphasis on Non-Hallucination and Agentic Tool Use
The Capability Indexes map tasks from O*NET occupations to benchmarks that represent them, weighting each benchmark by how often its capability appears in that occupation. There are six indexes: Finance & Accounting, Strategy & Ops, Legal, Healthcare & Medical, Engineering, and Economics.
Key changes:
➤ Finance & Accounting: increased weight on Non-Hallucination, upgraded HLE to HLE-Diamond and AA-Omniscience to v1.1, removed GDPval-AA from Agentic Knowledge Work, and removed AA-LCR from Long-Context
➤ Strategy & Ops: increased weight on Agentic Tool Use, added Non-Hallucination and upgraded AA-Omniscience to v1.1, removed GDPval-AA from Agentic Knowledge Work, and removed AA-LCR from Long-Context
➤ Legal: increased weight on Non-Hallucination, upgraded HLE to HLE-Diamond and AA-Omniscience to v1.1, removed GDPval-AA from Agentic Knowledge Work, and removed AA-LCR from Long-Context
➤ Healthcare & Medical: increased weight on Agentic Tool Use, upgraded HLE to HLE-Diamond and AA-Omniscience to v1.1, and removed GDPval-AA from Agentic Knowledge Work
➤ Engineering: added Science as a new capability sourced from CritPt v2 (Hard Subset) and Terminal-Bench-Science 0.1, added FrontierCode 2.0 to Agentic Coding, upgraded HLE to HLE-Diamond and AA-Omniscience to v1.1, and removed GDPval-AA from Agentic Knowledge Work
➤ Economics: increased weights on Agentic Knowledge Work and Long-Context Reasoning, replaced AA-LCR with GDP.pdf in Long-Context Reasoning, upgraded HLE to HLE-Diamond and AA-Omniscience to v1.1, and removed GDPval-AA from Agentic Knowledge Work
Key results:
➤ Claude Opus 5.5 (max) leads in all six indexes, followed by GPT-6 Astra (max) in Finance & Accounting, Legal, and Engineering
➤ Among open weights models, Kimi K3.1 Pro (weights not yet released) leads all six indexes, at #5 to #8. MiniMax-M3.1-Flash leads in Strategy & Ops (#10), and DeepSeek V4.1 Flash 1017 (max) leads Healthcare & Medical (#12)