MiniMax M3.1-Flash Launches with 13-Point Score Jump and Halved Costs
MiniMax has released its new Flash reasoning model, M3.1-Flash, which scores 42 on the Artificial Analysis Intelligence Index, a 13-point jump over its predecessor. The model demonstrates substantial improvements in complex reasoning while reducing cost per task by more than half through optimized token usage, with open weights scheduled for release on October 23.
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-19 15
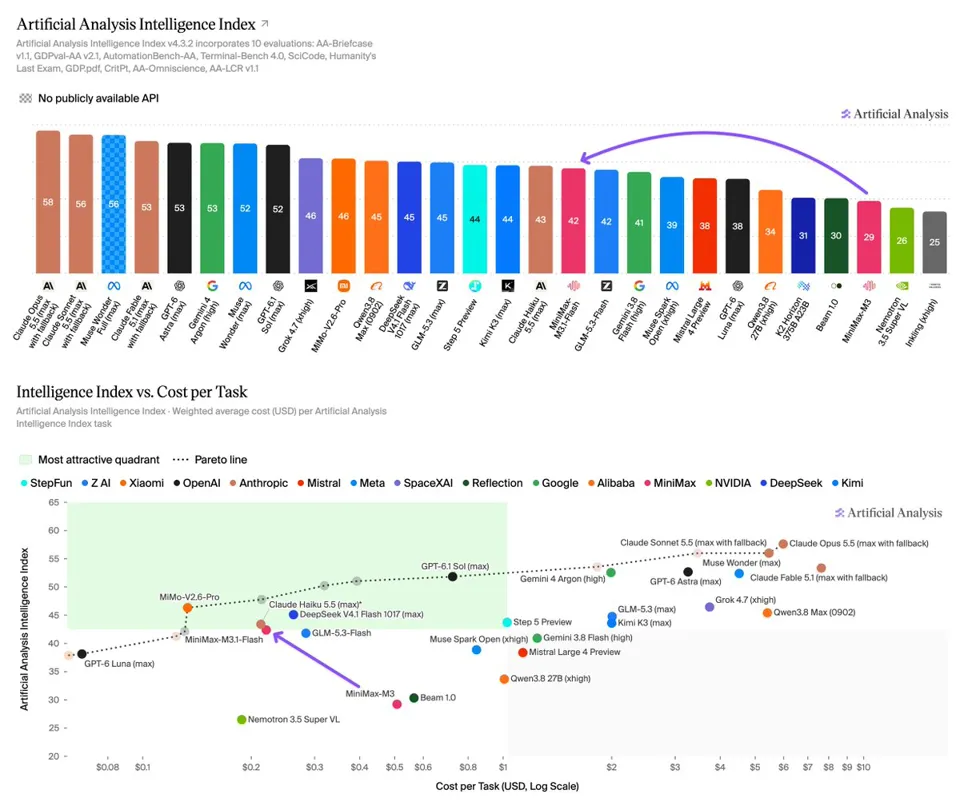
MiniMax-M3.1-Flash scores 42 on the Artificial Analysis Intelligence Index, 13 points higher than MiniMax-M3 and less than half the cost per task. It scores level with GLM-5.3-Flash but behind DeepSeek V4.1 Flash 1017
MiniMax-M3.1-Flash is @MiniMax_AI's new Flash reasoning model, which we benchmarked at its max effort setting. It scores 42 on the Artificial Analysis Intelligence Index, level with GLM-5.3-Flash (max, 42), just ahead of Gemini 3.8 Flash (high, 41), and behind DeepSeek V4.1 Flash 1017 (max, 45)
Key takeaways: ➤ Complex reasoning improved substantially compared to M3: MiniMax-M3.1-Flash scores 48% on Humanity's Last Exam, ahead of GLM-5.3-Flash (max, 40%) and DeepSeek V4.1 Flash 1017 (max, 43%), and level with Gemini 3.8 Flash (high, 48%). On CritPt it scores 22%, ahead of GLM-5.3-Flash (15%) and Gemini 3.8 Flash (18%) and just behind DeepSeek V4.1 Flash 1017 (24%). These are up from MiniMax-M3 which scored 39% and 4% respectively
➤ Fewer output tokens, lower cost per task: MiniMax-M3.1-Flash used ~189M output tokens to run the Intelligence Index, considerably fewer than GLM-5.3-Flash (max, ~324M), DeepSeek V4.1 Flash 1017 (max, ~224M) and Gemini 3.8 Flash (high, ~334M). Combined with pricing of 0.60 per 1M input/output tokens, this brings its cost to ~$0.22 per Intelligence Index task, vs ~$0.28 for GLM-5.3-Flash, ~$0.26 for DeepSeek V4.1 Flash 1017 and ~$1.24 for Gemini 3.8 Flash, and less than half MiniMax-M3's ~$0.51
➤ High AA-Omniscience accuracy, offset by a high hallucination rate: MiniMax-M3.1-Flash answers 56% of questions correctly on AA-Omniscience, our benchmark measuring factual recall and hallucination, vs 28% for GLM-5.3-Flash (max) and 43% for DeepSeek V4.1 Flash 1017 (max). It attempts almost every question, resulting in a hallucination rate of 93% and an overall score of 16 on AA-Omniscience
Key model details:
➤ Context window: 1M tokens
➤ Multimodality: Text and image input, text output
➤ Pricing: 0.60 per 1M input/output tokens, with cached input at $0.015/M
➤ Availability: MiniMax first-party API, with MiniMax announcing an open weights release on October 23rd
➤ Licensing: Closed weights currently, with MiniMax announcing a weights release on October 23rd