Zhipu Open-Sources GLM-OCR: 0.9B Model Tops Doc Parsing SOTA
Zhipu AI has released and open-sourced GLM-OCR, a lightweight model with only 0.9B parameters that achieves state-of-the-art performance (94.6 score) on OmniDocBench V1.5. Optimized for complex scenarios like handwriting, tables, and code, it supports efficient deployment via vLLM and SGLang, offering a high-performance solution for edge computing and high-concurrency applications.
Related Entities
Full Report
Contents2 sections
Today, we officially release and open-source GLM-OCR, setting a new benchmark for document parsing with its "compact size, high precision" design. As a lightweight, professional-grade OCR model, its core highlights are as follows:
- SOTA Performance: Tops the OmniDocBench V1.5 leaderboard with a score of 94.6, achieving State-of-the-Art (SOTA) results across multiple mainstream benchmarks in formula recognition, table recognition, and information extraction;
- Scenario Optimization: Specifically engineered to address real-world business pain points, delivering robust performance in challenging scenarios such as handwriting, complex tables, code documentation, and seals;
- Efficient Inference: With only 0.9B parameters, it supports deployment via vLLM, SGLang, and Ollama, significantly reducing inference latency and computational overhead—ideal for high-concurrency and edge deployments;
- Open-Source & Easy Integration: We simultaneously open-source the complete SDK and inference toolchain. With simple environment dependencies and one-command quick invocation, it integrates seamlessly into existing business systems.
SOTA Performance, Precision in Action
Leveraging our proprietary CogViT visual encoder and deep scenario optimization, GLM-OCR achieves "compact size, high precision." Despite having only 0.9B parameters, GLM-OCR attains SOTA performance on the authoritative document parsing leaderboard OmniDocBench V1.5 with a score of 94.6. It outperforms several specialized OCR models in four key sub-domains—text, formula, table recognition, and information extraction—with performance approaching that of Gemini-3-Pro.
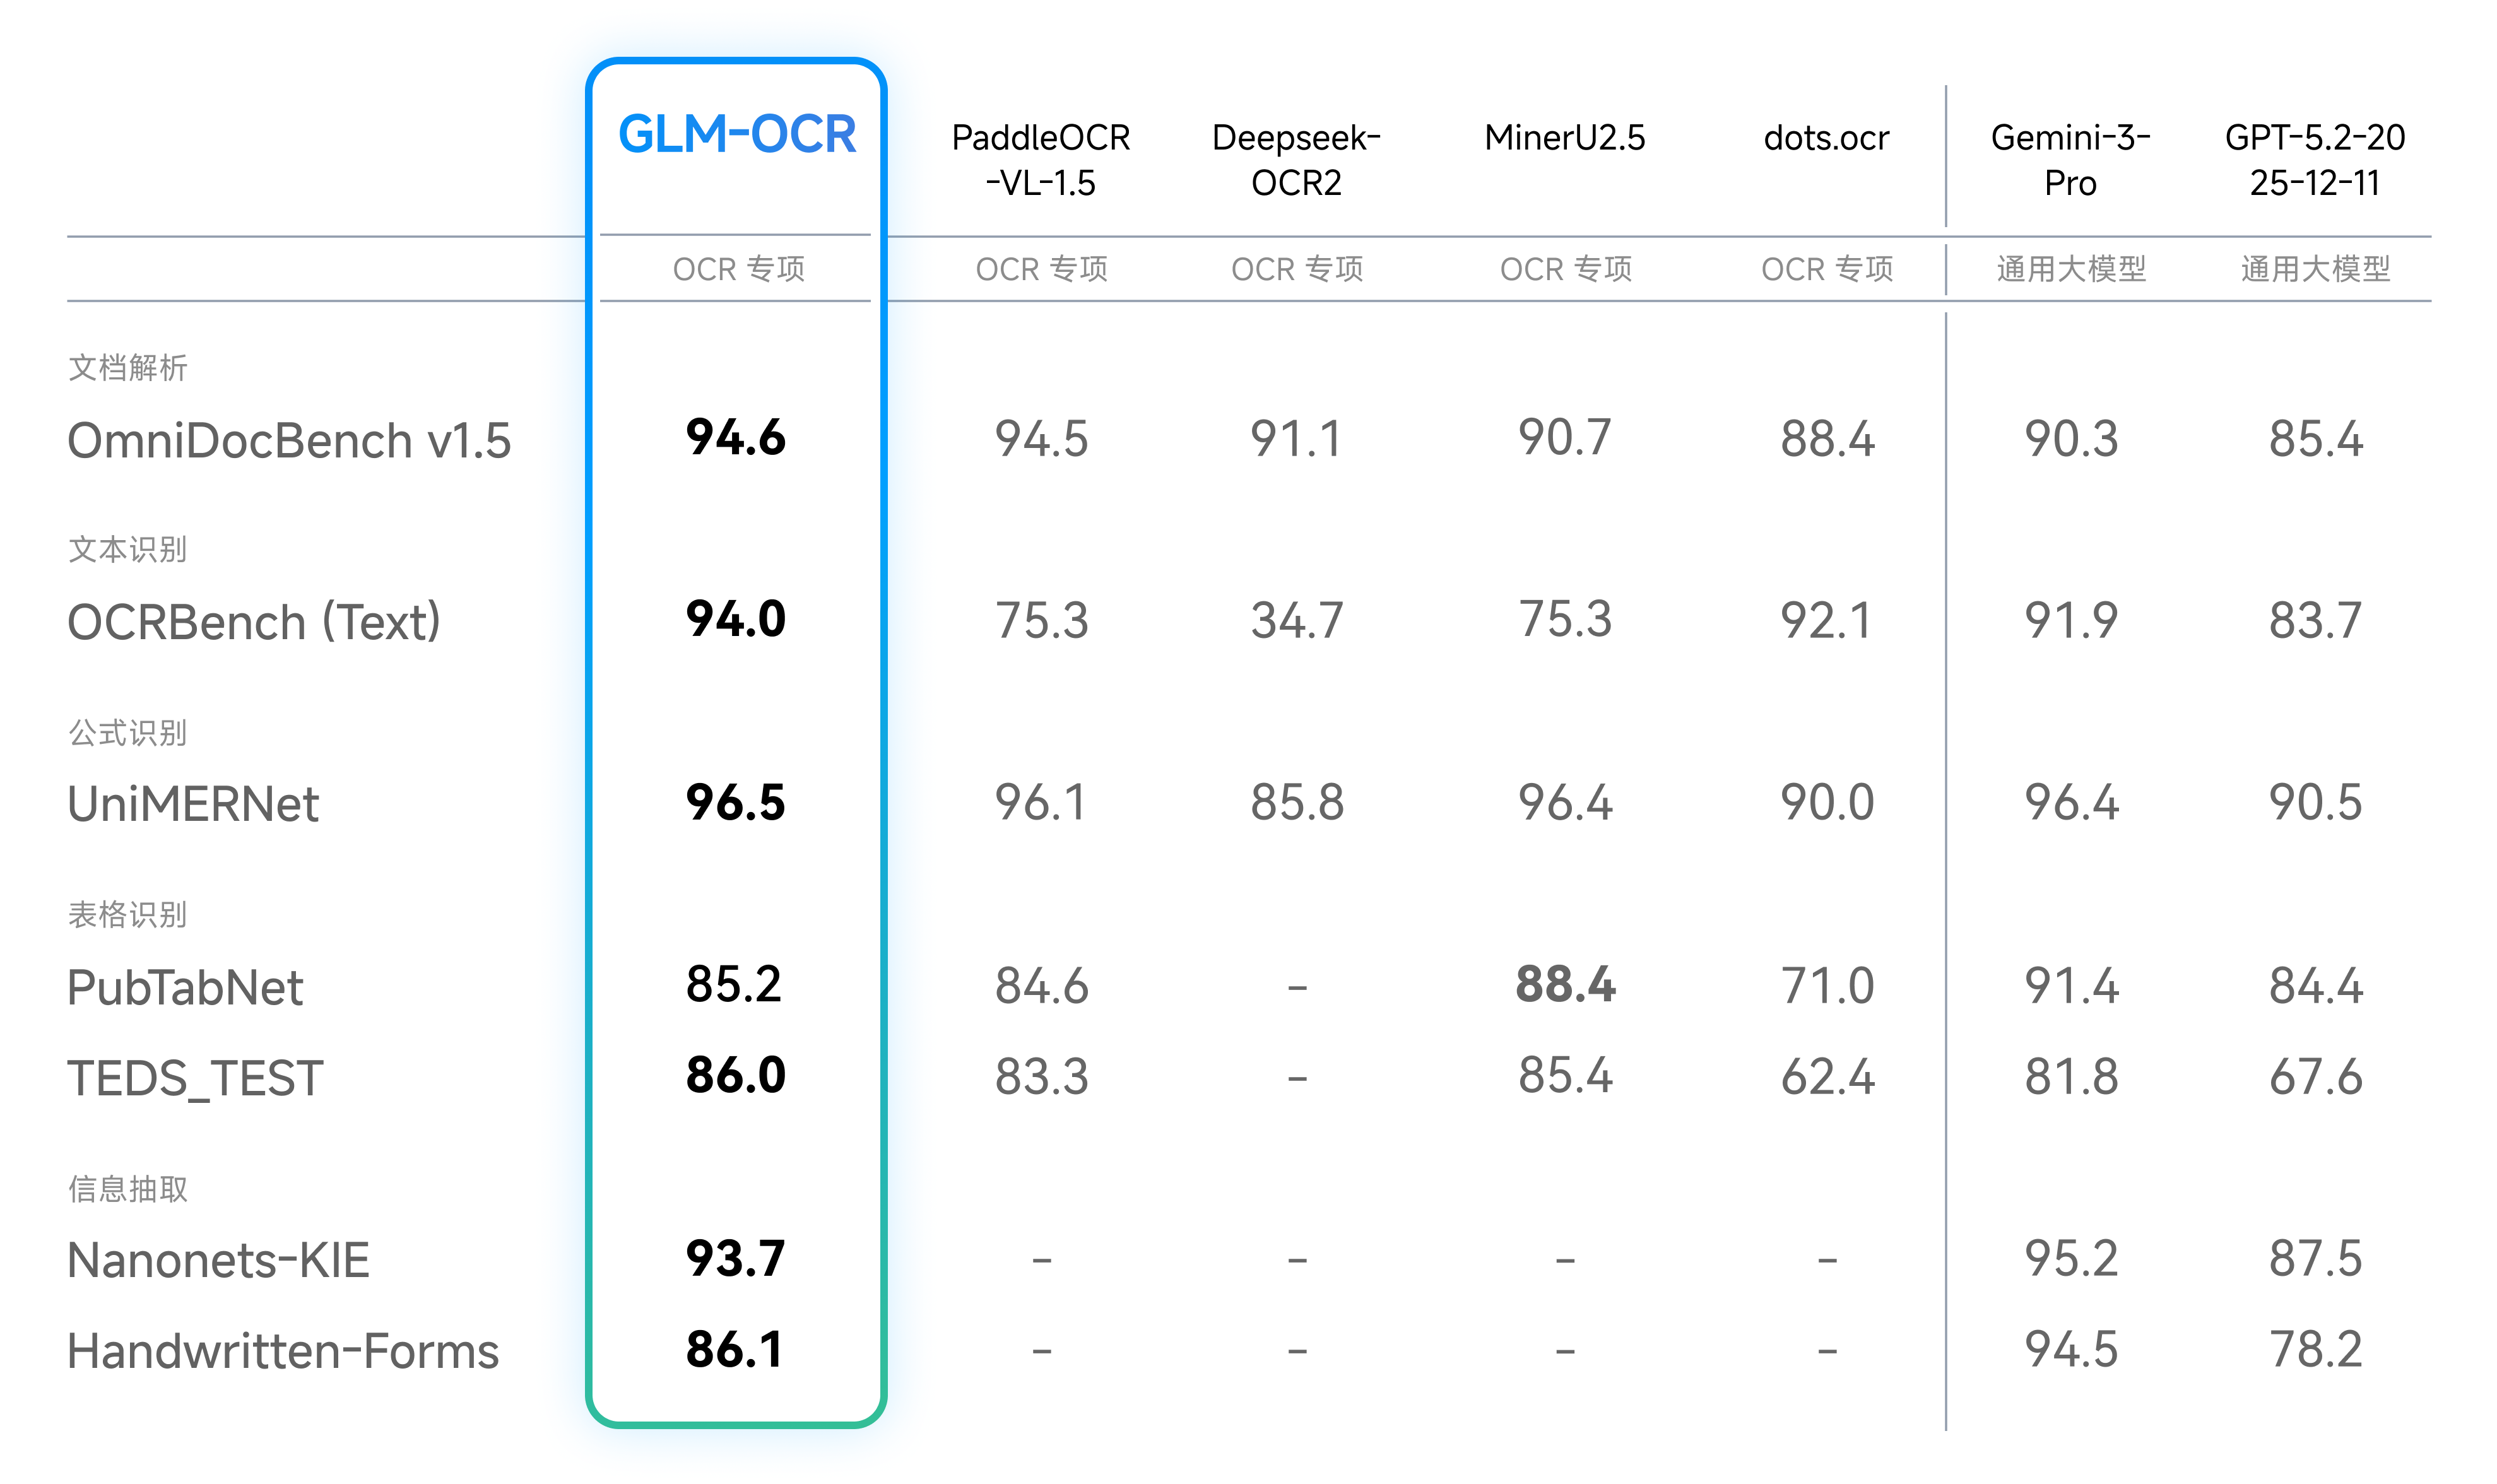
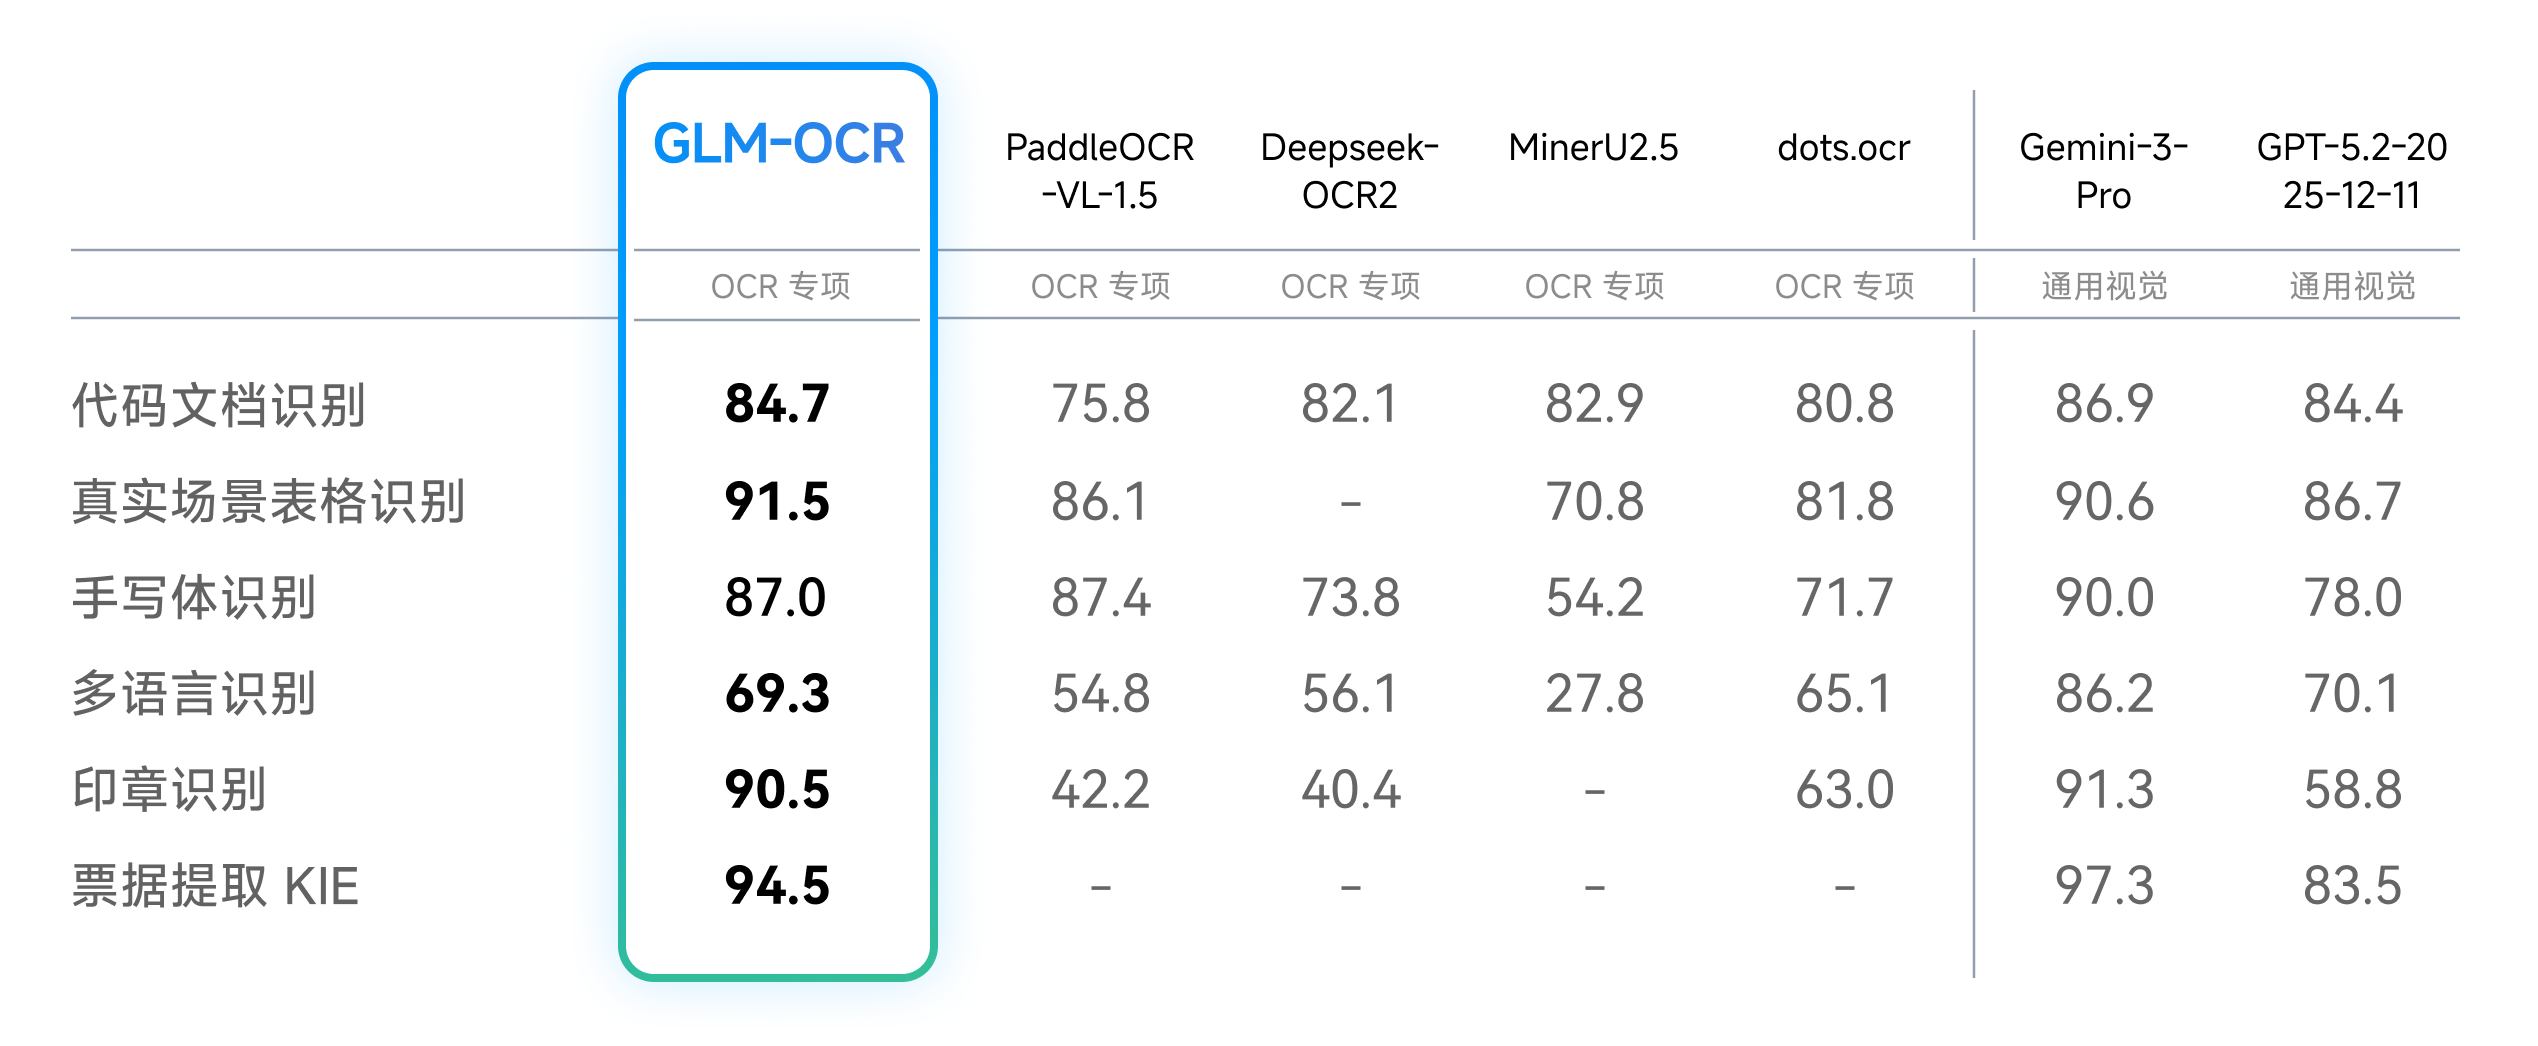
Beyond public leaderboards, we conducted internal evaluations across six core real-world business scenarios. The results show that GLM-OCR holds significant advantages in dimensions including code documentation, real-world tables, handwriting, multilingual text, seal recognition, and invoice extraction.
Case Studies
In practical applications, GLM-OCR accurately parses scanned documents, PDFs, tables, and invoices, effectively solving challenges related to handwriting, seals, vertical text layout, and mixed-language content. It maintains extremely high accuracy and robustness even under complex layouts.
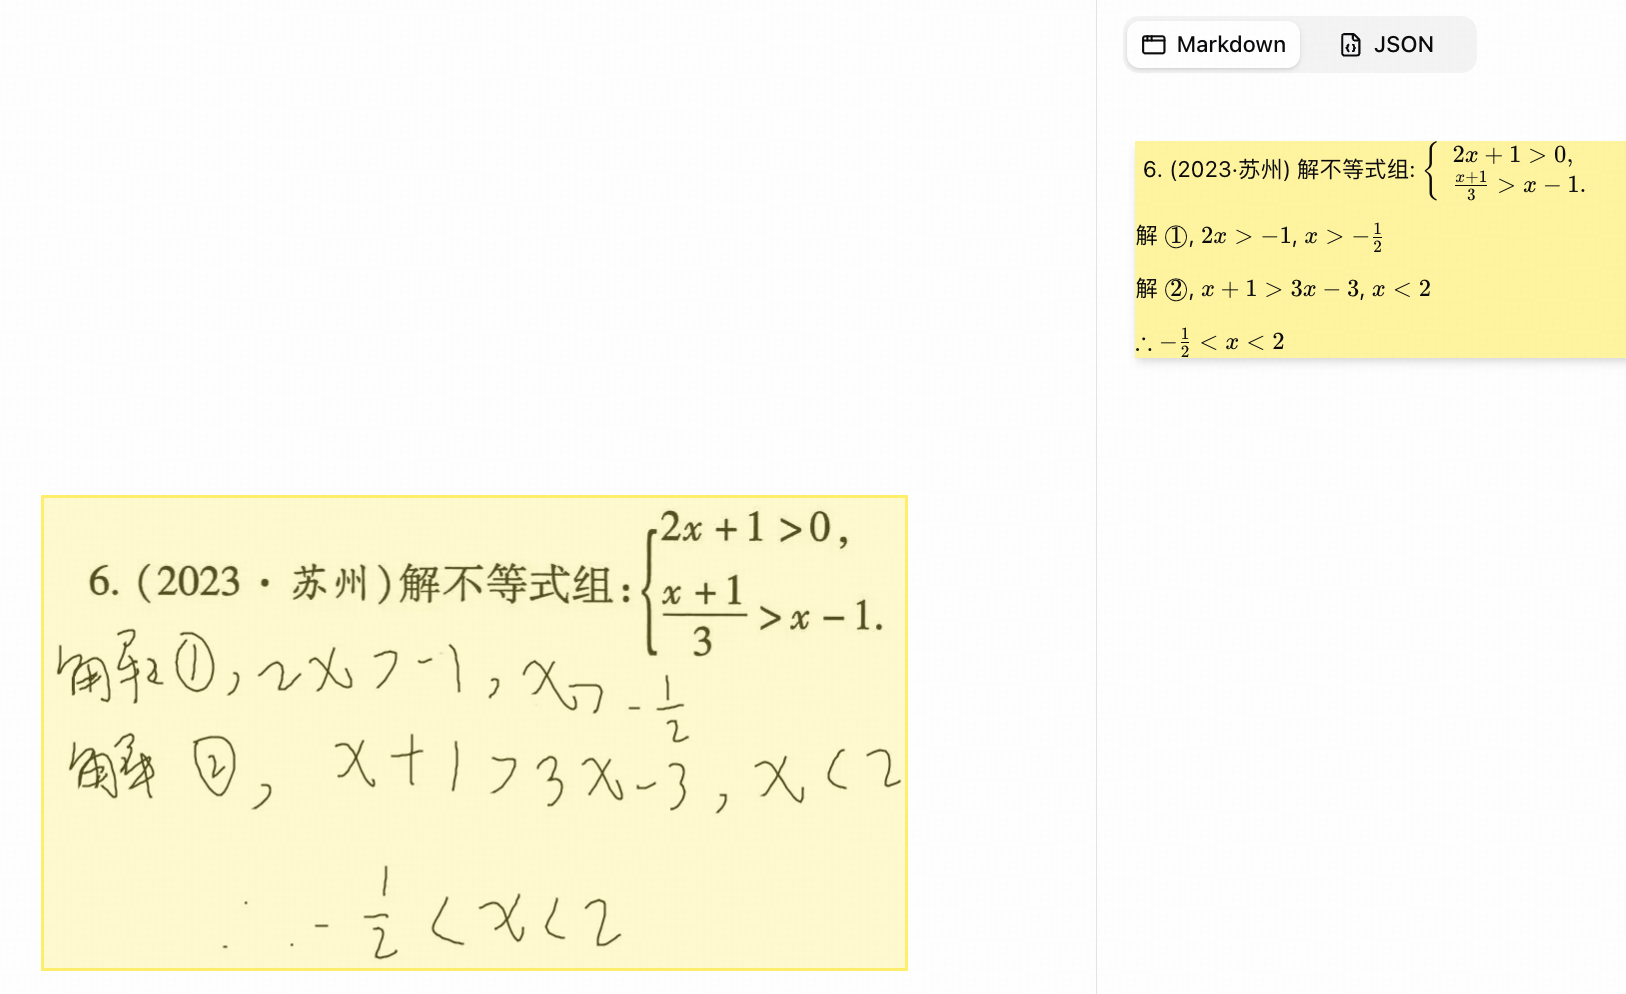
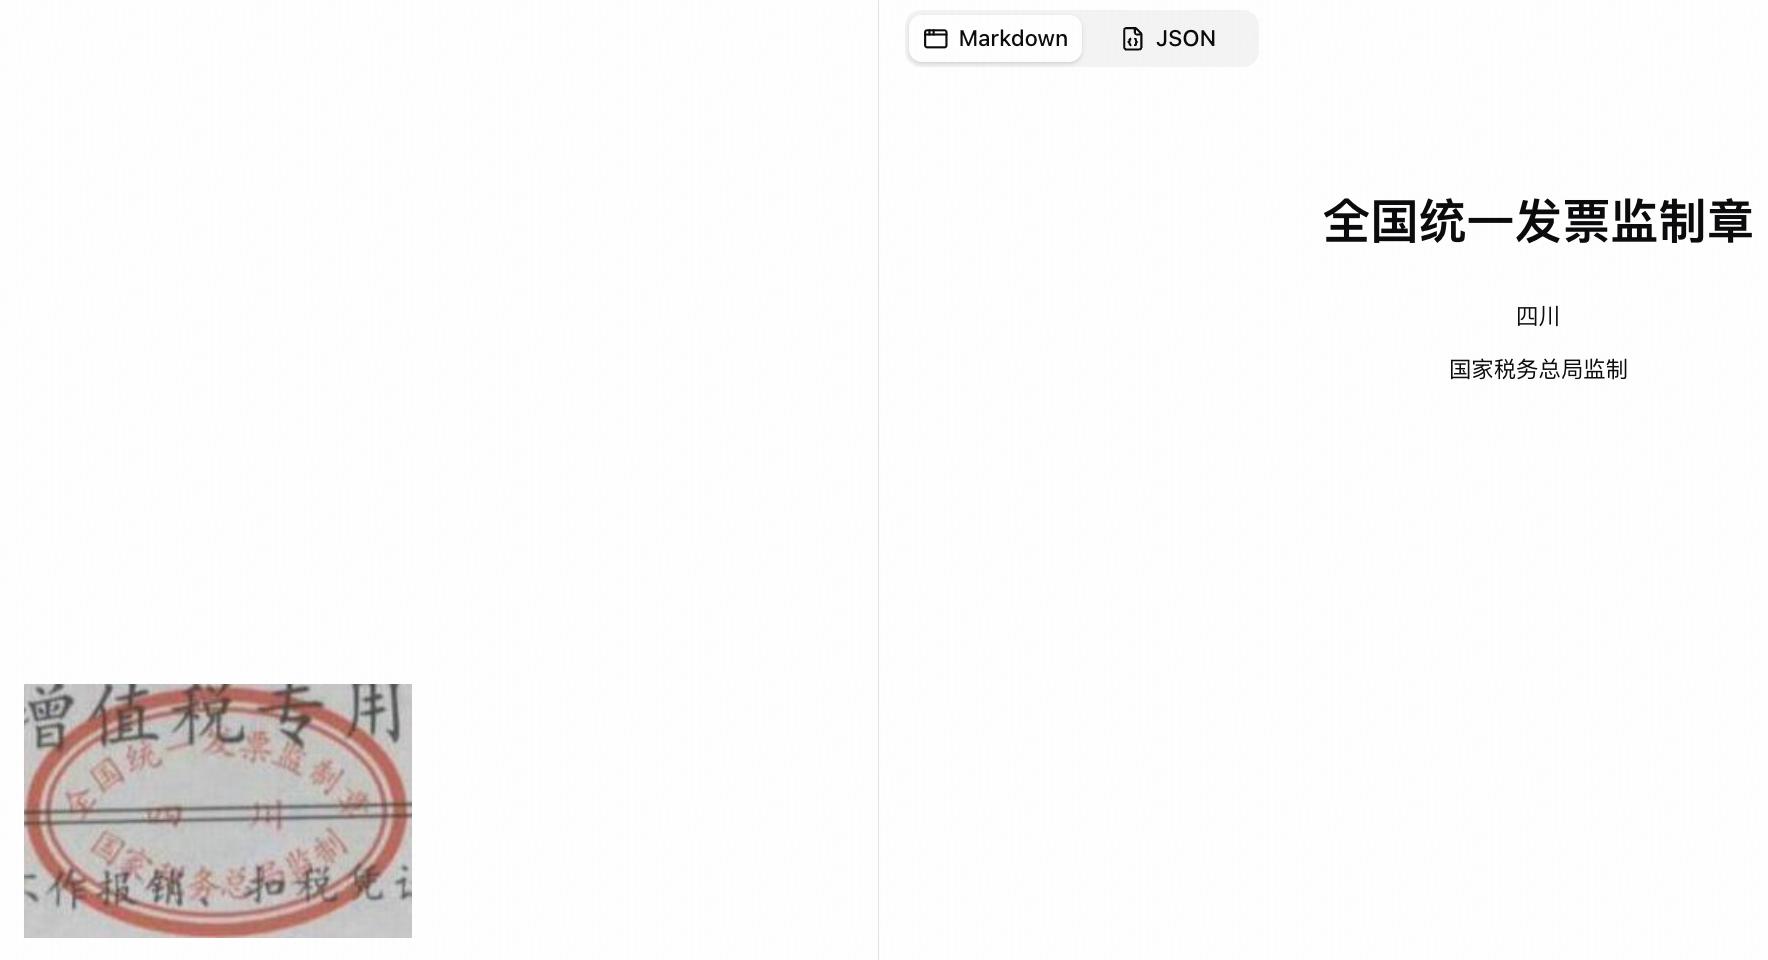
General Text Recognition: GLM-OCR supports inputs from photos, screenshots, scans, and documents. It can recognize special text types such as handwriting, seals, and code, making it widely applicable in education, research, and office scenarios.
Case: Handwritten Formula Recognition
Case: Seal Recognition
Case: Code Recognition
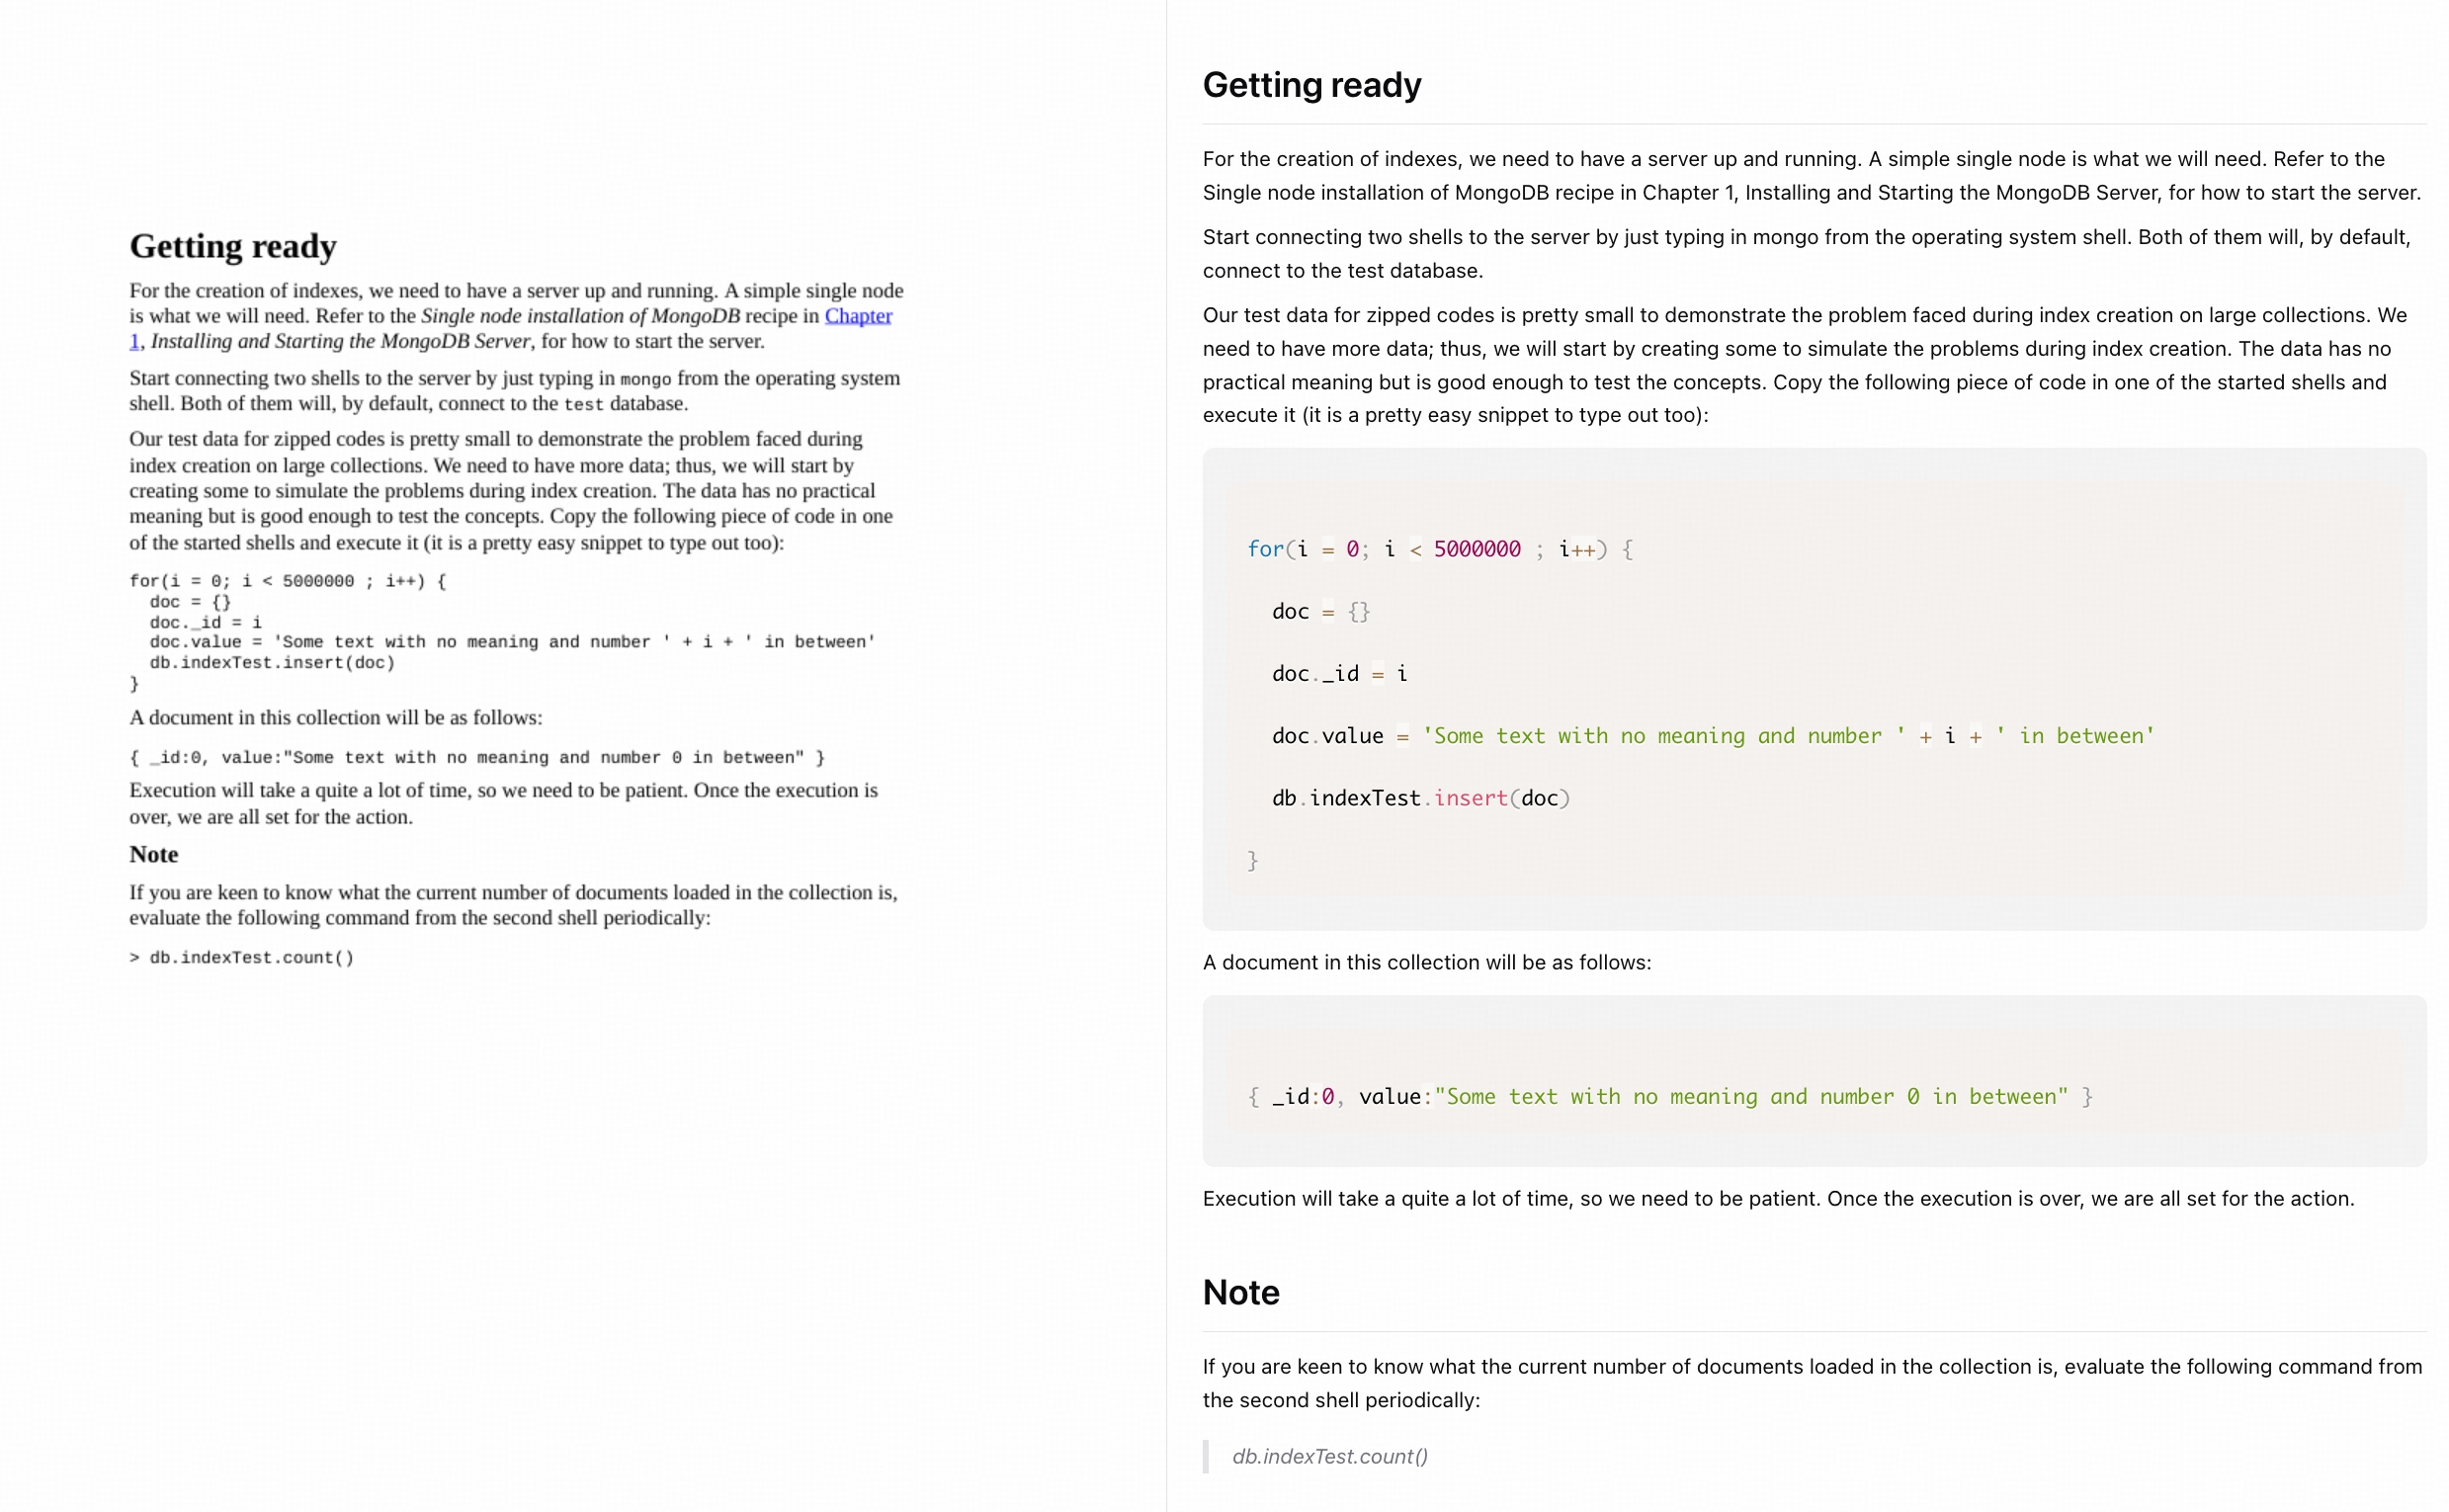
Complex Table Parsing: For complex structures involving merged cells and multi-level headers, the model precisely understands the layout and directly outputs HTML code. No secondary table formatting is required; the recognition results can be immediately used for web display or data processing, greatly improving table entry and conversion efficiency.
Case: Cross-Cell Tables
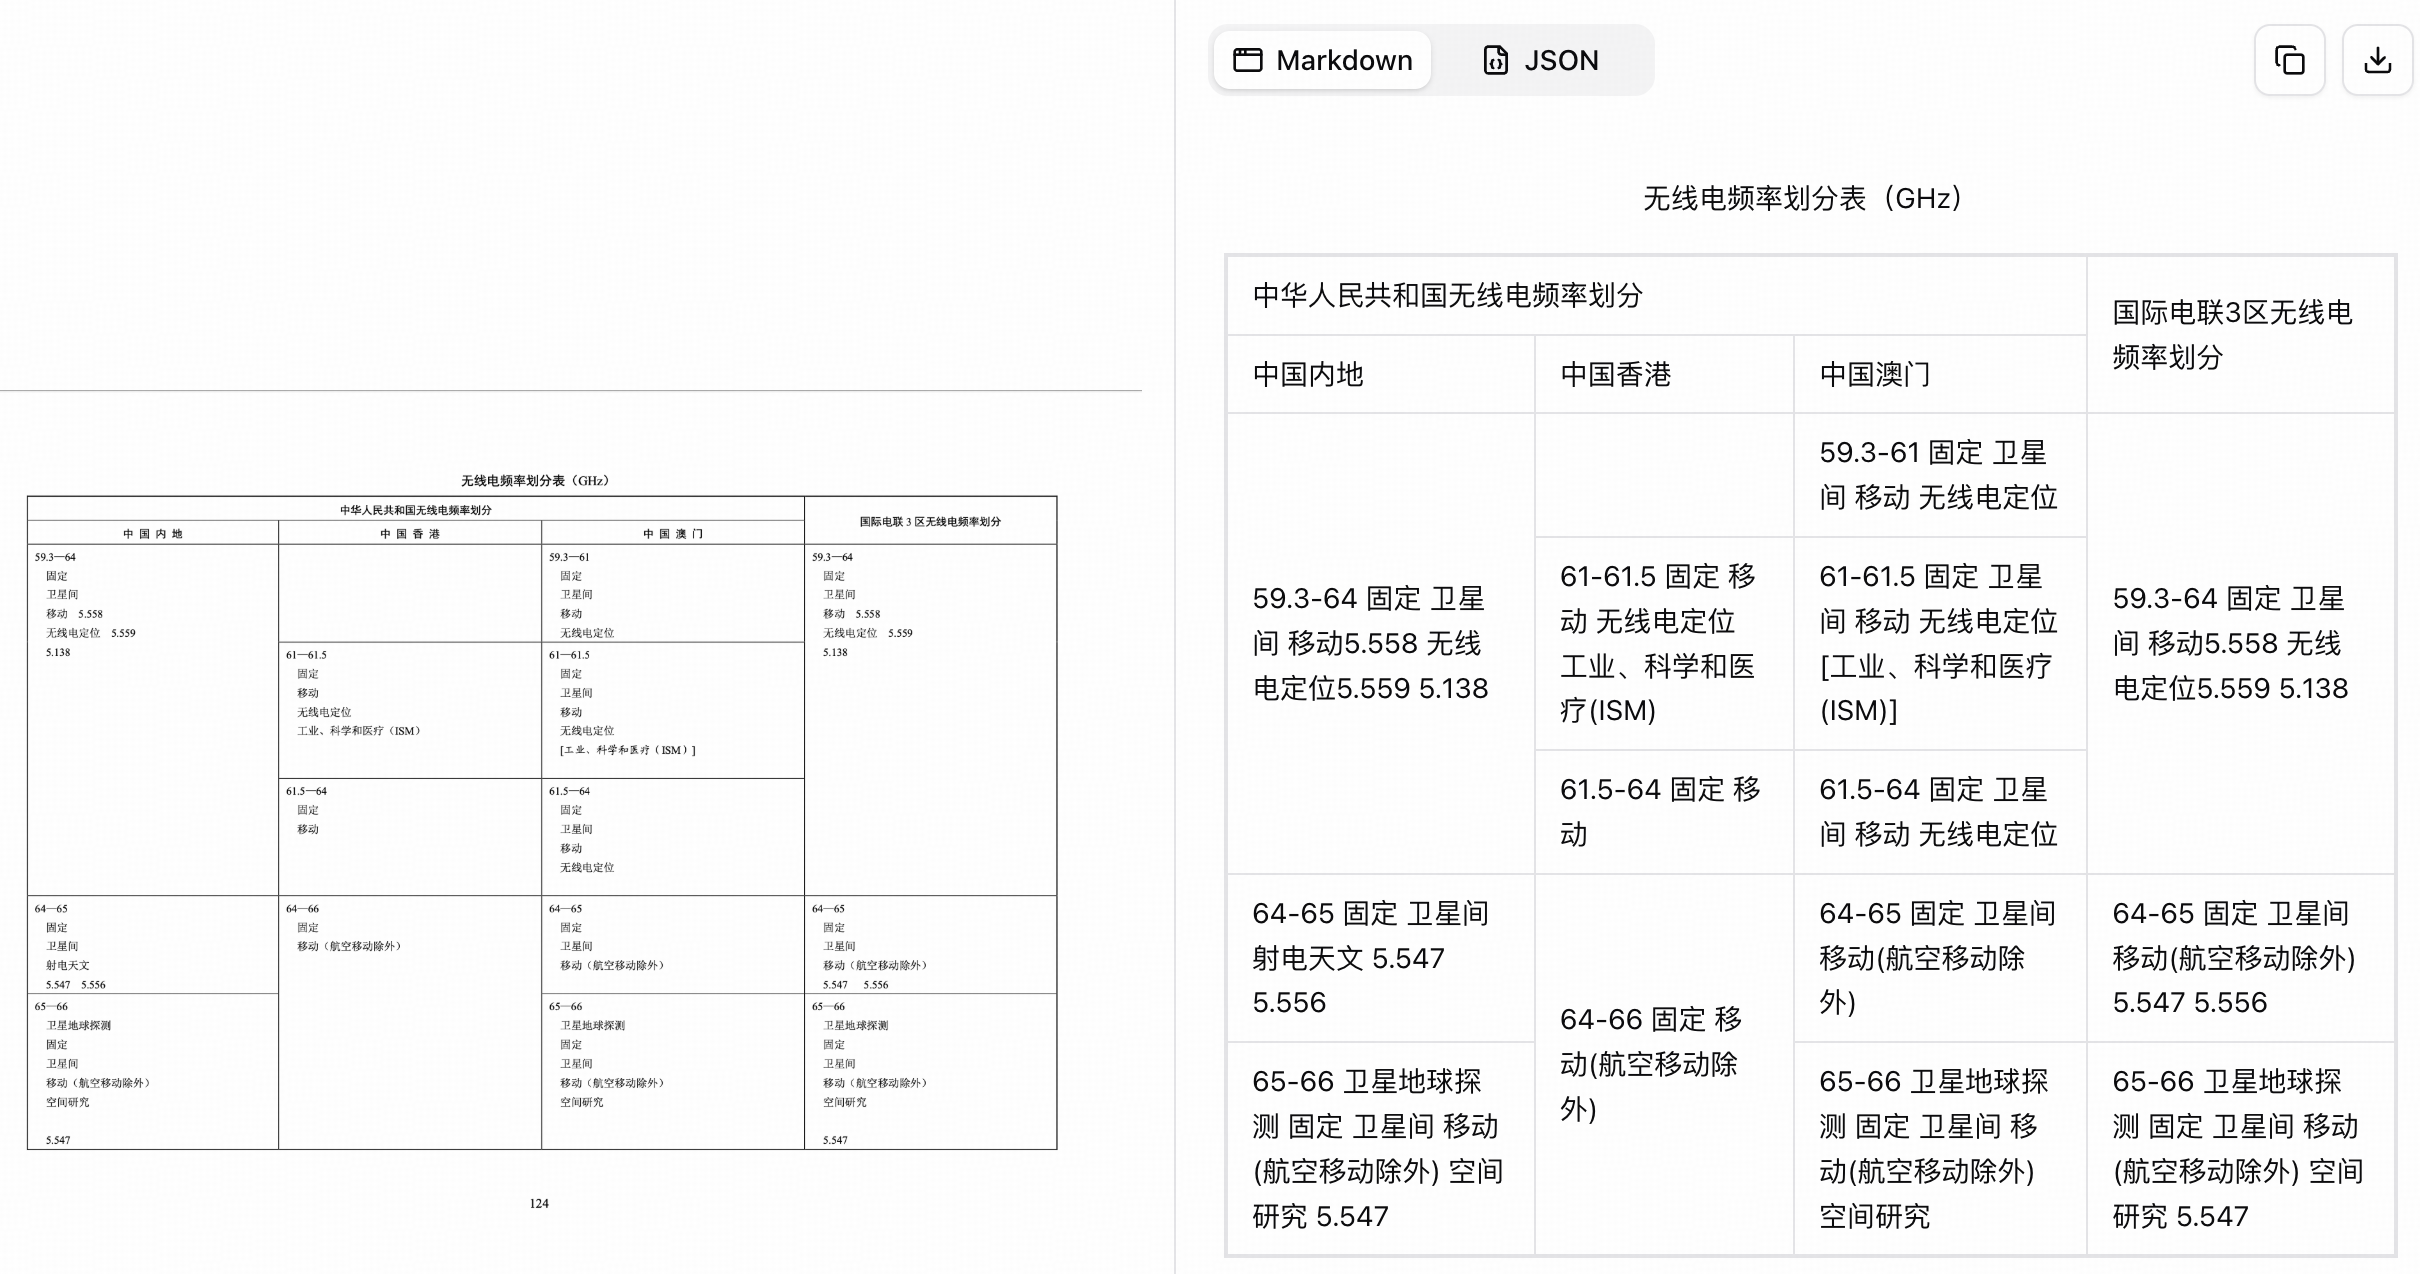
Case: Segmented Tables
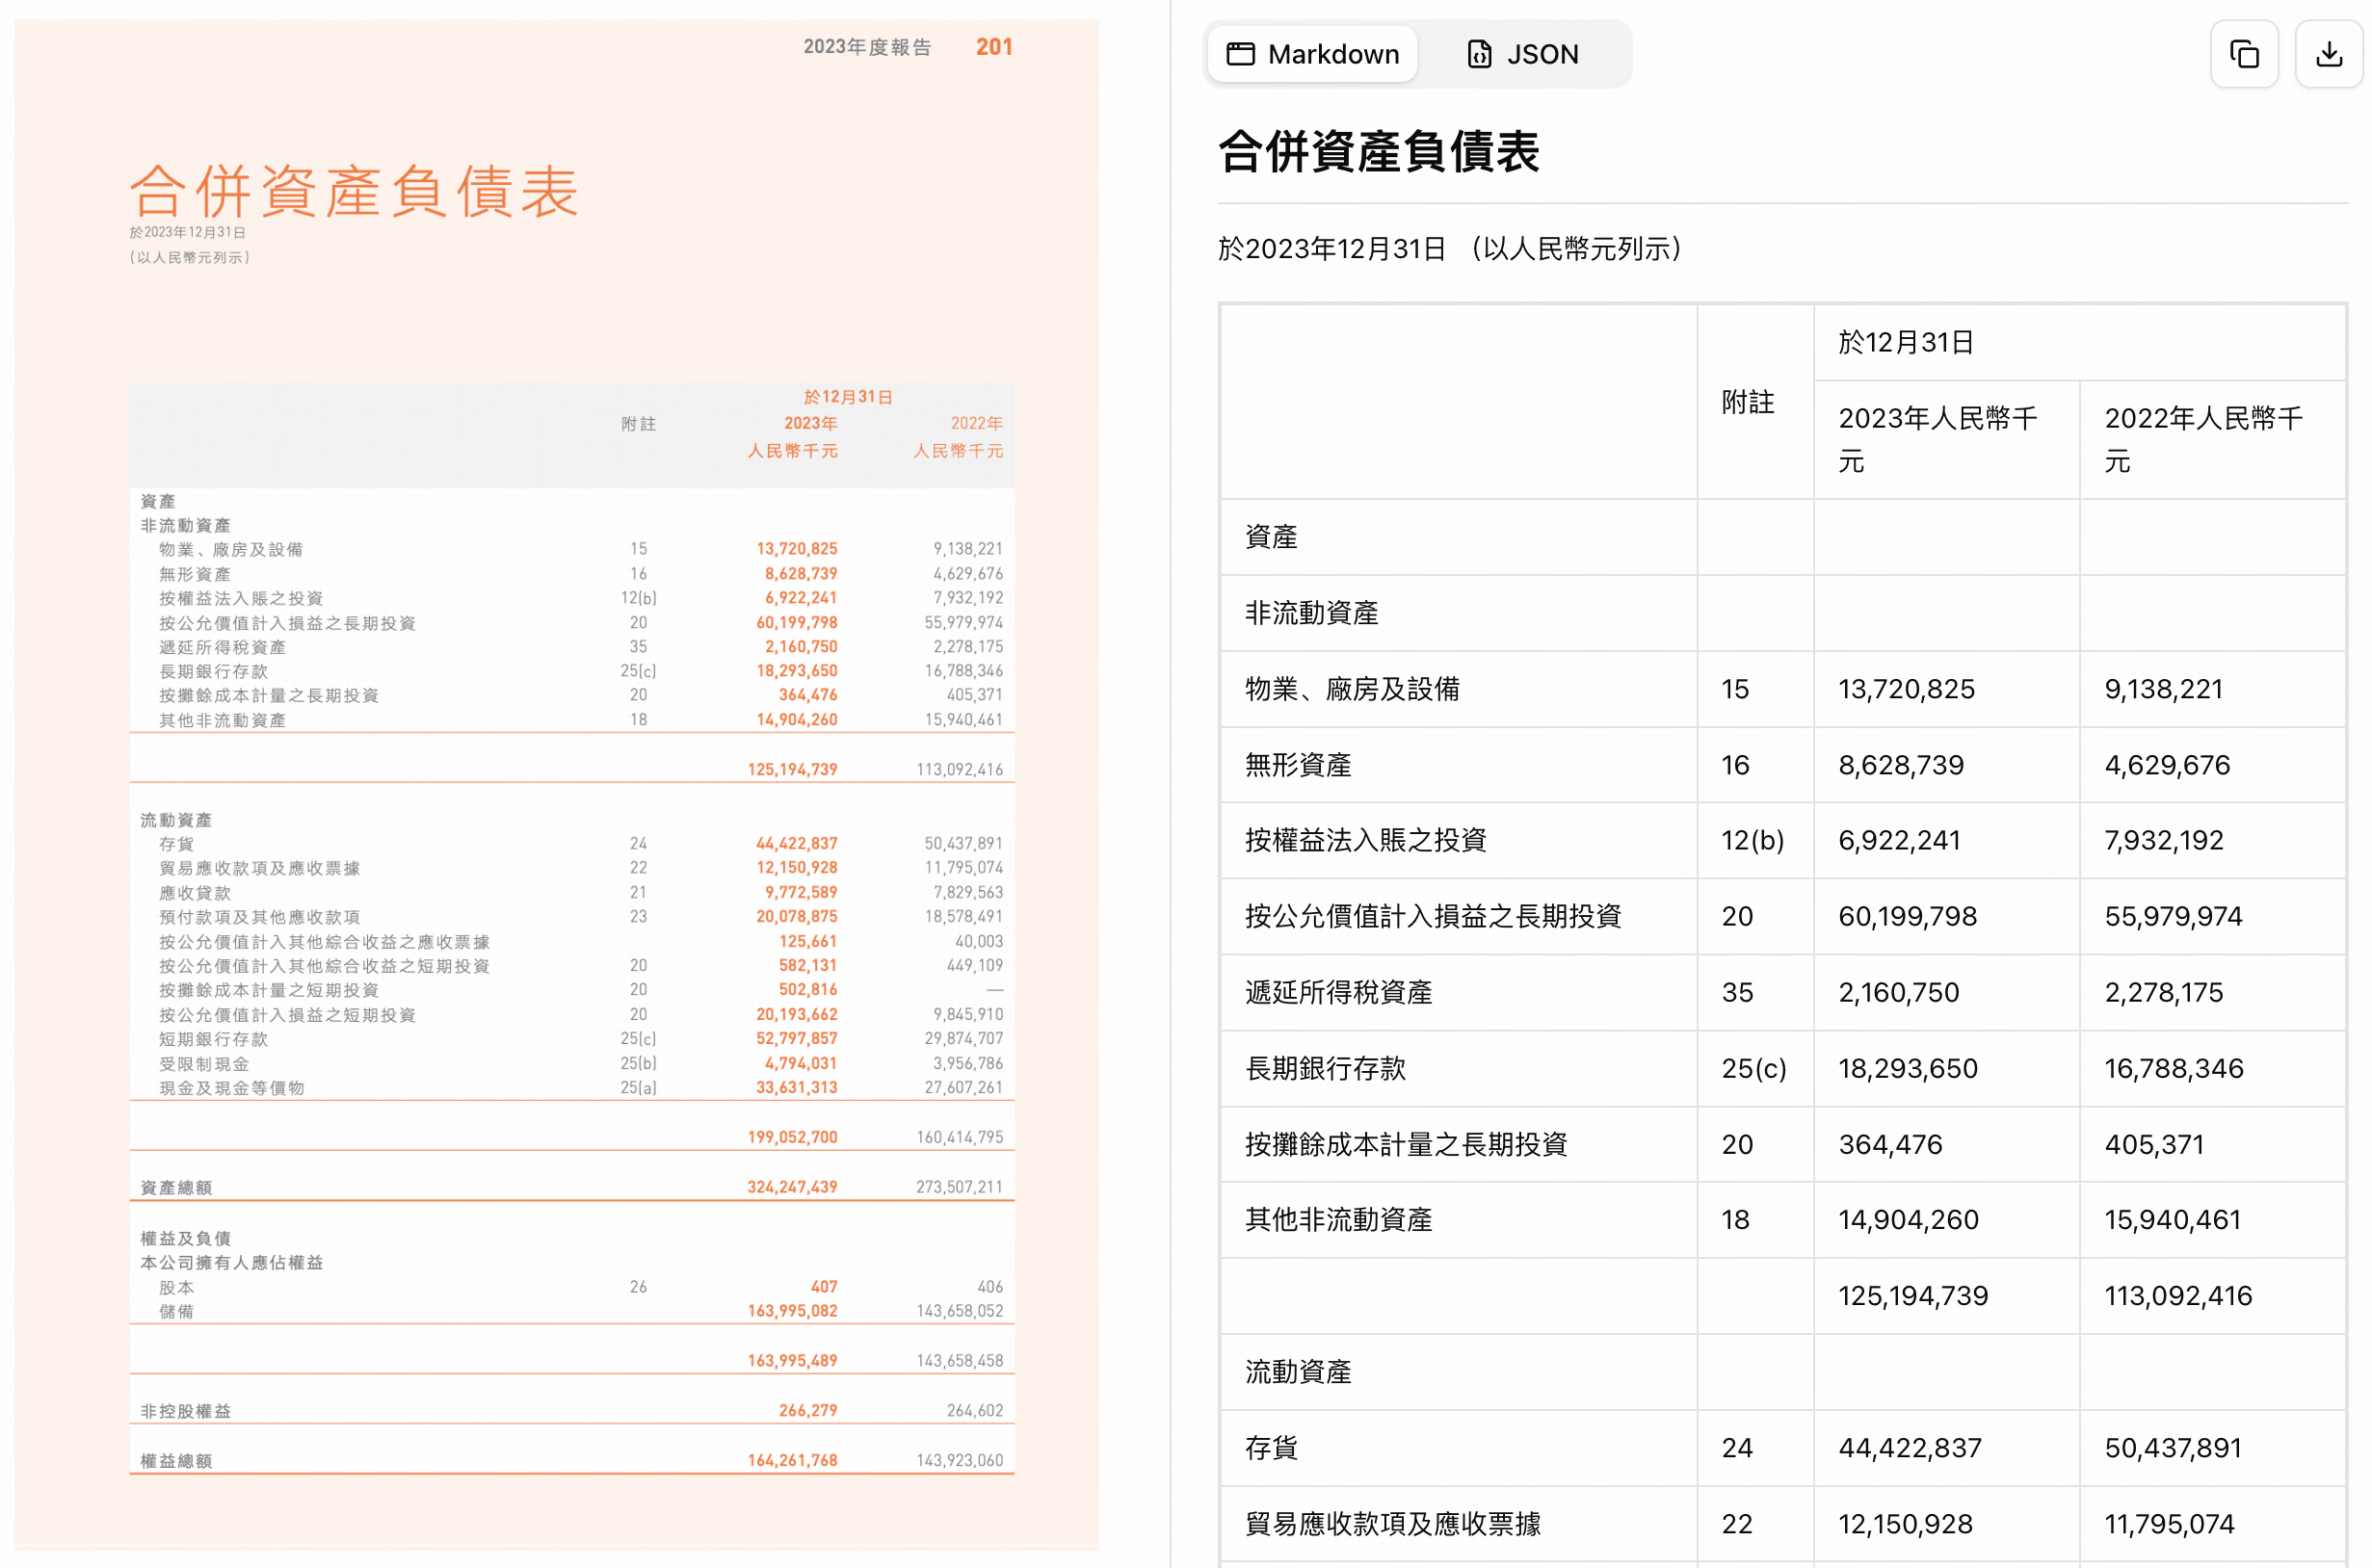
Structured Information Extraction: GLM-OCR intelligently extracts key fields from various cards, certificates, invoices, and tables, outputting standard JSON formats that integrate seamlessly with systems in banking, insurance, logistics, and other industries.
Input Image:

prompt:
Please output the information from the image in the following JSON format:{ "title": "Customs Declaration for Export Goods of the People's Republic of China", "domestic_consignor": { "name":"", "unified_social_credit_code":"", "10_digit_customs_code":"" }, "port_of_exit": "", "export_date": "", "declaration_date": "", "record_number": "", "overseas_consignee": "", "transport_mode": "", "transport_tool_name_and_voyage_number": "", "bill_of_lading_number": "", "production_and_sales_unit": { "name":"", "unified_social_credit_code":"", "10_digit_customs_code":"" }, "supervision_mode": "", "duty_collection_nature": "", "license_number": "", "contract_agreement_number": "", "trading_country_region": "", "country_of_destination_region": "", "port_of_discharge": "", "port_of_departure": "", "package_type": "", "number_of_packages": "", "gross_weight_kg": "", "net_weight_kg": "", "transaction_terms": "", "freight": "", "insurance_premium": "", "miscellaneous_charges": "", "product_information": [{ "item_number": 1, "hs_code": "", "product_name": "", "quantity": "", "unit_price": "", "total_price": "", "currency": "", "country_of_origin_region": "", "final_destination_country_region": "", "domestic_source_location": "", "duty_exemption_status": "", "specifications_model_declaration_elements": "" }, // If there are multiple products, create a new dictionary and continue recording in the list ] }
Output:
{ "title": "Customs Declaration for Export Goods of the People's Republic of China", "domestic_consignor": { "name": "Jiande Jiahong Tools Co., Ltd.", "unified_social_credit_code": "913301827042918701", "10_digit_customs_code": "" }, "port_of_exit": "", "export_date": "", "declaration_date": "", "record_number": "", "overseas_consignee": "ROSS PROCUREMENT, INC.", "transport_mode": "Waterway Transport", "transport_tool_name_and_voyage_number": "", "bill_of_lading_number": "", "production_and_sales_unit": { "name": "Jiande Jiahong Tools Co., Ltd.", "unified_social_credit_code": "913301827042918701", "10_digit_customs_code": "" }, "supervision_mode": "General Trade", "duty_collection_nature": "General Taxation", "license_number": "", "contract_agreement_number": "70037636", "trading_country_region": "United States", "country_of_destination_region": "United States", "port_of_discharge": "United States", "port_of_departure": "Beisanjisi", "package_type": "Carton + Double Blister Pack + Label", "number_of_packages": "300", "gross_weight_kg": "2700.00", "net_weight_kg": "2499.00", "transaction_terms": "FOB", "freight": "", "insurance_premium": "", "miscellaneous_charges": "", "product_information": [ { "item_number": 1, "hs_code": "8205400000 (999)", "product_name": "Screwdriver", "quantity": "1200", "unit_price": "", "total_price": "", "currency": "", "country_of_origin_region": "China", "final_destination_country_region": "United States", "domestic_source_location": "Hangzhou", "duty_exemption_status": "Taxable", "specifications_model_declaration_elements": "" } ] }
Batch Processing and RAG Integration with GLM-OCR
GLM-OCR supports batch processing, enabling developers to efficiently handle large volumes of documents. Combined with Retrieval-Augmented Generation (RAG) technology, it can significantly enhance the accuracy and relevance of document retrieval and generation tasks.
For example, when building an intelligent customer service system, GLM-OCR can first extract key information from user-uploaded documents (such as invoices or contracts), then use this structured data to query relevant knowledge bases via RAG, ultimately providing users with precise answers. This end-to-end solution greatly improves both efficiency and user experience.
Additionally, GLM-OCR offers flexible API interfaces that allow seamless integration into existing workflows. Whether used independently or combined with other AI models, it provides robust support for diverse application scenarios.
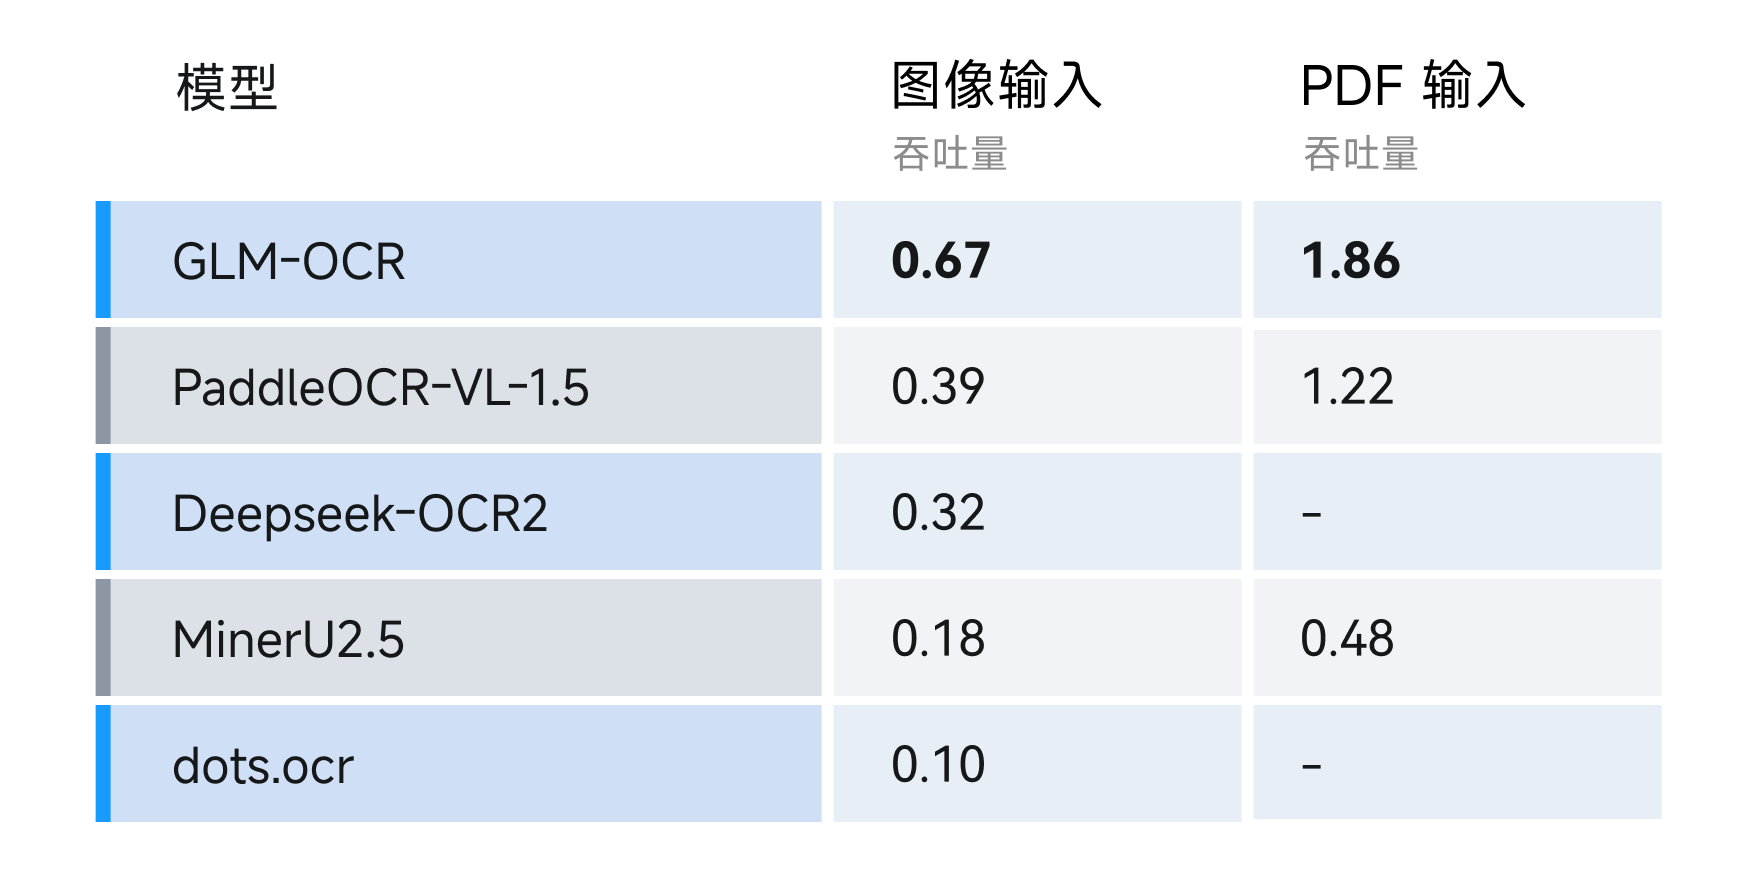
In terms of speed, we compared the parsing and Markdown export speeds of different OCR methods using image files and PDF files as inputs under identical hardware environments and testing conditions (single replica, single concurrency). The results show that GLM-OCR achieves a throughput of 1.86 pages/second for PDF documents and 0.67 images/second, significantly outperforming similar models.
Regarding pricing, API input and output costs are identical at only 0.2 CNY per million Tokens. For just 1 CNY, you can process approximately 2,000 A4-sized scanned images or 200 simple-layout 10-page PDFs, making the cost about 1/10th that of traditional OCR solutions.
## Technical Details
In terms of training strategy, GLM-OCR was the first to introduce Multi-Token Prediction (MTP) loss into the OCR model training process, enhancing loss signal density and improving model learning efficiency. Furthermore, continuous and stable full-task reinforcement learning training significantly boosts the model's overall recognition accuracy and generalization capability in complex document scenarios. These performance improvements also benefit from GLM-OCR's systematic design of its multimodal model architecture. The model adopts an "Encoder-Decoder" architecture inherited from the GLM-V series, comprising three core modules: a visual encoder (ViT), a cross-modal connector layer, and a language decoder. On the visual side, it integrates the proprietary CogViT visual encoder (400M parameters) and employs CLIP strategies for large-scale pretraining on billions of image-text pairs, endowing the model with robust text and layout semantic understanding capabilities. To achieve efficient fusion of visual and linguistic information, GLM-OCR features a lightweight yet highly effective connector structure that incorporates SwiGLU mechanisms and introduces a 4x downsampling strategy. This precisely filters and retains key visual tokens, efficiently transmitting high-density semantic information to the backend GLM-0.5B decoder, thereby supporting high-precision OCR output. At the system level, GLM-OCR utilizes a two-stage technical paradigm: "Layout Analysis → Parallel Recognition." The layout analysis module is based on PP-DocLayout-V3, enabling stable, high-quality, and efficient OCR parsing across diverse layouts and structurally complex documents.
## Open Source and Online Experience
1. Open Source Repositories
- GitHub: [https://github.com/zai-org/GLM-OCR](https://github.com/zai-org/GLM-OCR)
- Hugging Face: [https://huggingface.co/zai-org/GLM-OCR](https://huggingface.co/zai-org/GLM-OCR)
- Huanxin Community: [https://aihuanxin.cn/qdlake/qdh-web/#/model/detail/9745](https://aihuanxin.cn/qdlake/qdh-web/#/model/detail/9745)
2. Model API
- Zhipu AI Open Platform: [https://docs.bigmodel.cn/cn/guide/models/vlm/glm-ocr](https://docs.bigmodel.cn/cn/guide/models/vlm/glm-ocr)
- Special Trial Package Available: Get 50 million Tokens for 2.9 CNY: [https://bigmodel.cn/special_area](https://bigmodel.cn/special_area)
- Z.ai: [https://docs.z.ai/guides/vlm/glm-ocr](https://docs.z.ai/guides/vlm/glm-ocr)
3. Online Demo
- Z.ai: [https://ocr.z.ai](https://ocr.z.ai)
Looking ahead, we will continue to iterate on GLM-OCR, release versions of various sizes, and extend capabilities to support more languages and video OCR, comprehensively broadening the application boundaries of visual intelligence.