Ant Group Releases Ling 3.2 Flash Multimodal Model, Topping Claude Opus 5 on Three Benchmarks
Ant Group's Ling team released Ling-3.2-flash, a natively multimodal model built on a 560B-total / ~25B-active MoE architecture with a 1M context window and image, text and video input. In vendor-run tests it beats Claude Opus 5 on OmniDocBench1.5, ZEROBench and Vision2Web, and enters the DesignArena image-to-frontend top ten at 1238 Elo. API pricing is $0.30 per million input tokens and $0.90 per million output tokens, compatible with OpenAI and Anthropic protocols, and free for the first two weeks.
Full Report
IT之家 November 6 news, the Ant Ling official team announced today the launch of the native multimodal model Ling-3.2-flash, featuring 560B total parameters, 25B activated parameters, and a 1M context window.
The model natively integrates vision and language capabilities at the architectural level, supports image, text, and video inputs, and focuses on strengthening four major capabilities: complex visual understanding, multimodal long-horizon Agent, 3D understanding and interaction, and medical multimodality.
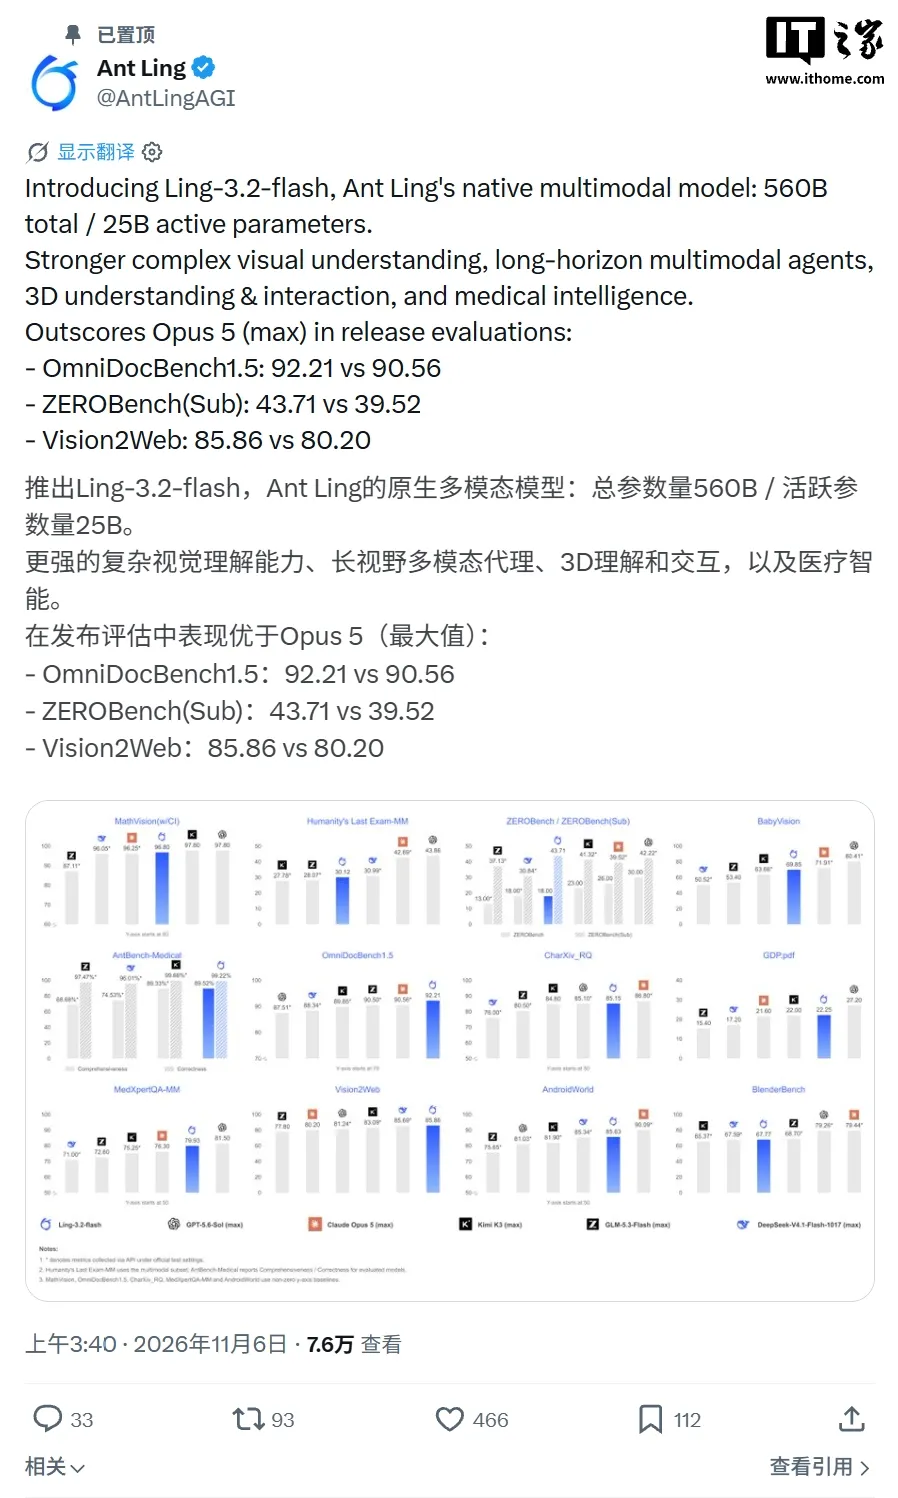
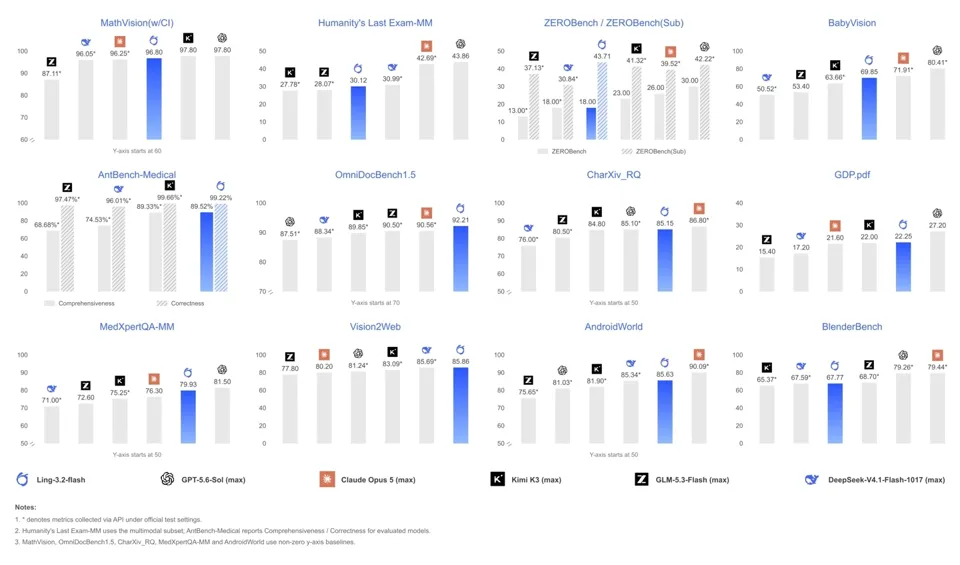
In the evaluation results published by Ant officially, Ling-3.2-flash surpasses Anthropic Claude Opus 5 (max) on three benchmarks:
- OmniDocBench1.5 score 92.21, versus 90.56;
- ZEROBench (Sub) score 43.71, versus 39.52;
- Vision2Web score 85.86, versus 80.20.
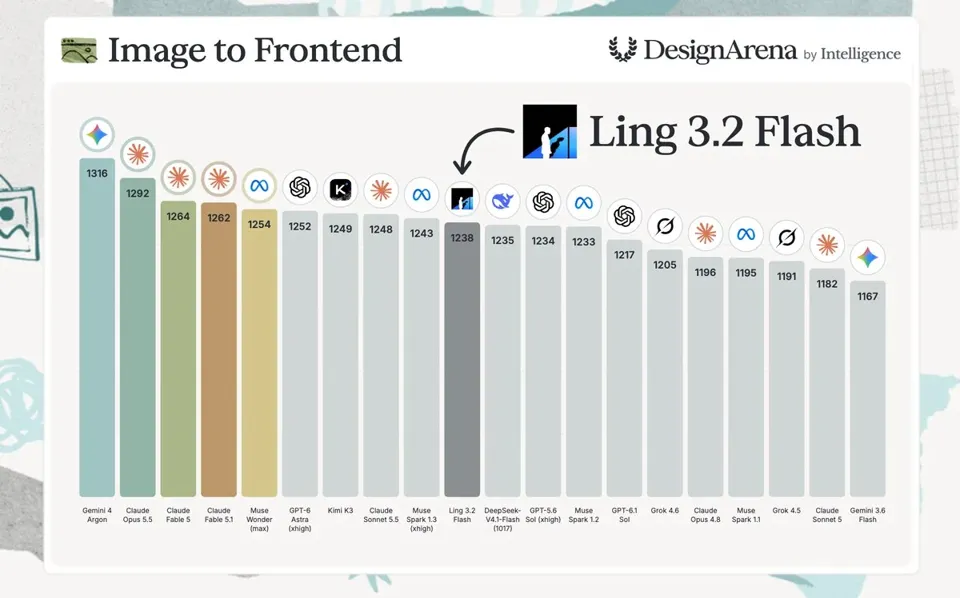
In the DesignArena image-to-frontend arena, the model entered the top ten with an Elo score of 1238, tied with competitors such as Meta, DeepSeek, and Anthropic.
The model focuses on strengthening four major capabilities: complex visual understanding targets deep reasoning and analysis of images and videos; multimodal long-horizon Agent requires maintaining goal consistency across multi-step tasks and completing decision-making and execution based on visual and textual information; 3D understanding and interaction focuses on parsing three-dimensional scenes and spatial relationships; medical multimodality covers medical image understanding and report interpretation, assisting professional medical analysis.
According to the introduction, the combination of 560B total parameters and approximately 25B activated parameters is the core trade-off of Ling-3.2-flash between capability and inference cost. This pattern typically corresponds to a Mixture-of-Experts (MoE) architecture, where the model invokes only part of its parameters in each forward computation, thereby controlling per-step computation cost while retaining large-capacity knowledge storage.
In terms of pricing, Ling-3.2-flash's API input price is $0.30 per million tokens (IT之家 note: approximately 2 RMB at current exchange rates), and the output price is $0.90 per million tokens (approximately 6 RMB at current exchange rates). The DesignArena leaderboard notes that this is the lowest rate among models of the same performance tier.
Its API has been launched through the Ant Bailian platform. Interested users can experience it online through the chat page, and it is compatible with the OpenAI and Anthropic protocols for API calls. In addition, it is free to experience for a limited time during the first 2 weeks after launch.