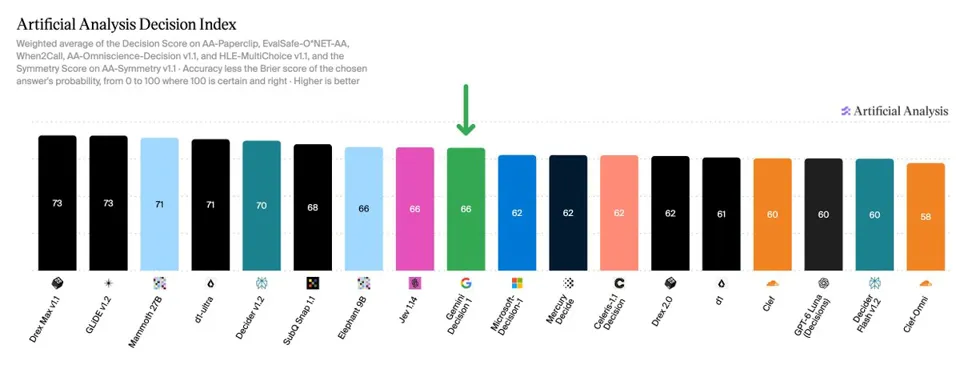
Google Releases First Decision Model Gemini Decision 1 Scoring 66
Google DeepMind has released Gemini Decision 1, its first decision model, scoring 66 on the Artificial Analysis Decision Index v2.1, level with Elephant 9B and Jev 1.14 but 7 points behind leaders Drex Max v1.1 and GLiDE v1.2. It leads knowledge and reasoning benchmarks yet costs about $345 per 1M tasks, over three times Drex Max v1.1, and trails on the new AA-Paperclip classification and extraction benchmark.
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-11 18
Google has released its first decision model, Gemini Decision 1, scoring 66 on the Artificial Analysis Decision Index and leading in knowledge and reasoning benchmarks
Gemini Decision 1 from @GoogleDeepMind scores 66 on the Artificial Analysis Decision Index v2.1, in line with Elephant 9B (@baselabs) and Jev 1.14 (@typesafeai), and 7 points behind leaders Drex Max v1.1 (@NaceAI) and GLiDE v1.2 (@fastinoAI), which both score 73. It is priced at $0.10 per 1M input tokens and costs $345 per 1M Tasks across the Index, around three times higher than Drex Max v1.1 ($103) due to its higher pricing
Key results for Gemini Decision 1:
➤ Not yet frontier on Decision Index: Gemini Decision 1 scores 66 on the Artificial Analysis Decision Index. It leads knowledge and reasoning benchmarks, scoring 66 on AA-Omniscience-Decision and 49 on HLE-MultiChoice. It trails on other evaluations, including our new proprietary classification and extraction benchmark AA-Paperclip, where it answers all 15 questions correctly on 33% of documents vs. 63% for Drex Max v1.1
➤ More than 3x the Cost per Task of leading models: Gemini Decision 1 costs $345 per 1M Tasks, compared with $103 for Drex Max v1.1, $156 for Jev 1.14. This difference is driven by its token price of $0.10 per 1M input tokens vs. $0.03 for Drex Max v1.1. Gemini Decision 1 has a similar Cost per 1M Tasks to GPT-6 Luna (Decisions, $339)
➤ Strong calibration for reasoning tasks: We measure calibration with the Brier score, the average squared gap between the probability a model assigns to its chosen answer and whether that answer was correct (lower is better). Gemini Decision 1 has a Brier score of 0.18 across the Index, between Drex Max v1.1 (0.16) and Jev 1.14 (0.19). Calibration varies by task. with its Brier score of 0.20 on HLE-MultiChoice among the lowest of all models in the Index, while its 0.14 on When2Call compares with 0.04 for Drex Max v1.1