Mistral Opens Weights for 1T-Param Large 4, Cutting Coding Agent Tokens by 47%
Mistral AI has released the weights for Mistral Large 4 (ML4), a 1-trillion parameter native multimodal MoE model. It matches leading open-source models on coding agent benchmarks while reducing average token consumption per task by 47%, significantly optimizing inference costs.
Related Entities
Full Report
IT Home reported on October 30 that, on October 29 local time, the French company Mistral AI officially released the model weights for Mistral Large 4 (abbreviated as ML4, codename "le Chonk").
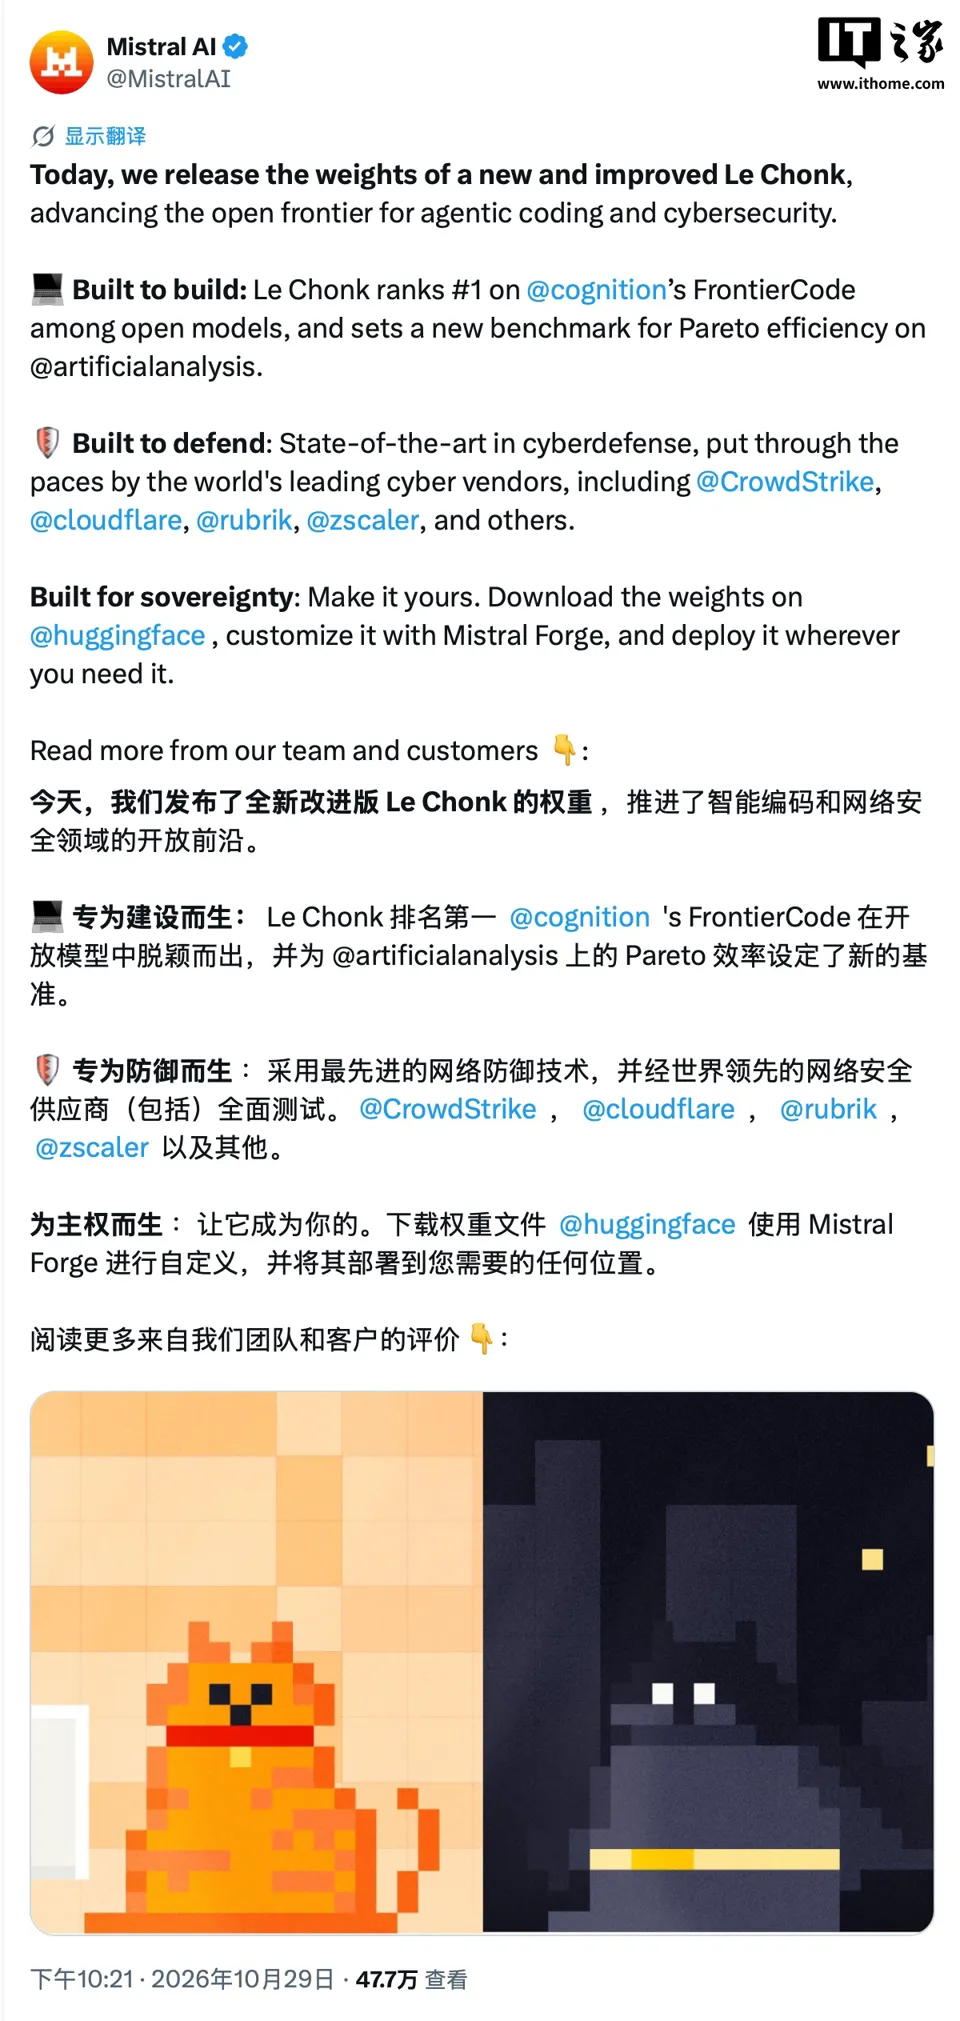
ML4 is a native multimodal model with 1 trillion total parameters and 49 billion active parameters (52 billion including embedding and output layers). It was trained from scratch using 3,800 NVIDIA Grace Blackwell GPUs at Mistral's own data centers in Europe.
Mistral stated that this release version has undergone performance optimization and upgrades compared to the initial version announced three weeks ago, following real-world testing with government and enterprise users.
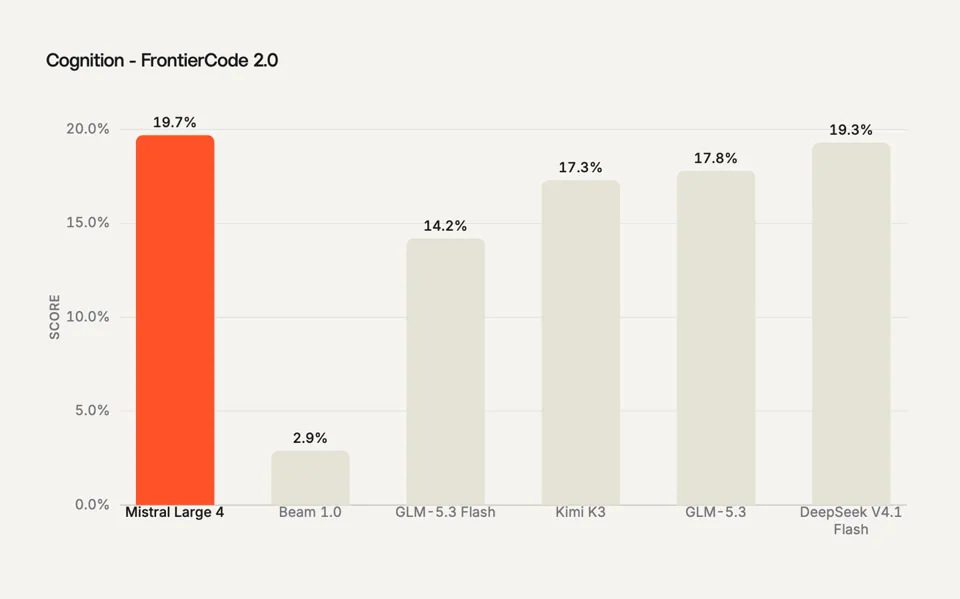
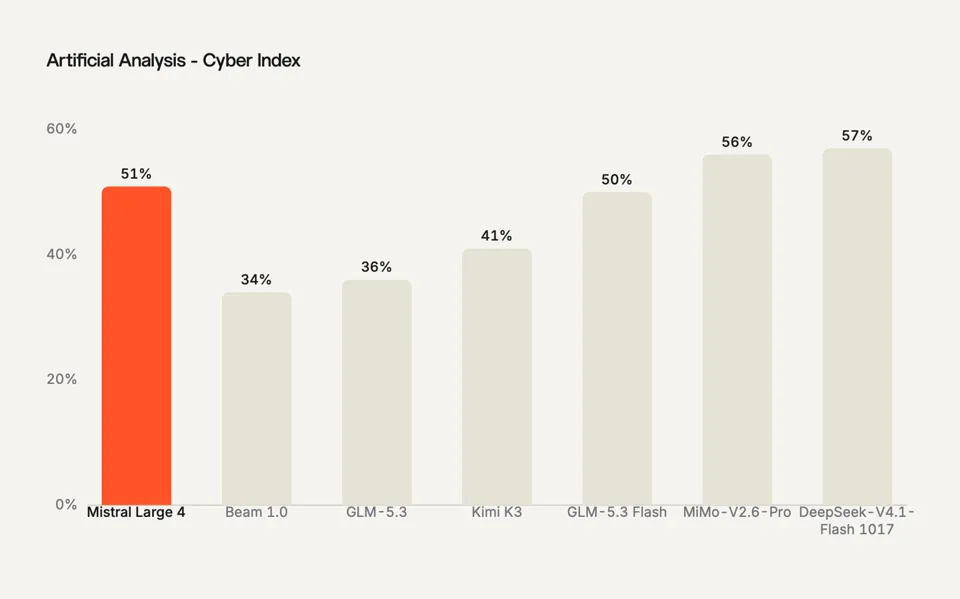
According to official statements, the model achieved a score of 48% on the Artificial Analysis Coding Agent Index, roughly matching the leading open-source model GLM-5.3, while reducing the average number of tokens consumed per task by 47%.



For online usage, the model is priced as follows: $0.70 per million input tokens (Note from IT Home: approximately 4.7 RMB at current exchange rates), $0.07 per million cached input tokens (approximately 0.47 RMB), and $2.10 per million output tokens (approximately 14 RMB).
The model is released under a modified MIT License, allowing free use for personal, academic, modification, fine-tuning, and general commercial purposes. Cloud service providers or vendors offering MaaS (Model-as-a-Service) for resale must obtain separate commercial authorization from Mistral before commercial use.
Open-source links provided by IT Home:
- Hugging Face: https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B
Advertisement Disclaimer: External redirect links contained in this article (including but not limited to hyperlinks, QR codes, passcodes, etc.) are intended to provide additional information and save selection time. Results are for reference only. All IT Home articles containing external links include this disclaimer.