Zyphra Open-Sources 800M Speech Model for Real-Time Voice Cloning on Phones
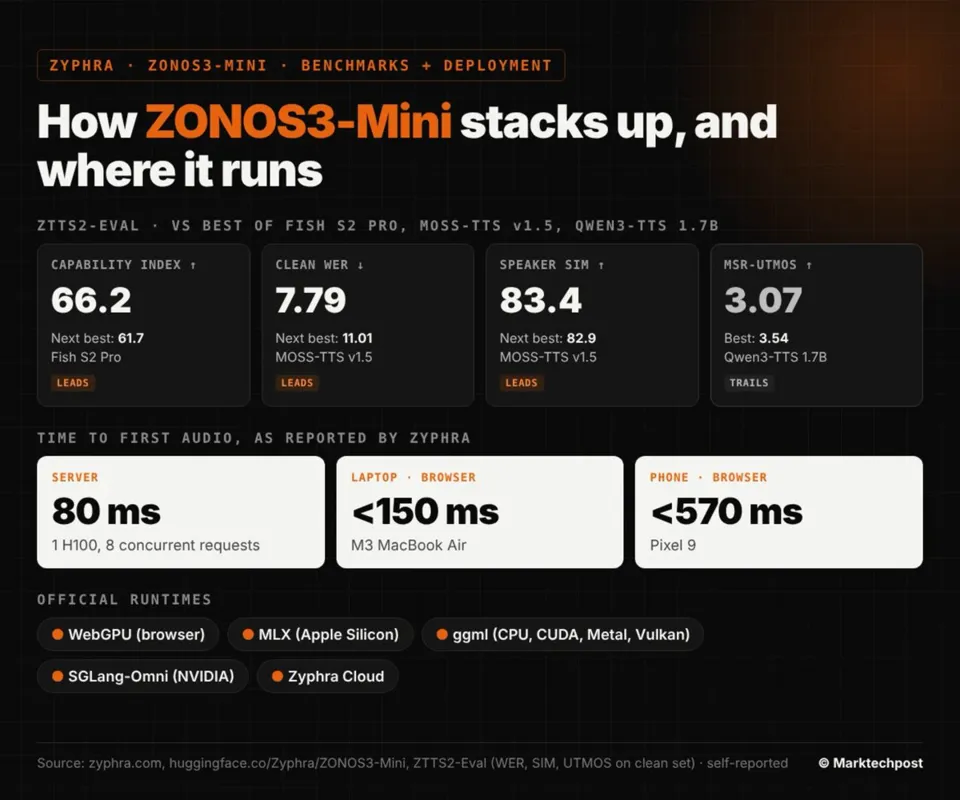
Zyphra has open-sourced ZONOS3-Mini under Apache 2.0, a text-to-speech model built on a sparse Mixture-of-Experts design with 800M total parameters and roughly 100M active per token, paired with a new 15 Hz codec (ZAC-1) that cuts the number of frames to generate, enabling real-time operation on phones and laptops. On Zyphra's own ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2), with clean-set WER of 7.79 and 80 ms time to first audio on a single H100; reference-clip cloning, however, drops to 44.7 on the same index, and all results come from the vendor's own benchmark.
Related Entities
Full Report
▲ Marktechpost AI · 2026-11-10 15
▲ Zyphra just open-sourced ZONOS3-Mini, a text-to-speech model that clones voices and runs in real time on a phone or laptop.
The key idea is sparsity. It is a Mixture of Experts with 800M total parameters, but only about 100M are active per token. A new 15 Hz codec (ZAC-1) cuts the number of frames the model has to generate.
On Zyphra's ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2). Clean-set WER is 7.79 vs 11.06 for Fish S2 Pro. Time to first audio is 80 ms on 1 H100. It is a trade-off though: all of this is Zyphra's own benchmark, and reference-clip cloning drops to 44.7 on the same index.
Weights are Apache 2.0. Runtimes cover WebGPU in the browser, MLX, ggml and SGLang-Omni, plus a hosted API on Zyphra Cloud......
Full analysis: