Zyphra 开源 8 亿参数语音模型 手机端实时克隆音色
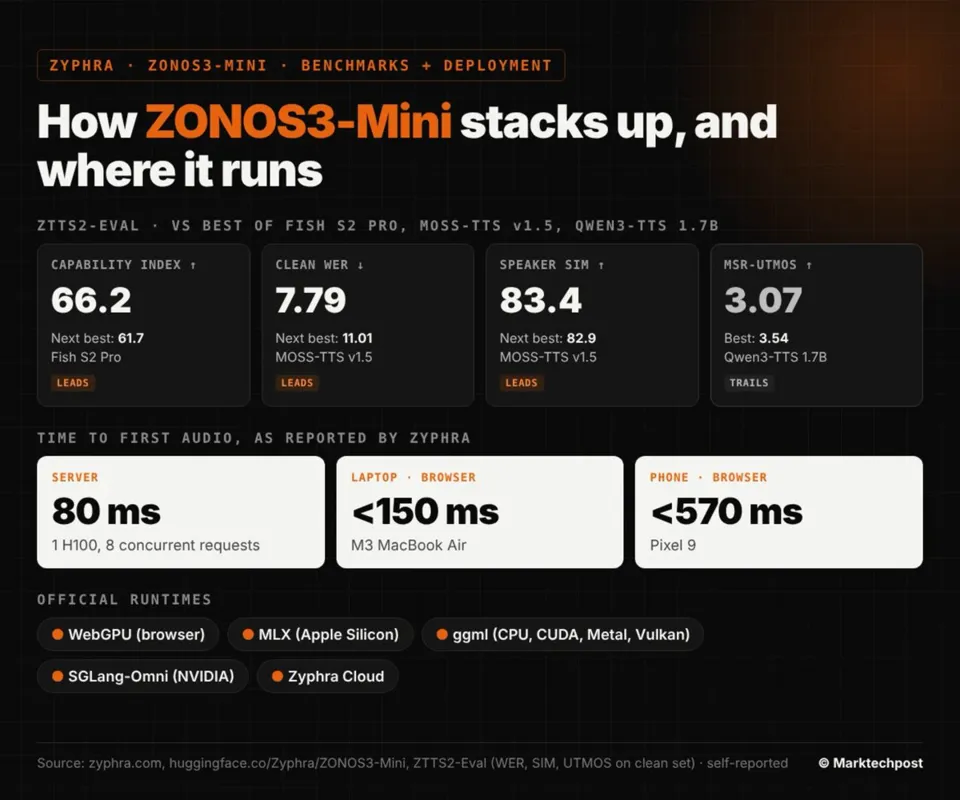
Zyphra 以 Apache 2.0 协议开源 ZONOS3-Mini 文本转语音模型,采用总参数 8 亿、每 token 仅激活约 1 亿的稀疏混合专家架构,配合自研 15 Hz 编解码器 ZAC-1 降低生成帧数,可在手机与笔记本上实时运行。在厂商自建 ZTTS2-Eval 上能力指数 66.2,领先 Fish Audio S2 Pro 与 MOSS-TTS v1.5,干净集 WER 为 7.79,单张 H100 首字音频延迟 80 ms;但参考音频克隆场景得分降至 44.7,且全部数据来自自家基准。
报道正文
▲ Marktechpost AI · 2026-11-10 15
▲ Zyphra just open-sourced ZONOS3-Mini, a text-to-speech model that clones voices and runs in real time on a phone or laptop.
The key idea is sparsity. It is a Mixture of Experts with 800M total parameters, but only about 100M are active per token. A new 15 Hz codec (ZAC-1) cuts the number of frames the model has to generate.
On Zyphra's ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2). Clean-set WER is 7.79 vs 11.06 for Fish S2 Pro. Time to first audio is 80 ms on 1 H100. It is a trade-off though: all of this is Zyphra's own benchmark, and reference-clip cloning drops to 44.7 on the same index.
Weights are Apache 2.0. Runtimes cover WebGPU in the browser, MLX, ggml and SGLang-Omni, plus a hosted API on Zyphra Cloud......
Full analysis: