WisprFlow Debuts In-House Speech Model Canto 1 at 3.4% WER
Speech-input startup WisprFlow has hired Ariya Rastrow, a founding Alexa scientist, as chief science officer and shifted from rented speech engines to training its own models. Its first in-house model, Canto 1, was trained on noisy real-world dictation and posted a 3.4% word error rate across roughly 10 hours of real Flow dictations from over 2,300 speakers, beating every competing model Wispr tested while cutting dictations that take over a second to appear by 54%.
Related Entities
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-15 21
The keyboard was a workaround for machines that couldn’t hear. Machines that hear make it optional.
WisprFlow recently hired Ariya Rastrow (founding Alexa scientist) as chief science officer and moved from rented speech engines to models it trains itself.
Hard to find a better fit for a speech lab than someone who scaled Alexa’s speech team.
Canto 1, his lab’s first model, was built to cut how often people edit dictated text, so Wispr trained it on noisy real-world dictations and tuned it to each user’s vocabulary and names.
And this is a hard test, unlike many, because Speech recognition was long tested on clean, read-aloud audio, but the hard problem is a cheap laptop mic in a room where someone else is talking.
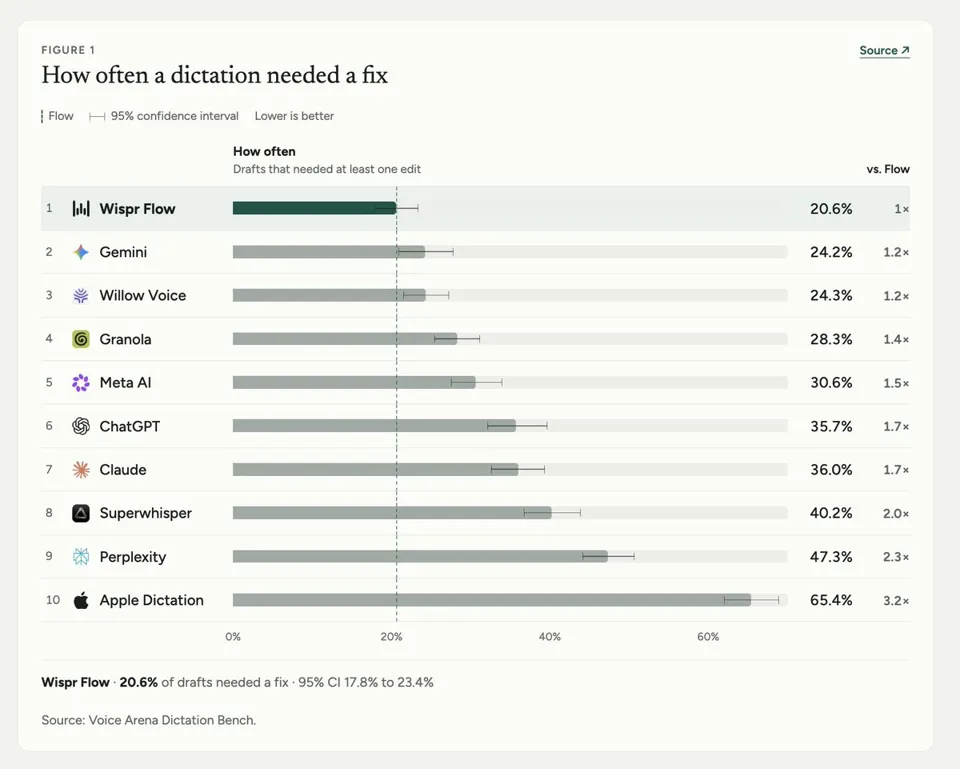
On about 10 hours of real Flow dictations from more than 2,300 speakers, it posted a 3.4% word error rate, lower than all competing models that Wispr tested.
Typing gives you feedback on every keystroke, while speech makes you wait until the end of a sentence to see what the machine heard, so speed counts as much as accuracy.
Since launch, dictations that take more than 1 second to appear are down 54%.
Its training runs through pretraining, supervised fine-tuning and reinforcement learning with GRPO, the same stages used for large language models.
The reinforcement learning stage uses corrections from Flow users who opted in to share data.
When someone fixes a dictated word, Wispr checks how the audio aligns with the text and how the edit is shaped.
A misheard word gets folded back into the training reference, and a plain rewrite of the sentence gets ignored.