Artificial Analysis (@ArtificialAnlys) · 10/16/2026, 08:41:11
Meta Releases Muse Spark Open: 816B MoE Model Tops US Open-Weights Leaderboard with Multimodal Input
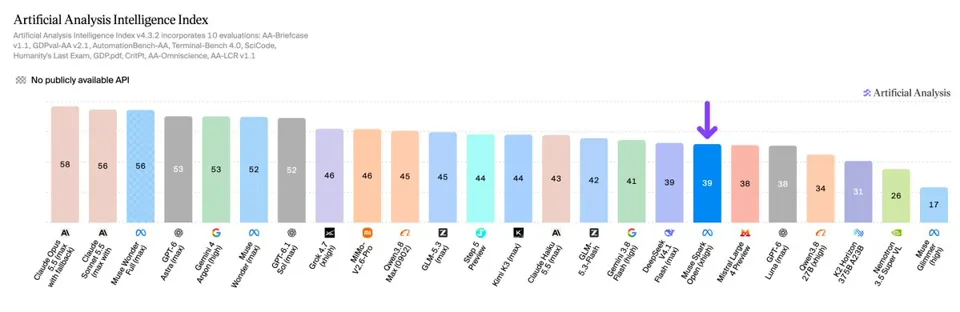
Meta has released Muse Spark Open, an 816B-parameter (42B active) open-weights model that scores 39 on the Artificial Analysis Intelligence Index, surpassing NVIDIA's Nemotron to become the top US open-weights model. The model supports multimodal inputs (text, image, video, audio), offers high token efficiency with only 40k output tokens per task, and demonstrates reduced hallucination rates alongside improved performance on automation benchmarks. Weights are available on Hugging Face, with API access provided through major inference platforms.
SOURCE COVERAGEFull Original Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-16 00
Meta has released Muse Spark Open, an 816B (42B active) open-weights model that scores 39 on the Artificial Analysis Intelligence Index, making it the #1 US open-weights model
Muse Spark Open (xhigh) scores 22 points above Muse Glimmer (high, 17), Meta's 30B dense open-weights model from August. It is also ahead of NVIDIA's Nemotron 3.5 Super VL (26), the next highest-scoring US open-weights model, which launched today
@AIatMeta shared access with us ahead of public release for benchmarking. Congratulations to @AIatMeta, @finkd, and @alexandr_wang on the release!
Key Takeaways:
➤ Open weights at the level of Meta's August flagship. Muse Spark Open scores within a point of Muse Spark 1.2 (xhigh, 40). It is stronger on AutomationBench-AA and has a lower hallucination rate, but weaker on GDPval-AA v2.1, CritPt and AA-Omniscience accuracy. Within Meta's current lineup, it sits 13 points behind Muse Wonder (max, 52) and 17 points behind Muse Wonder Full (max, 56)
➤ Token-efficient, at a moderate cost per task. Muse Spark Open uses 40k output tokens per Intelligence Index task, the fewest among the nine highest-scoring open-weights models: e.g. 16% fewer than Muse Spark 1.2 (xhigh, 48k) and 43% fewer than GLM-5.3 (max, 71k), its closest Chinese peer by size. Together AI, Fireworks and Baseten offer it at launch for 4.25 per 1M input/output tokens (0.84 per Intelligence Index task. That is less than Muse Spark 1.2 (2.01), but about three times DeepSeek V4.1 Flash (max, $0.27)
➤ A relative weakness in agentic work compared to Chinese open-weights leaders. Among the nine highest-scoring open-weights models, Muse Spark Open ranks last on the four agentic evaluations in the index but fourth on the other six combined, and it leads all open-weights models on AA-Omniscience (25). GLM-5.3 (max), the closest Chinese model by size, owes all of its 6-point lead to the agentic evaluations
➤ Self-hostable on a single node, or two Mac Studios. BF16 weights are ~1.6TB. Meta's NVFP4 checkpoint quantizes only the 256 experts, cutting the weights to ~530GB. Meta says this runs on four Blackwell Ultra GPUs or eight H200s, or on two 512GB M5 Ultra Mac Studios using MLX. The architecture uses 62 layers with grouped-query attention (16 KV heads), 8 of 256 experts active per token, and a 1.8B-parameter Perception Encoder for vision
Other model details:
➤ Parameters: 816B total, 42B active (MoE)
➤ Context window: 1M tokens
➤ License: Muse Model License, a custom license that requires "Built with Muse Spark Open" attribution and a separate agreement with Meta for Model-as-a-Service businesses with over $20M in annual revenue
➤ Input modalities: text, image, video and audio. Output: text
➤ Availability: weights on Hugging Face (BF16 and NVFP4), with API access via Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter and Together AI