NVIDIA Releases Sigma Diffusion Language Models with 3.46x Faster Decoding
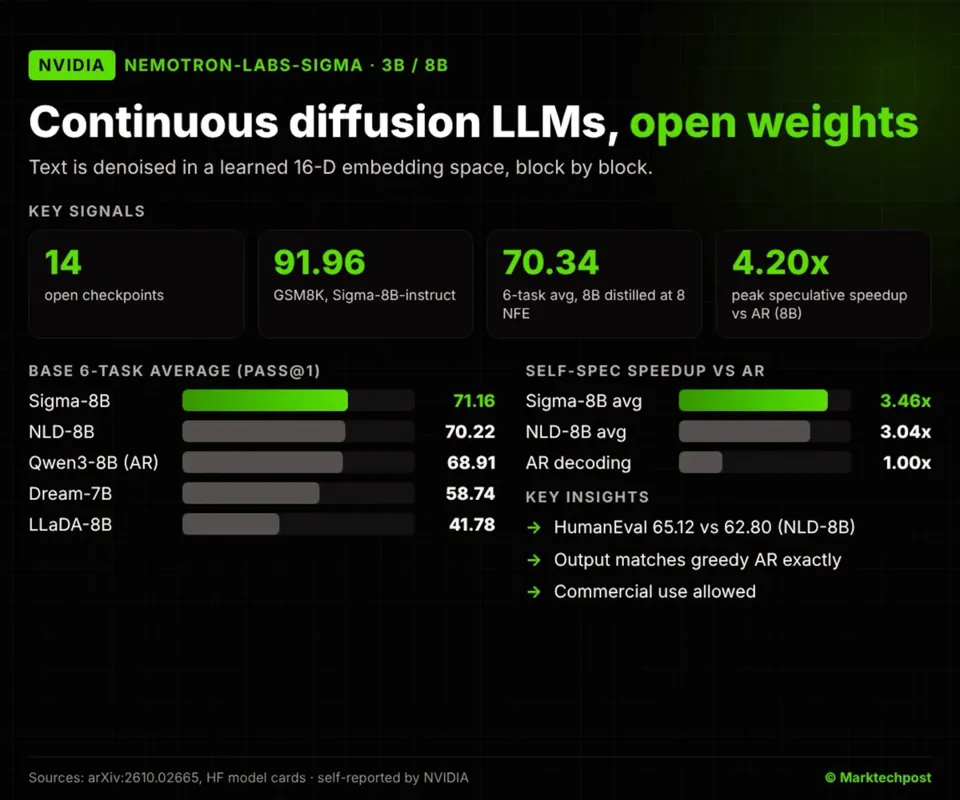
NVIDIA released Nemotron-Labs-Sigma, 14 continuous diffusion language model checkpoints at 3B and 8B that move diffusion out of discrete token space into a learned 16-D embedding space, adding and removing Gaussian noise block by block. Sigma-8B averages 71.16 on NVIDIA's 6-task base suite versus 70.22 for the discrete-diffusion NLD-8B, and self-speculative decoding runs 3.46x faster on average (up to 4.20x) on a single GB200. The trade-off is clear: instruct average of 59.14 trails NLD-8B's 59.92, and AIME25 sits at just 17.00.
Related Entities
Full Report
▲ Marktechpost AI · 2026-11-20 14
▲ NVIDIA just released Nemotron-Labs-Sigma, 14 continuous diffusion language model checkpoints at 3B and 8B that denoise text the way image models denoise pixels.
The key idea is moving diffusion out of discrete token space. Each token becomes a point in a learned 16-D embedding space. The model adds Gaussian noise to those points and learns to remove it, block by block. Smooth trajectories make few-step distillation and steering practical.
On NVIDIA's 6-task base suite, Sigma-8B averages 71.16 vs 70.22 for NLD-8B, NVIDIA's discrete diffusion model. HumanEval is 65.12 vs 62.80. The self-speculative 8B decodes 3.46x faster than AR on average (up to 4.20x) on 1 GB200. It is a trade-off though: the instruct average of 59.14 trails NLD-8B at 59.92, and AIME25 sits at 17.00......
Full analysis: