NVIDIA Study: Frequent Context Compaction Cuts Agent Costs with Minimal Accuracy Loss
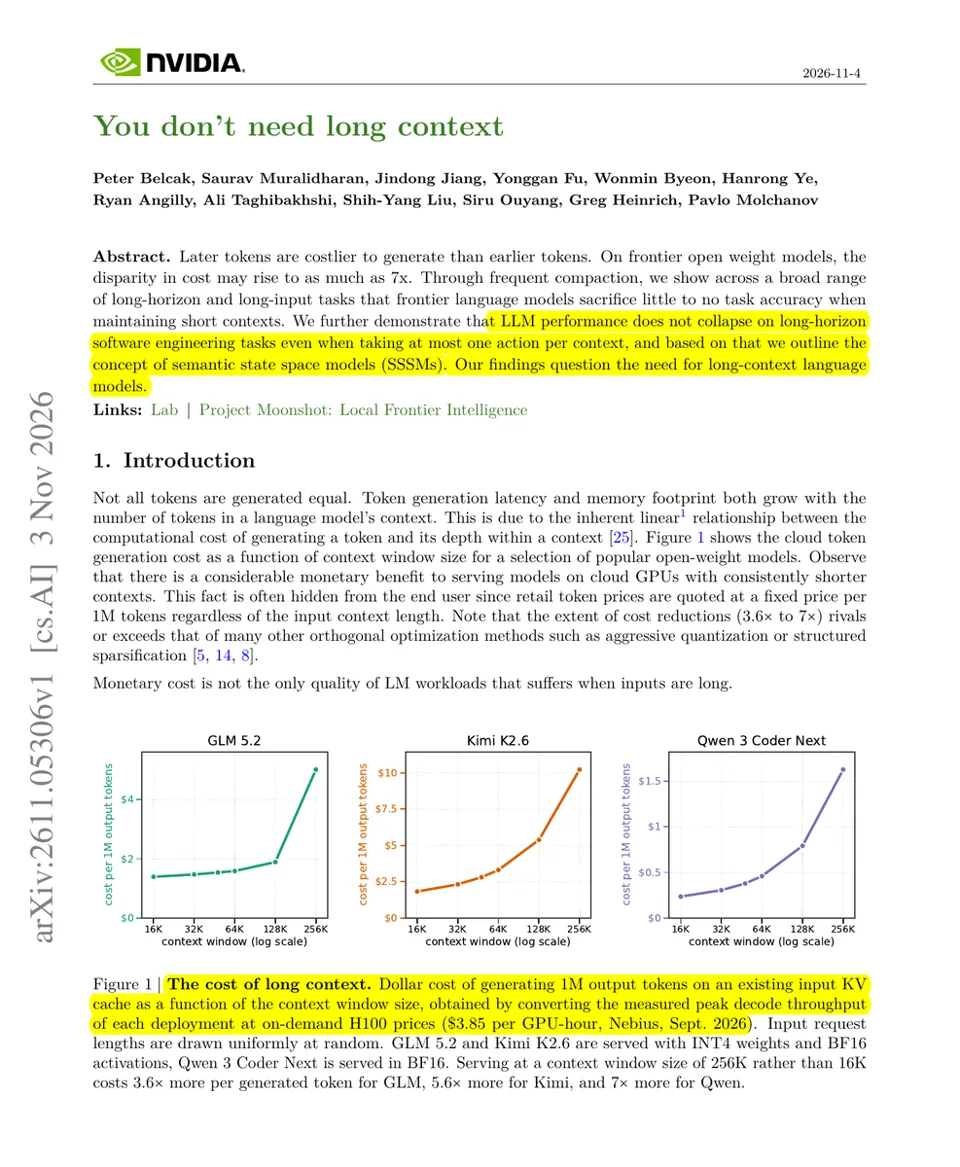
A new NVIDIA paper reveals that AI agents can significantly reduce inference costs by frequently compacting conversation history into short handoff notes and restarting sessions without sacrificing accuracy. Experiments show that combining file search tools with this strategy results in less than a 2-point accuracy drop on most benchmarks, whereas serving models with large context windows increases per-token generation costs by 3.6x to 7x.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-04 18
New NVIDIA paper finds that AI agents barely lose accuracy when they keep contexts short by compacting their history often.
Each new token costs more to generate as the context grows. Serving open models at a 256K context window instead of 16K cost 3.6x to 7x more per generated token.
They had agents stop at a set limit, write a short handoff note, and restart with only the task and that note. For long documents, the agent searched files with Bash tools instead of reading everything at once.
On 6 long-horizon benchmarks, at most 5 of 22 compaction settings per model lost more than 2 points versus full history. Compacting after every action kept Claude Opus 4.5 at 70.2% on SWE-bench Verified, versus 70.0% with full history.
Before paying for long context, give agents a structured handoff note and file search tools, then check if short contexts match your accuracy.