Hacker News AI · 10/14/2026, 05:57:29
AlphaNIST: End-to-End RL Policy for High-Precision Robotic Assembly Without Prescribed Stages
AlphaNIST applies the self-play philosophy of AlphaZero to contact-rich robotic assembly in simulation. It introduces an end-to-end reinforcement learning policy that learns to complete complex tasks, such as the NIST ten-component board, without human demonstrations or prescribed manipulation stages.
SOURCE COVERAGEFull Original Report
Contents8 sections
From AlphaGo to AlphaZero, reinforcement learning produced strategies that surprised expert players. AlphaZero learned from experience at scale, without human demonstrations.
AlphaNIST brings this philosophy to contact-rich, high-precision robotic assembly in simulation. An end-to-end policy learns how to complete the task, without prescribed manipulation stages.
Your browser does not support embedded video. Download the film. Ten-component assembly.
Four successful ten-part runs, using a policy trained separately from the single-component policy below.
The assembly challenge
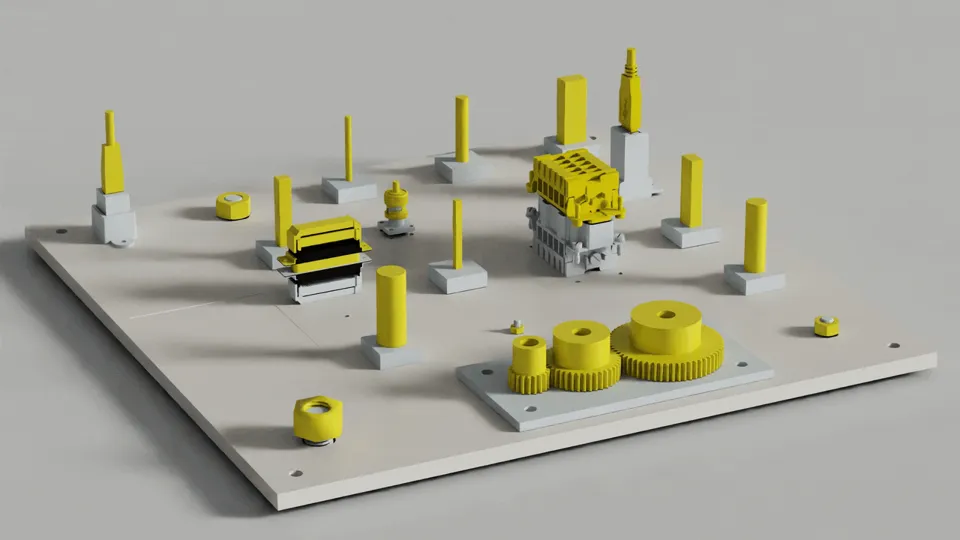
NIST Assembly Task Board #1, shown fully assembled.
The NIST board has twenty assembly tasks, with parts as small as 4 mm. Fitting one part can take several changes of grasp and orientation. Tight clearances leave little room for error: a tilted nut can jam or cross-thread.
With several parts, the robot also has to choose an order. An installed component may block the gripper’s next move.
Robots can be creative—if we give them room.
Trying to prescribe every maneuver means anticipating how the robot should respond as contacts and obstructions change. A two-finger gripper may also need solutions quite different from those that come naturally to a human hand.
Perhaps the answer is to stop telling the robot how we think the task should be done, and let it learn how to get there. We give it a binary task reward for success and train it through vast amounts of diverse experience. That leaves room for the robot to discover solutions we might never have thought to teach.
How the robot learns
Experience diversity:
heterogeneous assets and initial states
One policy trains across twenty heterogeneous assemblies, starting from loose parts, in-hand grasps, and partial assemblies cached in simulation.
Near-complete starts let the robot practice finishing an assembly before it can solve the whole task. The cache supplies starting states, not demonstrations.
Your browser does not support embedded video. Download the video. Examples of diverse training starting states
Success-guided sampling
Beta sampling favors starting states the policy solves about half the time, while giving every state a chance. Progress on one state can make another solvable; its sampling weight then changes with new outcomes.
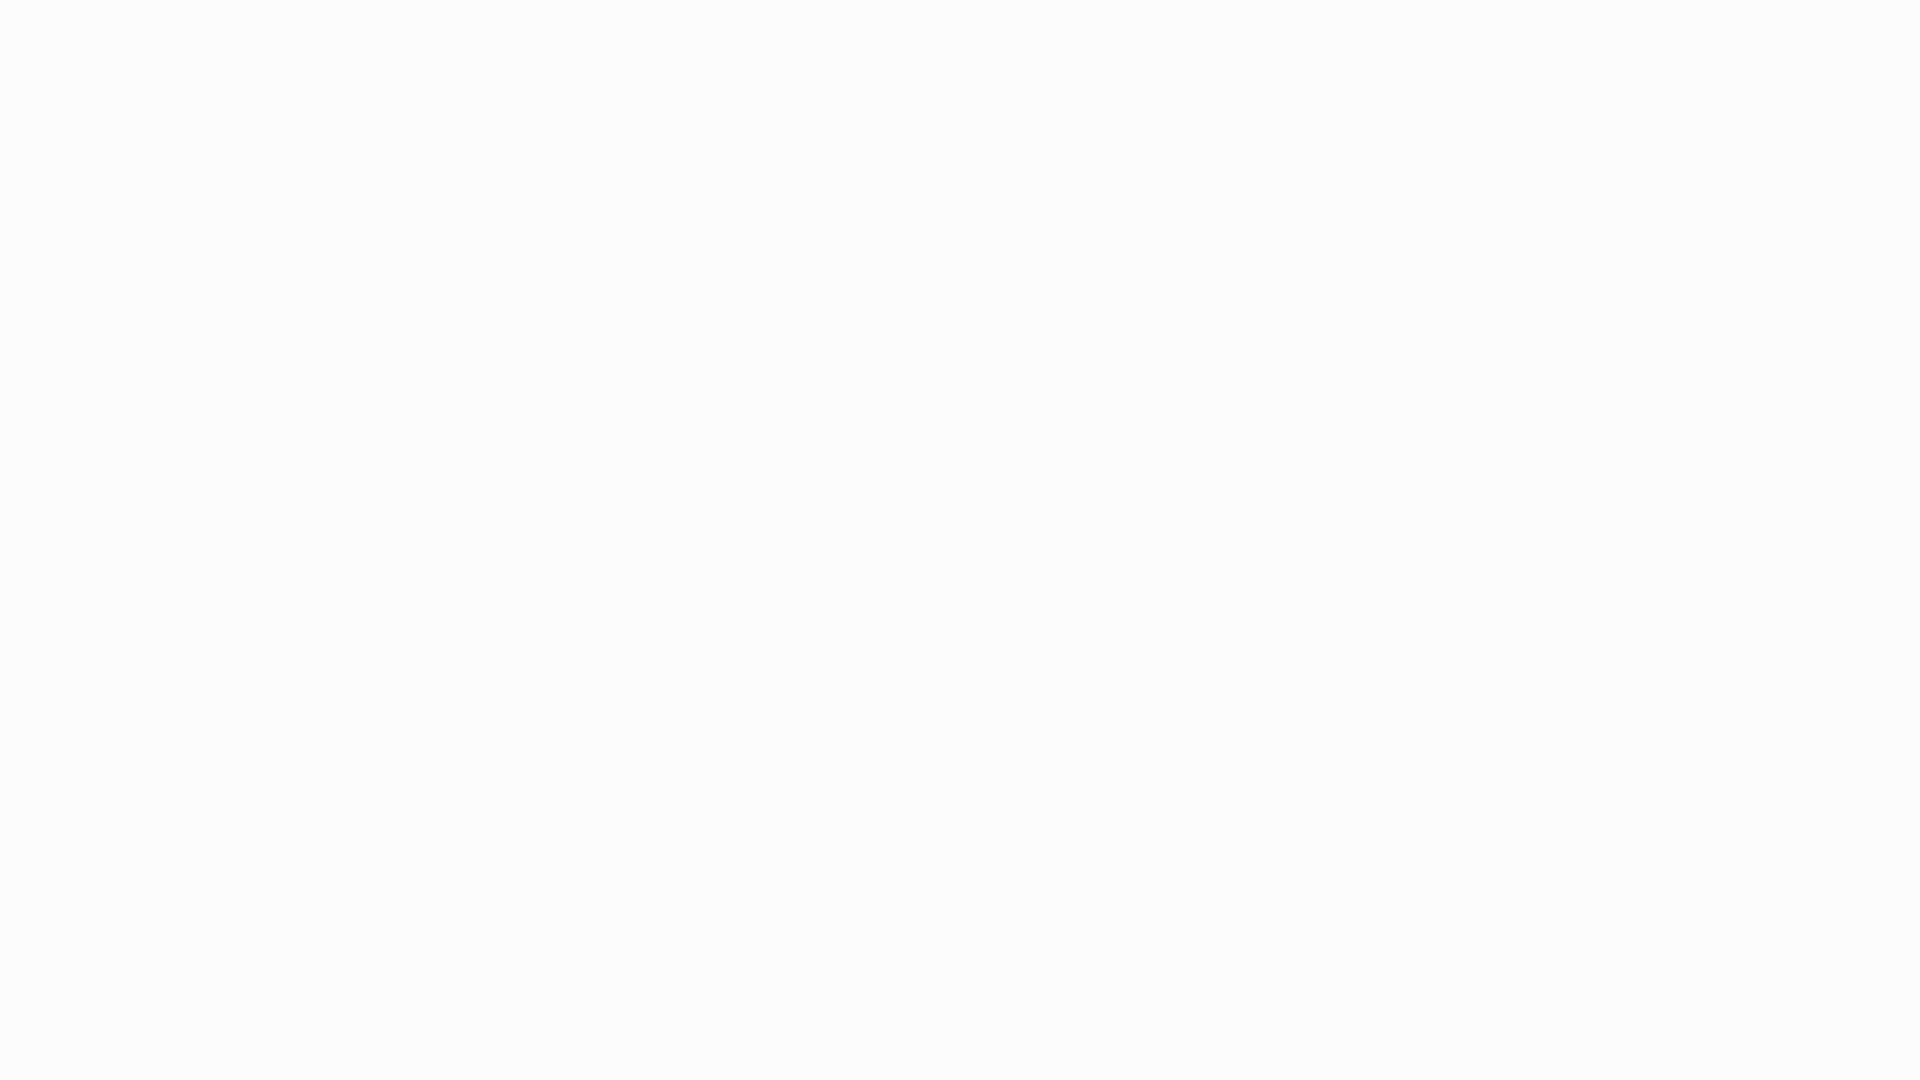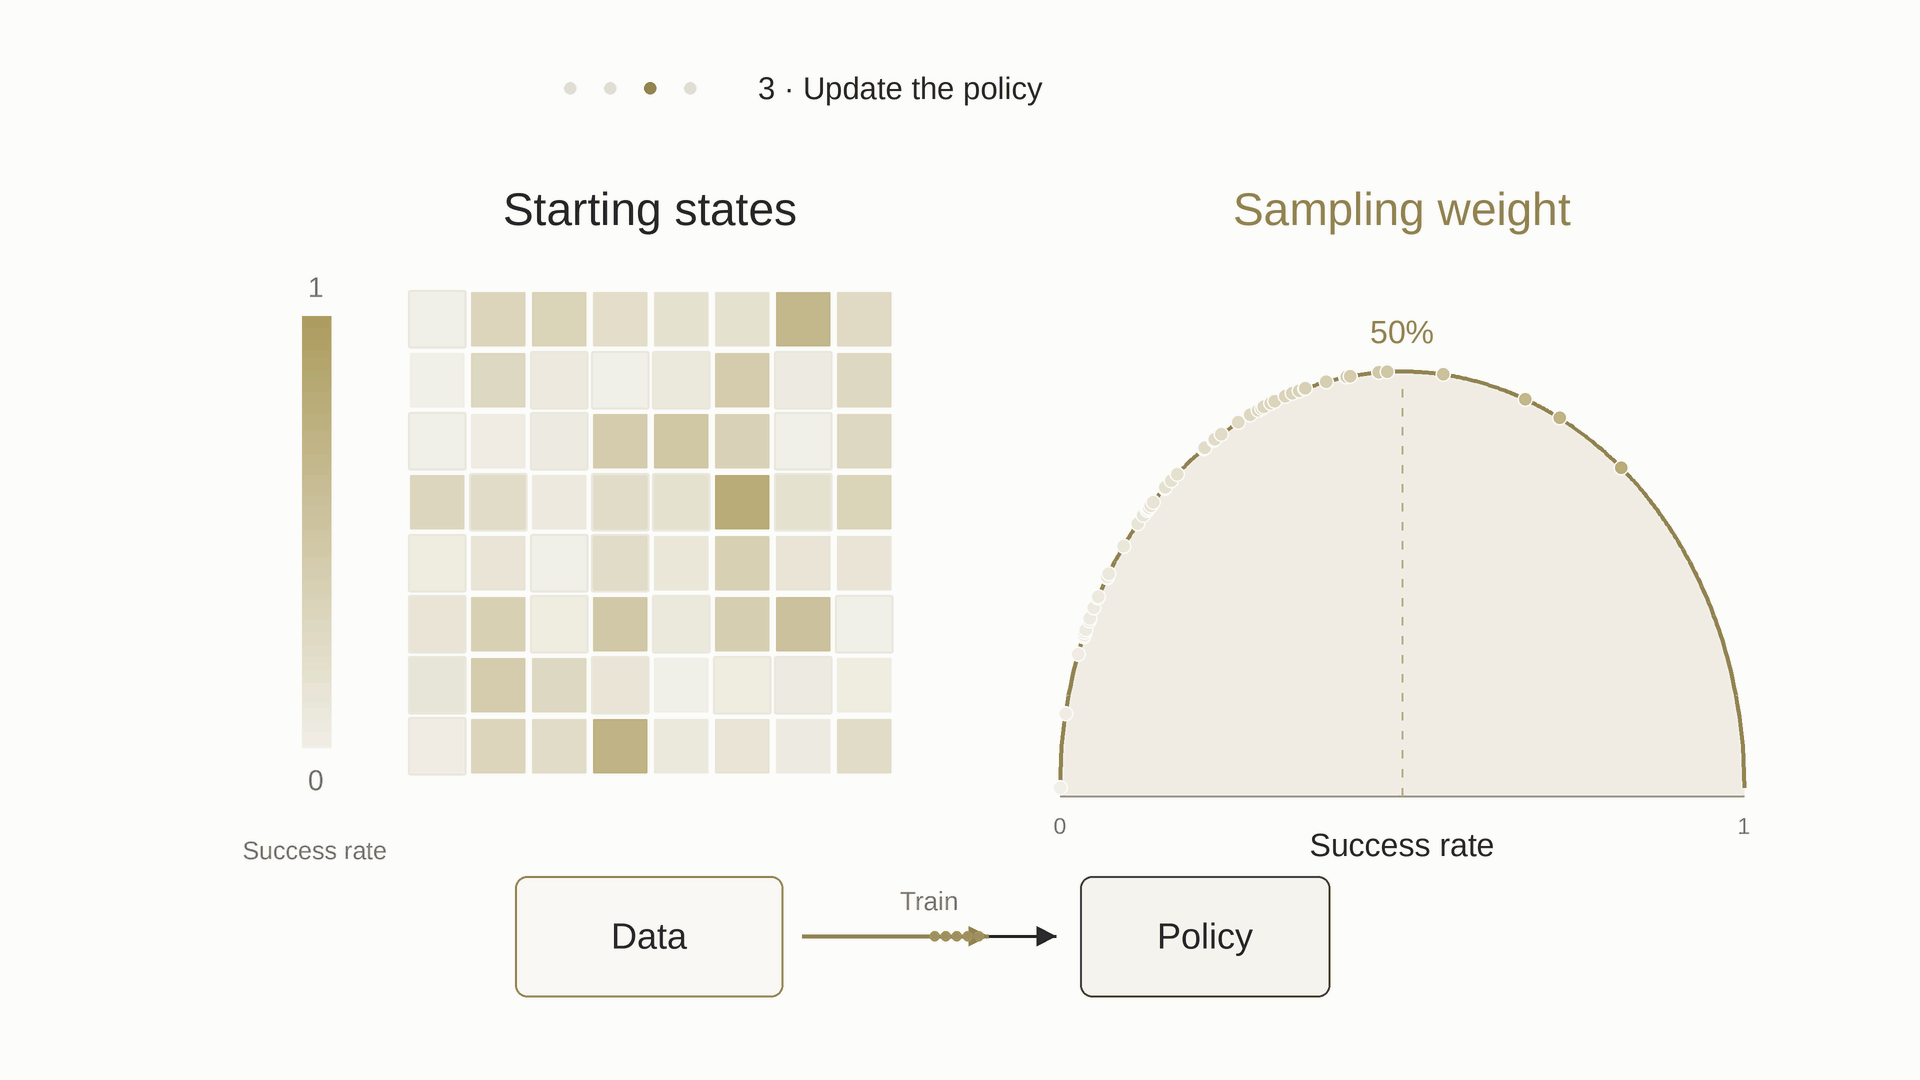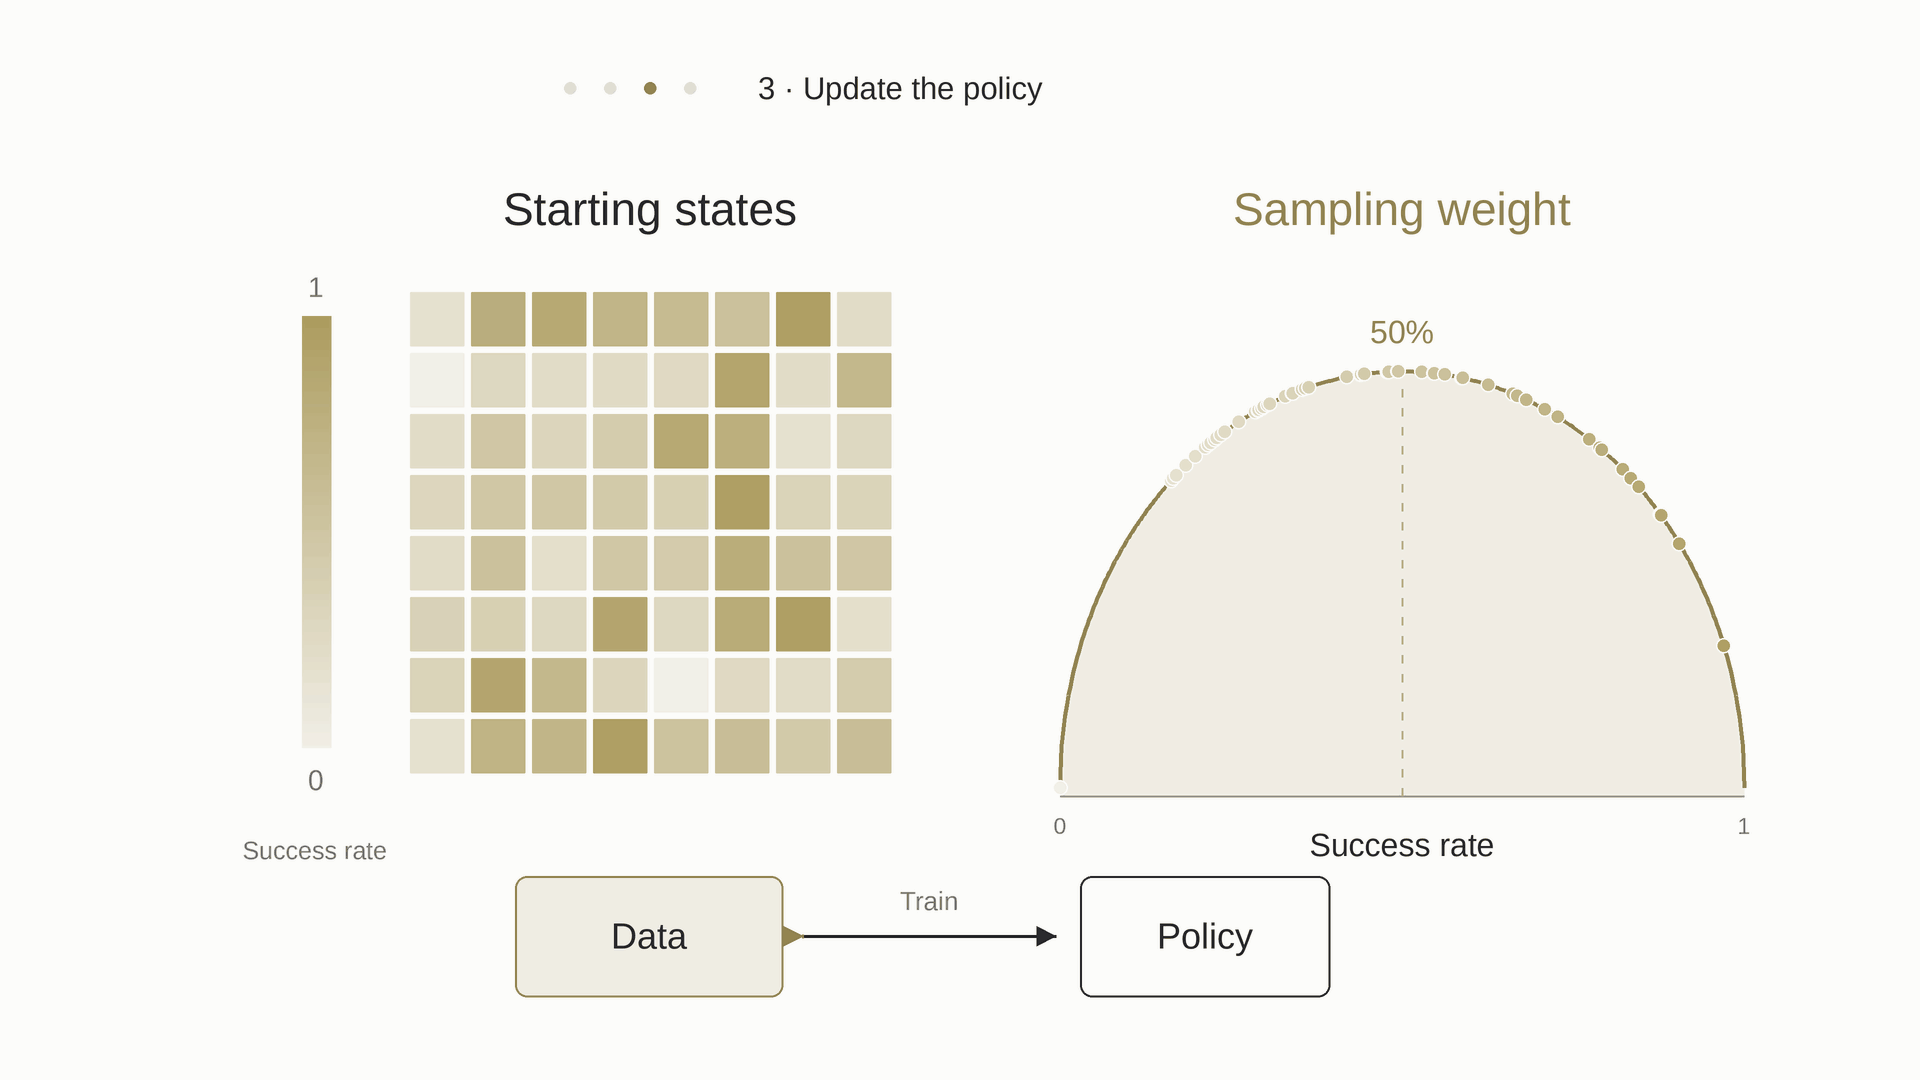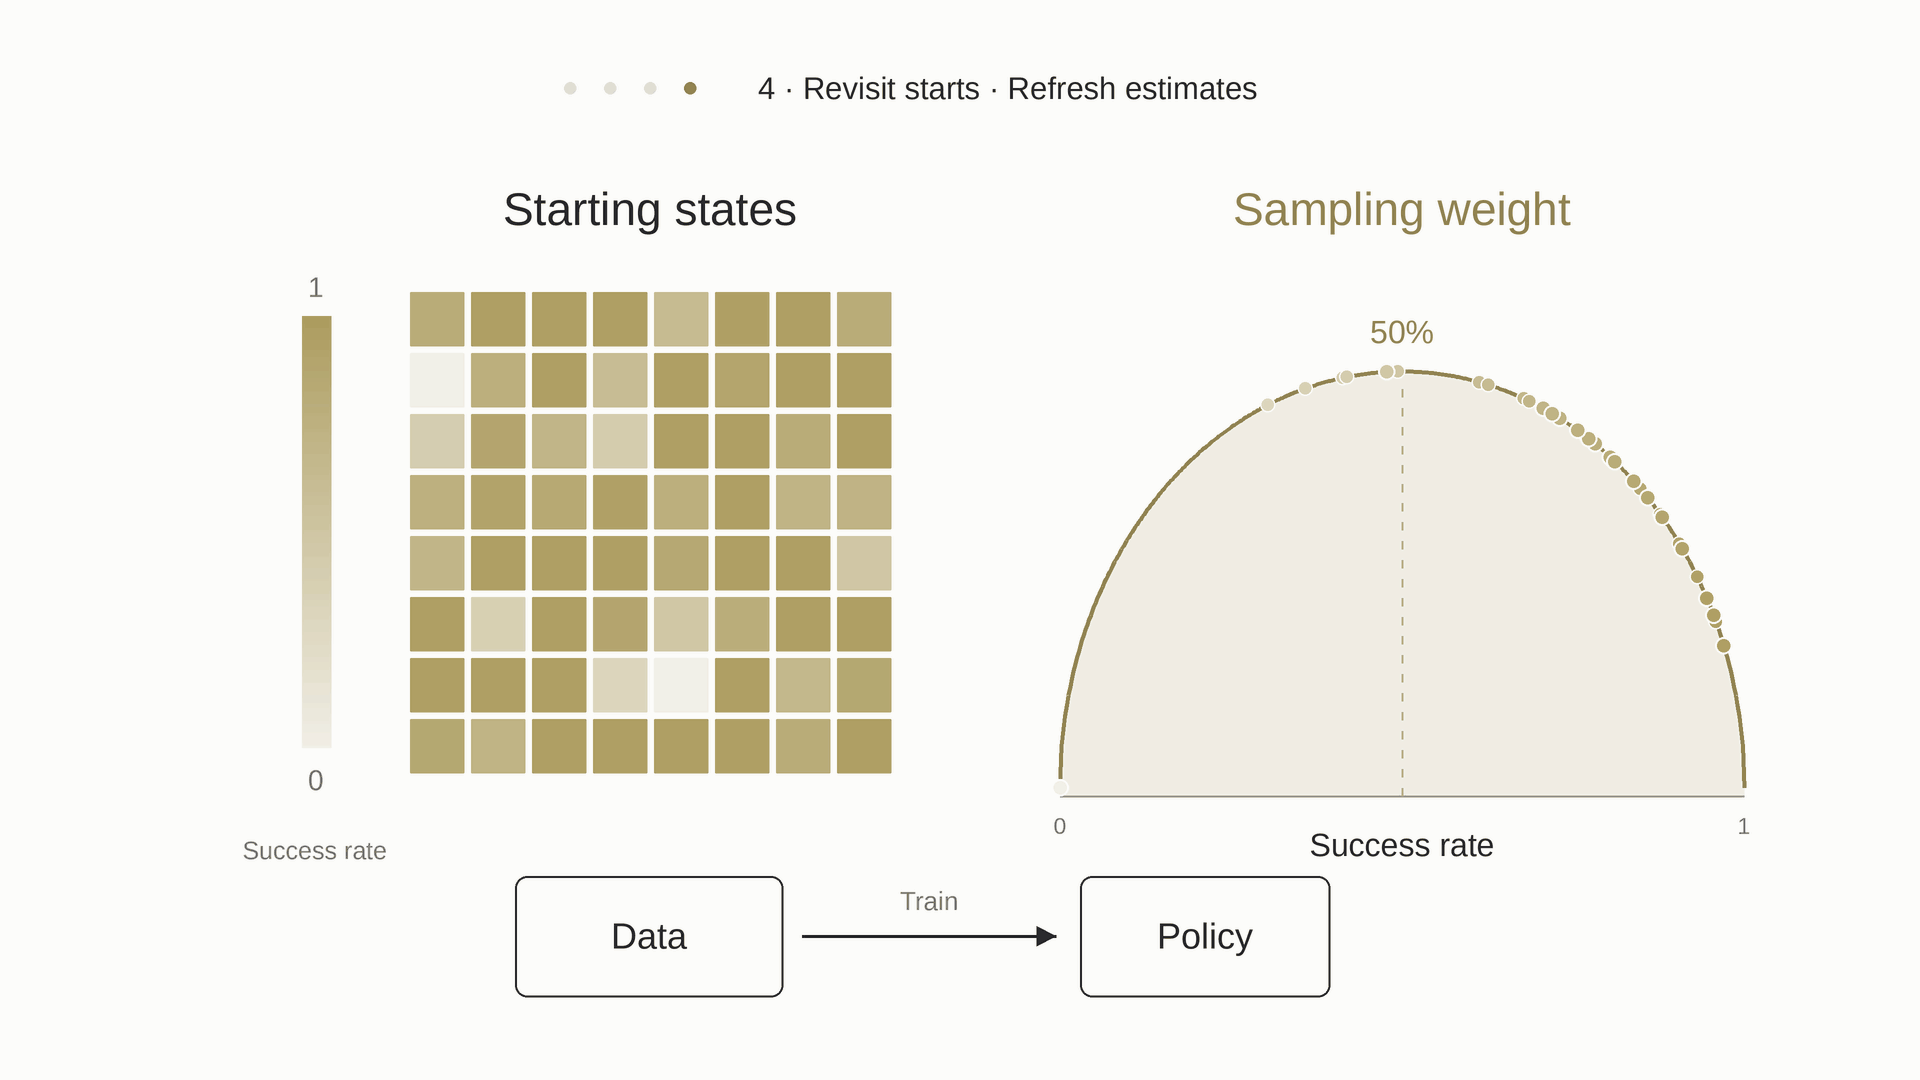
Starting states receive different amounts of practice as the policy learns. SGS project ↗
Single-component assembly experiment
Your browser does not support embedded video. Download the film. One policy performs all twenty assembly tasks, with one component to assemble in each run.
With binary task rewards, one policy trained across all twenty tasks reaches higher training success than twenty separate specialists. Adding rewards for reaching and alignment reduces success in this experiment.
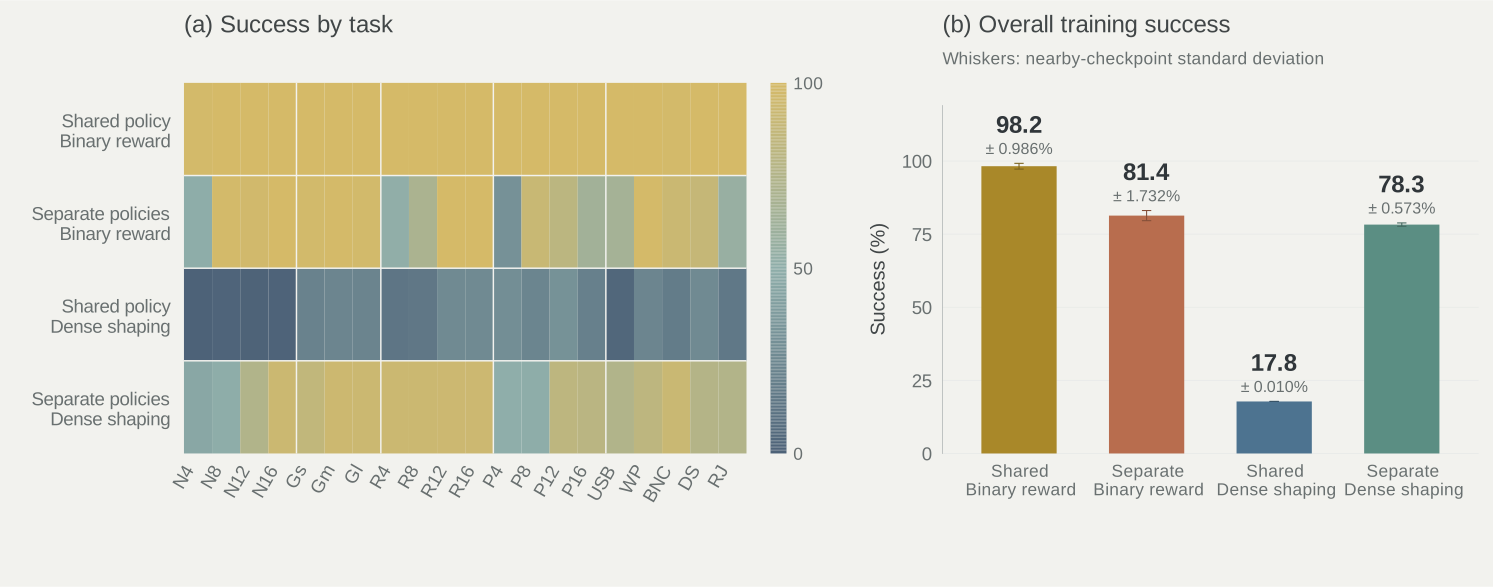
Swipe or scroll horizontally to view the full figure.Training success across varied starting states.
Emergent assembly behavior
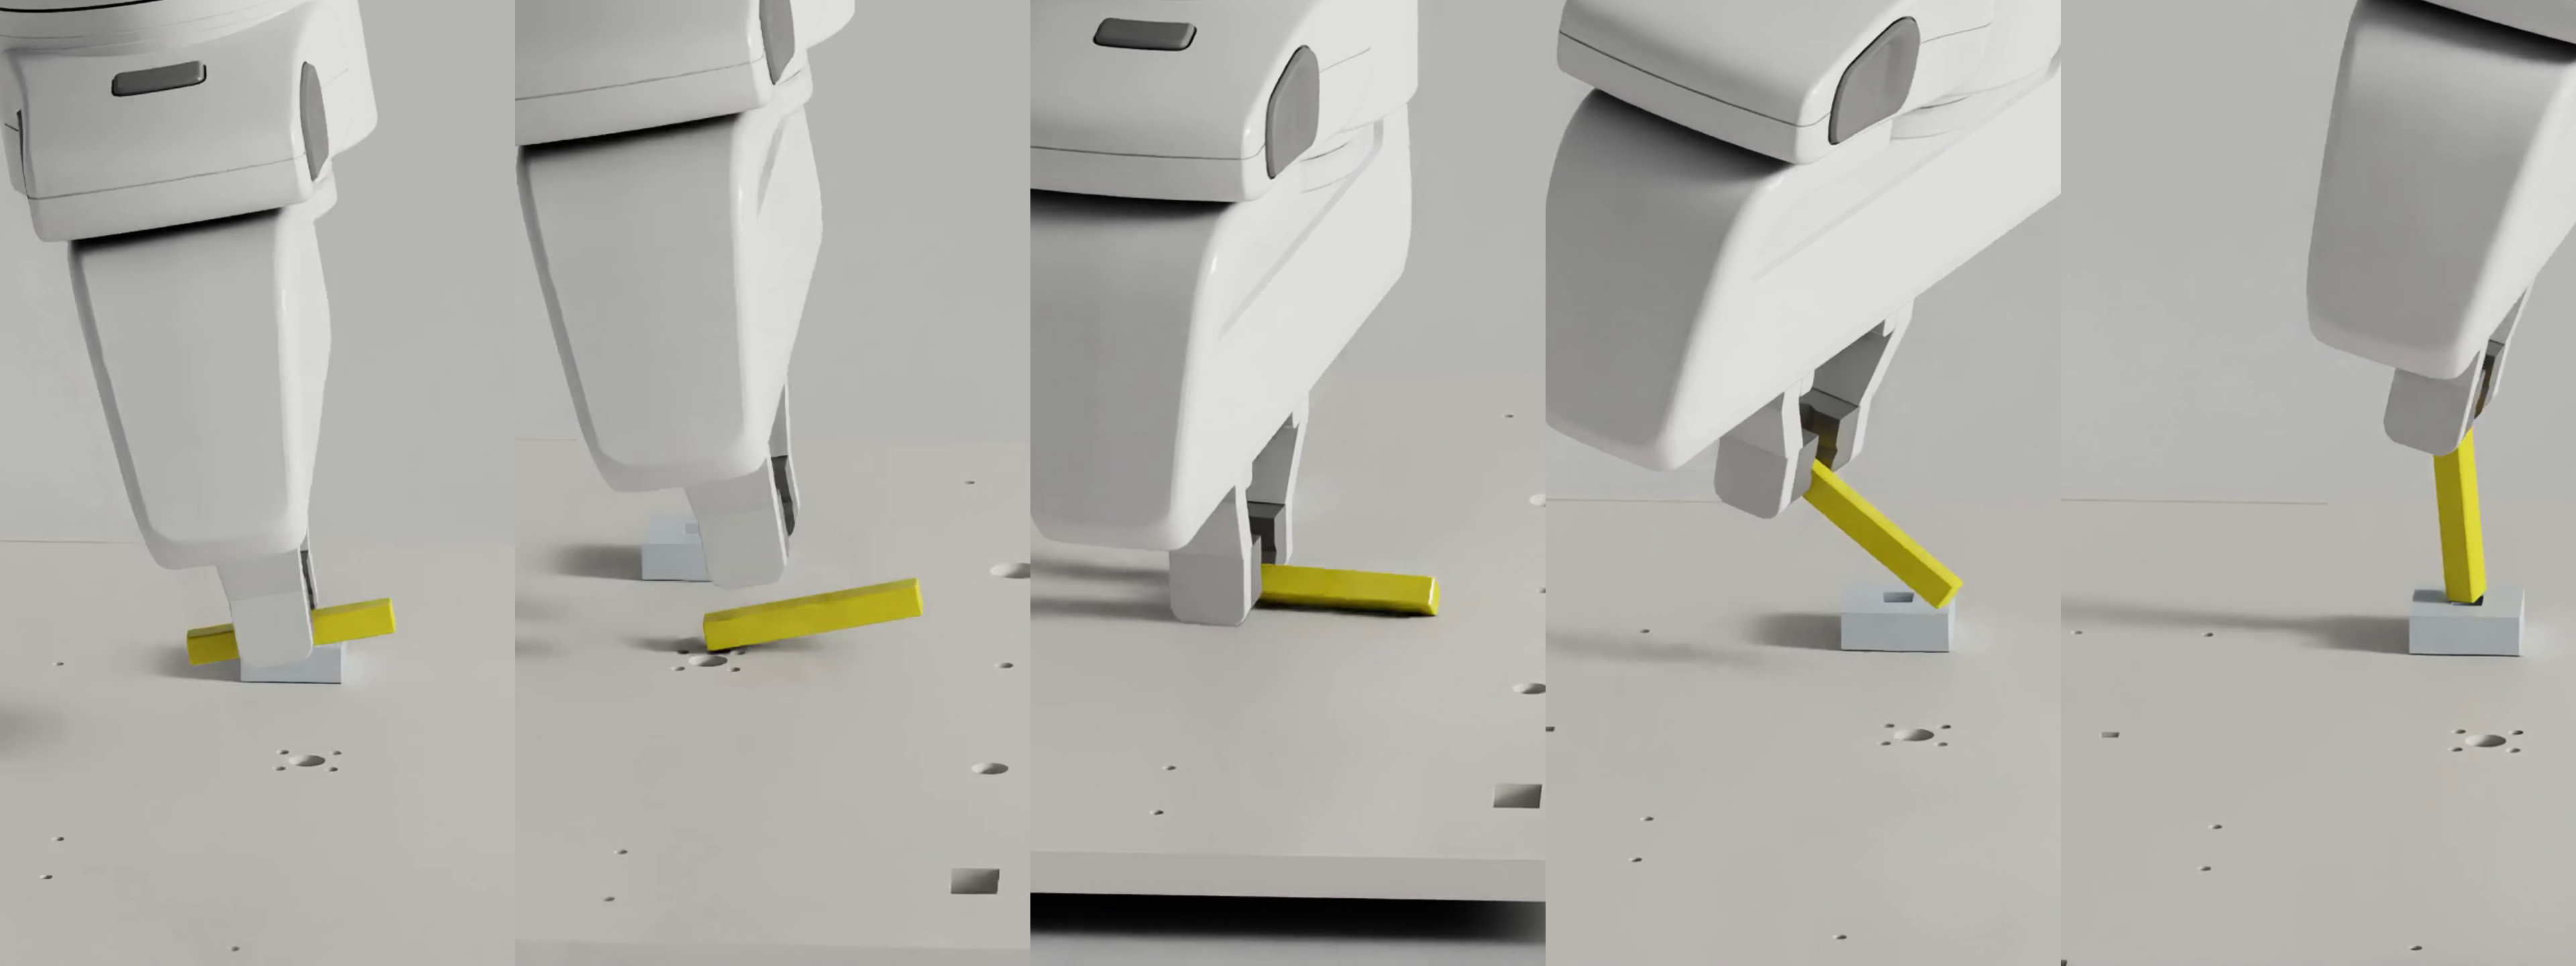 The gripper puts down the 8 mm peg and picks it up near one end, leaving more of the peg exposed for insertion.
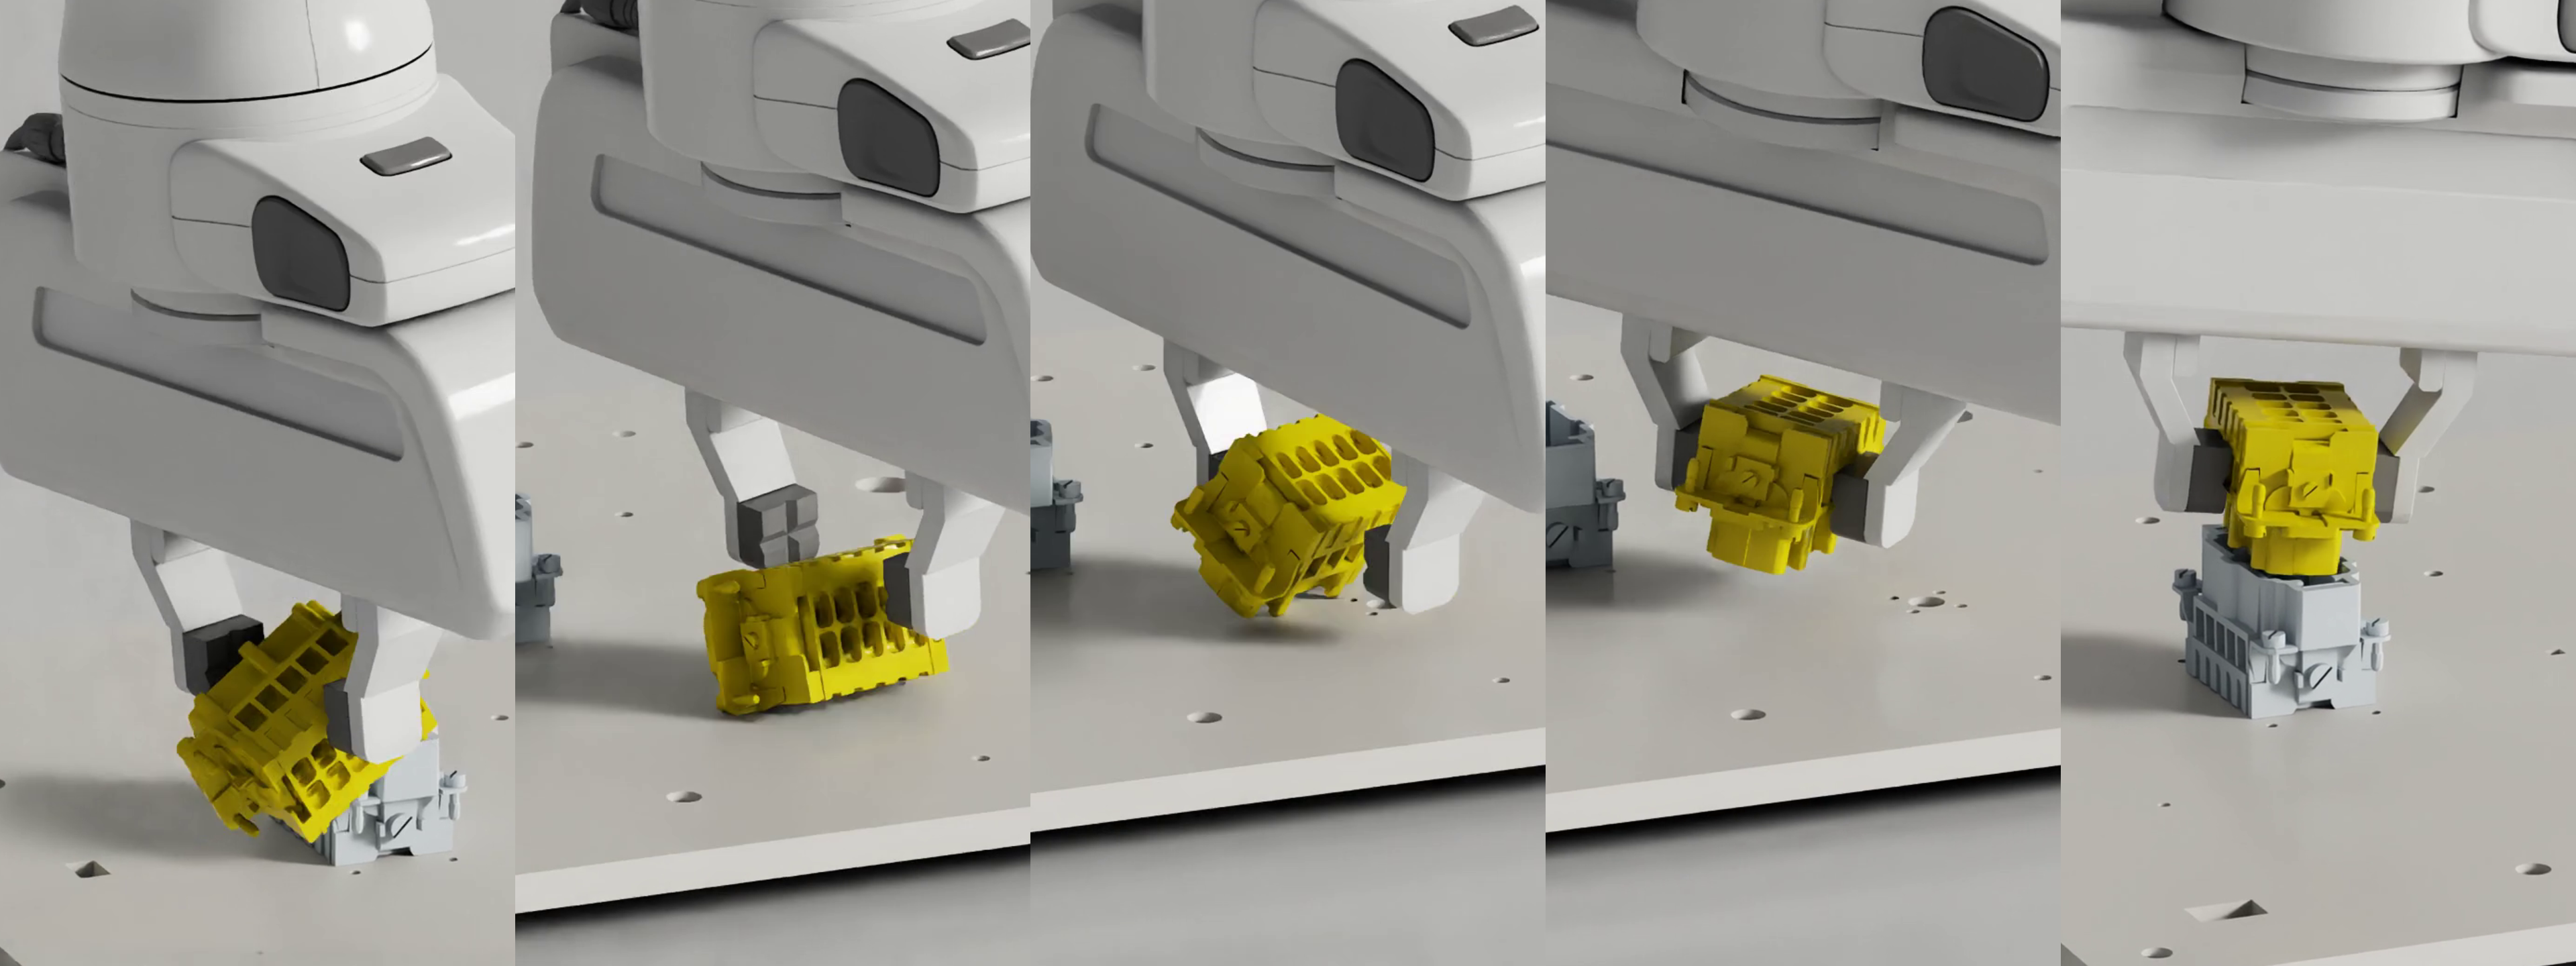 The gripper uses contact with the board to turn the waterproof connector before inserting it.
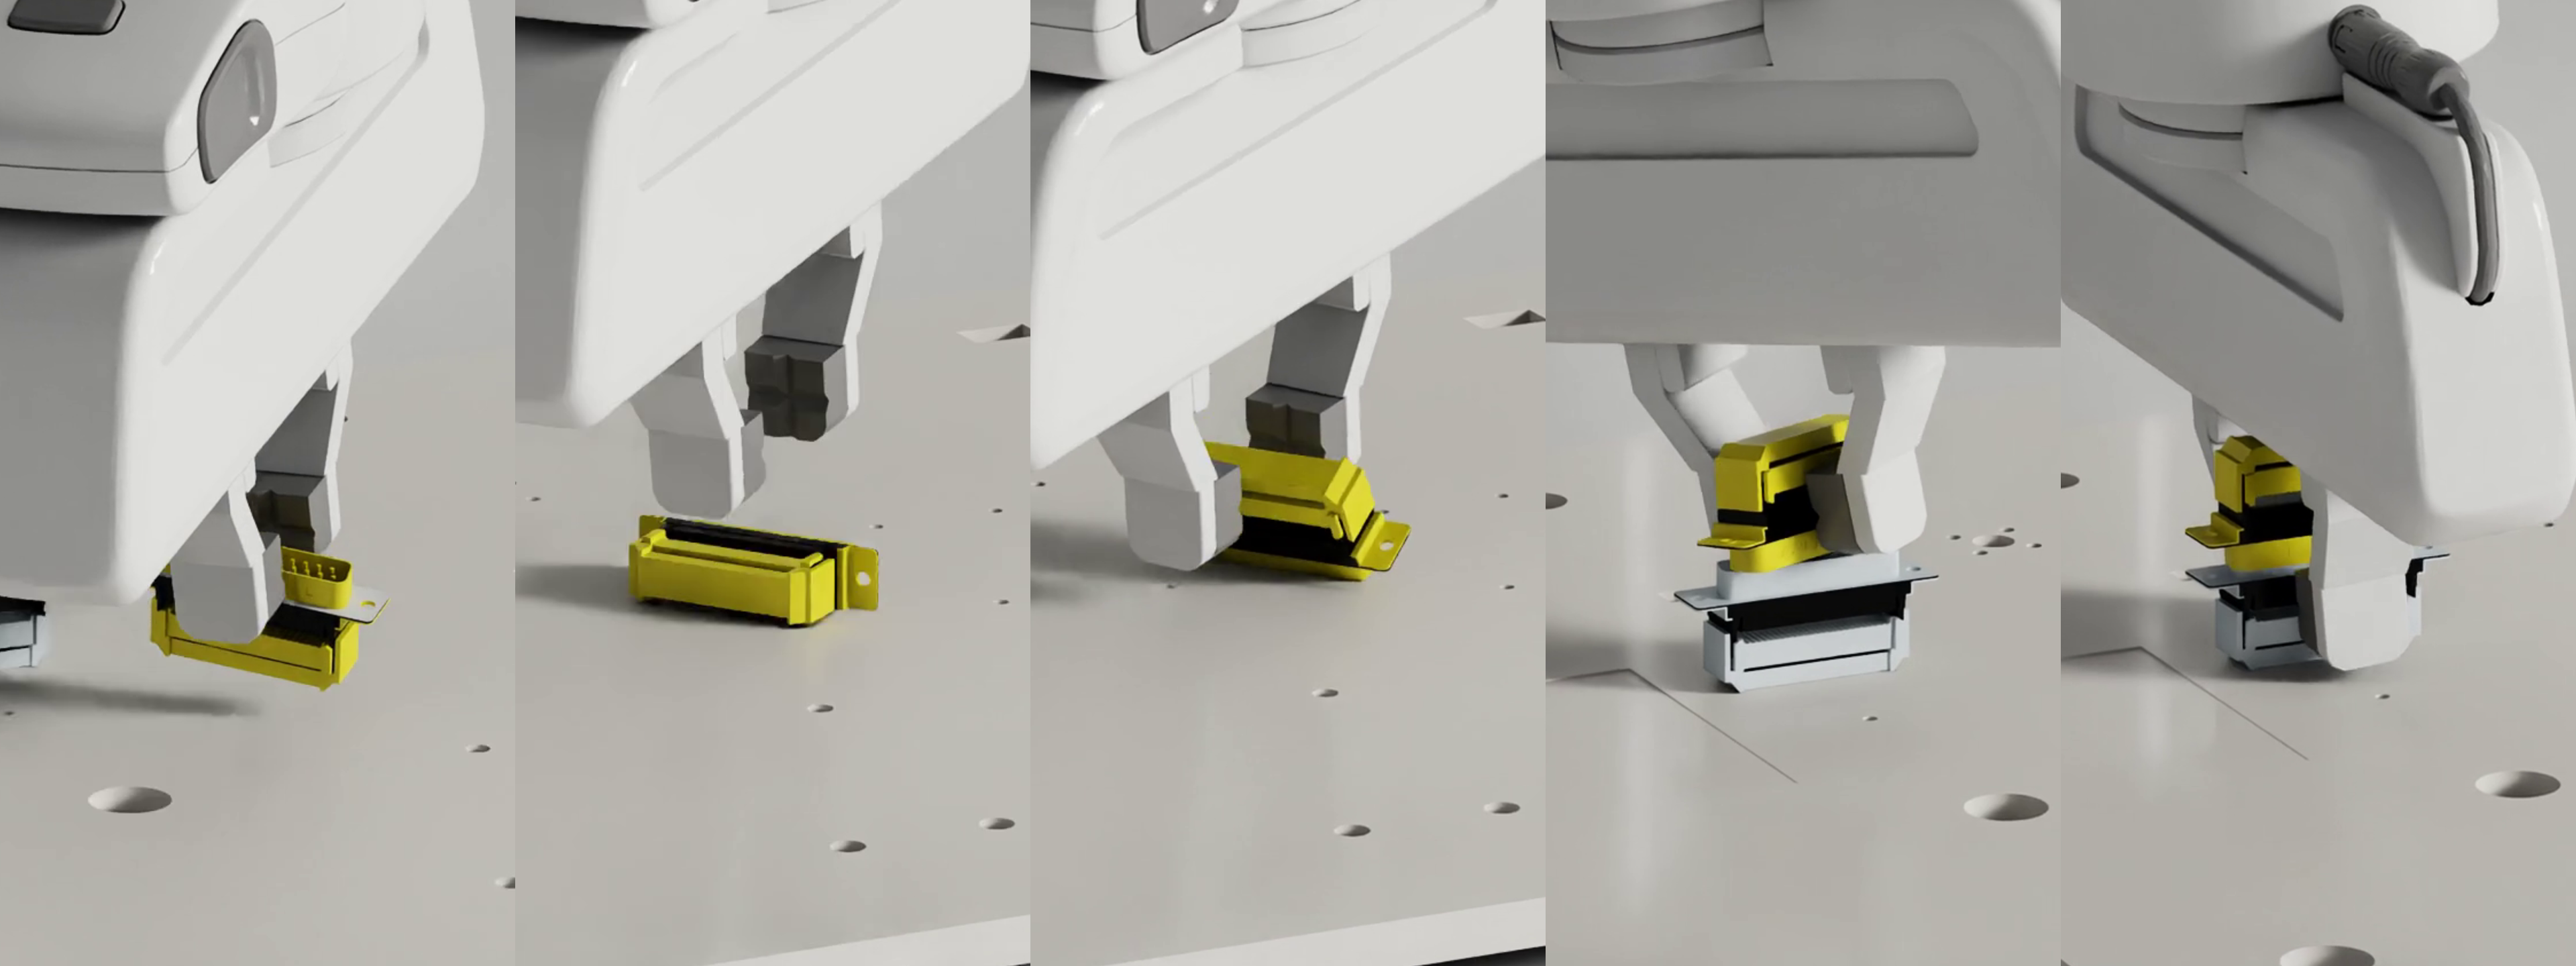 The D-sub connector is set down and regrasped to align it with its socket.
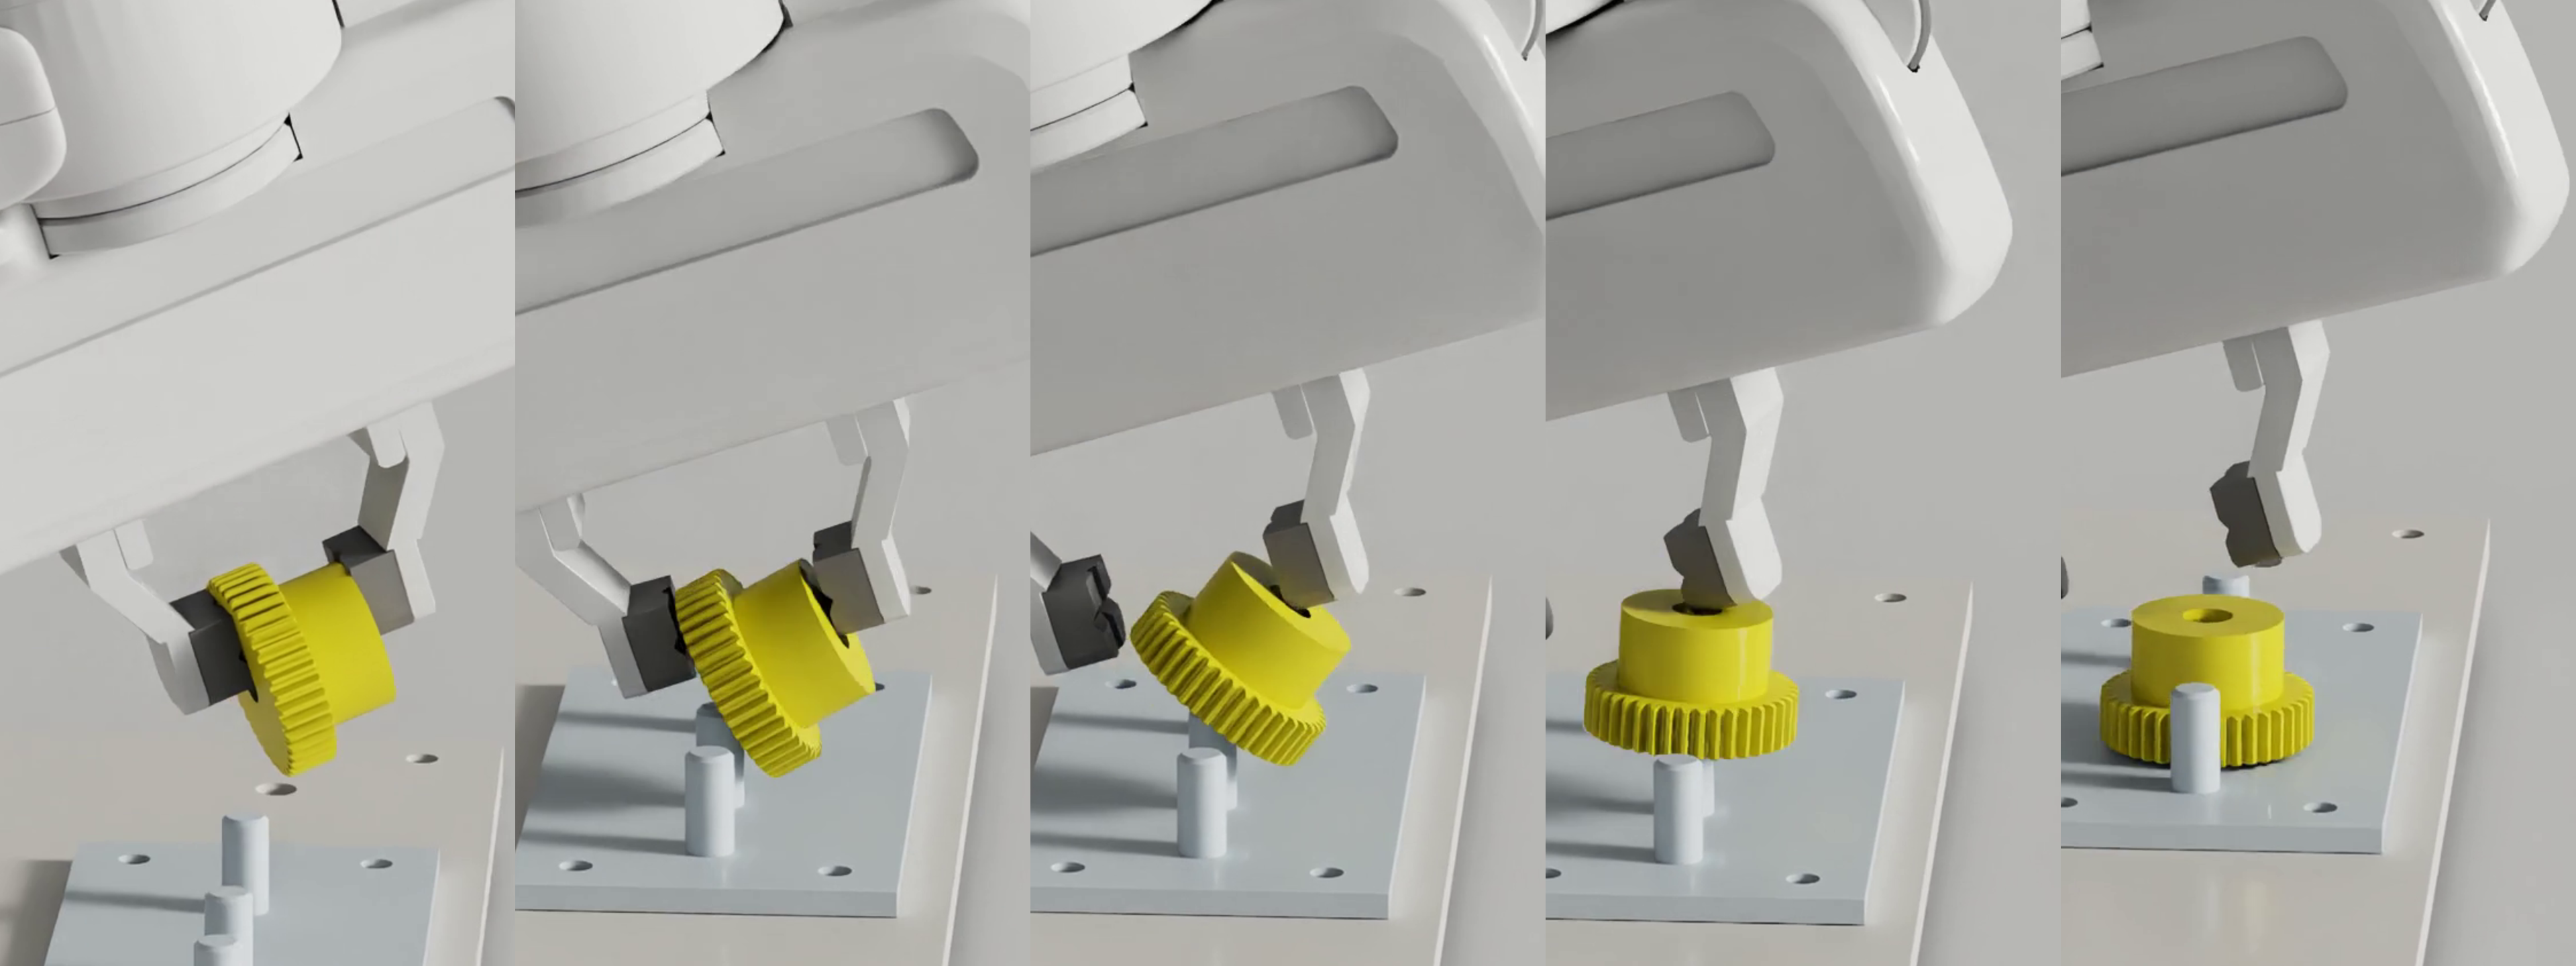 Held from the side, the medium gear pivots into a horizontal pose above its mounting post.
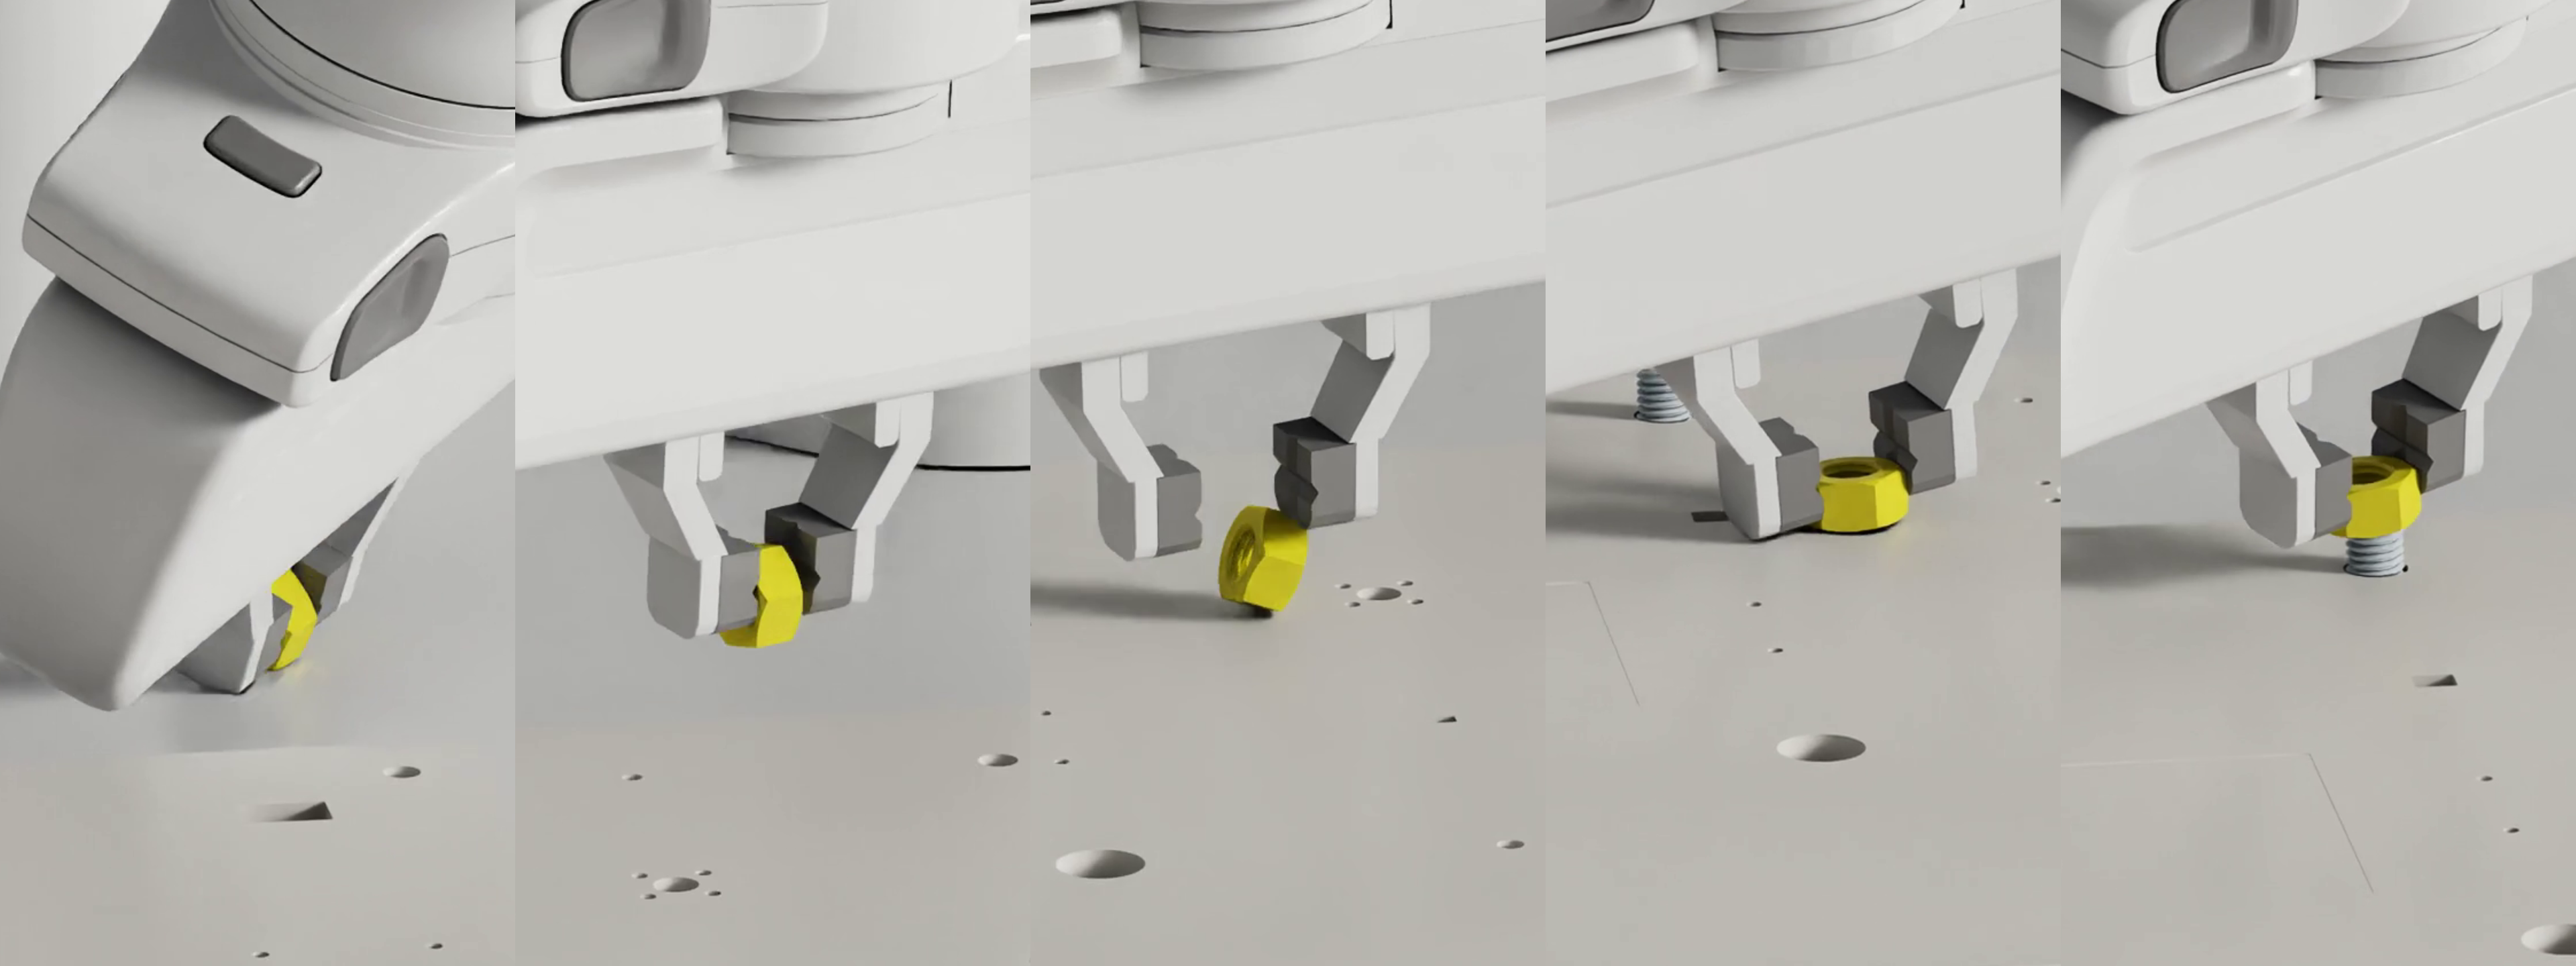 The gripper rolls the M12 nut from its edge onto a flat face before placing it on the bolt.
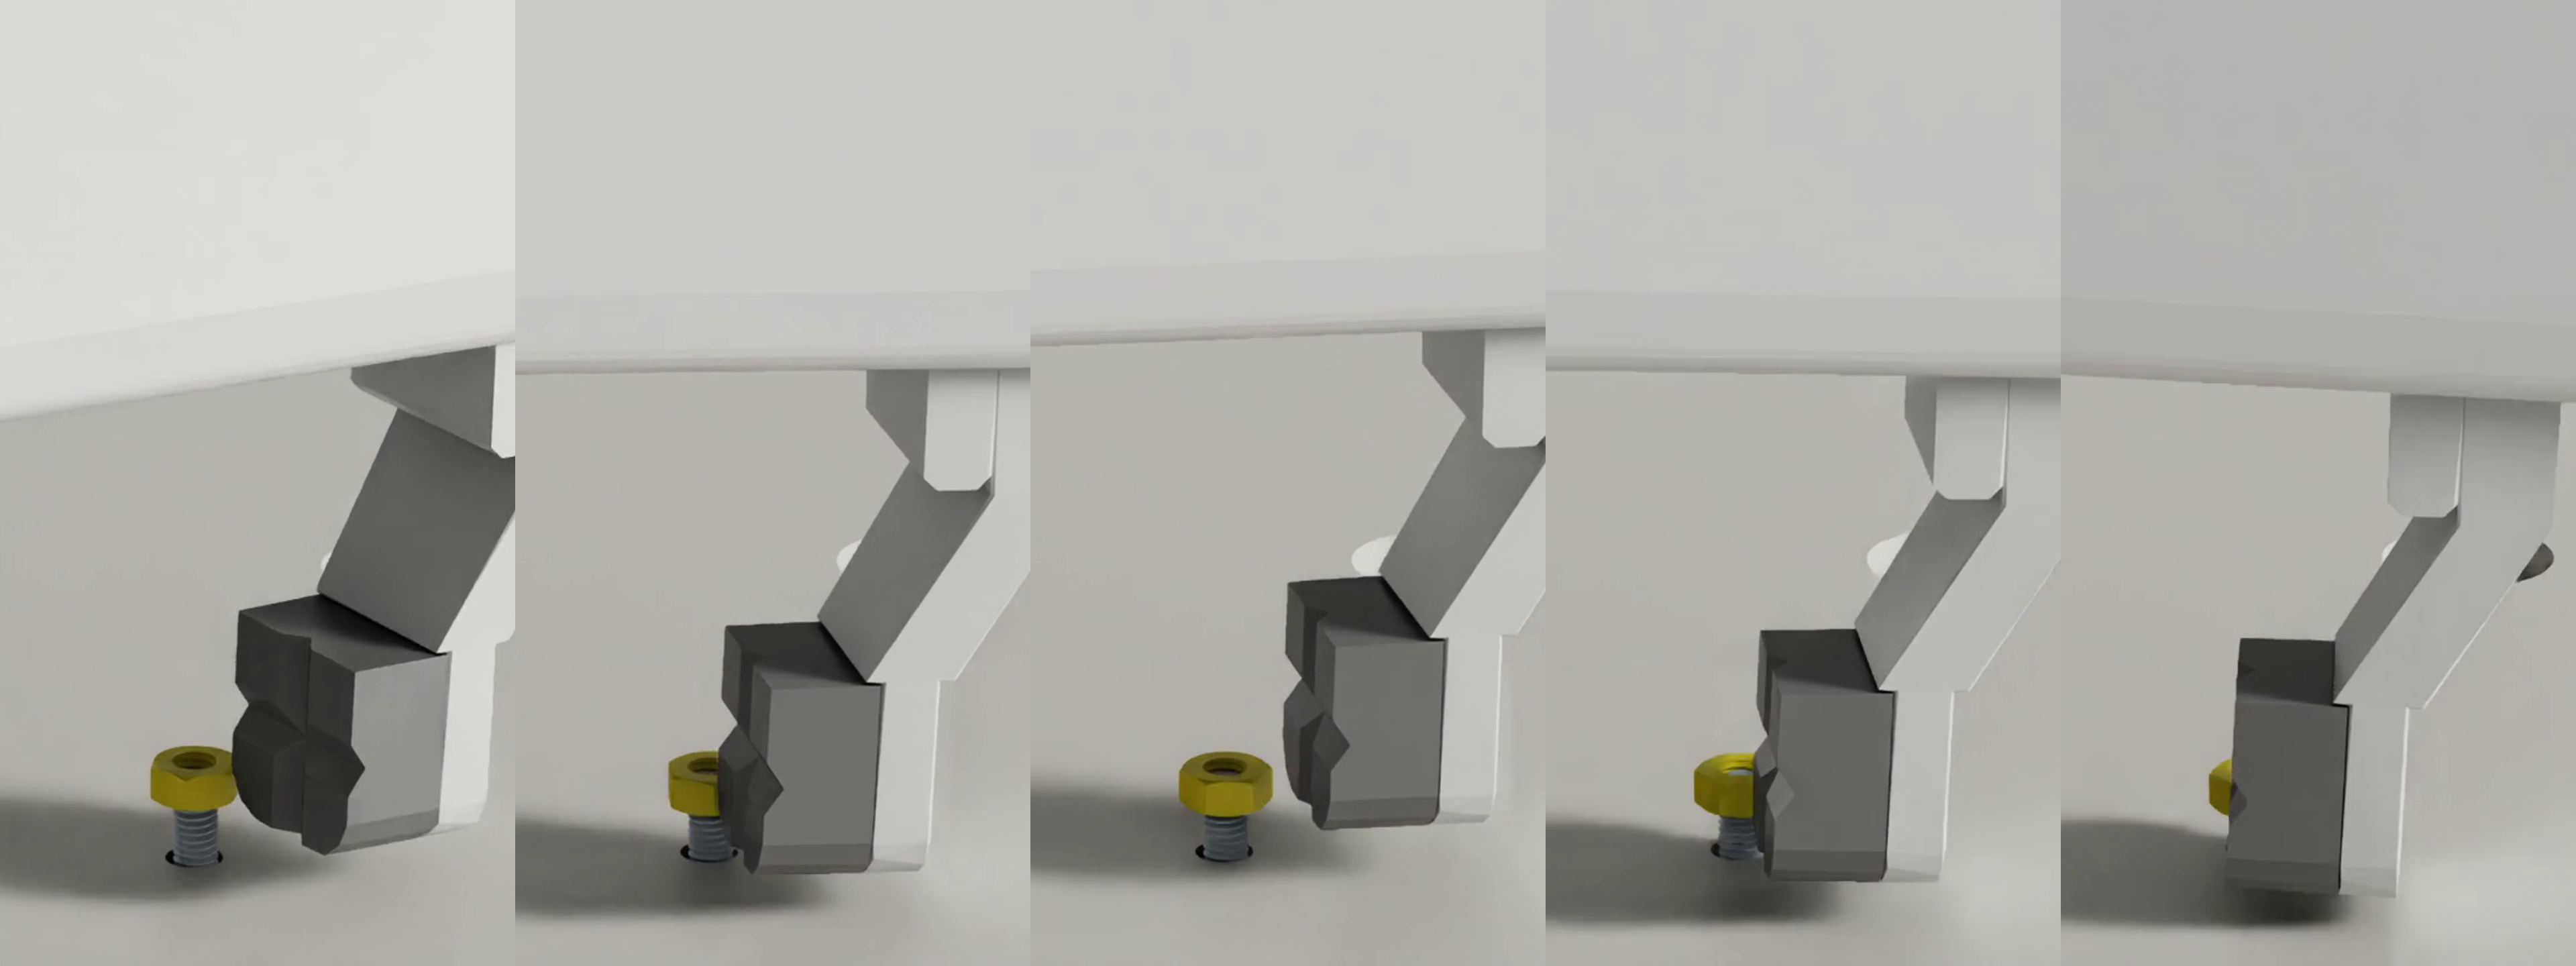 One-sided fingertip taps turn the M4 nut along the bolt.
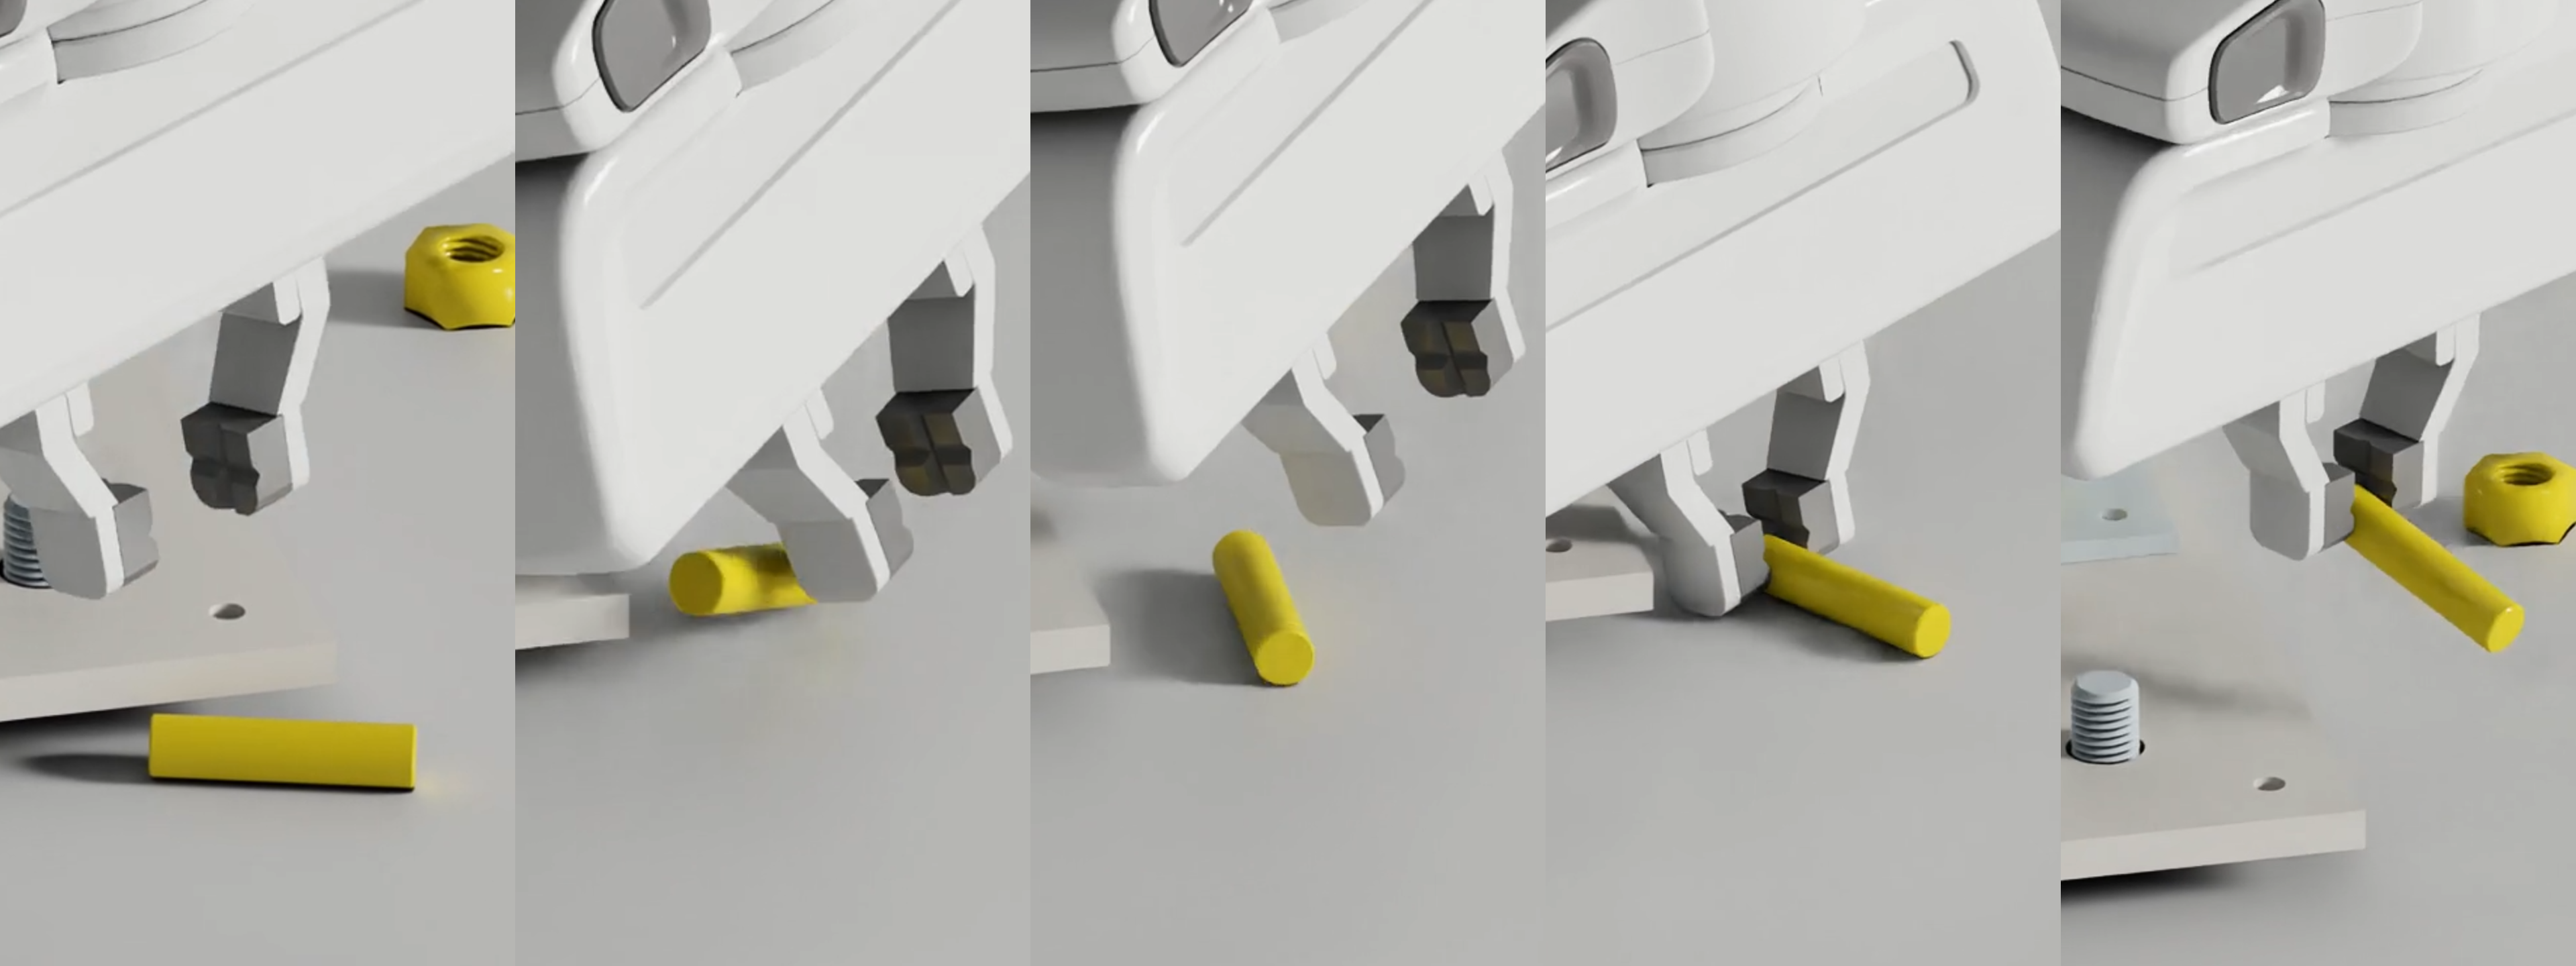 A fingertip pushes the 8 mm rod across the surface before the gripper picks it up.
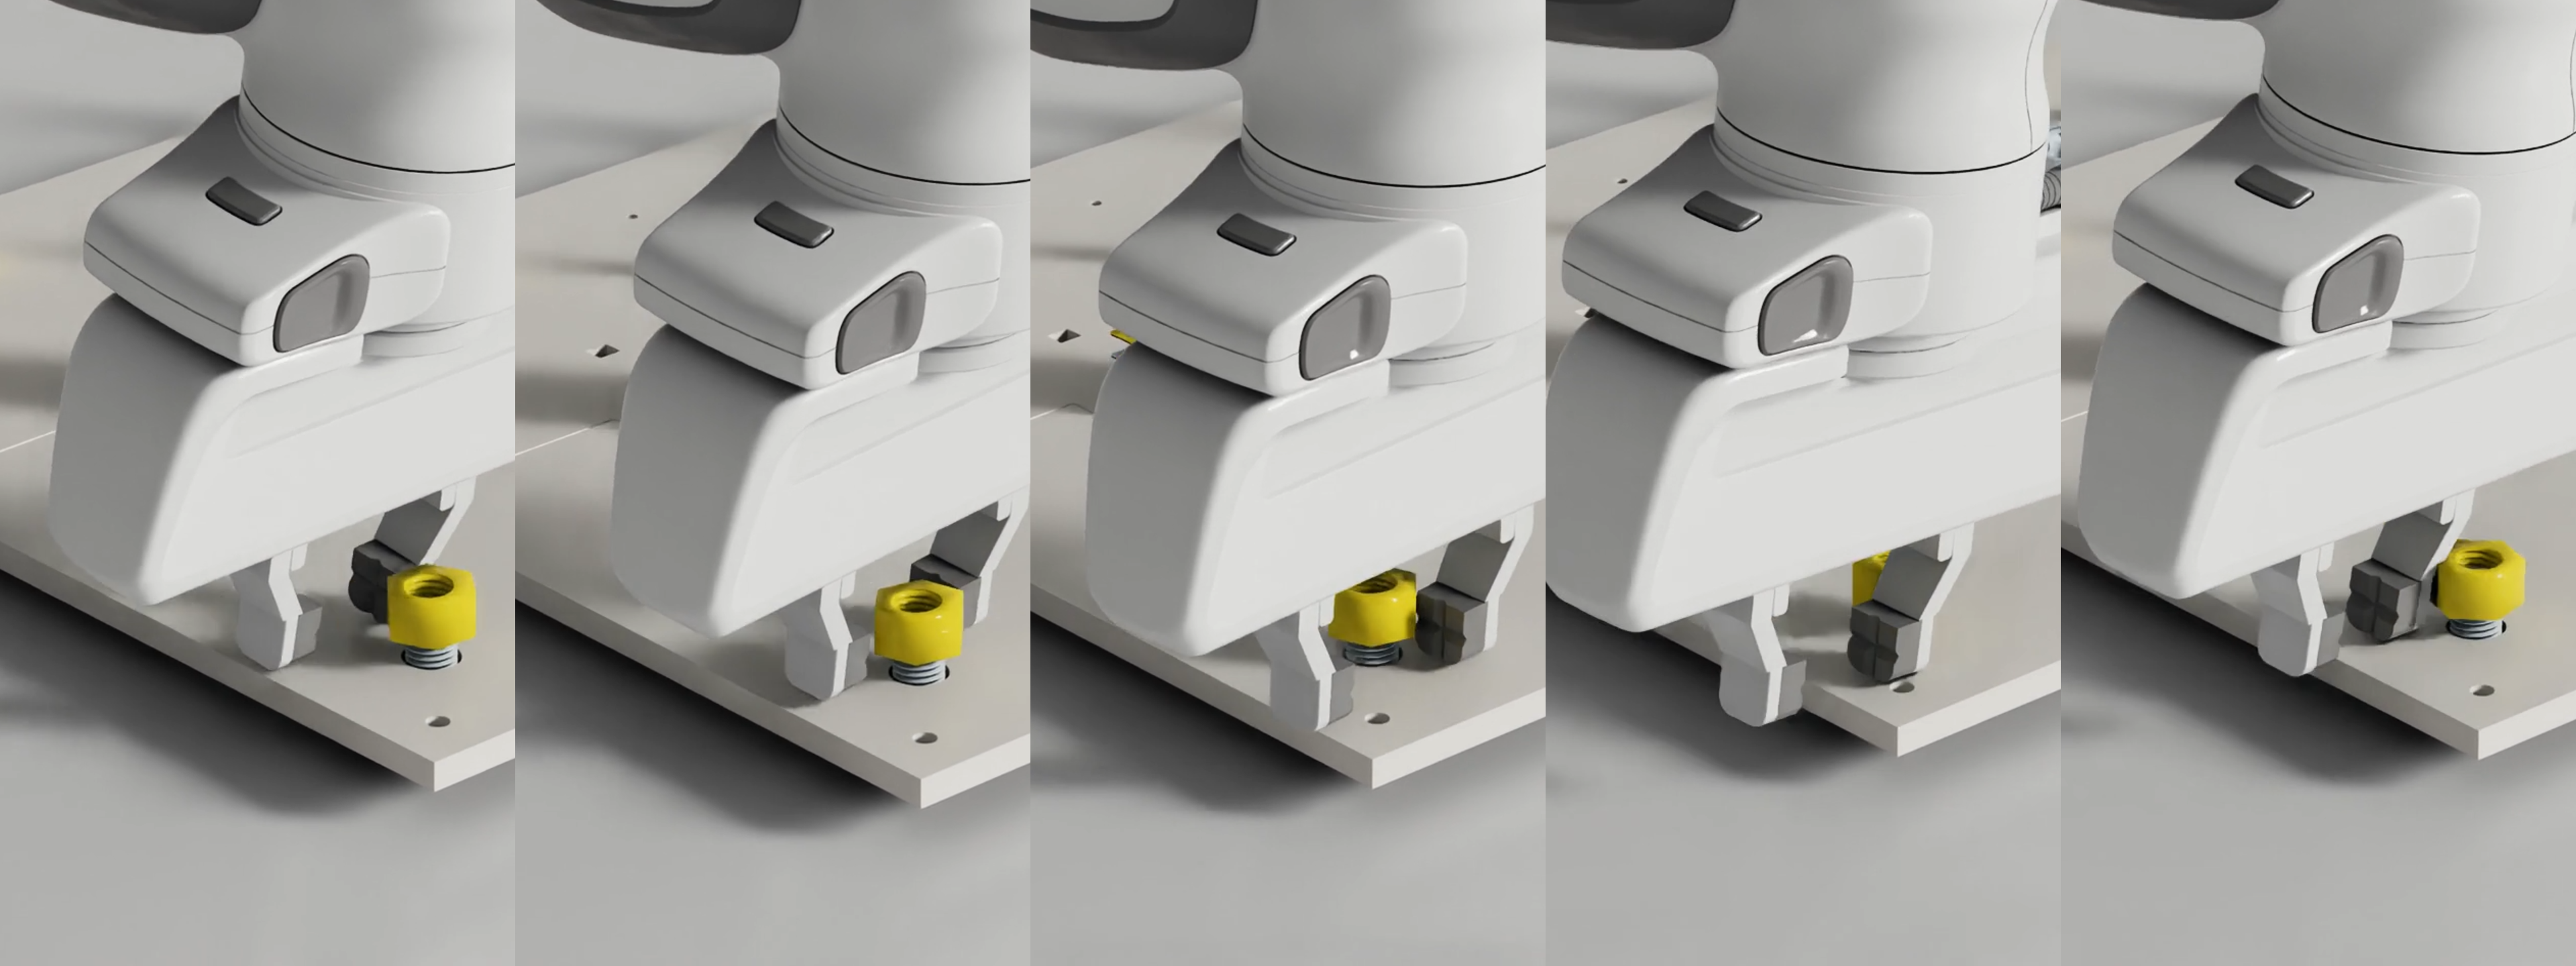 The gripper moves around the M16 nut, using fingertip contact to turn it along the bolt.
Citation
@misc{zhang2026alphanistemergentassemblyskills,
  title={AlphaNIST: Emergent Assembly Skills from Binary Task Rewards},
  author={Octi Zhang and Iretiayo Akinola and Rosario Scalise and
          Mateo Guaman Castro and Patrick Yin and Tobias Widmer and
          Miles Macklin and Chris Amevor and Dylan Turpin and
          Dirk Van Gelder and Jan Carius and Ankur Handa and
          Gavriel State and Yunrong Guo and Yashraj Narang},
  year={2026},
  eprint={2610.13354},
  archivePrefix={arXiv},
  primaryClass={cs.AI},
  url={https://arxiv.org/abs/2610.13354},
}