Google Releases Gemini 4 Hydrogen with New xhigh Reasoning Tier
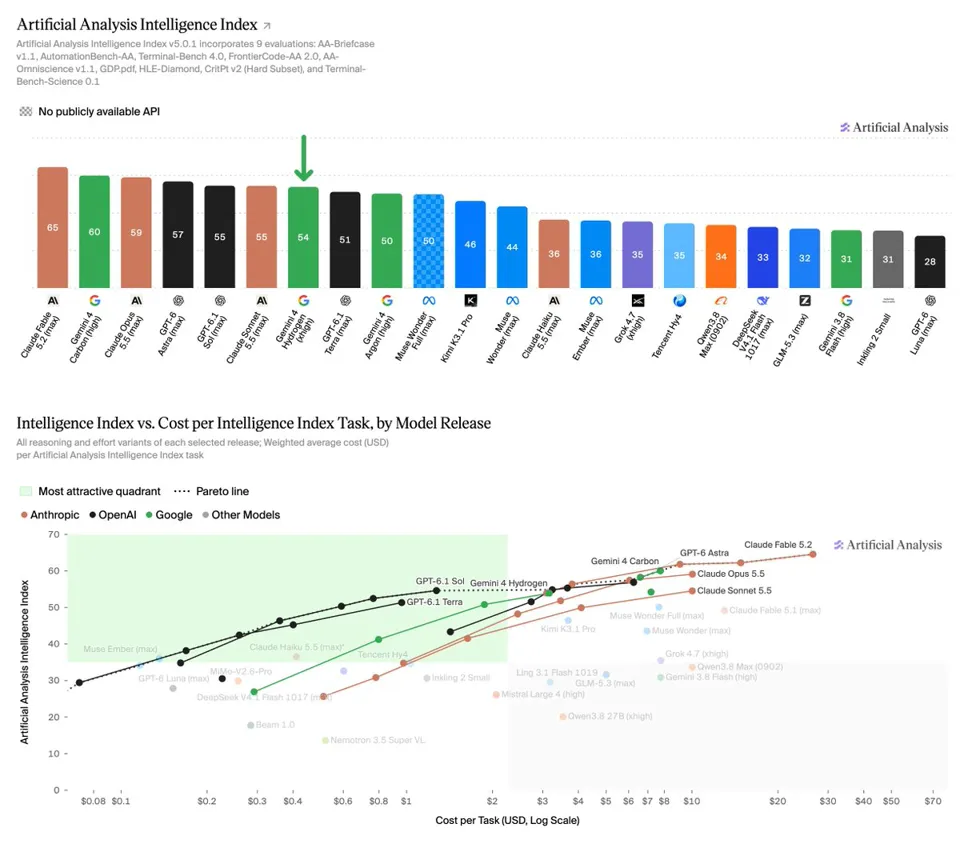
Google DeepMind has shipped Gemini 4 Hydrogen, its third new model in six weeks, introducing an xhigh reasoning tier above high. It scores 54 on the Artificial Analysis Intelligence Index, just one point behind Claude Sonnet 5.5 and GPT-6.1 Sol, at roughly 32% of Sonnet's cost but about 2.5x that of GPT-6.1 Sol, with standout visual reasoning and non-hallucination performance.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-12 18
Google's new Gemini 4 Hydrogen has Intelligence just below Claude Sonnet 5.5 and GPT-6.1 Sol, at a third of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol
@GoogleDeepMind has released their third new model in six weeks. Gemini 4 Hydrogen introduces an xhigh reasoning level and scores 54 on the Artificial Analysis Intelligence Index, with strengths in visual reasoning and non-hallucination. This places it 1 point behind Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), at ~32% of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol. With high reasoning, Gemini 4 Hydrogen matches the Intelligence of Gemini 4 Argon for ~19% of the Cost per Task
Key takeaways:
➤ The new xhigh reasoning level scores 54 on the Intelligence Index: xhigh is the first reasoning level above high on a Gemini model, and puts Hydrogen 1 point below Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), and 4 points ahead of Gemini 4 Argon (high). With default (high) reasoning, Gemini 4 Hydrogen scores 51, just behind GPT-6.1 Sol (xhigh, 52) and Claude Opus 5.5 (high, 52)
➤ Strong visual reasoning, presentation and non-hallucination: On GDP.pdf, a visual reasoning benchmark over long documents, it scores 33% all-pass on medium reasoning, the tied #1 score on the benchmark. On AA-Omniscience, Hydrogen has one of the lowest hallucination rates recorded at 8%, compared with 43% for Claude Sonnet 5.5 (max) and 52% for GPT-6.1 Sol (max). On AA-Briefcase, our agentic knowledge work evaluation, graders rate Hydrogen's presentation above other Gemini models, including Carbon
➤ Weaker on agentic terminal work: Hydrogen scores 54% on Terminal-Bench 4.0 and 50% on Terminal-Bench-Science 0.1, covering agentic coding and scientific research workflows in the terminal. Claude Sonnet 5.5 (max) scores 64% and 53%, and GPT-6.1 Sol (max) scores 56% and 58%. xhigh reasoning helps on the science tasks, lifting Terminal-Bench-Science from 41% at high to 50%, but makes no difference on Terminal-Bench 4.0 (54% at both). Science scores are even across domains, from 46% in earth sciences to 53% in physical sciences
➤ Low cost for its intelligence, with high token use at xhigh: Hydrogen is priced at 7.50 per million input/output tokens. At xhigh it costs ~32% as much per task as Claude Sonnet 5.5 (max) for near-equal intelligence, but ~2.5x as much as GPT-6.1 Sol (max). xhigh nearly doubles output tokens compared with high for a 3 point gain in Intelligence, and Cost per Task falls from $3.16 at xhigh to $1.87 at high. Medium ($0.80) and low ($0.29) cost less again, but score 41 and 27 on the Intelligence Index
➤ On the Time per Task vs. Intelligence Pareto frontier: Gemini 4 Hydrogen has an output speed of ~200 output tokens per second. With high, medium, and low reasoning effort, Gemini 4 Hydrogen is on the Time per Task vs. Intelligence Pareto frontier, meaning no models are both more intelligent and have a lower Time per Task
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Reasoning efforts: Gemini 4 Hydrogen offers four reasoning levels (low, medium, high, and xhigh) with xhigh new in this release
➤ Pricing: 7.50 per 1M input/output tokens. Cached input tokens receive a 95% discount ($0.075)
Congratulations to the @GoogleDeepMind team on the launch!