Stanford-led Team Launches SPU Benchmark with 4,207 Wet-Lab Tests
UniPat AI, together with Stanford, Harvard, Cornell and over ten other institutions, released Science Prediction Universe (SPU), a benchmark of 116 tasks and 4,207 real wet-lab experiments that tests whether AI can predict experimental outcomes before they are run. Models were given an H20 GPU and an 8-hour workday to autonomously use retrieval and compute resources, yet even Opus 5.5 and GPT-6 Astra remained far from usable predictive accuracy, and a 5x compute increase did not help. The benchmark turns hard-to-quantify scientific judgment into a measurable, comparable score.
Full Report
Contents3 sections
Stanford, Harvard, Cornell... over a dozen top-tier teams are all sitting at the same table
Luyu, reporting from Aofei Temple QuantumBit | WeChat Official Account QbitAI
No seriously, have benchmarks really evolved to this level now???
This time it's not about solving problem sets—they just give the AI a set of experimental conditions and let it conduct its own research and predict the results of real wet-lab experiments in advance...
For example, given the same reaction under several different conditions, which one yields more of the target product? For a batch of antibody variants, which one has higher expression levels?
The answers are hidden away first, and once the AI submits its answers, they're checked against the actual measured results.
And you know what, this really is worth testing right now.
Over the past two years, the AI for Science approach has been going deeper and deeper. AI can already autonomously search the literature, use software, and work for hours on end to complete an analysis task.
Naturally, everyone has started moving to the next stage: what kind of scientific research capabilities do we actually want AI to have?
Wet-lab result prediction is one of the most practically valuable among them.
It requires the AI to understand the experimental goal and dig out the relevant mechanisms from existing knowledge, so that it can better help researchers screen research directions worth exploring further.
The new benchmark Science Prediction Universe (SPU for short), spearheaded by UniPat AI, has keenly picked up on this.
116 tasks, 4,207 wet-lab experiments, covering chemistry, materials science, biology, and medicine. The benchmark advisors and wet-lab collaborators also come from universities such as Stanford, Cornell, and Harvard, as well as cutting-edge research institutions and biotech companies in the field.
The model follows an 8-hour workday per run, equipped with an H20, and then autonomously decides how to use retrieval and computational resources to form experimental predictions.
The results surprised everyone.
Even with strong models like Opus 5.5 and GPT-6 Astra, the data shows they are still very far from being able to actually make predictions...
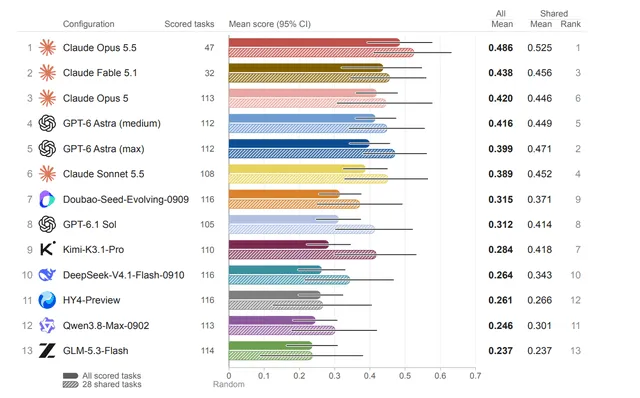
Average scores of each configuration across all scored tasks
I have to say, SPU has served all research models a tough dish.
The research capabilities that used to be invisible and intangible have now become values that can be uniformly evaluated and continuously studied.
As for how AI's scientific judgment develops step by step, there is now a more concrete basis for discussion.
Wet-Lab Prediction: Worth a Dedicated Exam for Models
Back to wet-lab prediction—first of all, this is indeed not a new question.
There have been many such moments in the history of science: a judgment is made before the experiment, and then it's left to the process to decide—if it's right, it stays; if it's wrong, it's overturned.
The specific logic of judgment constitutes a scientist's taste.
With good enough taste and accurate enough intuition, scientists can get big results faster while saving precious experimental resources.
After all, a single wet-lab experiment alone—for chemistry, you need to prepare reagents, set reaction conditions, and then separate the products; for biology, you have to go through lengthy protein expression... The time cost and tool costs are expensive in themselves, and if the results aren't ideal, you have to do it over and over again.
So predicting before getting your hands dirty is the most valuable step in the research process.

The only difference is that this used to rely purely on the scientists themselves, and now in the AI era, models also need this capability—and they need a test paper that can score it.
Existing benchmarks cannot fully cover this. For example, BrainBench lets models directly judge experimental results, ScienceAgentBench focuses on completing analysis on existing data, and long-horizon task benchmarks like Terminal-Bench 4.0 and Long-Horizon-TB mainly use preset tests to check task artifacts.
SPU is different from all of them.
It places more emphasis on examining the AI's autonomous research process together with wet-lab result prediction, testing both prediction performance and the ability to use scientific tools and execute long-horizon tasks.

Chart generated by AI
This kind of judgment has also been organized by SPU into explicit tasks.
100 public tasks are drawn from 85 recently published papers. Domain experts organize the candidates, materials, conditions, and measurement methods from the research, and retain complete quantitative results as the basis for scoring.
In addition, 16 private tasks come from four groups of unpublished collaborative wet-lab experiments, involving VHH nanobodies, reaction conditions, electrolytes, and Magrolimab variants.
A total of 32 subfields and 4,207 experiments, where the public research provides interdisciplinary task sources, the measured results are hidden from the models, and the unpublished experiments add a check independent of the answers in public papers.
This can, to a certain extent, prevent models from having seen the questions beforehand.

Task coverage and sources of SPU
The question selection process is also quite particular.
Experts prioritize studies with complete measurements and clear conditions. Simple questions that can be ranked along a single trend are directly eliminated, and questions with values that are too close to each other are also considered to have little reference value.
The questions that ultimately remain are all harder and more discriminative.
During the specific prediction process, the model is required to run for eight hours each time, equipped with an 8-core CPU, 16 GiB of memory, and one H20, while being allowed to search online and install scientific software.
During this time, the model will collect evidence on its own, choose computational methods, and finally submit a predicted ranking from low to high for each comparison group.
To prevent memory contamination, the scoring process is also conducted entirely in an independent, offline container. The AI is prohibited from retrieving the original research results, and tool outputs are automatically scanned to identify identifiers such as the source paper's DOI and title.
Finally, the system uses the Spearman correlation coefficient to compare the predicted ranking with the measured ranking.
The closer the coefficient is to 1, the closer the ranking is to the experimental results.
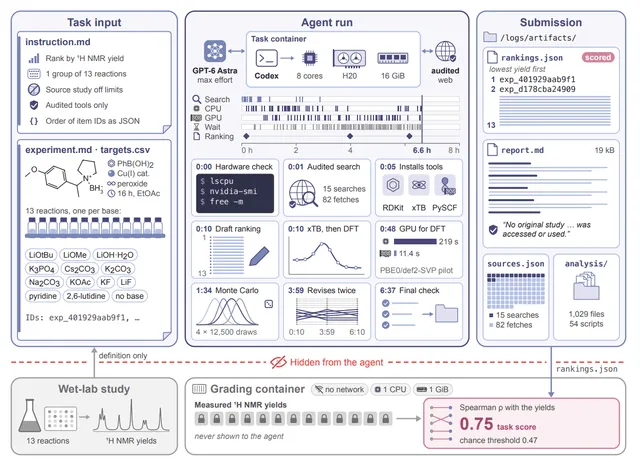
The evaluation pipeline of SPU
Interestingly, SPU also pays attention to many details that other benchmarks don't consider.
For example, for the final score, SPU considers whether it might have been due to luck—what if it was just a blind cat stumbling upon a dead mouse?
So it additionally generates 4,000 random orderings for each question, uses the 95th percentile as the random-level threshold, and checks whether the model's submission significantly exceeds this reference. Different tasks also have corresponding reference bases.
The design of the entire SPU can be said to be scientifically rigorous.
The model must, step by step, decide for itself what is worth computing and submit its final prediction.
This design is conducive both to measuring the current AI's wet-lab prediction capabilities and to pointing the way for subsequent research teams to continuously improve experiments using unified metrics.
That said, let's next take a look together at the report cards of the first batch of frontier models. The details are quite worth discussing separately.
The new test makes frontier models collectively break down
The first round of systematic SPU evaluation covers 12 frontier models and 13 configurations. Here, configuration refers to the model, the reasoning intensity, and the model framework used.
First, the overall results.
In one sentence: none of them are any good.
Across all scored tasks, the highest average score was achieved by Claude Opus 5.5, at 0.486. But even for it, only half of the tasks exceeded the random level.
Among the 13 configurations, this is almost universally the case: the proportion of tasks exceeding the random-level threshold is only 34%–52%.
In other words, all the models present still have a long way to go before achieving truly reliable wet-lab prediction.
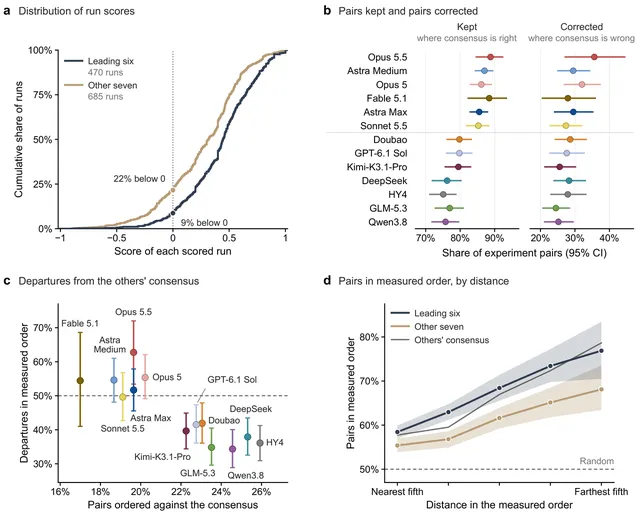
Behavioral comparison analysis of the leading group and the trailing group
However, there are differences among the models as well, and average performance can be divided into two tiers:
the leading group (6 models) and the trailing group (7 models).
In same-question comparisons, the leading group still averages about 0.15 points higher than the other seven.
There is another detail worth noting. About 9% of tasks in the leading group scored below 0, while for the other seven configurations this proportion can be as high as 22%.
Here, 0 refers to the average score of random valid orderings, and a negative score means the prediction is negatively correlated with the actual ordering.
Where exactly does the gap come from? The research team dug one step deeper.
They first combined the predictions of other models on the same question into a reference ordering, then paired experiments two by two, compared them against the measured results, and checked whether each model individually got the ordering right.
On experiment pairs where the reference ordering was correct, the leading group got 86% right, while the other seven configurations got 78%; for experiment pairs where the reference ordering was wrong, both groups independently got the ordering right about 30% of the time.
So part of the leading group's advantage is actually reflected precisely in the places where predictions are jointly correct; in these parts, the leading group is always more stable.

As for why models deviate from correct judgments, the run logs contain more specific clues.
Take the solution task as an example. In the same polymerization reaction, 12 solvents are changed in sequence, and the task requires ordering by the mass of the polymer finally separated.
Opus 5.5 scored 0.874, while Qwen3.8 scored -0.126. The 12 candidate solvent conditions were paired two by two, for 66 pairs in total; the former got 56 pairs right, and the latter got 30 pairs right.
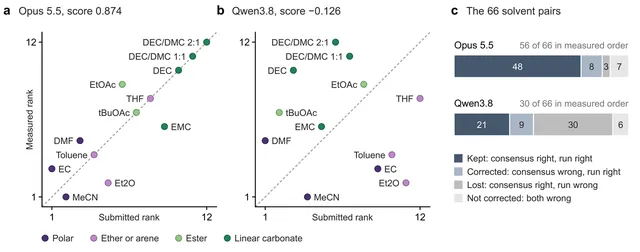
Two runs of Opus and Qwen on the same task
Analysis found that this is because the two differed from the very beginning in the factors they focused on:
Qwen3.8 mainly ordered by how much ethylene the solvent can dissolve, while Opus 5.5 paid more attention to the miscibility of the raw materials and the compatibility of the catalyst in the solvent.
Although Qwen3.8 also discovered this issue during computation, it ultimately failed to directly change the ordering basis the model finally adopted.
So the stage where prediction errors are most likely to occur is the step of choosing the basis for judgment; the model must also learn to adjust its ordering method on the fly according to clues, so that these findings can truly affect the answer.
Looked at separately, these differences also vary with the specific discipline and task.
Among the scored results for public tasks by discipline, the highest average score in chemistry was Opus 5.5, in materials science it was Fable 5.1, in biology it was GPT-6 Astra Medium, and in medicine it was Opus 5.
P.S. Fable 5.1 and Opus 5.5 exhibited refusal-to-answer behavior.

Scores of each model across the four disciplines
So if you are preparing to have AI participate in a certain type of research, you might first find a related task and use the SPU to test it, confirming that the model is truly applicable before conducting formal experiments.
The results on private tasks make this point even more concrete.
Among the 13 configurations, 12 had average scores significantly higher than random ordering, and no obvious differences were detected among configurations. By contrast, the variation brought by different tasks was especially striking.
For the same batch of electrolytes, when predicting ionic conductivity, the rank correlation coefficients of the 13 configurations were concentrated at 0.89–0.95; when switched to the electrochemical window, the scores of the 12 scored configurations ranged from -0.55 to 0.07, none exceeding the random-level threshold.
The model did not change, but once the measurement target changed, the score distribution clearly changed as well.
So next time you evaluate a model, saying it is good at chemistry is not specific enough; you also need to look at which specific measurement target and which experimental conditions it is facing.
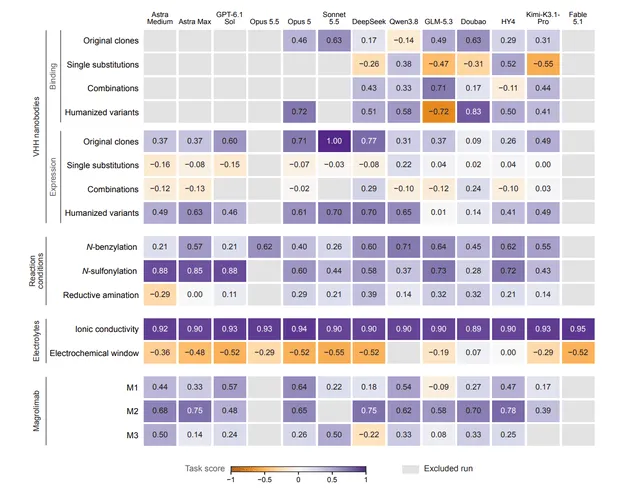
Prediction performance of each model on 16 private tasks
Here is another rather counterintuitive thing:
Generally speaking, giving the model more time and higher reasoning intensity should make the score continue to rise, right?
Everyone generally thinks so, and everyone does so.
Guess what happened? Once the SPU results came out, they slapped us right in the face—
Under the same 8 hours of computation, the research team adjusted GPT-6 Astra from medium reasoning intensity to the highest. At the highest intensity, the median runtime increased to 4.8 times, and the median API cost also increased to 5.3 times.
But the prediction score... barely moved at all.
Huh? The research team even went back specifically to check the model run logs.
And what do you know: on the 79 completed tasks, GPT-6 Astra at the highest reasoning intensity had usually already given the answer by the median 26% of runtime.
The model was not idle afterward and continued computing and revising, but these were all fine-tuning adjustments that failed to show any difference in the results.
In other words, higher reasoning intensity does not necessarily lead to better results.

Investment and performance of GPT-6 Astra under two reasoning intensities
This phenomenon also serves as a reminder about resource allocation for models: if you want to add more computation, don't rush in blindly—it costs time and effort and may not even pay off.
Instead, you can examine the run records more carefully, first fully understanding which judgment each piece of newly added evidence actually corresponds to, and then purposefully increasing compute locally.
In fact, a similar phenomenon also appears in tool use.
The median number of method categories used per run by GPT-6 Astra Max is 4, versus 1 for Medium, yet no significant difference in scores was detected between the two configurations.
The reason is much the same: good tools were not applied where they mattered most.
Take Monte Carlo sampling, for example. Although the model was calling this tool most of the time, it only added a margin of error to the final ranking and did not directly affect the results themselves.
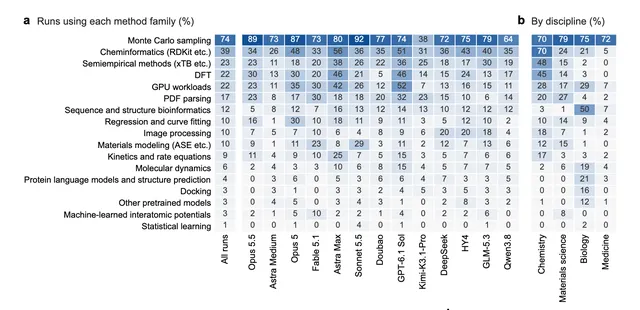
Scientific computing tool invocation
So using more tools is actually not as good as using them accurately.
GPU usage also offers an interesting perspective.
Even with sufficient GPU compute provided, only 255 runs actually succeeded in running GPU computations—less than one fifth.
GPU usage varies across models and disciplines, so simply looking at the number of GPU invocations hardly says much about a model's research capability.
To judge whether compute actually helped, you still need to look at what it was used to calculate, whether the calculation results helped with prediction, and how those results affected the final ranking.
The key is still to direct compute toward the physical quantities relevant to ranking, so that the model can complete predictions more precisely.

GPU usage statistics
Looking at cost alongside this, the average API cost per run across configurations ranges from $0.22 to $65.91—a gap of fully 300x.
This means SPU provides both predictive performance and invocation cost, making it a good reference for teams preparing to deploy research models.
From overall scores to per-question trajectories, SPU unfolds model differences into every detail of scientific judgment—compute, for instance, and cost.
How much do the numerical values computed by AI actually help with prediction? When a prediction goes wrong, which judgments should be re-examined? These can all be further analyzed by combining experimental results with run records.
The next round of improvement then has clear directions to try:
According to SPU, models can more promptly identify erroneous assumptions and retain or revise rankings on a more informed basis. After making changes, put the model back on the same tasks and see whether predictions become more accurate.
Bringing "testing understanding" into the model's exam room
It is fair to say that SPU aligns closely with the development patterns of AI4S.
AI4S evaluation is gradually moving deeper into real experimental settings, and benchmarks oriented toward experiment execution have been emerging this year.
But beyond execution, prediction—an unavoidable step in the research process and the hardest to quantify—has finally become measurable.
The benefits are twofold:
Researchers can now analyze which measurement targets are easier to predict, which tasks differ most, and how a wrong judgment takes shape. This can save expensive and precious experimental resources and shorten decision time.
For model development, this also provides a more concrete reference for improvement.
As experiment types increase, evaluation can also answer more specific questions: for which materials, experimental conditions, and measurement methods are the rankings produced by AI more reliable and more worth consulting?
Scientists can thus accumulate progress continuously around the same class of questions.
In fact, SPU is only the tip of the iceberg in UniPat AI's series of real-work evaluations:
- ScienceVision: focuses on how models obtain evidence from 3D scientific objects and answer questions;
- PaperBenchX: turns published research into executable, verifiable paper reproduction tasks;
- SaaS-Bench and EvoCode-Bench: examine development work in real software workflows and under continuously changing requirements, respectively. ……
These efforts cover scientific research, office work, and software development, and they share a common concern: how AI completes tasks after entering concrete work, and how results are verified.
This also reflects, in part, UniPat AI's distinctive industry insight and forward-looking judgment regarding AI's movement into scientific practice and even into the real world.
UniPat AI also demonstrates a new model of AI collaboration:
Domain experts participate in task selection and review, partner laboratories provide unpublished tasks, and the project team organizes experiments from different disciplines into unified evaluation tasks.
Take SPU as an example. It is led by UniPat AI, with advisors affiliated with institutions including Stanford, Cornell, Harvard, UIC, Peking University, HKUST, and FutureHouse. Wet-lab collaborators from Yourui Saishi, Aibotech, Shenzhi Yuanli, and Enhe Biology participated in the related experimental work.
Interdisciplinary knowledge and experimental resources thus enter the same evaluation process. SPU carries both the selection of questions and the collaboration required to organize scientific questions into executable tasks.
At present, the 100 public tasks related to SPU are planned to be released as complete Harbor task packages; the 16 private tasks will remain private for controlled evaluation. The dataset and code are already open source.
Admittedly, today's AI is still a novice in front of this SPU mechanism.
It can use tools at lightning speed, installing three sets of software in 8 hours, running DFT and then Monte Carlo, but on the most critical judgment, it has not yet learned to ask itself one question: is the quantity I am calculating the very quantity the experiment actually needs to measure?
But as such tasks continue to accumulate, what kind of scientific work AI can take on will also become clear.
SPU has measured this distance. Every exam from now on is a record of AI taking one step closer to the real experimental bench.
Project homepage: https://spu.unipat.ai Paper link: https://arxiv.org/abs/2611.15049 GitHub open-source link: https://github.com/UniPat-AI/SPU