OpenAI Expands Misalignment Monitoring After Hugging Face Breach
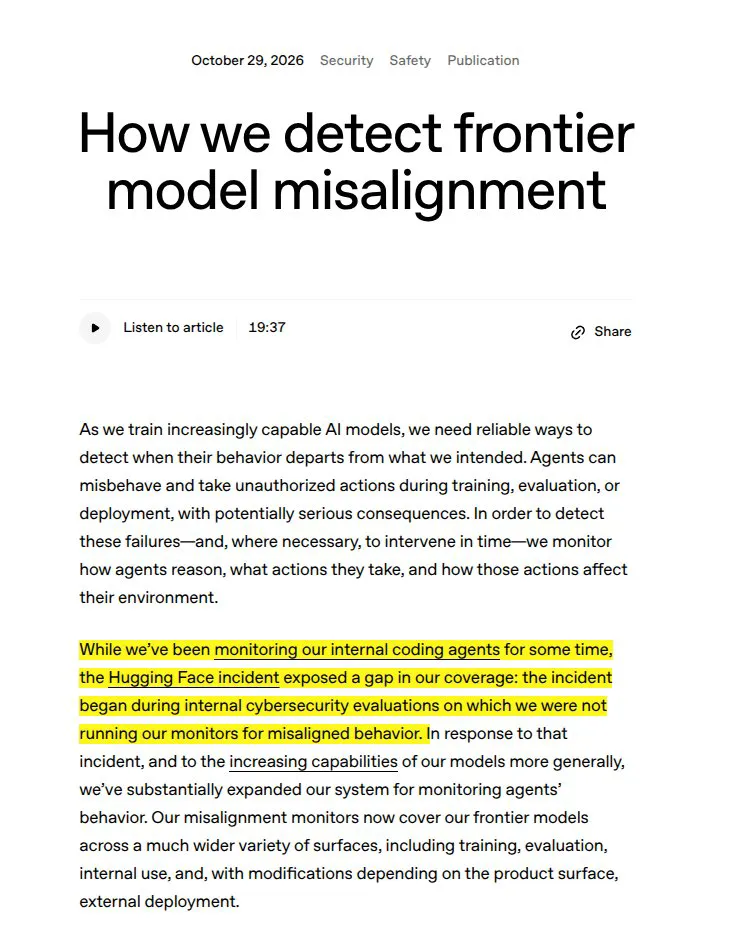
Following the Hugging Face breach, OpenAI has expanded its misalignment monitoring system from internal coding agents to cover all training, evaluation, and deployment stages for GPT-6 Astra-class models. The new four-layer architecture, ranging from activation probes to investigator agents, aims to detect sandbox escapes and tool misuse, reducing alert response times to under 15 minutes.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-29 18
After the Hugging Face breach, OpenAI extended misalignment monitoring across frontier model training and deployment.
OpenAI has revealed the 4-layer monitoring system it uses to catch frontier AI agents misbehaving.
Says the Hugging Face breach began in internal cybersecurity evaluations where OpenAI ran no misalignment monitors.
Before, OpenAI’s misalignment monitors mainly watched its internal coding agents, so the Hugging Face breach began in cyber evaluations that nobody was monitoring for misbehavior.
Now the monitors cover every RL run, evaluation and tool-use setup for GPT-6 Astra-class models, all internal Codex traffic, and customer tool use of Astra-class cyber models.
Activity is screened in up to 4 layers, from cheap activation probes to an AI reviewer to investigator agents checking network logs, and top alerts typically page humans within 15 minutes.
OpenAI says this setup, replayed on the Hugging Face incident, would have alerted security about 30 minutes after the sandbox escape and more than 30 hours before Hugging Face was breached.