Rohan Paul (@rohanpaul_ai) · 10/10/2026, 11:32:00
Tsinghua's TokenRouter Boosts LLM Serving Throughput by 64x via Per-Token Model Routing
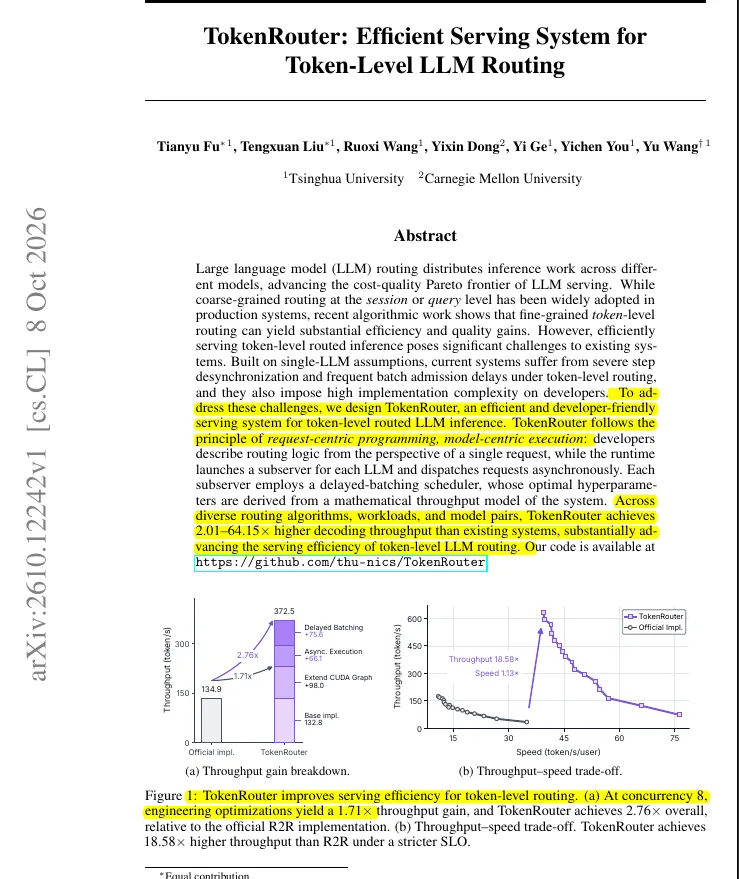
Tsinghua University introduced TokenRouter, a serving system that dynamically routes between small and large models at the token level to eliminate blocking delays in traditional frameworks. By enabling independent model deployment with shared KV caches and request buffering for optimized batching, it achieves throughput improvements ranging from 2.01x to 64.15x across five routing strategies.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-10 03
New Tsinghua paper builds TokenRouter, a serving system that runs per-token small-and-large model routing at upto 64.15X the throughput of existing setups.
Current popular serving frameworks (like vLLM and SGLang) run one model per request, so when two models share an answer, every step waits for the slower one.
TokenRouter gives each model its own server and lets them pass work back and forth. So, it hands a half-written answer between them while keeping the model’s memory of the text so far (the KV cache), and holds requests for a moment so each model works on bigger batches.
Across 5 routing methods, throughput rose 2.01 to 64.15 times over the stronger existing setup.
– arxiv. org/abs/2610.12242
Title: "TokenRouter: Efficient Serving System for Token-Level LLM Routing"